
Medium Article Scraper
Pricing
from $4.00 / 1,000 articles
Medium Article Scraper
Scrape full Medium article content past the paywall — title, subtitle, authors, publish and updated dates, reading time, cover image, table of contents, and the complete body as HTML, Markdown, and plain text. Accepts article URLs, author profiles, or publications. No login needed.
Pricing
from $4.00 / 1,000 articles
Rating
0.0
(0)
Developer
Muhamed Didovic
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
20 hours ago
Last modified
Categories
Share
Turn Medium articles into structured content — past the paywall. Scrape any Medium article's title, subtitle, author profile, publication, dates, reading time, word count, tags, claps, response count, cover image, table of contents, and the full body as HTML, Markdown, and plain text — even for member-only posts. Start from article URLs, an author's or publication's full archive, a tag, or a keyword search, and optionally pull each article's responses (comments) too. JSON or CSV out, billed per article.
How it works
✨ Why use this scraper?
Building an LLM/RAG corpus from Medium? Archiving a publication? Tracking which posts take off? Need the full text of paywalled posts without a Medium subscription?
- Five starting points. Article URLs, author profiles (
@username), publications (data-science-collectiveor a custom domain likelevelup.gitconnected.com), tags (machine-learning), and keyword searches (rust async). Authors and publications are read as full archives, not just the latest 10 posts. - Paywall bypass, no login. Every article body is resolved through the Freedium mirror, which returns the complete text for member-only posts — no cookies, no session, no subscription.
- Engagement and context from Medium itself. Claps, clapper count, response count, tags, language, license, and Medium's own word count, plus the author's bio, follower count and membership, and the publication's name and subscriber count.
- Responses on demand. Set
maxResponsesPerArticleto attach each article's comments: author, claps, date, and text. - Three body formats. Each row carries the body as
html,markdown, andtext(or pick one to shrink the dataset). Plain text is SVG-stripped and newline-normalized, ready for embeddings. Every image in the body is listed inimages. - Clean exports. One row per article. No padding, no duplicates across sources, and no empty rows: articles Freedium cannot resolve are skipped, so you never pay for them. Export as JSON, CSV, Excel, or through the API.
Overview
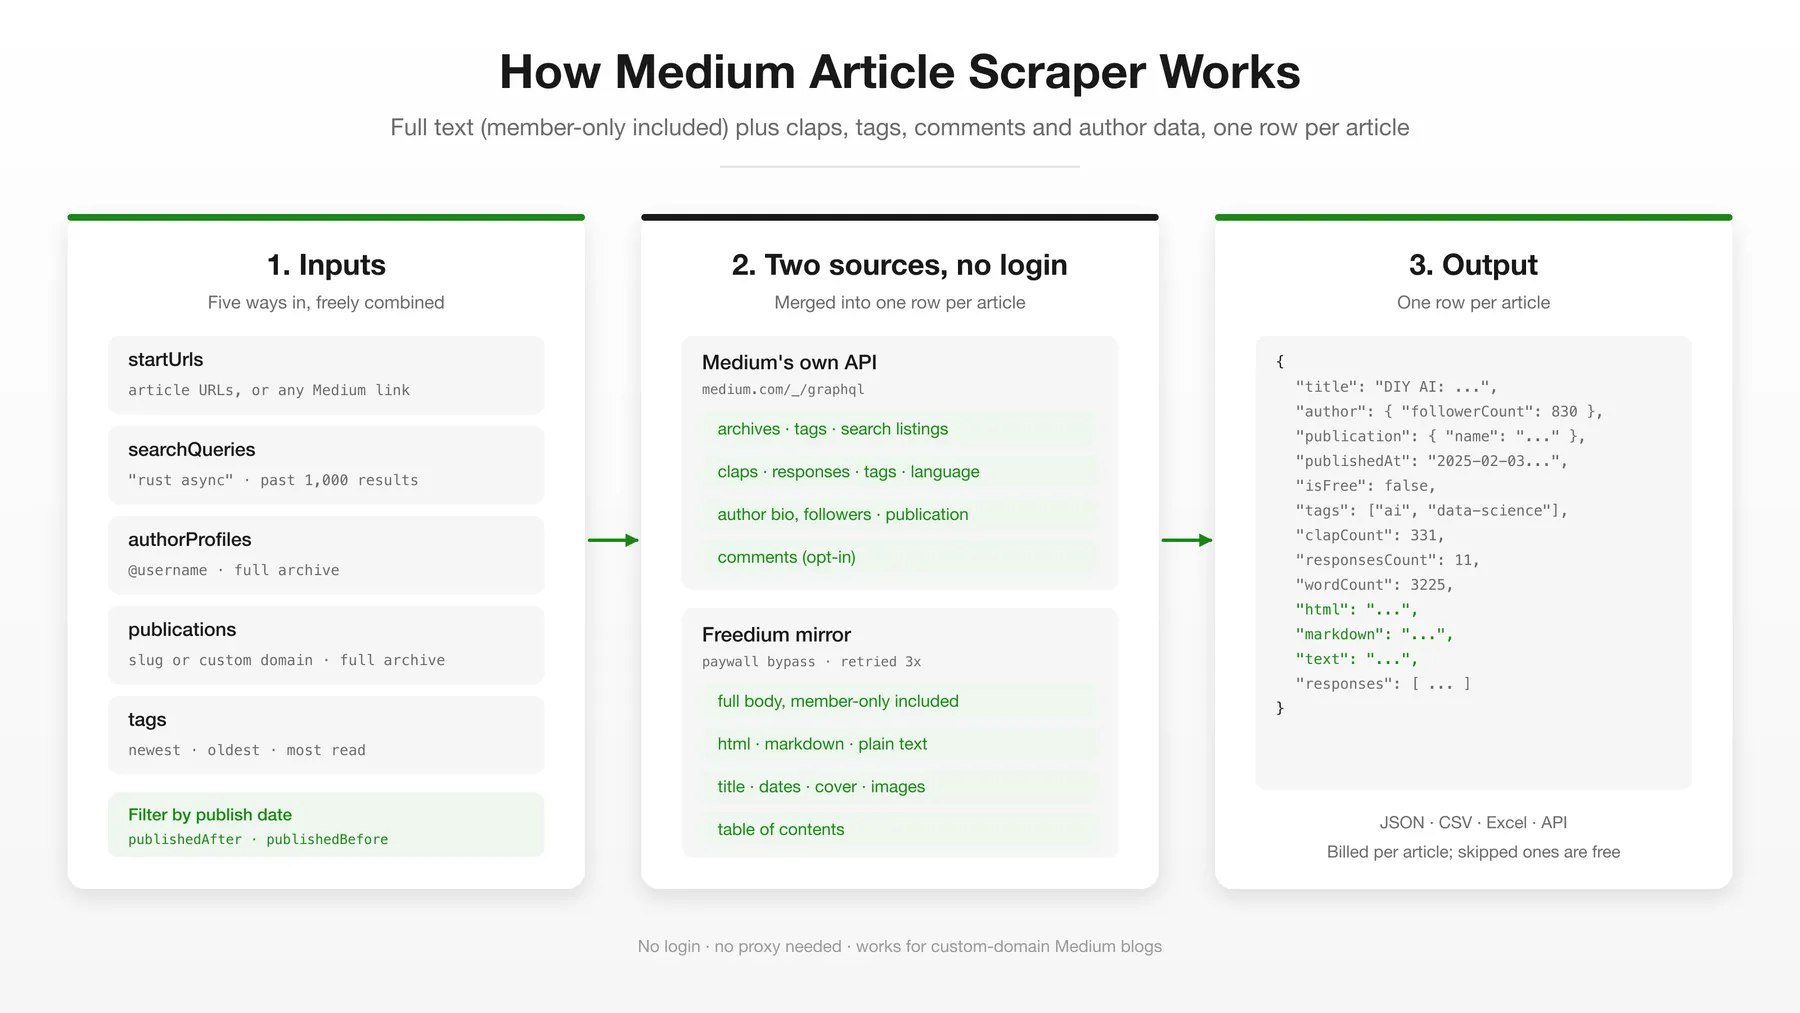
Medium hides most of its best writing behind the member paywall and offers no public API for article bodies. This actor combines two sources. Article bodies and core metadata come from the Freedium mirror, which serves member-only posts in full. Listings (author and publication archives, tags, search) and engagement data (claps, responses, tags, author and publication profiles) come from Medium's own public GraphQL API, the one medium.com's web pages call. The result is one clean dataset row per article with the complete body in three formats.
Supported inputs
Five input arrays, freely combined. Each is classified automatically.
| Input | Accepts | Behaviour |
|---|---|---|
startUrls | https://medium.com/@user/slug-<id>, https://medium.com/<pub>/slug-<id>, https://<user>.medium.com/slug-<id>, custom-domain Medium blogs (https://levelup.gitconnected.com/slug-<id>) | Resolved directly |
searchQueries | Any keywords, e.g. rust async | Medium's own search results; past Medium's ~1,000-per-query cap through publish-date windows |
authorProfiles | @username, https://medium.com/@username, username.medium.com | The author's post history, newest first |
publications | data-science-collective, https://medium.com/data-science-collective, https://medium.com/feed/..., levelup.gitconnected.com | The publication's archive, newest first |
tags | machine-learning, Machine Learning, https://medium.com/tag/machine-learning | Newest posts under the tag |
Each author, publication, tag and search contributes up to maxArticlesPerSource articles (default 50); maxItems caps the whole run.
You can also paste any Medium link into startUrls: a search page (https://medium.com/search?q=rust+async) runs as a search, a tag page as a tag, a profile as an author, and a publication home page as a publication.
Easiest workflow: copy a Medium article URL from the address bar into startUrls, or drop an @username into authorProfiles to grab their posts.
Not supported:
- Articles that have been deleted from Medium (skipped and not charged, never a failed run).
- Replies to responses.
responsesholds the top-level responses only. - Drafts, unlisted and private posts.
🎯 Use cases
| Team | What they build |
|---|---|
| AI / LLM apps | RAG corpora and embedding pipelines from Medium's long-form content, filtered by tag and language |
| Content & research | Archive a publication's or author's full body of work before it is edited or paywalled |
| Media monitoring | Track what a tag, author or publication publishes, and which posts collect claps and responses |
| NLP / data science | Datasets of article text, word counts, tags, engagement, and reader responses for analysis |
| Newsletter curators | Find the most-clapped posts on a topic and pull their full text for summarization |
Under the hood
- Gather article URLs.
startUrlsare validated directly. Authors, publications, tags and searches are listed through Medium's GraphQL API, page by page. If that API is unreachable, authors, publications and tags fall back to their RSS feed (which only lists the 10 most recent posts). - Dedupe + cap. All article URLs are merged into one set, deduped, and capped at
maxItems. - Fetch Medium stats for every queued article in batches of 25: claps, responses, tags, language, author and publication profiles. This step is best effort: if it fails, those fields are
nulland the article still comes back. - Resolve each article body through Freedium's
__data.jsonendpoint in parallel (sliding-window concurrency), with up to 3 attempts per article. Both the cached payload and the streamed one Freedium sends on a cache miss are parsed. - Fetch responses (only when
maxResponsesPerArticleis above 0), 25 per request. - Push one row per article. Articles Freedium cannot resolve are logged and skipped, never pushed as empty rows.
Input configuration
| Parameter | Type | Default | Description |
|---|---|---|---|
startUrls | array | [] | Medium article URLs to scrape directly. |
searchQueries | array | [] | Keyword searches through Medium's own search. Goes past 1,000 results per query. |
authorProfiles | array | [] | Authors (@username, profile URLs, or username.medium.com). Full post history, newest first. |
publications | array | [] | Publications (slug, URL, feed URL, or custom domain). Full archive, newest first. |
tags | array | [] | Medium tags (slug, name, or tag URL). |
tagSort | select | NEWEST | Tag feed order: NEWEST, OLDEST, or MOST_READ (a short list: about 15 to 20 posts per tag, or per month with a date range). |
publishedAfter / publishedBefore | date | none | Only list articles first published in this window (inclusive). Applies to searches, tags, authors and publications. |
outputFormat | select | all | Body formats per row: all (html + markdown + text), markdown, or text. |
includeTableOfContents | boolean | true | Attach the parsed table of contents array to each row. |
maxResponsesPerArticle | integer | 0 | Responses (comments) to attach per article. 0 = none. |
maxItems | integer | 100 | Hard cap on articles scraped across all sources. |
maxArticlesPerSource | integer | 50 | Cap per author, publication, tag or search query. |
maxConcurrency | integer | 10 | Concurrent article fetches. |
proxy | object | none | Optional proxy for all requests. Usually unnecessary. |
Example input
Output overview
Each scraped article is one single dataset row. The row count equals the article count exactly — no padding rows, no separate metadata rows. Responses ride inside their article's row.
Output sample
One row per article (body fields and long arrays trimmed):
Key output fields
| Field | Type | Description |
|---|---|---|
url | string | Canonical Medium article URL. |
postId | string | Medium's 12-character post id. Stable; good as a dedupe key. |
title / subtitle | string | Article title and subtitle. |
authors / authorNames | array | { name, avatar } per byline author, and the names alone. |
author | object | Primary author: username, name, bio, followerCount, isMediumMember, avatar, profileUrl. |
publication | object | name, slug, domain, subscriberCount, url; null for posts outside a publication. |
publishedAt / updatedAt | string (ISO 8601) | First published and last updated timestamps. |
readingTime | string | Medium's reading-time estimate (e.g. "14 min read"). |
wordCount | number | Medium's word count (counted from the text if Medium's is unavailable). |
language | string | Detected language code, e.g. "en". |
isFree | boolean | true if free to read, false if member-only. |
tags | array | { slug, title } per tag. |
clapCount / clapperCount | number | Total claps, and the number of people who clapped. |
responsesCount | number | Number of responses (comments). |
license | string | Medium license, e.g. ALL_RIGHTS_RESERVED or a Creative Commons variant. |
canonicalUrl | string | The canonical URL set by the author, when there is one. |
coverImage / coverImageLarge | string | Cover image URL at 700 px and at full size. |
coverImageCaption | string | Cover image caption / credit, as plain text. |
images | array | Every image URL in the article body, in order. |
tableOfContents | array | { id, level, title } per heading, when includeTableOfContents is on. |
html / markdown / text | string | Full article body, per outputFormat. |
responses | array | { id, url, authorUsername, authorName, clapCount, publishedAt, text } per response; null unless maxResponsesPerArticle is above 0. |
bodySource | string | freedium (the paywall mirror) or medium (Medium's own API, used for free articles when the mirror is unreachable). |
cacheStatus | string | Freedium cache state (l2_hit_cdn, inline, miss), or medium-api when the body came from Medium. |
error | object | Freedium's error object, normally null. Articles Freedium cannot resolve are skipped instead of pushed. |
Engagement fields (clapCount, clapperCount, responsesCount, language, license, author.bio, author.followerCount, publication details) come from Medium's API and are null if that lookup failed for a batch; the article itself still comes back.
FAQ
Does this work for member-only / paywalled articles? Yes. Freedium returns the full body regardless of the paywall, so isFree: false articles come back complete just like free ones.
Can I scrape everything by an author or publication? Yes. Authors and publications are read as full archives, newest first. Raise maxArticlesPerSource (up to 5,000) and maxItems to go deeper. In testing, 120 article URLs from an author's archive were listed in about 2 seconds.
Can I scrape by topic or keyword? Yes. Put tag slugs or names in tags for the newest posts under a tag, or keywords in searchQueries for Medium's own search results. A pasted medium.com/search?q=... link in startUrls works the same way. Set tagSort to MOST_READ for a tag's most-read posts, and publishedAfter / publishedBefore to limit any listing to a date window.
Can I get more than 1,000 search results? Yes. Medium's search serves only about 1,000 results per query (40 pages of 25). When a search hits that cap and you asked for more, the actor repeats it over publish-date windows, newest first (about a month each, halved again when a window is itself capped), and merges the results without duplicates. In testing, "python" returned 2,500 unique articles in about 90 seconds. Raise maxArticlesPerSource and maxItems to go deeper.
Does it get comments? Set maxResponsesPerArticle (for example 50) and each row gets a responses array with the top-level responses: author, claps, date, and text.
Does it work for Medium blogs on their own domain? Yes. Custom-domain Medium blogs such as levelup.gitconnected.com or netflixtechblog.com work as article URLs in startUrls and as publications (levelup.gitconnected.com in publications).
Why are image/avatar URLs on freedium-mirror.cfd? Freedium proxies Medium's images through its own host. The URLs are absolute and load directly. author.avatar comes from Medium's own image CDN.
What happens with a deleted or invalid article URL? Freedium answers ARTICLE_NOT_FOUND. Freedium sometimes sends that for live articles too (about 1 request in 13 on freshly published posts in testing), so the actor tries each article up to 3 times before skipping it. Skipped articles are not pushed and not charged, and they never fail the run. An author, publication or tag that does not exist is skipped with a note in the run's status message.
What if the Freedium mirror or Medium is down? Freedium is a third-party mirror and has outages (one ran for more than a day in October 2026). When it is unreachable, the actor gets the body from Medium's own API instead: free articles still come back in full, marked bodySource: "medium". Medium only serves a short preview of member-only articles, so those are skipped and not charged, and the run's status message says how many. After a few failed connections in a row the actor stops trying the mirror for the rest of the run, so an outage costs seconds, not minutes. If nothing at all comes back, the run ends as FAILED with the reason in its status message. If only Medium's API is unreachable, authors, publications and tags fall back to their RSS feeds (latest 10 posts) and the engagement fields are null.
Is a proxy needed? Usually not. Freedium and Medium's API both answered from datacenter IPs in testing. Leave proxy empty unless you hit rate limits; when set, it is used for every request.
How is it billed? Pay per event: a small fee when the run starts, then a fee per article row pushed to the dataset. Engagement data and responses are included in the article price. Skipped and failed articles are never charged. If you set a maximum cost per run, the actor stops at the number of articles that budget covers. On Apify's free plan, each run is capped at 60 articles and the first start URL; paid plans have no cap beyond your own maxItems. See the Pricing tab for current rates.
Your feedback
If this scraper saves you time, a short review on this page helps other people find it. If something's missing or broken instead, open an issue first: bugs and feature requests usually ship within days.
Support
- For issues or feature requests, please use the Issues tab of this actor on Apify Console.
- For further assistance, contact the author:
- Author's website: https://muhamed-didovic.github.io/
- Email: muhamed.didovic@gmail.com
Additional services
- Request customization, a full dataset, or a private build: muhamed.didovic@gmail.com
- Need scheduled monitoring of authors, publications or tags delivered to your database, or other blogging platforms scraped (Substack, Dev.to, Hashnode, Ghost)? Contact muhamed.didovic@gmail.com
- For API services of this scraper, reach out to muhamed.didovic@gmail.com
- Explore other scrapers at memo23's Apify profile
Explore More Scrapers
Other actors in the memo23 portfolio you might find useful:
- Substack Scraper: posts, comments, and subscriber data from Substack newsletters
- Google News Scraper: news results with full article bodies and entities
- LinkedIn Posts Scraper: posts from LinkedIn profiles and company pages, no cookies
- Quora Scraper: questions, answers, and topics by search or URL
- Reddit Scraper: posts, users, and subreddits
- YouTube Transcript Scraper: transcripts as text, SRT, or VTT for any YouTube video
🤖 For AI Agents & LLM Apps
Compact reference for AI agents calling this actor via the Apify MCP server or the Apify API (actor: memo23/medium-article-scraper).
Purpose: Returns the full body (HTML, Markdown, plain text) of Medium articles, member-only posts included, with engagement (claps, responses), tags, and author and publication profiles. One dataset row per article.
Minimal input:
Other modes: { "authorProfiles": ["@karpathy"] }, { "publications": ["data-science-collective"] }, { "tags": ["machine-learning"] }, { "searchQueries": ["rust async"] }. All five arrays can be combined in one run.
Output: url, postId, title, subtitle, authors, authorNames, author {username, name, bio, followerCount, isMediumMember, avatar, profileUrl}, publication {name, slug, domain, subscriberCount, url}, publishedAt, updatedAt, readingTime, wordCount, language, isFree, tags [{slug, title}], clapCount, clapperCount, responsesCount, license, canonicalUrl, coverImage, coverImageLarge, coverImageCaption, images, tableOfContents, html, markdown, text, responses, cacheStatus, error.
Behaviors an agent should know:
- Set
outputFormat: "markdown"or"text"to cut row size;allreturns the body three times. maxArticlesPerSource(default 50) caps each author, publication, tag and search;maxItems(default 100) caps the run.ACTOR_MAX_PAID_DATASET_ITEMS/ACTOR_MAX_TOTAL_CHARGE_USDrun limits are honoured. Free-plan users are capped at 60 articles and the first start URL per run.responsesisnullunlessmaxResponsesPerArticle> 0; it holds top-level responses only.- Engagement fields are
nullwhen Medium's API lookup fails; the body still comes back. - Deleted or invalid URLs are skipped after 3 attempts and not billed. Search, tag, profile and publication links pasted into
startUrlsare routed to the matching source. - Searches go past Medium's ~1,000-per-query cap through publish-date windows; deep searches take longer (2,500 results ≈ 90 s).
publishedAfter/publishedBeforelimit searches, tags, authors and publications to a date window;tagSortpicksNEWEST,OLDESTorMOST_READ.- If the Freedium mirror is down, free articles still come back (from Medium's API,
bodySource: "medium"); member-only ones are skipped and not charged. - A run where every article (or every requested source) fails ends FAILED with the reason in the status message.
- Pay-per-event billing: a small actor-start fee plus one charge per article row; see the Pricing tab.
⚠️ Disclaimer
This actor scrapes publicly accessible Medium article content via the third-party Freedium mirror and Medium's public web API for research and personal use. It does not bypass authentication on Medium itself. You are responsible for complying with Medium's Terms of Service and the copyright of the content you scrape. The actor and its author are not affiliated with, endorsed by, or sponsored by Medium (A Medium Corporation) or Freedium; all trademarks belong to their respective owners and are used here only to describe the sources the actor reads. Do not use this actor to bulk-republish copyrighted articles.
The author provides this actor "as is", without warranty of any kind, and disclaims any liability for damages arising from its use.
SEO Keywords
medium scraper, medium article scraper, medium paywall bypass, medium to markdown, medium rss scraper, scrape medium articles, medium content extractor, medium author scraper, medium publication scraper, medium tag scraper, medium search scraper, medium claps scraper, medium comments scraper, medium responses, medium article text, medium to text, medium api, freedium scraper, medium member-only article, medium archive, medium rag dataset, medium llm training data, medium custom domain scraper


