
Shopify Store Checker: Product Count and Scrape Cost Estimate
Pricing
from $0.56 / 1,000 domain checkeds
Shopify Store Checker: Product Count and Scrape Cost Estimate
Check which of your domains are readable Shopify stores, how many products each lists and what a full catalogue scrape would cost. Each miss says why: blocked, not found or not Shopify. A free dry run shows the price first, a spend cap stops the run, and a failed run costs nothing.
Pricing
from $0.56 / 1,000 domain checkeds
Rating
0.0
(0)
Developer

Monty Burrows
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
a day ago
Last modified
Categories
Share
Shopify Store Checker
Give it a list of domains. Get back which of them are readable Shopify storefronts, how many products each one holds, and what a full catalogue scrape would cost you before you start one.
One row per domain, whatever the answer is. "That is not a Shopify store" is the answer you came for, and it costs the same two requests to establish as "it is, and it has 1,675 products".
Why run this before the catalogue scraper
Roughly half of the domains anyone pastes are not readable Shopify storefronts. Forty-three brand-name guesses were tried on 2026-09-23, the way anyone builds a first list, and twenty answered with a catalogue. The other twenty-three failed in six distinct ways.
Running the Shopify Product & Variant Scraper over an unfiltered list means paying to discover that. Running this first costs $0.0008 a domain: five thousand domains is $4, against roughly $60 of catalogue scraping spent on the ones that were never going to answer.
And for the ones that do answer, this tells you what reading them is worth before you commit:
That is a real run, over live domains, on 2026-09-23.
What you get
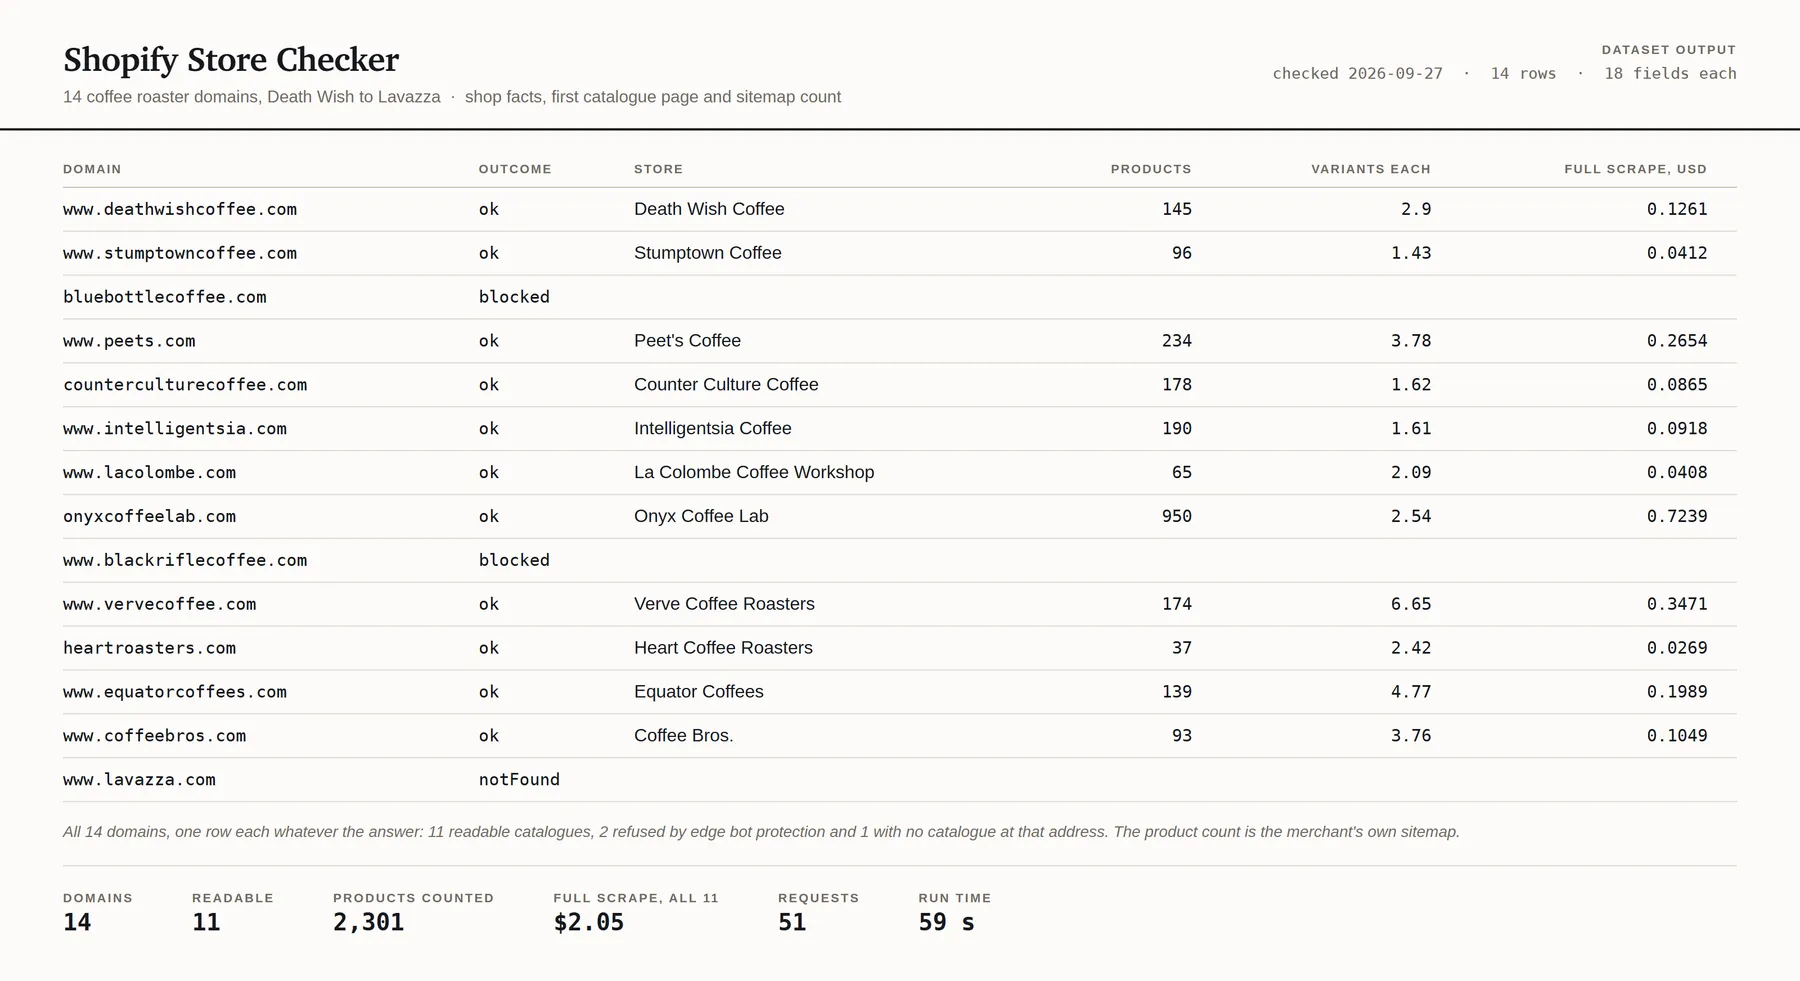
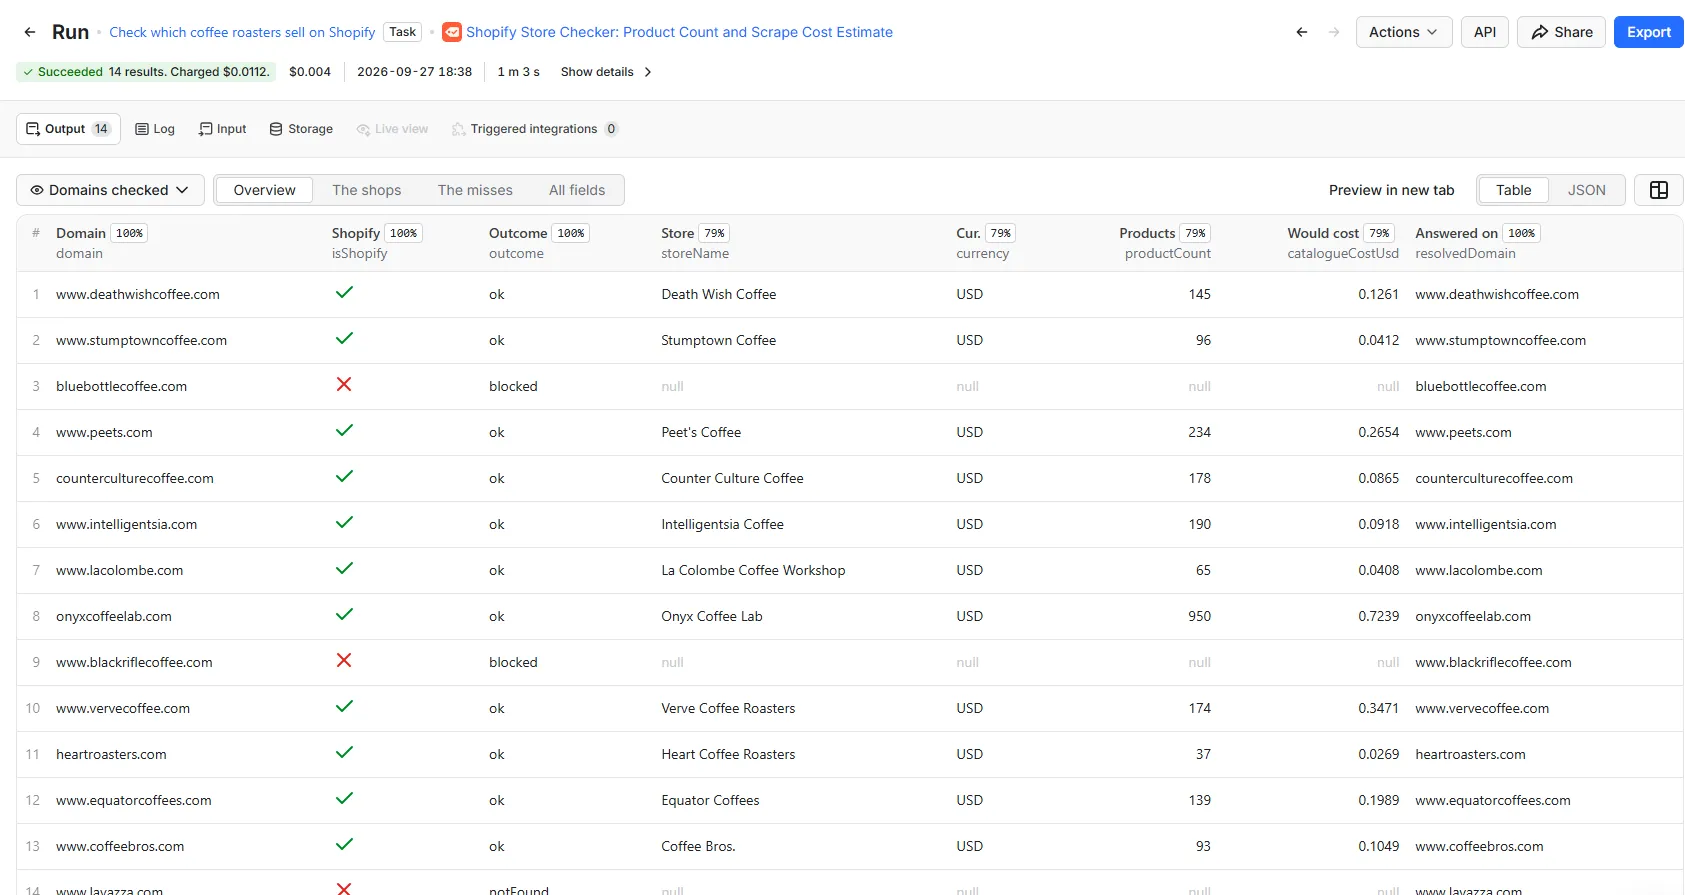
One row per domain.
| Field | Description |
|---|---|
domain | The domain you asked about |
resolvedDomain | The host that answered. Different when the apex redirects to the www |
isShopify | Whether the catalogue endpoint answered with a product list |
outcome | Which of the ways a domain can answer this one answered. See below |
statusCode | What the catalogue endpoint answered with |
storeName / storeCountry | The shop's own name and country, as it states them |
myshopifyDomain | The shop's platform identity, stable when it changes its public domain |
currency | ISO-4217, read from the shop rather than guessed from its country |
productCount | How many products the merchant lists in their own public sitemap. Empty when not counted |
variantsPerProduct | Measured on the first page of the catalogue |
catalogueCostUsd | What a full catalogue run would charge, at the free-plan rate. Empty when not counted |
detail | A one-line explanation, on the rows that need one |
The outcomes, and what each one means for your list
| Outcome | What it means | Worth retrying |
|---|---|---|
ok | A readable catalogue. This is the list you want | |
empty | A real Shopify shop with nothing in stock. Still a shop | |
notFound | No catalogue at that address. Not Shopify, or the merchant turned it off | |
notShopify | A live site that answered 200 and served a web page | |
blocked | Edge bot protection refused us. Not worked around | |
rateLimited | We were asked to slow down | Yes |
unavailable | A 5xx. The shop is having a bad day | Yes |
isShopify answers "can you read it", not "what platform is it on". A shop that is plainly
Shopify and sits behind Cloudflare comes back false with an outcome of blocked, because the
second question is not one this Actor can answer honestly from outside, and a column that
implied otherwise would be worse than no column.
About the product count
It comes from the merchant's own public sitemap, not from walking the catalogue. That is one or two small requests instead of up to seven large ones, and it is a more honest number: measured across six stores, the catalogue endpoint returned between zero and ten more products than the sitemap, and every extra read was an app-generated non-product such as a shipping-protection contract or a bundle-builder placeholder.
So productCount is a floor on what a catalogue run yields, and a fair estimate of what it is
worth.
A store that sells in several countries lists a separate product sitemap for each one:
liquiddeath.com lists 201 and www.aloyoga.com 1,290. The count is for the store's primary
market, which is the catalogue a run over that domain reads, and it costs one request per part of
that market's own sitemap rather than one for every country.
With the count switched off, productCount and catalogueCostUsd are empty, and they are
also empty when a store's sitemap cannot be read. The first page of the catalogue is not a count:
it stops at 250 products, and an estimate built on it would quote a large store a fraction of
what reading it costs.
variantsPerProduct is measured on the first page only, and it is the main source of error in
the cost estimate. catalogueCostUsd uses the free-plan rate, which is the dearest rung, so
the estimate is never lower than the bill.
Input
| Setting | What it does |
|---|---|
| Domains | One per line. A bare domain, or any URL on the store. Up to 2,500 |
| Count each store's products | On by default. Adds the sitemap count and the cost estimate. Off, both are empty |
| Dry run | Count what you would get and what it would cost, then stop |
| Maximum results | Hard cap on rows. The run stops the moment it is reached |
| Maximum spend (USD) | Hard cap on cost. The run stops before exceeding it |
The dry run here is exact rather than estimated. One row per domain, known before a single request goes out, so the number you see is the number you will get.
Pricing
From $0.56 per 1,000 domains checked, and nothing else. No per-run fee, no charge for compute or retries.
| Your Apify plan | Per domain | Per 1,000 domains |
|---|---|---|
| Free | $0.0008 | $0.80 |
| Bronze | $0.00072 | $0.72 |
| Silver | $0.00064 | $0.64 |
| Gold | $0.00056 | $0.56 |
| Platinum | $0.00056 | $0.56 |
| Diamond | $0.00056 | $0.56 |
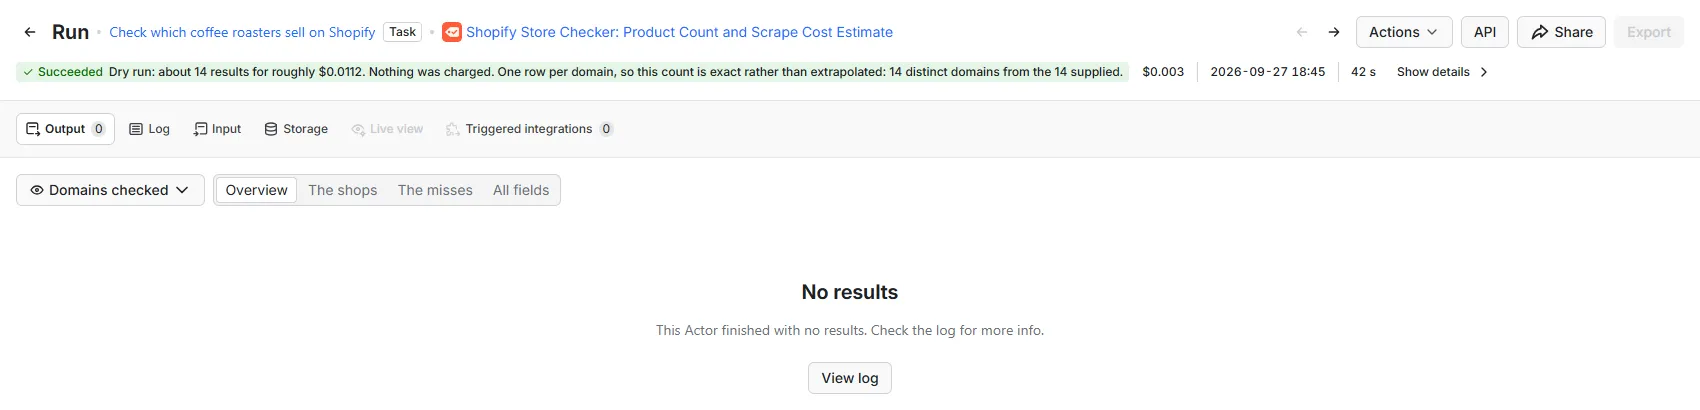
The status line is the estimate. A dry run writes no rows, so its results table stays empty, and it charges nothing.
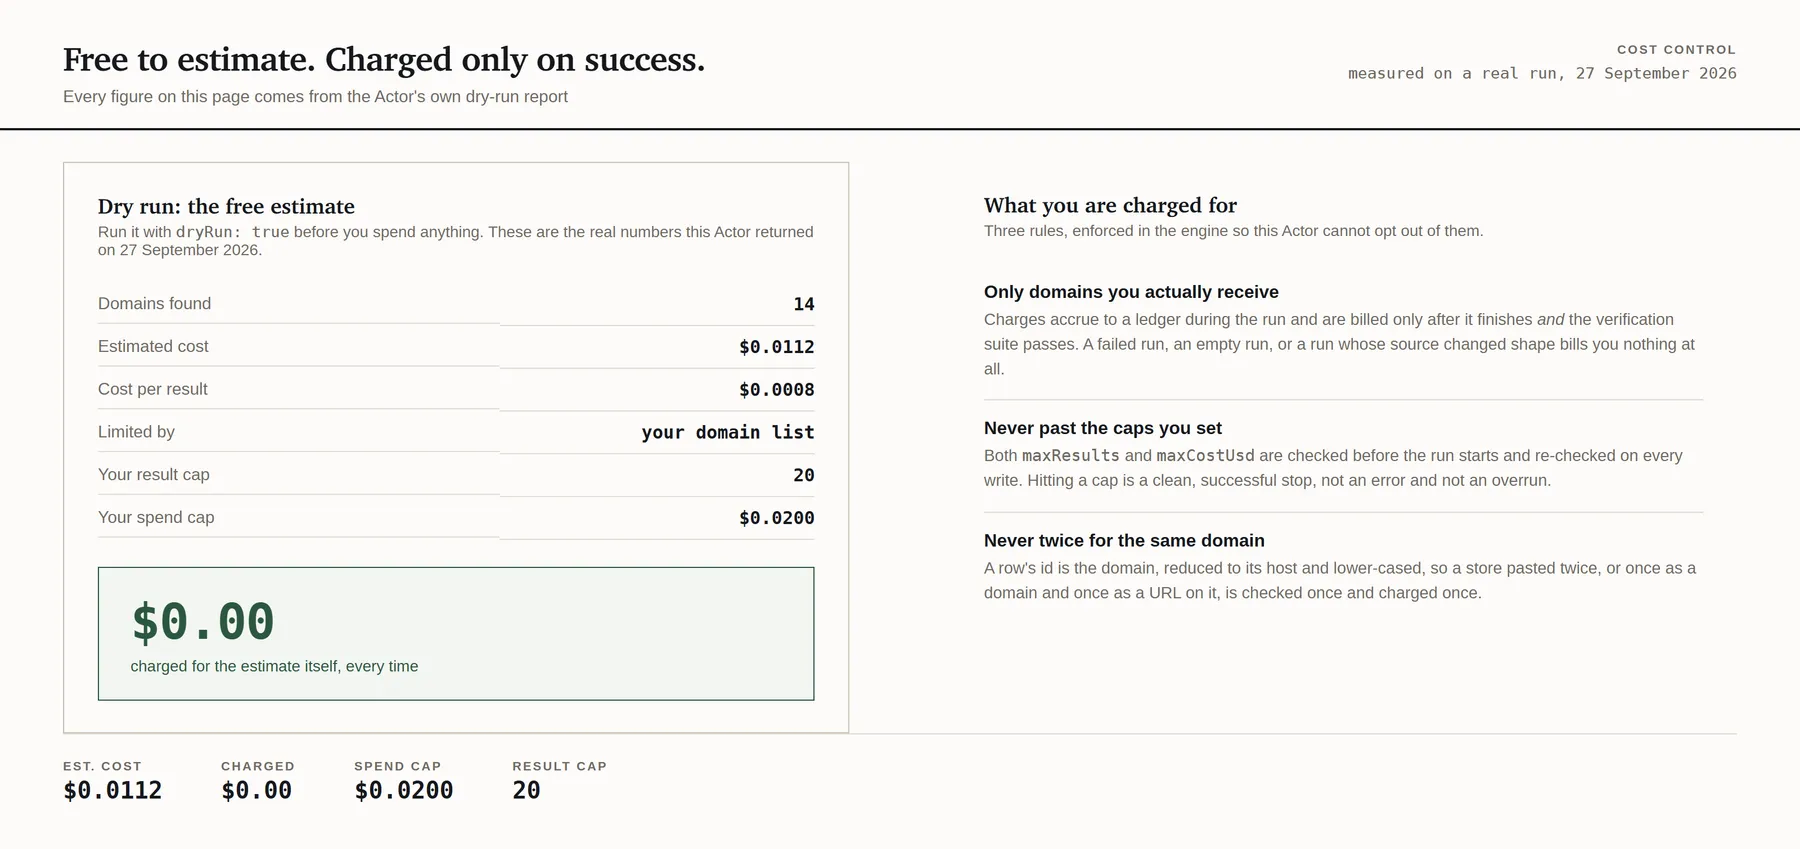
Every domain is charged, whatever the answer is, and this listing is the one place that is true across this developer's Actors. Everywhere else, a source that returned nothing costs nothing, because there were no rows. Here the row is the answer: twenty-three of the forty-three domains measured were not readable storefronts, and knowing which twenty-three is the whole job. Charging only for the hits would mean charging double for them, which is the same money with a better story.
A domain listed twice is checked once and billed once.
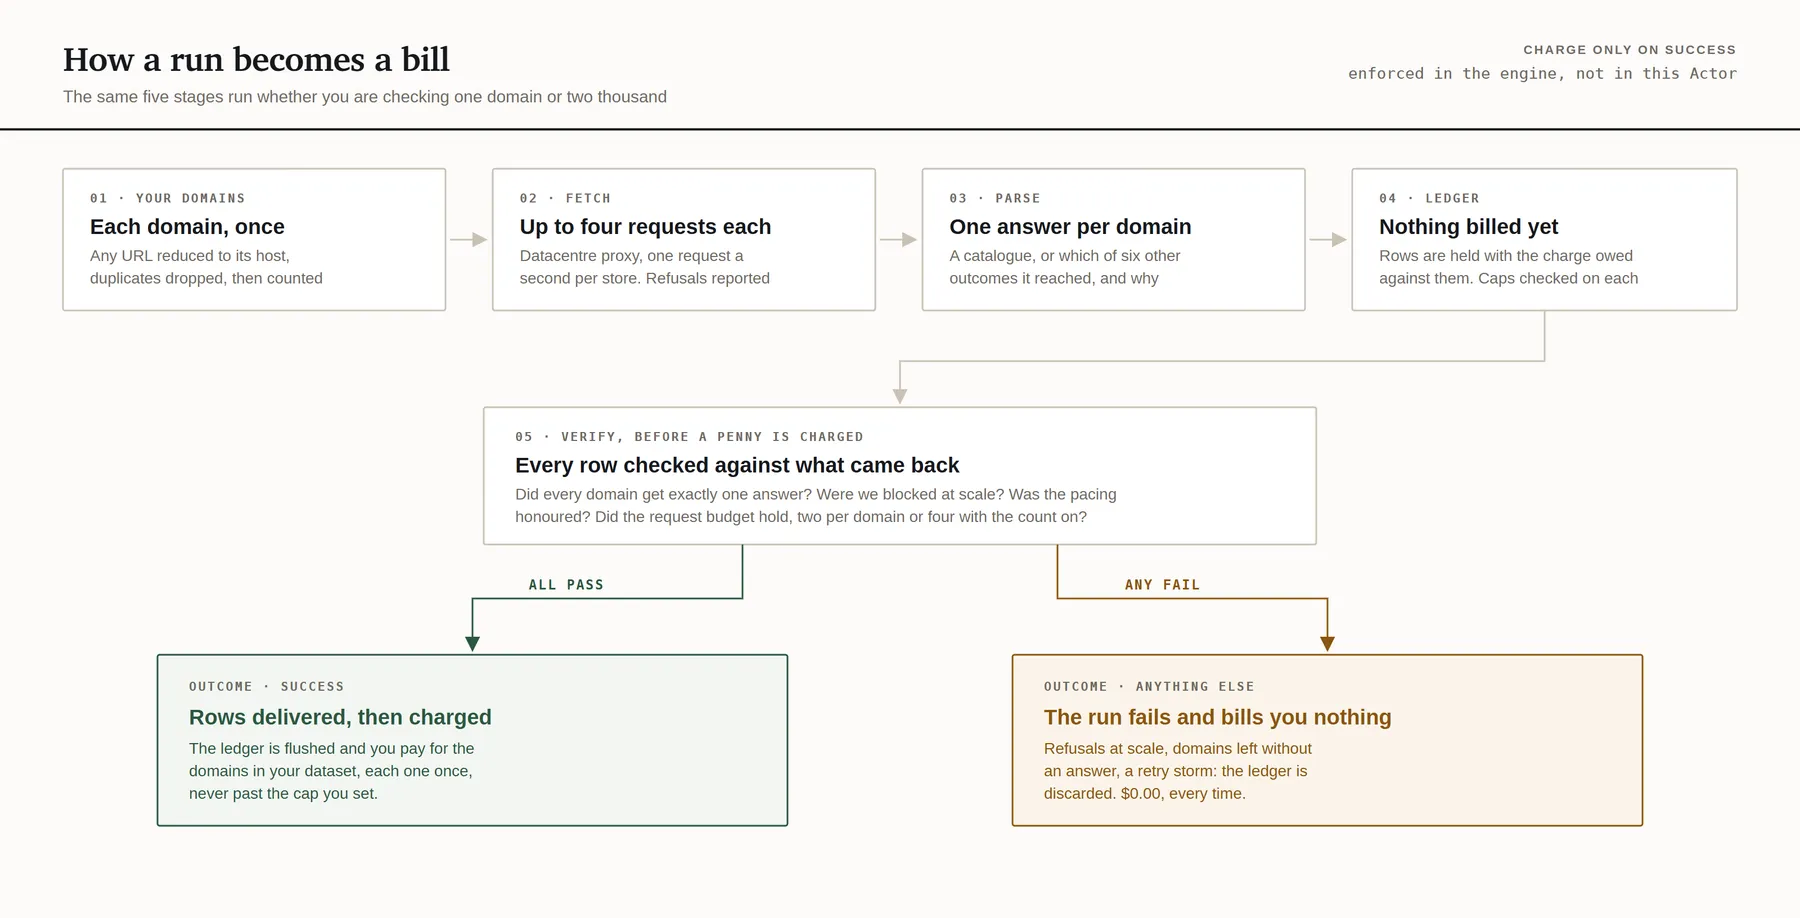
What you are not charged for is a wrong answer. If most of a run comes back blocked, that is
a fact about our exit IP rather than about your list, and the run fails and bills nothing rather
than selling you several thousand rows about somebody else's shop.
What happens when the source changes
Every run is checked against what a healthy run looks like, and a run that fails a check is not billed:
- Every domain got an answer. One row per domain is this Actor's entire promise, so a run that silently returned 900 rows for 1,000 domains would have dropped a hundred answers and looked complete doing it.
- We are not being blocked at scale, per the paragraph above.
- The pacing was honoured. One request per second per domain. A run here touches up to 2,500 other people's shops, and the run fails its own health check if two requests to one of them ever go out closer together.
- The request budget held. Two requests per domain, or up to four with the product count on. A number far above that means a retry storm, which costs compute rather than your bill, and you should still know about it.
How it reads the sources
Through the public endpoints every Shopify storefront serves on the merchant's own domain:
/meta.json for the shop's own facts, /products.json for the catalogue, and the merchant's own
/sitemap.xml for the product count. No login, no token, no session, no browser, and no personal
data of any kind.
A store that refuses us is reported, never worked around. On the seventeen stores whose
robots.txt was read on 2026-09-23, every path this Actor fetches is permitted, and none of them
publishes a crawl delay that applies to a general-purpose agent. A 403 from edge bot protection is
a shop saying no, and the answer to it is a row in your dataset rather than a different exit IP.
robots.txt is a crawling policy rather than a contract, and every merchant has their own terms.
The claim here is the narrow one that is actually true: this Actor fetches paths the store's own
robots.txt permits, at one request per second, with no login and no personal data.
Limits
- 2,500 domains per run.
- You supply the domains. This Actor checks a list; it does not find one. Knowing which domains are worth checking is a different product, and a dearer one.
- It cannot tell you a shop is Shopify if the shop will not talk to us.
blockedmeans exactly that and nothing more. - One currency per store. A shop that serves different prices by geography states one currency, and what you get is the one it stated to the run.
Run it on a schedule
Save your input as a task and add an Apify Schedule to run it daily, weekly or hourly. When a run finishes, Apify's integrations can pass its rows to Google Sheets, Zapier, Make or n8n, and a webhook can call your own endpoint. A run that fails costs nothing and does not fire an integration or webhook set to run on success.
Most lists need one run, before a catalogue scrape. On a schedule it checks the whole list again
every time, and every domain is charged whatever the answer. rateLimited and unavailable are
the two outcomes worth checking again later.
Use it from an AI agent
Apify's MCP server loads this Actor as a single tool:
An agent with it can run the Actor with the same inputs as the form, dry run and spend cap included, and read the answer for each domain, billed to your Apify account at the prices above.
FAQ
How much does it cost to check whether a site is a Shopify store?
$0.80 per 1,000 domains on Apify's free plan, and $0.56 per 1,000 on Gold and above, with no start fee. Every domain is charged whatever the answer, because "not a Shopify store" is the answer. Apify's free plan gives $5 of usage a month, which at $0.0008 a domain is 6,250 domains. A domain listed twice is billed once, a failed run and an empty run cost nothing, and the dry run is free and exact.
Is it legal to check Shopify stores this way?
This Actor reads public endpoints every Shopify storefront serves on the merchant's own domain:
/meta.json, /products.json and the merchant's /sitemap.xml, with no login, no token and no
personal data. A store that refuses a request is reported, never worked around. Every merchant has
their own terms, whether a particular use is lawful depends on what you do with the data and where
you are, and nothing here is legal advice.
Does isShopify: false mean the site is not on Shopify?
Not always. It answers "can you read it", not "what platform is it on": a Shopify shop behind bot
protection comes back false with the outcome blocked.
How accurate is the scrape cost estimate?
productCount comes from the merchant's own sitemap and is a floor on what a catalogue run yields.
catalogueCostUsd uses the free-plan rate, the dearest rung, and variants per product measured on
the first catalogue page, which is its main source of error.
Can it find Shopify stores for me?
No. It checks a list you supply; it does not find one.
Other Actors from this developer
Every one has the same free dry run and spend cap, and none charges for a failed run.
More for Shopify stores:
- Shopify Product Scraper: every product and variant from a list of Shopify stores, with SKU, price, compare-at price and stock
- Shopify Price & Stock Tracker: price and stock for the product pages you choose, one row per variant, built to run on a schedule
And for other data:
- Google Flights Scraper: live Google Flights fares for any route and date
- RSS Feed Reader: RSS, Atom and RDF feeds in one table
- Domain Expiry, WHOIS & DNS Lookup: expiry dates, registrar and live DNS for a list of domains
Support and feature requests
Found a bug, need another platform checked, or want a field adding? Email actors@montyburrows.com. Feature requests are welcome and usually quick.


