
Bulk File Downloader — Download Files from URLs
Pricing
from $33.50 / 1,000 file downloadeds
Bulk File Downloader — Download Files from URLs
Download files in bulk from a list of links, or every PDF, ZIP, CSV or Excel file a page links to. Each file is saved with a download link, file name, size, type, SHA-256, Last-Modified and ETag. Duplicates are skipped. Part of NexGen Signal — data tools and official-source data products
Pricing
from $33.50 / 1,000 file downloadeds
Rating
0.0
(0)
Developer
NexGen Signal
Maintained by CommunityActor stats
0
Bookmarked
3
Total users
2
Monthly active users
20 hours ago
Last modified
Categories
Share
📦 Bulk File Downloader — Download Files from URLs
Give a list of file links, or web pages plus the file types you want from them, and get each file downloaded, checksummed and saved with a download link: file name, extension, content type, size, SHA-256, Last-Modified and ETag.
Any type works: PDF, ZIP, CSV, Excel, Word, JSON, XML, audio, video. Set linkExtensions (for example pdf, zip, xlsx) and every link on your pages with those extensions is collected and downloaded. Files are streamed to disk and to storage, so large files (up to 2 GB) do not need large memory. The same file reached by two links is delivered once.
The unit of output is one file delivered. Files that are skipped (too big, wrong type, duplicate, blocked by robots.txt, unreachable) are not billed.
Who buys this and for what job
- Analysts pulling every report, form or data file a government or company page links to.
- Compliance and legal teams archiving published documents with hashes and dates as evidence.
- Data engineers fetching CSV, ZIP and Excel files into pipelines on a schedule.
- Researchers collecting papers and attachments from a list of pages.
Buyers usually search for this as "bulk file downloader", "download files from URL list" or "download all PDFs from a website".
📊 Sample Output
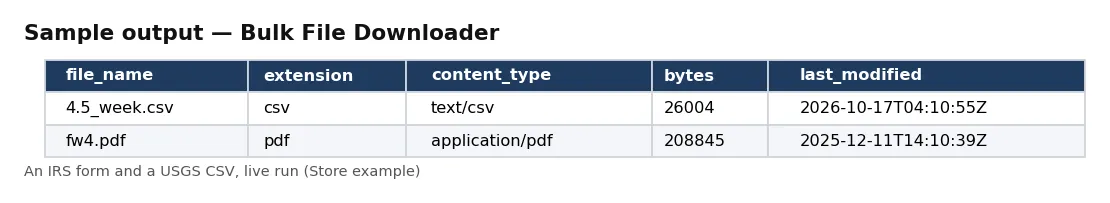
| file_name | extension | content_type | bytes | last_modified |
|---|---|---|---|---|
| 4.5_week.csv | csv | text/csv | 26004 | 2026-10-17T04:10:55Z |
| fw4.pdf | application/pdf | 208845 | 2025-12-11T14:10:39Z |
Rows from live run h1ZDF1gkKSmBbqW2O on Apify (the Store example: an IRS form and a USGS earthquake CSV). Notice the Last-Modified dates: the IRS form is from December 2025, the USGS file was refreshed minutes before the run.
✅ What you get
Every field of each record:
record_id,sha256— file hash (record_id is its first 24 characters).url,final_url,found_on_page— the link, where the file was served from after redirects, and the page it was found on (for page links).file_name,extension,content_type,bytes— the server's file name (Content-Disposition, else the address), extension, type and size.last_modified,etag— the server's Last-Modified date (UTC) and ETag, for change tracking.file_key,file_url— key and link of the saved file in the run's key-value store (empty when saveFiles is off).downloaded_at— when it was downloaded (UTC).
⚙️ Sample inputs
Two direct files (the Store example)
Each link is downloaded as it is.
Every PDF a page links to
Collects the page's .pdf links, in page order.
Check files for changes without storing them
Size, hash, Last-Modified and ETag only.
Input fields:
| Field | Meaning |
|---|---|
fileUrls | file links, or pages when linkExtensions is set (up to 10,000). |
linkExtensions | file types to collect from pages, e.g. pdf, zip, csv. Empty = download every link as it is. |
maxLinksPerPage | file links taken per page (default 100). |
allowedExtensions | keep only these types (checked after download). Empty = all. |
maxFileMb | skip files bigger than this (default 500, up to 2,000). |
saveFiles | store files with links (default true). |
maxFiles | stop after this many delivered files (default 1,000). Each delivered file is billed. |
🧾 JSON sample record
🔧 How it works
Files are downloaded 4 at a time and streamed to a temporary file while the SHA-256 is computed, then streamed into the run's key-value store under file-<hash>.<ext>. The temporary file is deleted straight away.
Every run reads each host's robots.txt first: a path it disallows is skipped, listed in the run receipt and never charged. Only public internet addresses are fetched (no private, loopback or cloud-metadata addresses, checked again on every redirect). No logins, no CAPTCHA solving, no proxies.
Saved files go to the run's own key-value store. If your Apify account keeps storages private, add your API token to the link (?token=…) or open the store from the run in Apify Console.
Delivery is pushed first and charged after. The run receipt (RUN_RECEIPT) lists every link with its outcome (and, for pages, how many file links were found and what happened to each), the robots.txt result per host, and the delivered and charged counts.
💰 Pricing example
Per file delivered, no start fee, no monthly charge:
| Apify plan | Price per file |
|---|---|
| Free | $0.05 |
| Bronze | $0.045 |
| Silver | $0.04 |
| Gold, Platinum, Diamond | $0.0335 |
- 10 files: $0.50 on the Free plan, $0.335 on Gold.
- 1,000 files: $50.00 on Free, $33.50 on Gold.
- 10,000 files: $500.00 on Free, $335.00 on Gold.
Coverage and size. Proof runs on 17 Oct 2026: 40 IRS PDFs collected from two IRS pages in about 7 seconds; a 3.1 MB file was skipped with maxFileMb 1; a second link to the same CSV was recognised as the same file and not billed again.
⚖️ Legal & ToS
Files belong to their owners. You choose the links. Make sure you have the right to download and use the content you point it at; the actor fetches only what you give it (and, where you turn it on, what those pages link to).
Every run reads each host's robots.txt first: a path it disallows is skipped, listed in the run receipt and never charged. Only public internet addresses are fetched (no private, loopback or cloud-metadata addresses, checked again on every redirect). No logins, no CAPTCHA solving, no proxies.
❓ FAQ
Does it unzip archives? No. Files are stored exactly as downloaded.
How big can a file be? Up to 2,000 MB (maxFileMb). Files are streamed, not held in memory.
Does it follow links more than one page deep? No. Pages you give are read once for file links; it does not crawl.
🆘 Troubleshooting
- file_url answers 403 — Your account keeps storages private: add
?token=YOUR_TOKENor open the store from the run. - A page link was saved as an .html file — Set linkExtensions to collect the files the page links to.
- SOURCE UNAVAILABLE — None of your links could be reached after retries. Nothing was charged.
🔗 Related Actors
- Website Tech Stack Detector — what a site is built with
- Website Contact Scraper — contact details from website lists
- PR Newswire Scraper — press releases by company or topic
🏢 About NexGen Signal — data tools and official-source data products on Apify. Browse the catalog: apify.com/nexgensignal
⭐ Found this useful?
If this actor saved you time, a rating on its Apify Store page helps other buyers find it.
Part of NexGen Signal — data tools and official-source data products.


