

Keka Careers Jobs Exporter
Pricing
from $33.50 / 1,000 job records
Keka Careers Jobs Exporter
One structured job record per active opening from employer career portals powered by Keka Hire — title, company, location, apply link. Keyless, logged-out, robots-honoured. Pay per job.
Pricing
from $33.50 / 1,000 job records
Rating
0.0
(0)
Developer
NexGen Watch
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Share
🧑💻 Keka Careers Jobs Exporter
One structured job_record per active opening from employer career portals powered by Keka Hire — keyless, logged-out, robots-honored.
Difference: One normalized record per Keka active requisition across one or many tenants — employer + host identity, title, department, job type, experience, org-level location (city/state/country), salary range, skills, excerpt, description, and the public job URL. The data is read only from Keka's robots-ALLOWED /careers/ path (Keka disallows root / and allows /careers/; the careers app itself serves its JSON under /careers/api/...), never from the disallowed root API.
Output is one keka_job row per result; billing is pay-per-event, the value event being one job record (a $0.02 start fee per run, then $0.05 per job record).
📊 Sample Output
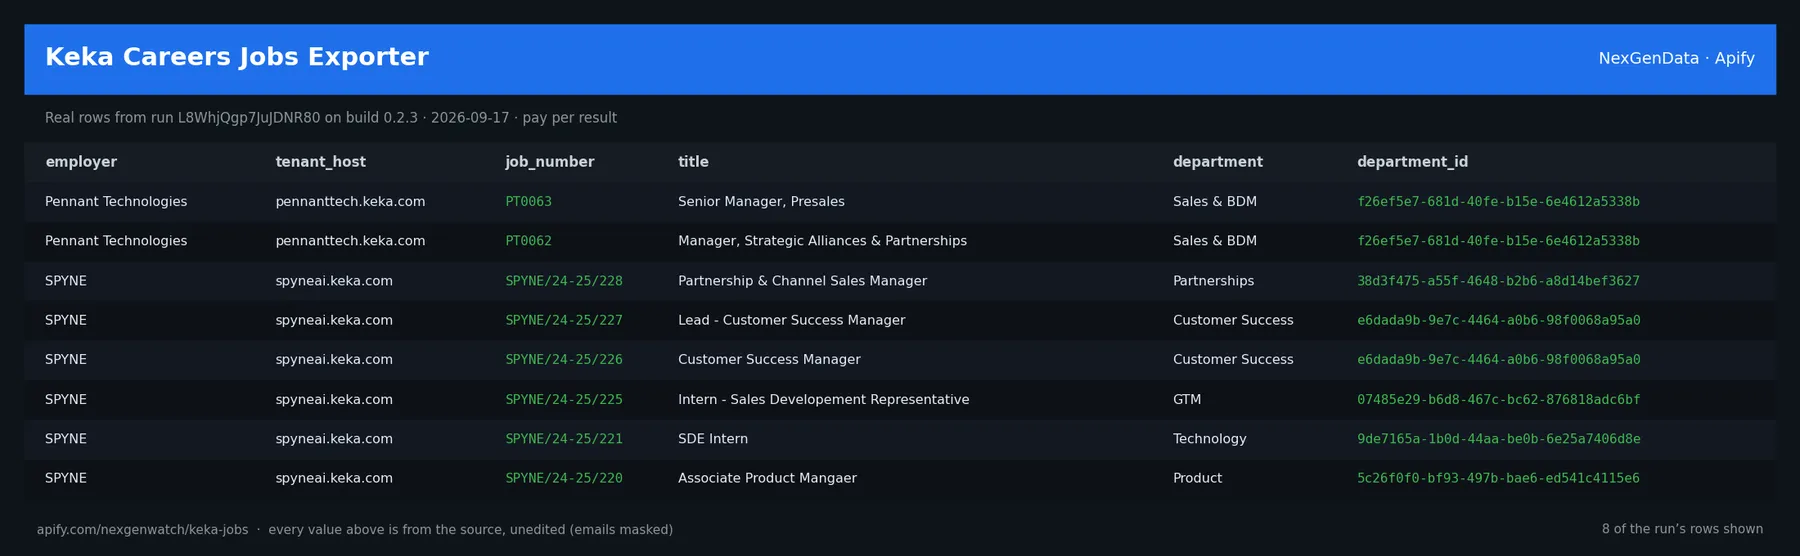
Real rows from run L8WhjQgp7JuJDNR80 on build 0.2.3 (2026-09-17), the same input as the Quick start below — every value is as the source published it (emails masked, long text shortened):
| employer | tenant_host | job_number | title | department | department_id |
|---|---|---|---|---|---|
| Pennant Technologies | pennanttech.keka.com | PT0063 | Senior Manager, Presales | Sales & BDM | f26ef5e7-681d-40fe-b15e-6e4612a5338b |
| Pennant Technologies | pennanttech.keka.com | PT0062 | Manager, Strategic Alliances & Partnerships | Sales & BDM | f26ef5e7-681d-40fe-b15e-6e4612a5338b |
| SPYNE | spyneai.keka.com | SPYNE/24-25/228 | Partnership & Channel Sales Manager | Partnerships | 38d3f475-a55f-4648-b2b6-a8d14bef3627 |
| SPYNE | spyneai.keka.com | SPYNE/24-25/227 | Lead - Customer Success Manager | Customer Success | e6dada9b-9e7c-4464-a0b6-98f0068a95a0 |
| SPYNE | spyneai.keka.com | SPYNE/24-25/226 | Customer Success Manager | Customer Success | e6dada9b-9e7c-4464-a0b6-98f0068a95a0 |
| SPYNE | spyneai.keka.com | SPYNE/24-25/225 | Intern - Sales Developement Representative | GTM | 07485e29-b6d8-467c-bc62-876818adc6bf |
| SPYNE | spyneai.keka.com | SPYNE/24-25/221 | SDE Intern | Technology | 9de7165a-1b0d-44aa-be0b-6e25a7406d8e |
| SPYNE | spyneai.keka.com | SPYNE/24-25/220 | Associate Product Mangaer | Product | 5c26f0f0-bf93-497b-bae6-ed541c4115e6 |
The run finished with the status message: NORMAL: 20 unique rows (0 duplicates collapsed) from None. billable=20
✅ What you get
Each row is flat JSON with these fields (from the dataset schema and the sample run; a field the source does not publish for a given row is null):
record_type(string) — e.g.keka_jobemployer(string/null) — e.g.Pennant Technologiestenant_host(string/null) — e.g.pennanttech.keka.comjob_id(string/integer/null) — e.g.39543job_number(string/null) — e.g.PT0063title(string/null) — e.g.Senior Manager, Presalesdepartment(string/null) — e.g.Sales & BDMdepartment_id(string/null) — e.g.f26ef5e7-681d-40fe-b15e-6e4612a5338bjob_type(string/null) — e.g.2experience(string/null) — e.g.8-15location(string/null) — e.g.Corporate Officecity(string/null) — e.g.Hyderabadstate(string/null) — e.g.TGcountry(string/null) — e.g.Indiasalary_range(string/null) — e.g.INR 0.00 - 0.00salary_min(string/null) — e.g.0.0salary_max(string/null) — e.g.0.0salary_currency(string/null) — e.g.INRskills(string/null) — null in every sample rowexcerpt(string/null) — e.g.Sr Manager, Presales Pennant is looking for highly experienced and seasoned Senidescription(string/null) — e.g.Sr Manager, Presales Pennant is looking for highly experienced and seasoned Senipublished_on(string/null) — e.g.2026-08-11T10:31:39.127Zpublished_since_days(string/null) — e.g.37job_url(string/null) — e.g.https://pennanttech.keka.com/careers/39543source(string/null) — e.g.keka-jobsrelease_date(string/null) — null in every sample rowsource_url(string/null) — e.g.https://pennanttech.keka.com/careers/observed_at(string/null) — e.g.2026-09-17T17:32:03Zattribution(string/integer/null) — e.g.Source: employer career portals powered by Keka Hire (public, logged-out /careerterminal(string/integer/null) — null in every sample rowreported_total(string/integer/null) — null in every sample rowraw_seen(string/integer/null) — null in every sample rowduplicates(string/integer/null) — null in every sample rowunique_found(string/integer/null) — null in every sample rowdelivered(string/integer/null) — null in every sample rowscope(string/integer/null) — null in every sample rownote(string/integer/null) — null in every sample rowlicense(string/integer/null) — null in every sample row
What you get
One job_record per active opening, deduplicated on tenant host + job id. A RUN_RECEIPT key-value record carries the tenants read, scope, attribution, and totals.
Every run also writes a RUN_RECEIPT record to its key-value store with the source checks it made and the counts it charged — diagnostics never land in the paid dataset.
⚙️ Sample inputs
1. Quick start — the Store example (this is what the sample above came from)
The sample run charged exactly: 1 × $0.02 apify-actor-start + 20 × $0.05 job_record = $1.02 on the Free tier — every delivered row was billed.
2. A smaller, narrowed run
Caps the run at 5 rows — about $0.27 on the Free tier ($0.02 start + 5 × $0.05).
3. A full-size run
Up to 5000 rows (the schema default for maxRecords) — about $250.02 on the Free tier ($0.02 start + 5000 × $0.05) if the source has that many.
🧾 JSON sample record
One real record from run L8WhjQgp7JuJDNR80, exactly as it lands in the dataset (emails masked, long text shortened):
🔧 How it works
Transport. Plain HTTPS from the Apify platform, no proxy. robots.txt is read first and a disallowed path is never fetched. Every request carries an identified contact User-Agent. Pacing: CRAWL_DELAY=0.0.
Charging. Each job record is charged at the moment it is pushed (job_record); a row that fails to charge is not delivered, so the dataset count always equals the charged count.
How it behaves
For each tenant, the company identity (/careers/api/organization/{portal}/careerportalinfo) and the active openings (/careers/api/jobs/{portal}/active) are fetched keyless and logged-out under the robots-permitted /careers/ path. Zero-auth only: if any tenant's door returns an auth challenge (401/403), a login/HTML body instead of JSON, or a token wall, the run STOPS loudly for that tenant with no workaround. A title-bearing canary rejects a drifted feed. Delivery is bounded to maxRecords.
Source
https://{tenant}.keka.com/careers/api/jobs/{portal}/active (robots: Disallow /, Allow /careers/)
Attribution
Source: employer career portals powered by Keka Hire (public, logged-out /careers/ listings).
What is not done. No login, no cookie or CAPTCHA bypass, no private or personal-account data, no browser automation.
💰 Pricing example
| Event | Free | Bronze | Silver | Gold |
|---|---|---|---|---|
Actor Start (apify-actor-start) | $0.02 | $0.02 | $0.02 | $0.02 |
Job record (job_record) | $0.05 | $0.04 | $0.04 | $0.03 |
Worked at the live Free-tier price:
- 8 job records: $0.02 start + 8 × $0.05 = $0.42
- 25 job records: $0.02 start + 25 × $0.05 = $1.27
- 5000 job records: $0.02 start + 5000 × $0.05 = $250.02
A run that delivers zero rows charges the $0.02 start fee only. A BLOCKED run (source refused) fails loud and charges no value event. The start fee is charged once per GB of run memory; the default run memory is 1024 MB.
Yield on the sample run: NORMAL: 20 unique rows (0 duplicates collapsed) from None. billable=20. maxRecords is a hard ceiling on what is delivered and billed, never a target.
⚖️ Legal & ToS
This actor reads public data only. It collects only what the source publishes to any visitor, keeps to the source's robots rules (checked on every run), identifies itself with a contact User-Agent, and does not access accounts, private data or anything behind authentication. Use the output in line with the source's terms and your local law; the intended use is B2B research and monitoring.
❓ FAQ
Q: Do I need an API key or a login?
A: No. the input schema has no key field and the actor carries no secrets.
Q: Why did my run return 0 rows?
A: Read the run's status message. GENUINE_EMPTY means the source was read and had nothing in scope for your input; BLOCKED means the source refused and the run failed without billing a value event — retry later or narrow the input. A zero-row run bills the start fee only.
Q: How many rows can one run return?
A: Up to maxRecords (default 5000). Raise the cap for a bigger run; you pay per delivered row.
Q: How fresh is the data?
A: Every run reads the source live at run time; nothing is cached between runs. Put it on a schedule for a continuous feed.
Q: What formats can I export?
A: The dataset downloads as JSON, CSV, Excel, XML or RSS from the run's Dataset tab or the Apify API, and any run can push to a webhook or integration.
Q: How is this different from the other ATS job feeds actors?
A: Same output shape and billing model; this one covers Keka Careers Jobs Exporter. The siblings under Related Actors cover the other sources or slices — run several on one schedule for a combined feed.
Q: Are there rate limits?
A: The actor paces itself against the source (CRAWL_DELAY=0.0) and honours its robots rules; there is no per-buyer limit beyond your Apify plan's concurrency.
🆘 Troubleshooting
- Run FAILED with BLOCKED → the source refused the request or changed its page shape → nothing was billed beyond the start fee; retry after a while, and if it persists open an Issue with the run id.
- Status says CAPPED → your cap (
maxRecords) was reached → raise it for a bigger run. - Input validation error on start → a field is outside the schema's allowed values → start from the Quick start block and change one field at a time.
- Run TIMED-OUT → a very wide request on a slow day → raise the run timeout in Run options or narrow the input; what was delivered before the timeout is still in the dataset.
🔗 Related Actors
- HireBridge Jobs Scraper — One structured jobrecord per LIVE job posting from a public, logged-out ATS board. Public, robots-honoured
- JazzHR Job Feed — Any Employer Board — Scrape jobs from any JazzHR employer careers board. One structured record per public posting — title, location, link. No API key; pay per job
- Jobvite Job Feed — Any Employer Board — One structured jobrecord per public posting on a Jobvite employer board. You supply a tenant (or list of tenants); the actor reads that board's publi…
- LinkedIn Job Postings API — Public Hiring Data — Query public LinkedIn job postings by role, location, employment type, and posting age. Receive normalized records through an Apify dataset or API. P…
- Manatal (careers-page.com) Job Feed — Any Employer Board — Manatal (careers-page.com) Job Feed — Any Employer Board
- Oracle Recruiting Jobs Exporter — One structured job record per open requisition across Oracle Recruiting Cloud career sites, read from the keyless candidate-experience contract — tit…
- 🏢 About NexGenData — NexGen Watch is NexGenData's fleet of 256 public monitoring and lookup actors built on official sources, pay-per-result. Browse the catalog at apify.com/nexgenwatch.
⭐ Found this useful?
If this actor saved you a manual check, a quick review on the Apify Store helps other teams find it. Feature request or a source that changed? Open it from the Issues tab — every one is read.


