
Google News Scraper: Articles, Real Publisher URLs, Dates
Pricing
from $0.75 / 1,000 articles
Google News Scraper: Articles, Real Publisher URLs, Dates
Scrape Google News articles by keyword, topic, city, country and language. Each row has the title, publisher, ISO 8601 date and the publisher's own article URL (the Google link if decoding fails). $1.00 per 1,000 articles, pay per result.
Pricing
from $0.75 / 1,000 articles
Rating
0.0
(0)
Developer
Red Fox Scout
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
a day ago
Last modified
Categories
Share
Scrape Google News articles by keyword, topic or city, in the language and country edition you choose. Each row has the title, publisher, ISO 8601 date and the publisher's own article link, plus time ranges, exact dates and keyword searches past Google's usual 100-article feed. No login, no cookies, no API key.
Price: $1.00 per 1,000 articles. Failed searches and error rows are free. Apify's free plan ($5 monthly credit) covers about 5,000 articles a month.
Questions it answers
- Which publishers covered a company or product this week, and when?
- What did German news say about a topic in the last 7 days?
- What are the latest headlines for a city or a news section?
- Which outlets covered this subject, and what did each one headline?
Who uses this
- 📰 Media monitoring and PR teams: track which publishers mention a brand, product or event, with dates and links.
- 📊 Analysts and researchers: build a dated dataset of headlines on a topic, by country and language.
- 📍 Local businesses and newsletters: pull the latest headlines for the cities they serve.
- 🤖 AI agent builders: give an agent a news feed with real article links.
Why this Google News Scraper
- 🔗 Publisher links: each row links to the publisher's own article when Google's decoder resolves it. Otherwise the row keeps Google's link and says so with
resolved: false. - 🕒 Dates in ISO 8601 (UTC): ready to sort, filter and join.
- 🌍 Any edition: 20 verified language and country pairs, such as de-DE, ja-JP and en-GB.
- 📚 Past the 100-article feed: keyword searches read back day by day, up to 60 days.
- 📰 Related headlines: the other articles in the same story, with their publishers.
How to use the Google News Scraper
- Click Try for free (a free Apify account is enough).
- Enter keywords and cities, one per line, e.g.
"electric vehicles" OR EVorsite:reuters.com climate. Pick any topics you want. - Optional: set the language and country edition, a time range or exact dates.
- Click Start, then download as JSON, CSV or Excel, or schedule it for a daily feed.
Input
| Field | Default | What it does |
|---|---|---|
queries | – | Keywords or phrases, one per line. Google News operators work: "quoted phrase", OR, site: and intitle:. |
topics | – | Google News sections: TOP, WORLD, NATION, BUSINESS, TECHNOLOGY, ENTERTAINMENT, SPORTS, SCIENCE, HEALTH. |
locations | – | City or region names for local headlines, one per line, e.g. Berlin. |
language | en | Language of the edition, two letters, e.g. de. |
country | US | Country of the edition, two letters, e.g. DE. |
timeRange | any | Keyword searches only: any, 1h, 1d, 7d, 30d or 1y. |
dateFrom, dateTo | – | Keyword searches only: days as YYYY-MM-DD. Either or both. They override timeRange. |
resolveUrls | true | Swap Google's link for the publisher's URL. Off keeps every Google News link. |
maxItems | 100 | Articles per query, topic or city (max 1,000). |
Example (the input behind the output below):
Output
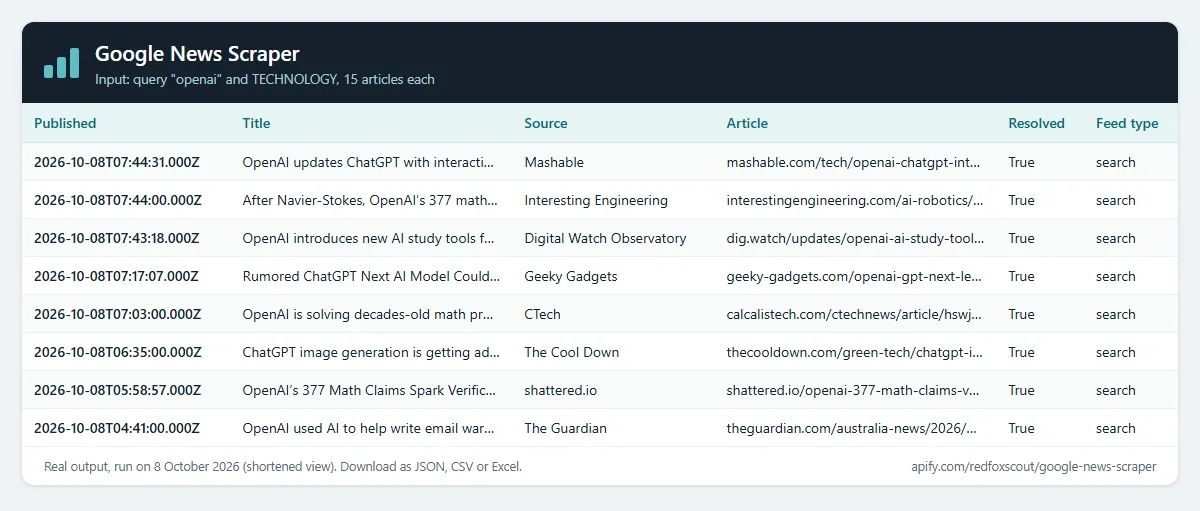
One row per article. A real row from that run (IDs and the Google link shortened):
url is the publisher's link when resolved is true, and the Google News link when it is false. feedType is search, topic, top or location. searchQuery names the keyword, topic or city that found the article.
Example tasks
Ready-made inputs you can open, change and run:
Editions and languages
The language and country pair picks the Google News edition. language: "de" with country: "DE" gives German news from Germany's edition. These pairs are verified: en-US, en-GB, en-IN, en-AU, en-CA, de-DE, fr-FR, es-ES, es-MX, it-IT, pt-BR, ja-JP, ko-KR, ar-AE, hi-IN, nl-NL, sv-SE, pl-PL, tr-TR, id-ID. Other pairs still run and write a warning to the log. If Google serves another country's edition instead, the search fails with a message rather than returning articles from the wrong country.
Time ranges and more than 100 articles
Google's keyword feed holds about 100 articles. For a keyword search above 100, the Actor reads one day at a time, back from your end date (or today) for up to 60 days, and stops after three empty days in a row. Last hour and Last 24 hours stay on the single feed. Each day is requested about two seconds after the last, so long searches take minutes.
How much does it cost?
$1.00 per 1,000 articles.
- 100 articles: about $0.10
- 1,000 articles: about $1
- 10,000 articles: about $10
Publisher-link resolution is included. Failed searches, error rows and articles repeated within one run are free. Articles whose link stays unresolved (resolved: false) are still articles, so they are charged.
Apify's free plan gives $5 of credit every month, enough for about 5,000 articles.
FAQ
Is this legal? It reads Google News's public RSS feeds and the public article pages Google serves to anyone, without signing in. It does not use cookies, solve CAPTCHAs or open publisher websites. The output holds headlines, publisher names, dates and links, with no article text and no personal data. Google does not offer these feeds as an official API, so they can change without notice.
Why do some rows have resolved: false? Google News gives each article a link to Google, and the Actor decodes it to the publisher's URL. Decoding sometimes fails for one article; then the row keeps the Google News link. If Google shows a CAPTCHA check or rate-limits the run, decoding stops, the remaining searches end with an error message, and the rows already collected are kept. Rows with resolved: false are still charged.
How many articles can I get per search? You set maxItems for each query, topic or city, up to 1,000. Topic and city feeds hold about 100 articles. Keyword searches above 100 read back day by day (see Time ranges), so a search returns fewer articles when Google has fewer matches.
Related Actors
- RSS Feed Finder: the RSS, Atom and JSON feeds of a list of websites, with their latest posts.
- URL Status & SSL Checker: check that article links still load, with redirects and SSL expiry.
- Company Social Links Finder: a company's official social profiles and contact pages from its website.


