
SEO Meta Tag & Schema Checker (Bulk On-Page SEO Audit)
Pricing
from $1.13 / 1,000 pages
SEO Meta Tag & Schema Checker (Bulk On-Page SEO Audit)
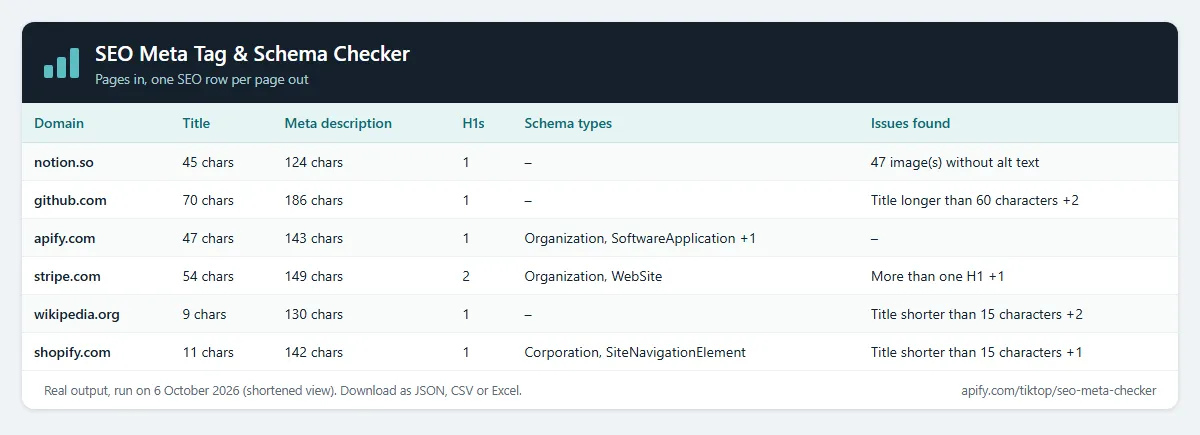
Check titles, meta descriptions, canonical, robots/noindex, H1s, Open Graph, Twitter cards, hreflang and schema.org structured data on any list of pages, with a plain-English list of SEO issues per page. Bulk URLs in, clean table out.
Pricing
from $1.13 / 1,000 pages
Rating
0.0
(0)
Developer
Red Fox Scout
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Share
Check whether AI crawlers can read your pages, and fix the on-page SEO behind them. For each URL you get an AI search readiness score (0-100) with the reasons: what robots.txt lets GPTBot, ChatGPT-User, OAI-SearchBot, ClaudeBot, PerplexityBot and four more AI crawlers read, and whether the site publishes an /llms.txt file. The same run gives a 0-100 SEO score, the title, meta description, canonical, robots and noindex, H1 to H3 headings, Open Graph and Twitter cards, hreflang, schema.org (JSON-LD, microdata and RDFa), LocalBusiness name, address and phone, article dates and authors, link and image counts, and a plain-English fix for every issue. For SEO agencies, site owners and content teams.
Price: $1.50 per 1,000 pages checked. Pages that fail to load or block the visit are free. Apify's free plan ($5 monthly credit) covers about 3,300 pages a month.
Questions it answers
- Can ChatGPT, Claude or Perplexity read these pages, or does robots.txt block them?
- Does the site publish an llms.txt file for AI tools?
- Which pages are set to noindex, point their canonical elsewhere or have no H1?
- Does the LocalBusiness schema show the right name, address and phone?
- Which pages have the most SEO issues, so I know what to fix first?
Who uses this
- 🔍 SEO agencies and freelancers: audit a client's key pages or a competitor's in one run.
- 🤖 Publishers and SaaS teams: see which AI crawlers a site lets in, and whether it has an llms.txt file.
- 🛠️ Developers: check releases for noindex mistakes, missing tags and robots.txt rules, on a schedule.
Why this SEO Meta Tag & Schema Checker
- 🤖 AI search readiness: robots.txt rules for 10 AI crawlers, llms.txt, and a 0-100 score with the reasons.
- 📊 SEO score with fixes: 0-100 per page, each issue with its severity and a plain-English fix.
- 🕸️ Whole-site crawl: up to 200 pages per site from its sitemap, with duplicate title and description flags.
- 🧩 Structured data: JSON-LD, microdata and RDFa types, LocalBusiness name, address and phone, article dates and authors.
- 🔔 Change alerts: title, noindex and schema changes since the last run.
- 💰 $1.50 per 1,000 pages, pages that fail to load are free.
How to use the SEO Meta Tag & Schema Checker
- Click Try for free (a free Apify account is enough).
- Paste the pages to check, one per line. A bare domain checks its home page.
- Click Start. Each page takes about a second.
- Sort by
seoScore(lowest first) oraiReadinessScoreto see the pages that need work first, then download as JSON, CSV or Excel.
Input
| Field | Default | What it does |
|---|---|---|
urls | – | Pages to check: full URLs or bare domains (the home page is checked). |
checkAiReadiness | true | Reads robots.txt for the AI crawlers and checks for /llms.txt. Adds two or three small requests per site, once per run. Turn it off to get only the SEO fields. |
maxConcurrency | 20 | Pages checked in parallel. |
requestTimeoutSecs | 30 | Give up on a page after this long. |
Example (the input behind the prefill):
Output
One row per page. Existing fields keep their names and meaning. The SEO score and AI readiness fields are new, and issues stays a plain list of sentences while issueDetails adds a code, severity and fix for each one. This is the real row for apify.com from a local run on the input above, shortened:
Export as JSON, CSV or Excel, or connect Google Sheets, Slack or a webhook through Apify integrations.
SEO score and issues
seoScore starts at 100 and loses 15 points per high-severity issue, 7 per medium and 3 per low, never below 0. Each entry in issueDetails has code, severity, message and fix. The checks include the title and description lengths, a missing or incorrect canonical, noindex, the H1 and heading levels, Open Graph and Twitter card tags, the viewport, charset and language, invalid JSON-LD, missing structured data, images without alt text, thin content (under 300 words) and pages with no internal links.
Other new fields
h2Count,h2,h3Count,h3: heading outline (texts capped at 10 per level and 120 characters each).internalLinkCount,externalLinkCount,nofollowLinkCount: links in the page's HTML (fragment, mailto and tel links are not counted).favicon,charset,viewport: icon link (data:icons are reported as null), declared character set and viewport meta content.openGraphMissing: which of title, description, image, url and type are missing.rdfaTypes,structuredDataFormats: schema.org types in RDFa, and which formats the page uses.localBusiness: type, name, address and telephone from LocalBusiness-type JSON-LD (Restaurant, Store, Dentist, Hotel and similar). Null when the page has none.article: type, headline, datePublished, dateModified and author from Article-type JSON-LD. Null when the page has none.aiReadinessScore,aiReadinessReasons,aiCrawlerAccess,aiCrawlerRules,blockedAiCrawlers: the AI search readiness result described above.llmsTxt,llmsFullTxt,robotsTxtUrl,robotsTxtStatus,robotsTxtHttpStatus,robotsTxtSitemaps: the files the AI check read.
Pages that return an HTTP error (403, 404, 500 and so on) get the SEO fields but no AI fields, and they are free.
Example tasks
Ready-made inputs you can open, change and run:
- Can ChatGPT and other AI crawlers read these websites
- Bulk meta description and title length checker
- Schema markup checker (JSON-LD structured data)
- Noindex checker for a list of pages
- Open Graph and Twitter card checker
- Compare competitors' titles, meta descriptions and H1s
Can AI crawlers read these pages?
The AI search readiness score reads each site's robots.txt the way the crawlers do. Each AI crawler gets its own answer for the checked URL, and the reason for any block is in aiCrawlerRules, for example Disallow: /.
| Crawler | Kind | Points if allowed |
|---|---|---|
| ChatGPT-User, OAI-SearchBot, Claude-Web, PerplexityBot | Answer engines (search and user-triggered reads) | 12 each (48 in total) |
| GPTBot, ClaudeBot, Google-Extended, CCBot, Bytespider, Applebot-Extended | Training crawlers and opt-out tokens | 3 each (18 in total) |
| /llms.txt is served as a text file | Guide for AI tools | 12 |
| Schema.org structured data (JSON-LD, microdata or RDFa) | 10 | |
| At least 150 words in the server HTML | 12 |
Blocking a training crawler costs only 3 points, because it stops model training rather than AI answers. Every group of lost points comes with a reason in aiReadinessReasons. The score is 100 when nothing is lost.
robots.txt is read once per site per run, with the rules from RFC 9309: the group that names the crawler wins over *, the longest matching rule wins, and Allow wins a tie. Wildcards (*) and end anchors ($) work, and the query string is part of the path. A missing robots.txt (404) allows everything. A robots.txt that cannot be read (HTTP 429 or 5xx) leaves access unknown (null), and the reason says so.
What it does not do: it reads the rules and files, not server logs, so it cannot tell you whether a crawler actually visited. Crawlers that do not run JavaScript only see the text in the server HTML, which is what this Actor reads.
Check websites from another Actor (Google Maps leads, lead lists)
Have a list from Google Maps Scraper or any other Actor? Pick its dataset under Websites from another Actor. This Actor reads the website field (or the field you name, e.g. url, domain or contact.website) and checks every site. No copy and paste.
To run it automatically after every scrape, add an Actor-to-Actor integration to the source Actor or task with this input:
Change alerts
Give the run a Change alert name (e.g. clients-weekly) and put it on an Apify schedule. Each row then gets changeStatus (new, changed or unchanged) and changedFields, compared with the previous run of the same name, so you see when a title, meta description, noindex, H1, schema type, robots.txt rule for an AI crawler or llms.txt file changes. Turn on Only new and changed sites and each run's dataset is just the change report; unchanged sites are still checked and charged as usual. Add Apify's Slack or email integration to get the report delivered.
Notes
- Checks the HTML the server returns (no JavaScript rendering). Tags injected only by JavaScript won't appear.
- Reads only the pages you list; it doesn't crawl a whole site.
- What this Actor does not do: it does not log in, solve CAPTCHAs or collect personal data about people. It does not measure Core Web Vitals or page speed, which need a browser.
- Issue thresholds follow common guidance (title 15–60 characters, description up to 160).
How much does it cost?
- Page checked: $0.0015 per page that loads ($1.50 per 1,000).
- Actor start: $0.00005 per GB of memory (default 1 GB = $0.00005 per run).
- Pages that fail to load or block the visit: free.
| Pages | Cost |
|---|---|
| 100 | about $0.15 |
| 1,000 | about $1.50 |
| 10,000 | about $15 |
Apify's free plan includes $5 of credit every month, enough for about 3,300 pages. Paid Apify plans get Store discounts of up to 25%. You can set a maximum cost per run; the Actor stops cleanly when it's reached.
FAQ
Is this legal? It loads each public page once, like a browser, and reads its HTML tags, robots.txt and llms.txt. No personal data is collected.
Does a robots.txt block stop ChatGPT from citing my site? Not all of it. GPTBot is OpenAI's training crawler, OAI-SearchBot is used for ChatGPT search and ChatGPT-User for pages a user asks ChatGPT to open. Each one has its own rule, so the score lists each one separately. Whether a crawler honours the rules is up to its operator.
Why is a tag I can see in my browser missing? It's probably added by JavaScript after the page loads. Search engines mostly read the server HTML too, so it's worth fixing.
Can it crawl my whole site? No, it checks the pages you list. Export your sitemap URLs and paste them in, or feed it a dataset from a crawler Actor.
Related Actors
- Bulk URL Status & SSL Checker: status codes, redirects and SSL expiry.
- Website Tech Stack Detector: what a site is built with.
- Shopify Store Detector: theme and apps of Shopify stores.


