
Lighthouse Audit API: Core Web Vitals and Performance Scores
Pricing
from $6.00 / 1,000 page auditeds
Lighthouse Audit API: Core Web Vitals and Performance Scores
Run Lighthouse on any public page and get Performance, Accessibility, Best Practices and SEO scores, lab Core Web Vitals and the biggest savings. No Google key, robots.txt obeyed, pay only per page audited.
Pricing
from $6.00 / 1,000 page auditeds
Rating
0.0
(0)
Developer
Rowcraft
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
an hour ago
Last modified
Categories
Share
Run Lighthouse on any public web page without a Google API key. Give the actor a list of addresses and it audits each one in its own headless Chrome: the Performance, Accessibility, Best Practices and SEO scores, the lab Core Web Vitals (Largest Contentful Paint, Total Blocking Time, Cumulative Layout Shift), the other speed metrics, the five biggest time savings and the audits that failed. You get one dataset row per page and device as JSON, CSV or Excel, and the complete Lighthouse HTML report of every page in the key-value store of the run.
It is built for the checks that come back every week: a performance budget for the pages of a site, a before-and-after comparison around a release, mobile against desktop, a client report with real numbers, or a schedule that tells you when a page drops below a score you set. Nothing is installed, no quota is shared with other users, and you pay only for pages that were actually audited.
What you get
One row per page audited, with 25 fields:
- The page: the address you gave, the address Lighthouse ended on after redirects, the HTTP status and the device (
mobileordesktop) - The four scores:
performanceScore,accessibilityScore,bestPracticesScoreandseoScore, whole numbers from 0 to 100, ornullfor a category you did not ask for - The lab metrics: First Contentful Paint, Largest Contentful Paint, Total Blocking Time, Cumulative Layout Shift, Speed Index, Time to Interactive, server response time, total transfer size in bytes and the number of requests
- What to fix:
topOpportunities, the five biggest time savings Lighthouse found with the estimated milliseconds, andfailedAudits, the ids of the audits that scored below 0.9 - The full report:
reportUrl, a link to the complete Lighthouse HTML report of that page, the same report you would get from DevTools - The audit itself: the Lighthouse version, the time of the audit and any warnings Lighthouse gave about the run
The run also writes a COVERAGE record with one line per page and device you asked for (ok, blocked, robots_disallowed, not_found, timeout, error or not_checked, with the reason) and a RUN_SUMMARY with the counts, the average audit time, the browser and Lighthouse version, the pages below your performance threshold and any warnings.
Why this actor
- No Google key and no shared quota. The audit is run by Lighthouse in a Chrome of our own, not fetched from a Google service, so there is no API key to create, no daily limit to hit and no rate limit shared with other users.
- Pay for audits, not attempts. A page that answers with an anti-bot page, an HTTP error, a robots.txt refusal or a timeout is listed in
COVERAGEand costs nothing. So do duplicates, invalid entries and, with Only new rows, pages whose scores did not change. - Mobile, desktop or both in one run. The mobile audit uses the same phone profile that Google tests first (a slow 4G connection and a 4x slower processor); the desktop audit uses a wide screen on a fast connection. With Both every page gets two rows.
- The report comes with the numbers. Every row links to the full Lighthouse report: filmstrip, every audit with its explanation and the list of resources behind each saving. Switch it off if you only need the numbers.
- A threshold for schedules. Set
alertBelowPerformanceand the end-of-run notification lists the pages delivered in that run whose Performance score is under it. - Polite by design. robots.txt is read for every site (and every redirect target) before the page is opened, audits run one at a time, requests to the same site are spaced out and the visit carries a user agent that names Rowcraft so site owners can recognise it.
How to use it
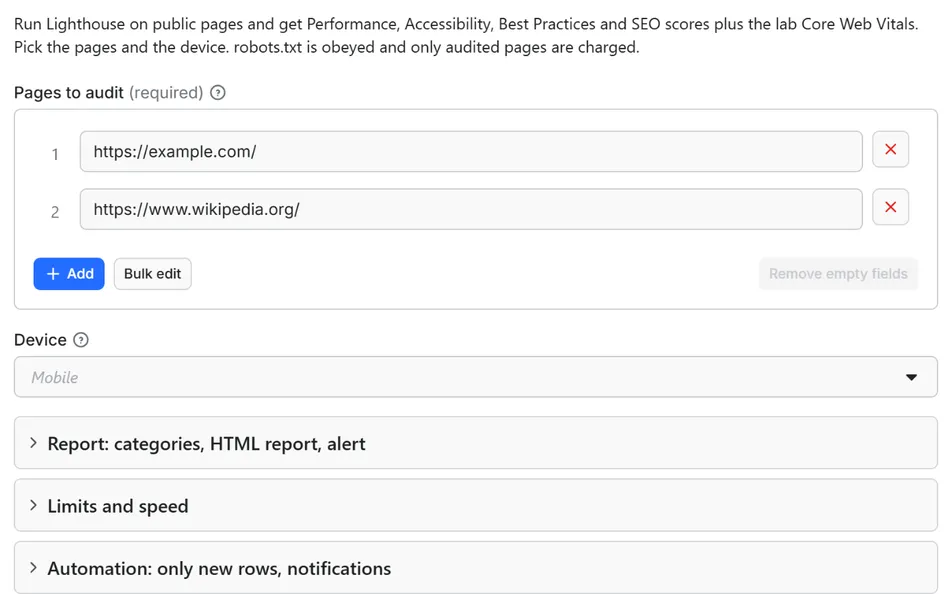
- Open the Actor and fill in Pages to audit (the other fields are optional filters).
- Set Maximum pages to a small number for a first try (the default is a safe start).
- Click Start. The status line shows progress; the run stops cleanly at your limit or at the charge limit you set in the run options.
- Open the Dataset tab and download JSON, CSV, Excel, XML or HTML, or send the rows to Google Sheets, Slack, Make, n8n or Zapier with the Integrations tab.
- To run it on a schedule, use Schedules in Apify Console and turn on Only new rows since the last run below: every run then costs only the new rows, and a webhook URL tells you when something new came in.
For the first try keep the list short: one audit takes roughly 10 to 30 seconds, depending on the page. The full report of each page is in the key-value store of the run, under the key that starts with lighthouse- and ends .html; the same link is in the reportUrl column of the dataset.
Input
| Field | What it does |
|---|---|
startUrls | Pages to audit, one per line: a full address (https://example.com/pricing) or a domain (example.com). Every page is audited on its own; the actor never follows links. Up to 20,000 per run. |
formFactor | mobile (default), desktop or both. Both gives two rows per page and counts as two pages in the price and in maxItems. |
categories | Which of performance, accessibility, best-practices and seo to score. Empty = all four. Lighthouse runs only the audits of the categories you pick, so fewer categories are faster. |
saveHtmlReport | Save the complete Lighthouse report of each page in the key-value store and put its link in reportUrl (default on). Each report is about 0.4 to 1 MB. |
alertBelowPerformance | Optional, 0 to 100. Pages delivered in this run with a Performance score under this number are listed in the notification and in RUN_SUMMARY. |
maxItems | Stop after this many audits are delivered. 0 = the whole list. |
onlyNew, stateName | Deliver a page again only when one of its four scores changed since the last run with the same state name. |
notifyUrl, notifyWhenEmpty | A webhook that receives one message when the run ends; see Automation below. |
requestIntervalMs | Pause between the requests the actor makes to the same site before an audit, default 1000 ms, minimum 250 ms. |
Example: three documentation pages on mobile, all four categories.
Example: the same two pages on phone and desktop, with an alert under 80.
Example: only SEO and Accessibility, numbers only, no report files.
Output
25 fields per row. Empty values are null, never missing, so CSV and Excel columns are stable.
| Field | Type | Example |
|---|---|---|
id | string | mobile:https://developer.mozilla.org/en-US/docs/Web/API/Fetch_API |
url | string | https://developer.mozilla.org/en-US/docs/Web/API/Fetch_API |
finalUrl | string | https://developer.mozilla.org/en-US/docs/Web/API/Fetch_API |
formFactor | string | mobile |
statusCode | integer | 200 |
performanceScore | integer | 94 |
accessibilityScore | integer | 100 |
bestPracticesScore | integer | 96 |
seoScore | integer | 100 |
firstContentfulPaintMs | integer | 1215 |
largestContentfulPaintMs | integer | 1750 |
totalBlockingTimeMs | integer | 40 |
cumulativeLayoutShift | number | 0.012 |
speedIndexMs | integer | 1530 |
timeToInteractiveMs | integer | 2100 |
serverResponseTimeMs | integer | 118 |
totalByteWeight | integer | 482113 |
requestCount | integer | 38 |
topOpportunities | string | Reduce unused JavaScript — 300 ms Enable text compression — 150 ms |
failedAudits | string | unused-javascript, uses-long-cache-ttl, meta-description |
reportUrl | string | https://api.apify.com/v2/key-value-stores/abc123/records/lighthouse… |
lighthouseVersion | string | 12.8.2 |
fetchTime | string | 2026-10-18T16:47:45.849Z |
runWarnings | string | Warnings Lighthouse gave about the run, separated by " |
note | string | Set when a category could not be scored on this page (the other scores are still delivered) |
Example rows
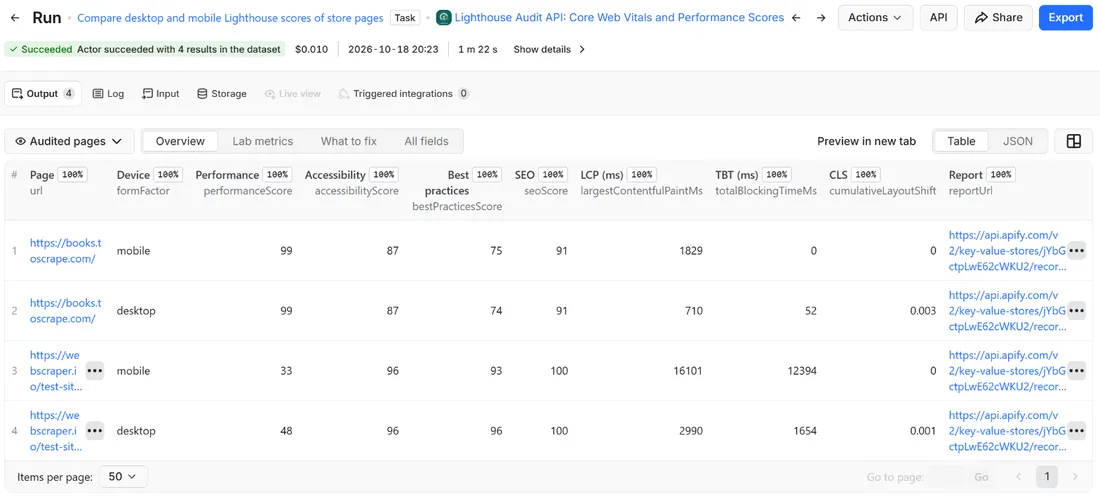
Two real rows from a run (long texts shortened here, complete in the dataset):
Results can be downloaded as JSON, CSV, Excel, XML or HTML from the Dataset tab, or read through the Apify API.
How to read the numbers
- Scores are Lighthouse's own weighted scores: 90 to 100 is good, 50 to 89 needs work, below 50 is poor. The Performance score is a weighted mix of the lab metrics; the other three categories count passed audits. How Lighthouse weighs the metrics is described on developer.chrome.com.
- Largest Contentful Paint (good: 2,500 ms or less) and Cumulative Layout Shift (good: 0.1 or less) are two of the three Core Web Vitals. The third, Interaction to Next Paint, needs a real person clicking, so a lab run cannot measure it; Total Blocking Time is the lab metric that moves with it and is delivered instead.
- Milliseconds, bytes and counts are plain integers;
cumulativeLayoutShifthas three decimals; a metric that Lighthouse did not compute for the page, or that belongs to a category you did not ask for, isnull. topOpportunitieshas one line per saving,title — estimated milliseconds, largest first. The estimate is Lighthouse's own simulation of the page without that problem.failedAuditslists the ids (for exampleunused-javascript,meta-description) of the audits that scored under 0.9 in the categories you asked for. Open the report to see what each one found.
Pricing
Pay per result. You pay for each page delivered to your dataset, nothing else: no subscription, no minimum, no charge for rows your filters drop or for the requests behind them.
| Your Apify plan | Price per 1,000 rows | Price per row |
|---|---|---|
| Free plan | $8.00 | $0.008 |
| Starter plan | $7.20 | $0.0072 |
| Scale plan | $6.60 | $0.0066 |
| Business plan and above | $6.00 | $0.006 |
Example: 1,000 pages cost $8.00 on the Free plan and $6.00 on the Business plan. Platform usage of the run (compute, storage) is included in that price and is not billed to you separately (pay per event: the actor covers it).
A start event of $0.00005 is charged once per run (Apify default).
Cap your spend: set Maximum total charge in the run options. The actor stops cleanly when the cap is reached and you keep everything delivered until then. The run summary (RUN_SUMMARY in the key-value store) says why a run stopped.
Both devices on 100 pages are 200 audits: $1.60 on the Free plan and $1.20 on the Business plan. A single mobile audit costs $0.008 on the Free plan.
Automation: only changed pages, notifications, schedules
Only new rows since the last run. Turn on onlyNew and the actor remembers every page it delivered to you (in a key-value store named rowcraft-lighthouse-performance-audit-state in your Apify account). The next run with the same stateName skips what you already have and you pay only for new rows. The first run delivers everything that matches. Use a different stateName for each schedule or search so they keep separate memories.
Notification when the run ends. Put a webhook address in notifyUrl and the actor sends one JSON POST with the number of new rows, links to the dataset (JSON and CSV) and the run. It works out of the box with Slack and Discord incoming webhooks (the message is in text and content), with Make, n8n and Zapier catch hooks, and with your own endpoint. By default it is sent only when there is at least one new row; notifyWhenEmpty sends it every time.
Schedules. Create a schedule in Apify Console (hourly, daily, weekly or cron) with onlyNew on. A daily schedule gives you a feed of new pages for the price of the new rows only.
Integrations. Send the results to Make, n8n, Zapier, Google Sheets, Slack, Google Drive, Airtable or any webhooks from the Integrations tab of the Actor, with no code. Apify also offers native actions for Make, n8n and Zapier.
API, SDKs and AI agents. Every run is available through the Apify API and the official JavaScript and Python clients; the Actor can also be called by AI agents through the Apify MCP server. The example input in the API tab is a working call.
What "new" means here. With onlyNew, a page and device is delivered again only when at least one of its four category scores differs from the last time it was delivered under the same stateName. A page whose four scores are unchanged is still audited, because the scores are only known after the audit, but it is not delivered and not charged; the run summary counts it under unchangedSkipped. The Performance score moves by a few points between runs even on an untouched page (see the section on limits), so for a stable signal watch the other three categories or compare the metrics yourself; the memory keeps the latest delivered scores per page and device.
Alert for schedules. Combine a daily schedule, alertBelowPerformance and notifyUrl: the message says how many pages were delivered and lists the ones under your threshold with their address, device and score. Pages that were audited but not delivered (for example unchanged ones) are not part of the list.
Use cases
- Performance budget for a site: audit the ten pages that earn the money every night and get a message when one falls under 70.
- Before and after a release: run the same list on the staging and production addresses, or before and after a change, and compare the scores and the five savings.
- Mobile against desktop:
formFactor: bothshows which pages are fine on a laptop and slow on a phone. - Client and agency reports: one row per page with the numbers, and the full report as a link to attach.
- SEO and accessibility sweeps: run only those two categories over a list of landing pages and sort by
failedAuditsto find the common problems first. - Competitor benchmarks: the same four scores and the three Core Web Vitals for your pages and theirs, in one table.
- A data feed for dashboards: a scheduled run into Google Sheets, a warehouse or a BI tool, one row per page per day.
Ready-made examples, each with the input filled in (open one and press Start, or save it as your own task):
- Check Core Web Vitals on mobile for documentation pages
- Compare desktop and mobile Lighthouse scores of store pages
- SEO and accessibility scores for home pages of public sites
What this actor does not do
- Give the field data from real visitors: the Chrome User Experience Report (CrUX) numbers shown by Google's PageSpeed Insights come from real Chrome users over 28 days. This actor delivers lab measurements only, exactly like Lighthouse in DevTools. Lab and field numbers answer different questions; see web.dev for the difference.
- Audit pages behind a login, a paywall or a step that needs a click: every page is opened as a first-time visitor with empty storage, and nothing is typed or accepted on the page.
- Crawl a site: it audits the addresses you list, never the links found on them.
- Return identical scores on every run: Lighthouse scores move by a few points between runs because load times vary. To compare over time, always use the same device and the same list, and look at trends and not at single points.
- Fix the page or rank it in Google: it measures and explains; the changes are yours to make.
- Measure Interaction to Next Paint, or anything that needs real user input.
- Solve CAPTCHAs or get around anti-bot protection: a page that answers with a challenge or an access-denied page is reported as
blockedand not charged. - Use proxies or hide where it runs: every page is opened from the Apify platform's own network.
- Open private or local addresses: page addresses (and redirect targets) that resolve to a private network, such as localhost, 10.x, 192.168.x or 169.254.x, are refused on the platform.
Limits and fair use
- Speed and size of a run. Audits run one at a time in one Chrome, roughly 10 to 30 seconds per page and device. At that pace the default one-hour run timeout fits about 120 to 360 audits; for longer lists raise the timeout in the run options or split the list. The actor stops before the timeout with the summary, the coverage and the Only new rows memory saved.
- Time limit per page. An audit that has not finished after 90 seconds is cut, listed in
COVERAGEastimeoutand not charged. - Scores vary. Expect the Performance score of the same page to differ by a few points, sometimes more on heavy pages or pages with ads and personalised content. Accessibility, Best Practices and SEO barely move. Use the same
formFactorwhen you compare. - What the profiles mean. Mobile: a phone-sized screen, a simulated slow 4G connection (about 1.6 Mbps and 150 ms round trip) and a processor slowed 4x. Desktop: a wide screen, about 10 Mbps and 40 ms, no slowdown. The slowdown is simulated from one unthrottled load, the same method PageSpeed Insights uses.
- Pace. Before each audit the actor reads robots.txt and checks the page, and those requests to the same site are at least 1,000 ms apart by default (minimum 250 ms). Lighthouse then loads the page like a browser: the page, its scripts, styles and images, and a few extra requests such as robots.txt for the SEO audit.
- Anti-bot pages. Websites behind a bot challenge (Cloudflare, Akamai, DataDome and similar) are reported as
blockedand not charged. After 10 blocked pages in a row the run stops and says why in the run summary. - robots.txt is obeyed for the page address, for every redirect target and for the address the browser ends on. If robots.txt disallows the address, the page is
robots_disallowed; if robots.txt answers with a server error, the page is not opened, as the robots.txt standard (RFC 9309) requires. Images, scripts and styles that the page itself loads are loaded the way any browser loads them. - Memory. The run uses 2,048 MB: Chrome needs most of it. Audits are not run in parallel, because Lighthouse is not reliable with two audits in one browser.
- Dataset size. The rows are small. The HTML reports are stored as files in the key-value store, which is why they are a separate switch.
Data source and licence
There is no third-party data source and no Google service is called. The actor opens the addresses you give it, runs Lighthouse (open source, Apache License 2.0, made by the Chrome team at Google and published at github.com and described at developer.chrome.com) in a headless Chrome, and delivers what Lighthouse measured. Rowcraft is independent and not affiliated with or endorsed by Google, the Chrome team or the websites the actor opens.
The visit identifies itself with a Chrome user agent, phone or desktop as the audit requires, that ends with Rowcraft-Lighthouse/1.0 (+https://apify.com/rowcraft); robots.txt is read under the product token rowcraft. The Lighthouse version is in every row (lighthouseVersion) and the browser version in RUN_SUMMARY, so a result can always be traced to the tools that made it.
Privacy: no personal data
Rowcraft actors are built not to collect personal data:
- The rows hold addresses, scores, numbers and the ids of audits. No names, e-mail addresses, phone numbers or other fields about people are requested or delivered, and an e-mail address inside a page address is removed from the row.
- The saved HTML report is a different matter: it shows what Lighthouse saw on the page, including its small screenshots and the addresses of the files it loaded. You choose the pages, so you are responsible for the reports you keep and share; turn
saveHtmlReportoff to keep only the numbers. - Each audit starts from a clean browser profile with no cookies, no login and no stored data.
- The actor sends no form data, stores nothing about the pages outside your run and your own Only new rows memory, and does not open private network addresses.
Other Rowcraft actors
All Rowcraft actors read official or public sources, deliver flat rows without personal data and support only-new runs and notifications:
- Ashby Jobs Scraper – Job Postings with Salary Ranges — Job postings from Ashby job boards (jobs.ashbyhq.com) by company: title, department, team, locations with country, employment and workplace type, published salary range, full text.
- Broken Link Checker – Find 404s and Dead Links API — Pay per crawled page, not per link: crawl a site within robots.txt and check every link on each page for 404s, 5xx errors, DNS and TLS failures and redirects.
- Bulk Image Downloader API: Save Page Images with Sizes — Download the images of any web pages, or direct image links, into a key-value store with width, height, format, size and a download link per file.
- Career Site Jobs Scraper: Greenhouse, Lever, Ashby, Workday — Job listings from the career pages of the companies you choose on Greenhouse, Lever, Ashby, Workday, Workable, Personio, Recruitee, Teamtailor and Gem, in one run and one format: title, locations, department, salary when published, full text.
- Chrome Web Store Scraper: Users, Ratings & Versions — Reads public Chrome Web Store listing pages with no login, no proxy and no personal data: users, rating, category, version, update date, permissions and company developers.
- Domain Email and DNS Checker API: MX, SPF, DMARC, Providers — Find which email provider, sending services and DNS host each domain uses, from public DNS records only.
- SIRENE France Company Scraper: SIREN, NAF, Revenue, Status — French companies from the official Recherche d'entreprises API (INSEE SIRENE + INPI): SIREN and SIRET, legal form, NAF activity, head-office address, employee band, revenue and net income, labels, creation date and VAT number.
- Gem Jobs Scraper – Job Board Listings from jobs.gem.com — Job listings from Gem job boards (jobs.gem.com) by company: title, department, offices with country, employment type, remote, hybrid or on-site, requisition ID, publication date and full ad text, from the public Gem Job Board API.
- Google Play Apps Scraper: App Details, Installs, Ratings — Public Google Play app details as flat rows: installs, rating, number of ratings, price, version, last update, minimum Android, ads and in-app purchases.
- Greenhouse Jobs Scraper – Job Listings by Company Board — Job listings from Greenhouse job boards by company: title, departments, offices, publication date, full ad text, published pay ranges.
- Hacker News Scraper API: Top, New, Best, Ask, Show Stories — Read Hacker News stories from the official Firebase API: top, new, best, Ask HN, Show HN and job lists with score, comments, domain and age.
- Himalayas Jobs Scraper: Remote Jobs API with Salaries — Remote jobs from Himalayas through its public jobs API: title, company, salary range, seniority, categories, the countries and time zones open to candidates, full description and job link.
- Image to Text OCR API: Extract Text from Images in Bulk — Read the text in images given by link or found on web pages, with a local OCR engine and no third-party API.
- KRS Poland Companies Scraper: Register Data, PKD, Status — Polish companies from the official KRS register API of the Ministry of Justice: name, KRS, NIP and REGON numbers, legal form, status, address, PKD activity codes, share capital, branches and registration dates.
- LEI Records Scraper: Legal Entity Identifier Lookup API — Legal Entity Identifier (LEI) records from the Global LEI Index, read through the public GLEIF API: legal name, legal form, register number, addresses, status, renewal date and parent companies.
- Lever Jobs Scraper – Job Postings from jobs.lever.co — Job postings from Lever career pages (jobs.lever.co) by company: title, team, department, location, commitment, workplace type, salary range when published, description, requirements and benefits.
- Norway Company Register Scraper: Brønnøysund Business Data — Norwegian companies from the Central Coordinating Register for Legal Entities (Brønnøysund, NLOD open data): organisation number, legal form, industry, employees, share capital, addresses, website, VAT and bankruptcy status.
- PDF Text Extractor: Text, Pages and Metadata from PDF Links — Get the text of every PDF you link, page by page, with page count, language and word count.
- Personio Jobs Scraper: Job Listings, Salaries, Departments — Job ads from any company's Personio careers feed: title, department, office, employment type, schedule, seniority, salary when published, keywords and the full description in the language you choose.
- Platsbanken Scraper: Sweden Jobs, Employers, Org Numbers — Every job ad on Platsbanken (Arbetsförmedlingen) from the official JobTech API: headline, employer and organisation number, occupation codes, municipality, coordinates, salary type, deadline and full text.
- Recruitee Jobs Scraper – Job Listings by Company Career Site — Job listings from Recruitee career sites by company: title, department, locations with country, employment type, remote flag, published salary and full text, one request per company.
- Remote Jobs Aggregator API: RemoteOK, WeWorkRemotely, Jobicy — Remote jobs from RemoteOK, We Work Remotely and Jobicy in one clean list, read from their official feeds and APIs, merged without duplicates.
- Robots.txt and AI Crawler Access Checker API — Check which AI and search crawlers a website lets in: GPTBot, ClaudeBot, PerplexityBot, Google-Extended and more, read from robots.txt by the RFC 9309 rules.
- RSS Feed Finder and Reader – Blog and News Article API — Find the RSS, Atom and JSON feeds of any website and read their newest articles, from a domain name alone.
- SEO Audit Tool: Titles, Meta Tags, Headings and Links API — Audit the on-page SEO of any list of pages or websites: titles, meta descriptions, headings, canonicals, indexing, links, images and structured data, with a score and the issues found per page.
- Shopify Products Scraper: Store Catalog Export to JSON, CSV — Products from any Shopify store's public catalog: title, vendor, type, tags, description, variants with price, compare-at price, SKU and stock, images, options, store currency.
- Sitemap URL Extractor: Every Page with Last-Modified Dates — Get every page a site lists in its sitemaps, with last-modified dates, from robots.txt through sitemap indexes and .gz files.
- SSL Certificate and Security Headers Checker API — Check the TLS certificate and the HTTP security headers of every domain in one run, with an A+ to F grade and the exact issues to fix.
- Store Products Scraper – Shopify, WooCommerce, VTEX — Export the product catalogue of any Shopify, WooCommerce or VTEX store from its public catalogue endpoint: title, brand, prices, discounts, stock, categories, images and links, one row per product, the same columns on every platform.
- Structured Data Extractor: JSON-LD, Schema.org, Open Graph — Pull the schema.org JSON-LD, Microdata, RDFa and Open Graph of any page list into flat rows: types, product price, availability, ratings, organization, breadcrumbs, with validation issues.
- Teamtailor Jobs Scraper – Career Site Jobs by Company — Job listings from Teamtailor career sites by company: title, department, role, locations with city and country, remote or hybrid status, publication date and full ad text, from the official job feed.
- TED Tenders Scraper: EU Public Procurement Notices API — EU public procurement notices from TED (Tenders Electronic Daily), the official EU tenders portal, through its public Search API: title, buyer, country, CPV codes, values, deadlines, lots and document links.
- UK Companies House Scraper: Company Search & Profiles API — UK companies from the official Companies House API with your free key: search by name, status, type, SIC code, date or location, or look up company numbers.
- UK Tenders Scraper: Find a Tender + Contracts Finder API — UK public procurement notices from Find a Tender and Contracts Finder, the official UK government portals, through their open OCDS APIs: title, buyer, region, CPV codes, values, deadlines, notice type and links.
- Bulk URL Status and Redirect Chain Checker API — Check the status code, redirect chain, canonical and indexing signals of every URL in a list, with the final destination and a loop flag.
- Video Frame Extractor: Thumbnails and Frames from Video URLs — Extract JPG, PNG or WebP frames from direct video links (MP4, WebM, MOV, MKV, OGV): evenly spaced, every N seconds, at exact times or at scene changes.
- VTEX Products Scraper – Public Catalog Export — Export the catalogue of any VTEX store (Auchan, Chedraui and thousands of retailers in Europe and Latin America) from its public search endpoint: title, brand, EAN, prices, list prices, stock, categories, specifications and images, one row per product.
- Website to Markdown Extractor: Clean Text for LLMs and RAG — Turn a list of web page addresses into clean Markdown and plain text for LLMs and RAG: the main content only, with headings, links, images and tables.
- Website Screenshot API: Full-Page PNG, JPEG and PDF Captures — Capture full-page or viewport screenshots of any public web page as PNG, JPEG or WebP, with an optional A4 PDF.
- Website Tech Stack Detector – Technology Lookup API — Find the technologies behind a list of websites: CMS, e-commerce platform, analytics, tag managers, ad pixels, consent tools, chat, CDN and payments, from one polite home-page request per domain.
- WooCommerce Products Scraper – Store API Export — Export every product of a WooCommerce store through its public Store API: title, SKU, prices and sale prices, stock, categories, tags, attributes, ratings, images and links, one row per product.
- Workable Jobs Scraper: Job Listings from Career Pages — Job listings from any company's Workable career page: title, department, location, remote or on-site, employment type, description, requirements, benefits and salary when published.
- Workday Jobs Scraper – Jobs from myworkdayjobs.com Sites — Job listings from Workday career sites (myworkdayjobs.com) by company: title, locations, country, posting date, time type, requisition ID and the full description.
FAQ
How much does it cost? $8.00 per 1,000 pages audited on the Free plan and $6.00 on the Business plan, only for pages that were audited (see Pricing). Platform usage of the run is included in that price and is not billed to you separately; set a maximum total charge in the run options to cap a run.
Why do the scores differ from PageSpeed Insights or from DevTools on my laptop? Lighthouse is a lab test and its numbers depend on the machine and the moment. PageSpeed Insights runs Lighthouse on Google's servers and also shows field data; DevTools runs it on your own computer, often without the slowdown a phone profile applies. The method is the same, the hardware is not, so expect differences of a few points in Performance. For tracking, compare this actor with itself over time.
Why is the Performance score different every time I run it? Page load times vary with the server, the network path, third-party scripts and ads, and Lighthouse measures one load. The other categories are rule checks and hardly change. Use the same formFactor, look at a trend over several runs, and treat a one-point move as noise.
What is the difference between lab data and field data? Lab data (this actor) is one controlled load of the page. Field data (CrUX in PageSpeed Insights) is the experience of real Chrome users over 28 days. Lab data tells you why a page is slow and lets you test a fix at once; field data tells you what users felt. This actor does not provide field data.
How do I open the full report? Click reportUrl in the dataset, or open the file in the key-value store of the run. If your browser downloads the file instead of showing it, open the downloaded file: it is one self-contained HTML file and works offline.
Is it legal? The actor opens public pages as any visitor's browser would, obeys robots.txt, never logs in and does not collect personal data in its rows. Whether and how you may use the results (for example in a report for a client) depends on the page's owner and on the law that applies to you.
Does it collect personal data? No personal data in the rows: no names, e-mail addresses or phone numbers. The saved reports show what the page showed to a first-time visitor, so choose pages with care. See the Privacy section.
Why is the result empty? Every page in the list could not be audited, or was skipped. The COVERAGE record gives the reason per page: an anti-bot page (blocked), robots.txt (robots_disallowed), no website or an HTTP 404 (not_found), a page that did not finish in 90 seconds (timeout), an invalid entry or another problem (error). With Only new rows on, pages whose scores are unchanged since the last run are skipped. Nothing is charged for any of those, apart from the start event.
Do I pay for pages that fail? No. Blocked pages, robots.txt refusals, HTTP errors, timeouts, pages Lighthouse could not score, invalid entries and duplicates are never charged. A row exists only when Lighthouse produced at least one score. If one category could not be scored on a page, the row is delivered with that score empty and a note, and the page is charged as one audit.
What does Both do to the price? Each page is audited twice, once per device, and each audit is one row and one charge. A list of 50 pages with Both is 100 audits.
Can I audit a page that needs a login? No. The audit opens the page with empty storage, like a first-time visitor, and never types or clicks. The login page itself can be audited.
How do I get a message when a page gets slower? Run the actor on a daily schedule with alertBelowPerformance set and a webhook in notifyUrl. The message lists the pages delivered in that run whose Performance score is under your number. Slack and Discord webhooks show it as plain text; Make, n8n and Zapier receive the same data as JSON fields (pagesBelowThreshold).
Which Lighthouse and Chrome versions are used? Lighthouse 12 and the Chrome that ships in the actor image. Both versions are written to the run (lighthouseVersion in every row, browser in RUN_SUMMARY). When a new build changes either, the changelog says so, because scores can shift slightly between Lighthouse versions.
Why does the audit not hide my cookie banner? Lighthouse measures the page as it loads for a first-time visitor, and the banner is part of that. Nothing is clicked or accepted. If the banner drags the score down for your visitors, it should show in the numbers.
Support and reviews
Problems, missing fields, questions: open an issue on the Issues tab of this Actor. We answer within one working day and fix confirmed bugs in the next release; the changelog lists every change.
If this Actor saved you time, a short review on its page helps other users find it and helps us keep improving it.


