
Career Site Jobs Scraper – Greenhouse, Lever, Workday & more
Pricing
from $2.00 / 1,000 jobs
Career Site Jobs Scraper – Greenhouse, Lever, Workday & more
Search live jobs from 12,000+ company career sites (Greenhouse, Lever, Ashby, Workday) by title, location, remote and seniority, or scrape any company on 8 ATS. Salary ranges, Markdown descriptions, new-jobs mode with free closed-job alerts. No start fee.
Pricing
from $2.00 / 1,000 jobs
Rating
0.0
(0)
Developer
Smoldesk Studios
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
20 hours ago
Last modified
Categories
Security
Limited permissionsShare
Career Site Jobs Scraper – Greenhouse, Lever, Workday, Ashby & more
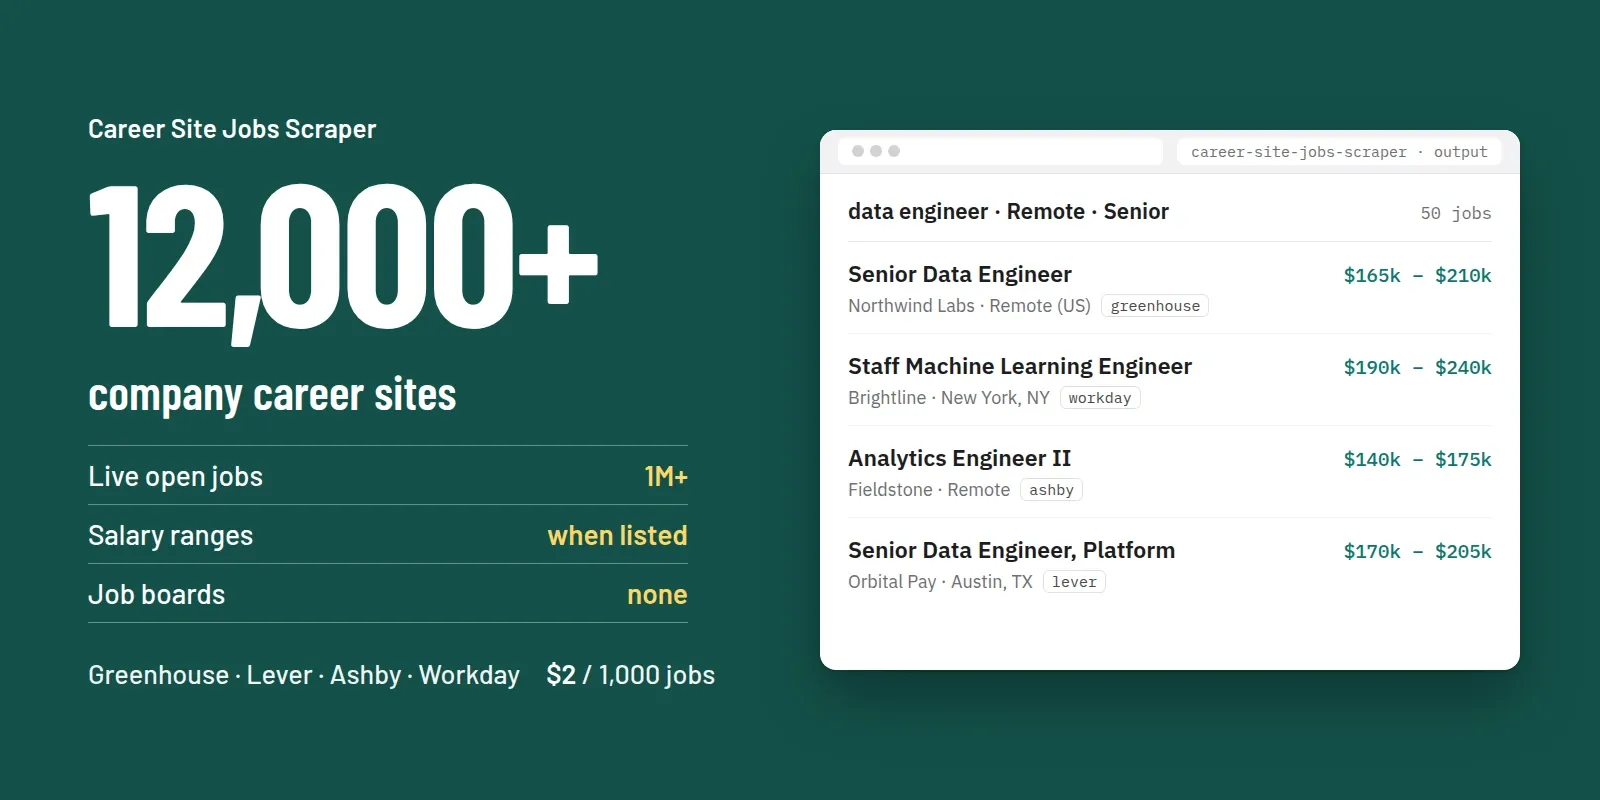
Search live job postings straight from 12,000+ company career sites (over 1 million open jobs) by job title, location, remote type and seniority: Greenhouse, Lever, Ashby and Workday boards of companies like NVIDIA, Salesforce, SpaceX, Airbnb, Anduril, GitLab, Ramp and Notion. Or point it at any company's careers page on Greenhouse, Lever, Ashby, Workday, Workable, Recruitee, SmartRecruiters or Personio and get every open role. No login, no API key, no start fee.
Every job comes with title, company, department, location(s), remote / hybrid / on-site, employment type, seniority (intern → executive), post date, job URL and apply URL, the full description as clean Markdown (ready for LLMs and RAG) plus HTML, and a salary range (min / max / currency / period) taken from the ATS pay-transparency fields or, when the employer only writes it in the text, parsed from the description ("$165,000.00 - $265,000.00", "184,000 USD - 287,500 USD", "€55k–65k"). In our tests 3 out of 4 US remote jobs came with a salary.
The data is fetched live from each employer's own job board on every run, so there are no stale or expired jobs from a weeks-old database. Turn on "Only new jobs" and schedule it daily: you get a feed of fresh postings, pay only for jobs you haven't seen before, and get a free "closed" notice for every job that has been taken down since your last run.
What you can use it for
- Job boards & aggregators: fill a niche job board (remote, AI, climate, fintech…) with fresh postings direct from employers, with apply links, and remove jobs as soon as they close.
- Job alerts: a daily feed of new "senior data engineer, remote, US" jobs into Slack, Sheets, Airtable or email.
- Sales & recruiting leads (hiring signals): find companies hiring for roles that need your product or your candidates.
- Salary benchmarking: structured pay ranges from US pay-transparency postings across thousands of companies, by seniority.
- Competitor & market research: track what a set of companies is hiring for and how fast roles close.
- AI agents & RAG: give an LLM clean, current job ads in Markdown for job matching, CV tailoring or market summaries.
How to use it
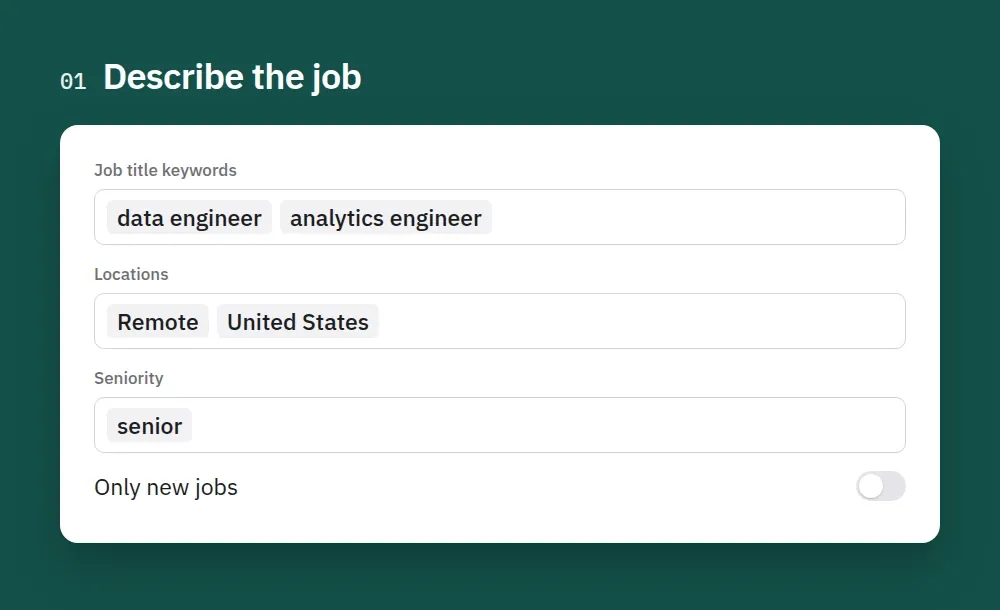
1. Describe the job. Type job titles, locations and seniority, or paste the career pages of the companies you care about.
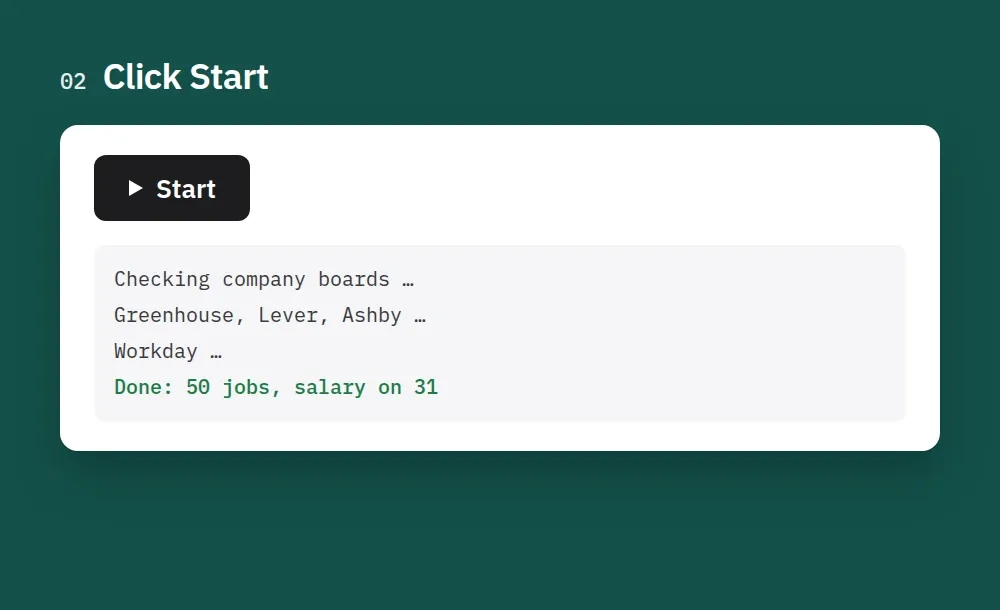
2. Click Start. The Actor checks the company boards and stops as soon as it has the number of jobs you asked for.
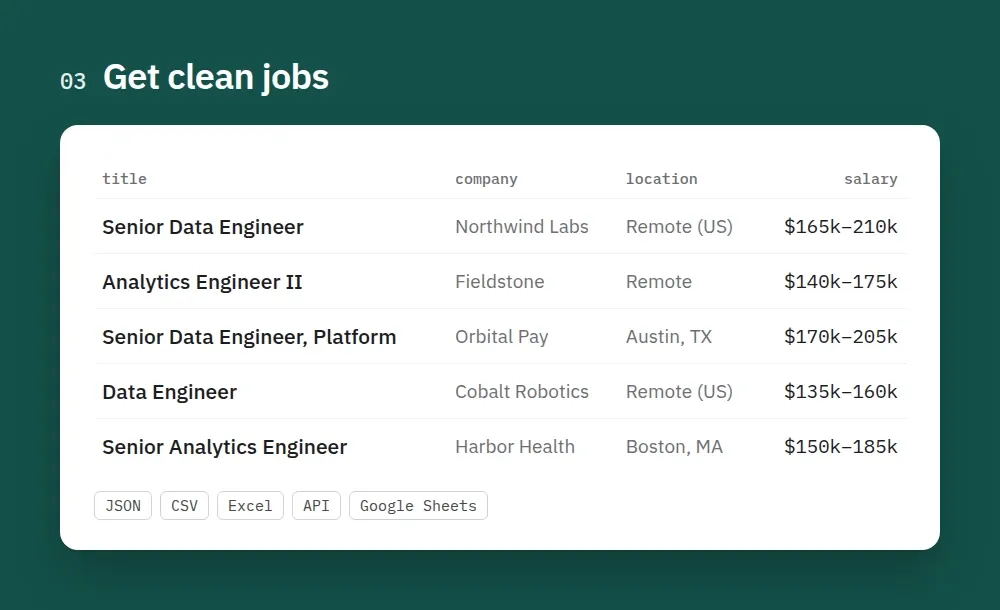
3. Get clean jobs. Every job comes with title, company, location, remote type, seniority, salary range when the company lists one, and the description in Markdown.
How to scrape company career sites
- Create a free Apify account (no credit card needed to start) and open this Actor.
- Choose how to run. Leave Companies empty to search the built-in directory of 12,000+ company boards by job title, or paste career-page links in Companies to read specific employers.
- Add filters. Use Job title keywords, Locations, Remote / hybrid / on-site, Seniority and Posted within (days). Exclude noisy recruiters with Exclude companies.
- Set the limit. Max jobs caps the total, Max jobs per company keeps one employer from filling the results.
- Click Start. Results appear in the Output tab while it runs.
- Download or connect. Export as JSON, CSV, Excel or HTML, or read the dataset through the API, Make, Zapier, n8n, Google Sheets or a webhook.
- Automate it. Open Schedules, add a daily schedule and switch on Only new jobs (and Also report closed jobs if you track removals).
Tips
- The directory covers Greenhouse, Lever, Ashby and Workday boards. For a company you care about, paste its careers link to read all its open jobs.
- A narrow search through the whole directory reads thousands of boards; the cost is explained in the Pricing section below.
- If a custom career page is not recognized, paste the underlying Greenhouse, Lever or Workday board link instead.
Two ways to run it
1. Search the directory (leave companies empty): the Actor checks the boards of 12,000+ companies (4,400 on Greenhouse, 1,400 on Lever, 2,200 on Ashby, 4,900 on Workday: US/EU tech, startups and large enterprises) and returns jobs matching your filters. It stops as soon as maxJobs is reached. Workday boards are searched when you give title keywords.
2. Scrape specific companies (fill companies): paste careers URLs, ats:slug pairs or just company names. The ATS is detected automatically:
| You paste | Platform |
|---|---|
https://boards.greenhouse.io/stripe, job-boards.greenhouse.io/airbnb, greenhouse:spacex | Greenhouse |
https://jobs.lever.co/palantir, jobs.eu.lever.co/... | Lever |
https://jobs.ashbyhq.com/ramp, ashby:notion | Ashby |
https://nvidia.wd5.myworkdayjobs.com/NVIDIAExternalCareerSite | Workday |
https://apply.workable.com/huggingface | Workable |
https://bunq.recruitee.com | Recruitee |
https://jobs.smartrecruiters.com/BoschGroup | SmartRecruiters |
https://acme.jobs.personio.de | Personio |
notion (just a name) | looked up in the directory, then tried on every platform |
https://careers.acme.com (own careers page) | the page is checked for an embedded board from the list above |
Your title / location / remote / seniority / date filters apply in both modes.
Output
status:open, orclosedfor the free closed-job notices (those only carry id, title, company, URL, location andclosedDetectedAt).ats:greenhouse,lever,ashby,workday,workable,recruitee,smartrecruitersorpersonio.seniority:internship,entry,mid,senior,lead,manager,director,executiveornull(title has no level word). "Product / Project / Account Manager" titles count asmid, not people managers.workplaceType:remote,hybrid,on-siteornullwhen the board doesn't say.employmentType:full-time,part-time,contract,internshipornull.salarySource:ats(structured pay range from the job board) ordescription(parsed from the ad text).salaryPeriod:hour,day,week,monthoryear.countryCodeis filled where the platform provides it (Lever, Ashby, Workday, Workable, Recruitee, SmartRecruiters).
Input
| Field | Description |
|---|---|
titleKeywords | Job title contains ANY of these (whole words: engineer matches "Engineering", java doesn't match "JavaScript"). Empty = all titles |
titleExcludeKeywords | Skip titles containing any of these |
locations | Location contains ANY of these words, e.g. New York, Germany, London, Remote, US |
workplaceTypes | remote, hybrid, on-site |
seniorityLevels | internship, entry, mid, senior, lead, manager, director, executive |
excludeCompanies | Skip companies whose name/slug contains these (agencies, aggregators) |
postedWithinDays | Only jobs first published in the last N days (0 = any) |
maxJobs | Stop after this many jobs (0 = no limit) |
companies | Scrape only these companies instead of the directory (see table above) |
maxJobsPerCompany | Cap per company, newest kept (0 = no cap) |
ats | Directory search only: limit to greenhouse, lever, ashby and/or workday |
onlyNewJobs | Skip jobs this same search returned in earlier runs |
reportClosedJobs | With onlyNewJobs: add a free closed record for jobs from earlier runs that were taken down |
Pricing
Pay per result, no monthly rental:
| Event | Price |
|---|---|
| Job | $2.00 per 1,000 jobs (full description, salary and seniority included) |
| Career sites checked | $0.0006 per 100 boards read ($0.006 per 1,000; $0.0004 until 21 Nov 2026) |
| Closed-job notice | free |
What that means in practice:
| Run | You pay |
|---|---|
| 20 jobs, stops early after ~200 boards | about $0.04 |
| Specific companies, 10 boards, 100 jobs | about $0.20 |
| Whole 12,900-company directory, 145 matching jobs | about $0.37 |
| Whole directory, only 5 matching jobs | about $0.09 |
Set "Maximum cost per run" in the run options to stay within budget. The Actor stops cleanly at your limit and never charges for jobs it doesn't deliver. The same job is returned (and charged) once per run, and boards that are retried after throttling are charged once.
Use with AI agents (Claude, ChatGPT, Cursor, MCP)
Add the Actor as a tool through the Apify MCP server: https://mcp.apify.com?actors=smoldesk/career-site-jobs-scraper. Then paste this into your agent's system prompt or tool notes, so it knows when to call it:
Questions an agent can answer with it:
- Which companies posted remote senior data engineer jobs this week, and what do they pay?
- List every open role at Stripe and Notion with salary ranges.
- Which of the jobs I tracked yesterday are now closed?
Your agent can pay for its own runs. This Actor is approved for agentic payments on Apify, so an agent with a Skyfire token or an x402 wallet can call it and pay per result without an Apify account. Skyfire: use https://mcp.apify.com?payment=skyfire. x402: buy a prepaid Apify token with USDC. Setup: Apify agentic payments docs.
Use with AI (LangChain / LlamaIndex / CrewAI)
Each job's markdown field is the full ad with HTML stripped and headings/lists kept, so it drops straight into an LLM pipeline. With LangChain (pip install langchain-apify):
Already have a run? Load its dataset with ApifyDatasetLoader(dataset_id="<run's dataset ID>", dataset_mapping_function=...) from the same package. LlamaIndex: ApifyActor from llama-index-readers-apify with the same actor_id and mapping. CrewAI / MCP clients: add the Actor as a tool through the Apify MCP server: https://mcp.apify.com?actors=smoldesk/career-site-jobs-scraper.
Tips
- A search that matches few jobs checks every board in the directory, which takes about 10 minutes (~$0.08 in board checks). A search that reaches
maxJobsearly finishes in under a minute. Narrow the directory withats(e.g. onlyworkdayfor large enterprises, or onlyashbyfor startups) to make it faster and cheaper. - Use
maxJobsPerCompany(e.g. 5) so a single big employer or job aggregator doesn't fill your whole result, andexcludeCompaniesto drop recruiting agencies. - Monitoring: turn on
onlyNewJobs, setpostedWithinDaysto2and schedule the Actor daily. Closed jobs come back as freestatus: "closed"records, so your job board can unpublish them. - Workday uses its own search ranking, so for big Workday employers the Actor reads the first pages of results for each keyword. For a complete list of one Workday company, put it in
companiesand leavetitleKeywordsempty. - Lever boards don't show a post date in their list, so with
postedWithinDaysthe Actor checks Lever jobs one by one. That's slower, but nothing extra to pay. - Missing a company? Put its careers URL in
companies. The directory is refreshed regularly.
FAQ
Do I need an account or API key for Greenhouse, Lever, Workday etc.? No. The Actor reads the same public job boards that candidates see.
Do I need proxies? No. All sources are public job-board APIs.
Is it legal? The Actor only collects job ads that employers publish openly for candidates. Follow privacy laws (GDPR, CCPA) in your use case if you store recruiter names or emails that appear in ad text.
Which ATS platforms aren't covered? iCIMS, Taleo, SuccessFactors and BambooHR are not supported yet. Pages using them are skipped with a warning and nothing is charged.
Feedback
Found a bug or missing a field? Open an issue in the Issues tab. If the Actor saved you time, a short review on this page helps other people find it.
Code examples and a quick reference are also on GitHub: smoldesk/career-site-jobs-scraper.
More Actors from Smoldesk Studios
- Airbnb Scraper: Airbnb listings with the price for your dates, full details (amenities, host, house rules, ratings), guest reviews and the 12-month availability calendar, no login
- Contact Details Scraper: emails, phone numbers, social profiles and contact forms from any list of websites, with email domains checked and junk removed, charged only when contacts are found
- Google Maps Scraper: places with phones, websites, ratings and hours from any search, plus emails and social profiles from each business website, lead filters and new-place monitoring
- WeChat Articles Scraper: WeChat Official Account (公众号) articles from keyword search, full text as Markdown, images, account IDs and publish dates, no login
- Toutiao Scraper: Toutiao (今日头条) news search with date ranges, reads and likes, comments and the hot board (热榜), no login
- YouTube Scraper: videos, Shorts, channels and comments from search, channels and playlists — exact views, likes, publish dates and durations, no API key
- YouTube Comments Scraper: comments and replies from videos, channels, playlists or keyword searches, with likes, pinned/hearted flags and authors
- YouTube Channel Scraper: subscribers, exact total views, join date, country and social links of any channel, plus its latest videos
- Google Ads Transparency Scraper: every ad a competitor runs on Google Search, YouTube and Shopping — creatives, landing pages, countries, EU impressions and new-ad alerts
- Weibo Scraper: keyword and hashtag search, posts, comments, profiles and the hot-search board from China's biggest microblog, no login
- Tennis Scraper: ATP, WTA, Challenger and ITF results and fixtures with odds from 15 bookmakers, H2H, players and rankings, back to the 2000s
- Google Hotels Scraper: hotel prices for your dates in any currency, ratings, review aspects and booking-site prices, worldwide
- Google Hotels Price Calendar: the cheapest nightly rate for every check-in date up to a year ahead, for any hotel, with taxes and booking-site prices
- Bilibili Scraper: videos, danmaku, comments and creator stats from China's YouTube (哔哩哔哩)
- Google Trends Scraper: interest over time, by region and city, related queries and Trending now — no API key
- SEEK, JobStreet & JobsDB Scraper: jobs and normalised salaries in 8 APAC countries
- Substack Scraper: newsletters, subscriber counts and posts
- Shopify Store Analyzer: products, prices and apps of any Shopify store
- Telegram Channel Scraper: public channel posts and stats


