
Contact Details Scraper – Emails, Phones, Socials from Websites
Pricing
from $1.50 / 1,000 website with contacts
Contact Details Scraper – Emails, Phones, Socials from Websites
Get emails, phone numbers, social profiles (Facebook, Instagram, LinkedIn, X, TikTok, YouTube, WhatsApp) and contact forms from any list of websites. Checks homepage + contact/about pages, flags emails whose domain takes no mail. Pay only for websites where contacts are found.
Pricing
from $1.50 / 1,000 website with contacts
Rating
0.0
(0)
Developer
Smoldesk Studios
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
4 hours ago
Last modified
Categories
Security
Limited permissionsShare
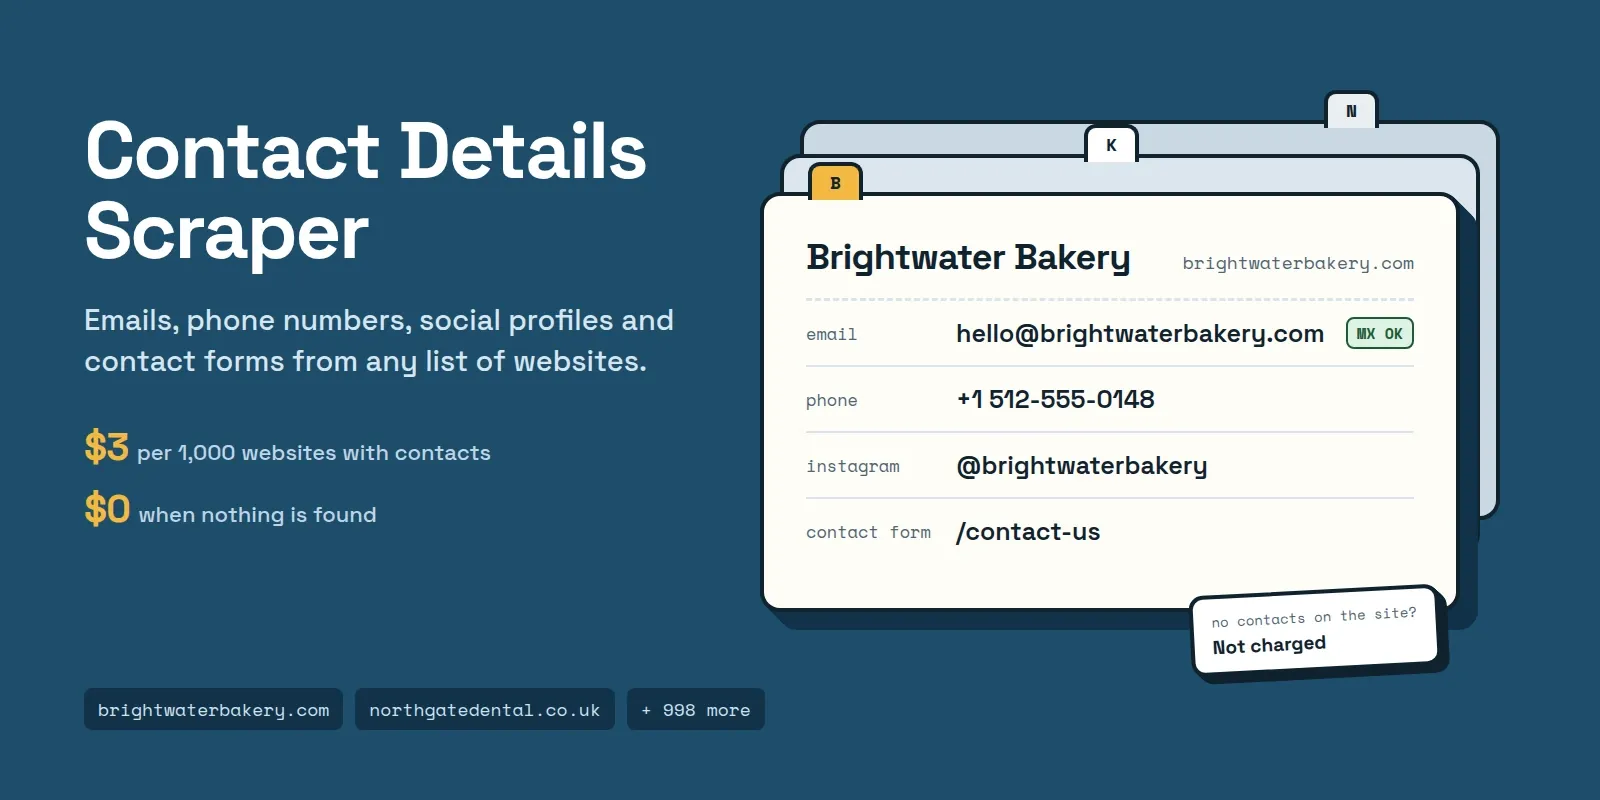
Give it a list of websites and get back each one's emails, phone numbers, social profiles (Facebook, Instagram, LinkedIn, X, TikTok, YouTube, Pinterest, WhatsApp, Telegram) and contact form, one clean row per website. The Actor reads the homepage plus the contact, about, team and legal pages, where businesses actually put their details. Every email comes with the page it was found on, whether it's on the website's own domain, and a free mail-server check of its domain. You pay only for websites where contacts were found. Websites with nothing, unreachable ones and duplicates are free.
Works great with a list from Google Maps Scraper: pick its dataset as the input and your places come back with emails and socials.
What you can use it for
- Lead generation: turn a list of company websites into a sheet of emails, phones and social profiles.
- Enrich a Google Maps or directory export: add emails and socials to the places you already have, joined back by name or place ID.
- Agencies and freelancers: find the right contact (and the contact form) for every prospect before you pitch.
- CRM clean-up: check which of your accounts still list an email, and whether that email's domain still takes mail.
- Social media research: collect the Instagram, TikTok and LinkedIn accounts behind a list of brands.
How to scrape contact details from websites
- Create a free Apify account and open this Actor.
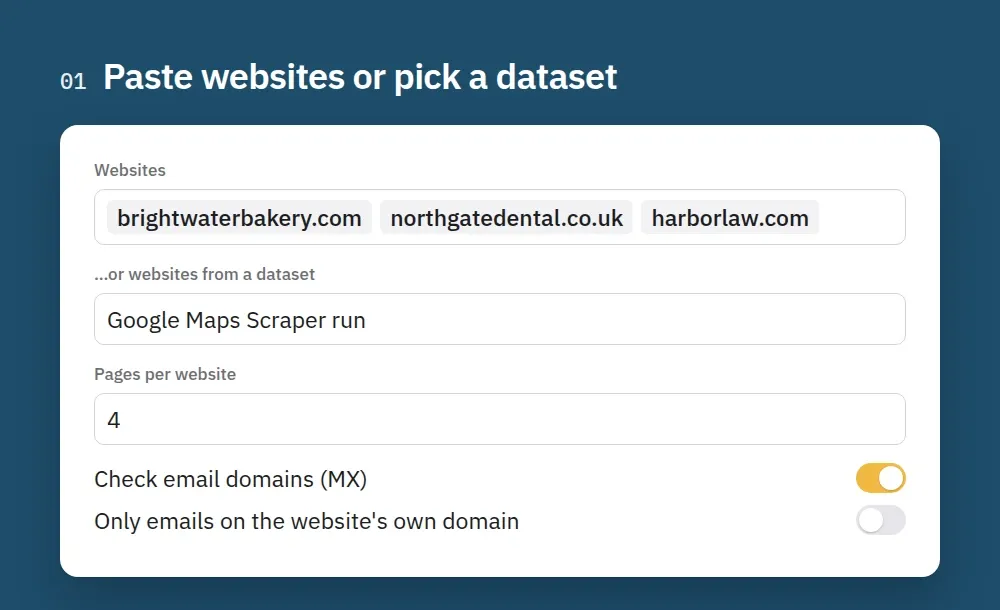
- Paste your websites into Websites, one per line. Full URLs or bare domains both work (
barleyswine.com). - Or pick a dataset in …or websites from a dataset, for example the results of a Google Maps Scraper run. The
websitefield is read by default. - Keep Pages per website at 4 (homepage + 3 contact-like pages). That finds almost everything.
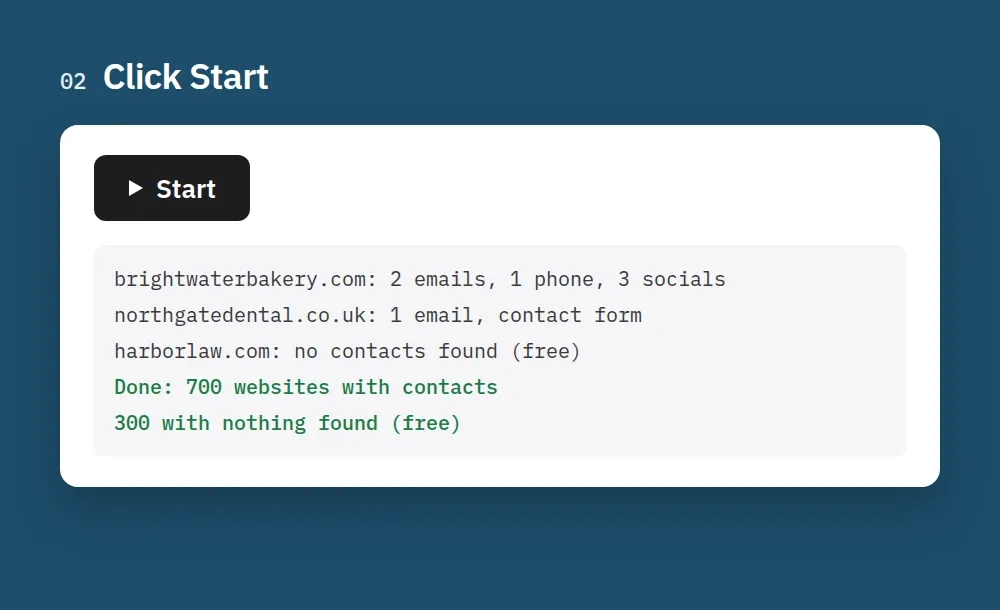
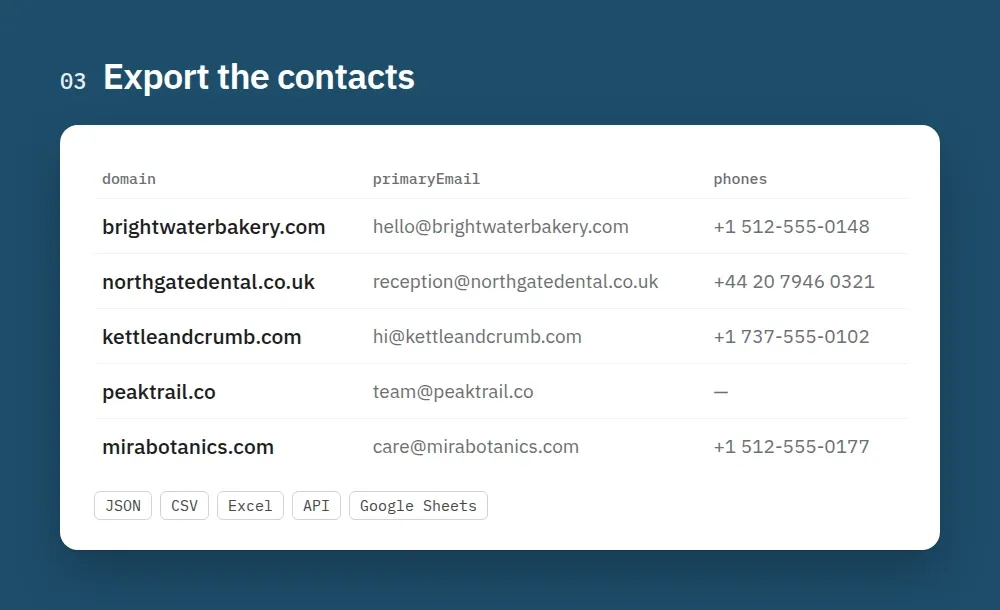
- Click Start. About 700 websites take 6 minutes. Download the results as CSV, Excel or JSON, or read them through the API.
What we measured
We ran it on 690 restaurant websites in Austin, TX (the websites from a Google Maps search):
| Result | Websites |
|---|---|
| Contacts found (charged) | 506 (73%) |
| …with at least one email | 360 |
| …with a social profile | 423 |
| …with a phone number | 219 |
| …with a contact form | 172 |
| No contacts on the website (free) | 84 |
| Protected by a bot check, not scraped (free) | 53 |
| Unreachable, 403/404 or not a web page (free) | 33 |
| A social profile given instead of a website (free) | 14 |
The run took 6 minutes. On the Free plan it would cost $1.52 (506 × $0.003).
Output
One row per website. The Contacts view shows the flat columns; Email details and Run report show the rest.
| Field | What it is |
|---|---|
primaryEmail | The best email: on the website's own domain and from structured data or a mailto: link first, emails whose domain takes no mail last |
emails / phones | All emails and phone numbers as plain lists (phones in international format) |
facebook, instagram, linkedin… | The first profile of each network, ready for a spreadsheet; socialProfiles has all of them |
contactFormUrl | A page with a contact form (a message box or an email + name form, not a newsletter box) |
emailDetails[].foundIn | schema.org (the site's structured data), mailto link, page text or page source |
emailDetails[].ownDomain | true when the email is on the website's domain (info@theirsite.com) |
emailDetails[].domainAcceptsMail | Result of the DNS check: false means the domain has no mail server (a typo like gmail.co, or a dead domain) |
status | contacts found, no contacts found, protected by a bot check (not scraped), unreachable: …, blocked or missing (HTTP 4xx) |
sourceData | Fields copied from your dataset row, so you can join the results back (null for websites typed into the list) |
Every row has the same fields, including websites with nothing found (empty lists and null), so CSV columns stay the same from run to run.
Clean emails, not junk
Contact scrapers often return emails that aren't anyone's real contact. This one removes or flags them:
- Removed:
noreply@, placeholders (you@example.com,name@yourdomain.com), image file names (logo@2x.png), error-tracking keys (…@o123.ingest.sentry.io), template emails from website builders and font licences. - Social links that aren't the business are dropped: the website builder's own accounts in the footer (
facebook.com/wix,instagram.com/squarespace), share buttons and the oldfacebook.com/2008/fbmlcode that sits in many page headers. - Emails glued to the next word are repaired:
info@shop.comsocial→info@shop.com, but only when the repaired domain really takes mail. - Every email's domain is checked in DNS (MX record). Typos and dead domains are marked
domainAcceptsMail: falseand moved to the end, or removed with Drop emails whose domain takes no mail. - Emails written as
name [at] domain [dot] comare read too.
Gmail addresses and a parent company's domain are kept, because many small businesses use them. Switch on Only emails on the website's own domain if you want just @theirdomain emails.
Input examples
A list of websites:
Enrich a Google Maps Scraper run (pick its dataset in the input, or paste the ID):
Strict B2B list: own-domain emails only, dead domains removed, UK numbers:
Pricing
You pay once per website where at least one email, phone number or social profile was found, with a lower price on bigger Apify plans.
| Event | Free plan | Starter | Scale | Business |
|---|---|---|---|---|
| Website with contacts | $3.00 / 1,000 | $2.50 / 1,000 | $2.00 / 1,000 | $1.50 / 1,000 |
| Actor start | $0.00005 | $0.00005 | $0.00005 | $0.00005 |
Free: websites with no contacts, unreachable or bot-protected websites, duplicates and social-profile URLs. The price is the same whether the Actor reads 1 page or 10, so you never pay for pages crawled. Proxy and compute are included.
Example: 1,000 websites where 7 in 10 have contacts (what we measured) = 700 × $0.003 = $2.10 on the Free plan, $1.05 on Business. Set Maximum cost per run in the run options and the Actor stops before going over it.
Use with AI agents (Claude, ChatGPT, Cursor, MCP)
Add the Actor as a tool through the Apify MCP server: https://mcp.apify.com?tools=smoldesk/contact-details-scraper. In Claude Desktop, Claude Code, Cursor or VS Code, add this to your MCP config (you sign in to Apify in the browser on first use, or put your API token in a headers → Authorization: Bearer <APIFY_TOKEN> field instead):
Or let the Apify CLI write it for you: apify mcp install cursor --tools smoldesk/contact-details-scraper (also claude-code, vscode, codex). Then paste this into your agent's system prompt or tool notes:
Questions an agent can answer with it:
- Find the contact email and Instagram of these 20 agencies.
- Which of the companies in this sheet have a contact form?
- Add emails to the places in my last Google Maps Scraper run.
Use with AI (LangChain / LlamaIndex / CrewAI)
With LangChain (pip install langchain-apify):
Already have a run? Use ApifyDatasetLoader(dataset_id="<run's dataset ID>", dataset_mapping_function=...). LlamaIndex: ApifyActor from llama-index-readers-apify. CrewAI: use the Apify MCP server above.
Limitations
- Websites behind a bot check are skipped, not scraped. About 8% of the restaurant websites we tested show a Cloudflare "Just a moment…" page to scripts. The Actor doesn't try to get around these checks. It marks the row
protected by a bot check (not scraped)and doesn't charge for it. - No browser. Contacts that appear only after JavaScript runs (some single-page apps, or emails loaded by a widget) are missed. Most business websites (WordPress, Squarespace, Wix, Shopify, Webflow) show their contacts in the HTML and work fine.
- Emails protected by Cloudflare's email obfuscation, or shown only as an image, are not read. The website owner hid them on purpose.
- Emails are not verified by sending mail. The DNS check tells you the domain accepts mail, not that the mailbox exists.
- Phones: numbers in
tel:links and structured data are always read. Numbers written in plain text are read when the country is known, from Country for local phone numbers or the website's country domain (.co.uk,.de,.com.my). On.comsites set the country to pick them up. - It reads only the website you give it, not LinkedIn, Facebook or search engines, and doesn't guess emails from names.
FAQ
How is this priced compared with crawler-based contact scrapers? Many charge for every page they crawl, so a website with nothing on it still costs you. Here a website costs nothing unless it gave at least one email, phone or social profile, and the price doesn't change with the number of pages read.
Which pages does it read? The homepage, then the best contact-like links on it: contact first, then about, team and legal / impressum / privacy, in many languages (kontakt, contacto, hubungi, 联系, お問い合わせ…). If no contact link is found it tries /contact.
Can I use the results of Google Maps Scraper? Yes. Pick that run's dataset in …or websites from a dataset. The website field is read and name, placeId, phone, address and category are copied into sourceData.
Do I need proxies? No. If a website refuses the run's IP, the Actor retries it once through an Apify datacenter proxy on its own. Residential proxies are never used.
Is it legal to scrape contact details? The Actor reads only pages that are public on the business's own website. You are responsible for how you use the data, especially for contacting people (GDPR, CAN-SPAM and similar rules).
Feedback
Found a bug or a website where contacts were missed? Open an issue in the Issues tab with the URL. If the Actor saved you time, a short review on this page helps other people find it.
Code examples and a quick reference are also on GitHub: smoldesk/contact-details-scraper.
More Actors from Smoldesk Studios
- Google Maps Scraper: places with phones, websites, ratings and hours from any search, plus emails and social profiles from each business website, lead filters and new-place monitoring
- Career Site Jobs Scraper: live jobs from 12,000+ company career sites (Greenhouse, Lever, Workday, Ashby) with salary and seniority
- Shopify Store Analyzer: apps, contacts and products of any Shopify store
- Google Ads Transparency Scraper: every ad a competitor runs on Google Search, YouTube and Shopping — creatives, landing pages, countries, EU impressions and new-ad alerts
- Google Hotels Scraper: hotel prices for your dates in any currency, ratings, review aspects and booking-site prices, worldwide
- Google Hotels Price Calendar: the cheapest nightly rate for every check-in date up to a year ahead, for any hotel, with taxes and booking-site prices
- Google Trends Scraper: interest over time, by region and city, related queries and Trending now — no API key
- YouTube Scraper: videos, Shorts, channels and comments from search, channels and playlists — exact views, likes, publish dates and durations, no API key
- YouTube Comments Scraper: comments and replies from videos, channels, playlists or keyword searches, with likes, pinned/hearted flags and authors
- YouTube Channel Scraper: subscribers, exact total views, join date, country and social links of any channel, plus its latest videos
- Tennis Scraper: results, fixtures and betting odds for ATP, WTA, Challenger and ITF, with H2H and rankings
- SEEK, JobStreet & JobsDB Scraper: jobs and salaries across Australia and Southeast Asia
- Telegram Channel Scraper: public channel posts, views, reactions and subscribers
- Substack Scraper: newsletters, subscriber counts and posts
- Weibo Scraper: keyword and hashtag search, posts, comments, profiles and the hot-search board from China's biggest microblog, no login
- WeChat Articles Scraper: WeChat Official Account (公众号) articles from keyword search, full text as Markdown, images, account IDs and publish dates, no login
- Toutiao Scraper: Toutiao (今日头条) news search with date ranges, reads and likes, comments and the hot board (热榜), no login
- Bilibili Scraper: videos, stats, danmaku, comments and creators from China's video site, no login


