
Substack Scraper – Newsletters, Subscribers & Posts
Pricing
from $3.00 / 1,000 newsletters
Substack Scraper – Newsletters, Subscribers & Posts
Scrape Substack newsletters without login: subscriber counts, paid tiers, prices, author socials and posts with likes, comments and full text. Discover newsletters by category.
Pricing
from $3.00 / 1,000 newsletters
Rating
0.0
(0)
Developer
Smoldesk Studios
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
2
Monthly active users
3 hours ago
Last modified
Categories
Security
Limited permissionsShare
Substack Scraper – Subscriber Counts, Newsletters & Posts
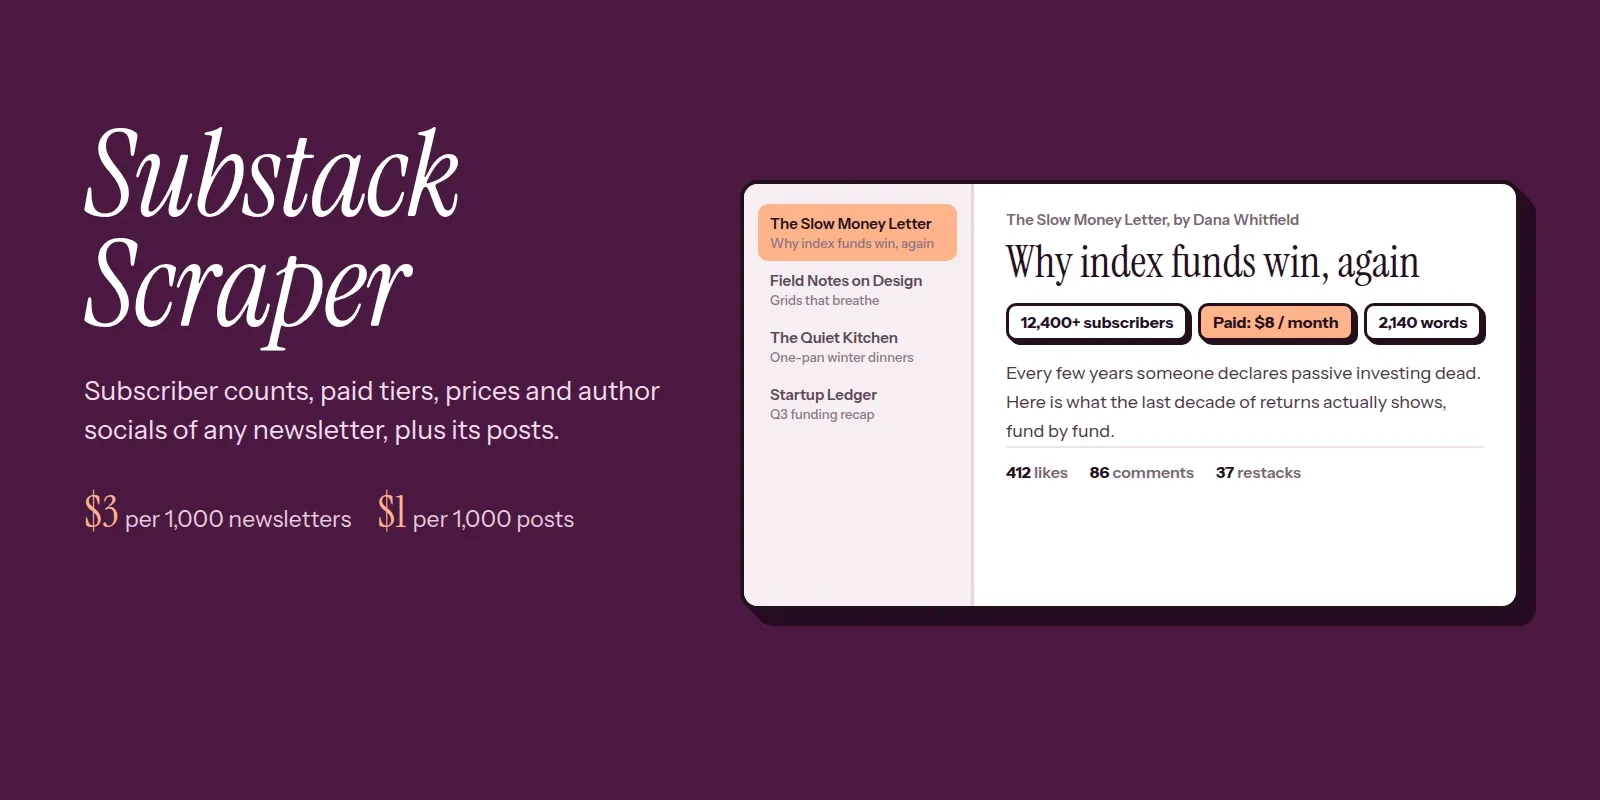
Scrape Substack newsletters without login or API keys. Get each newsletter's subscriber count, paid subscriber tier, subscription prices, author bio and X/Twitter, plus posts with likes, comments, restacks, word count and optional full text.
Discover newsletters by category, too (Technology, Business, Finance, Crypto and 28 more), straight from Substack's leaderboards.
What you can use it for
- Sponsorship & influencer marketing: find newsletters in your niche with their audience size, then shortlist the best fit for ads.
- Lead generation: build lists of creators with subscriber counts, paid status and X/Twitter handles.
- Competitor & content research: see which topics and formats get the most likes, comments and restacks.
- Market research: compare pricing of paid newsletters in a category.
- AI / LLM datasets: collect clean full-text posts for summarization, RAG or trend analysis.
How to use it
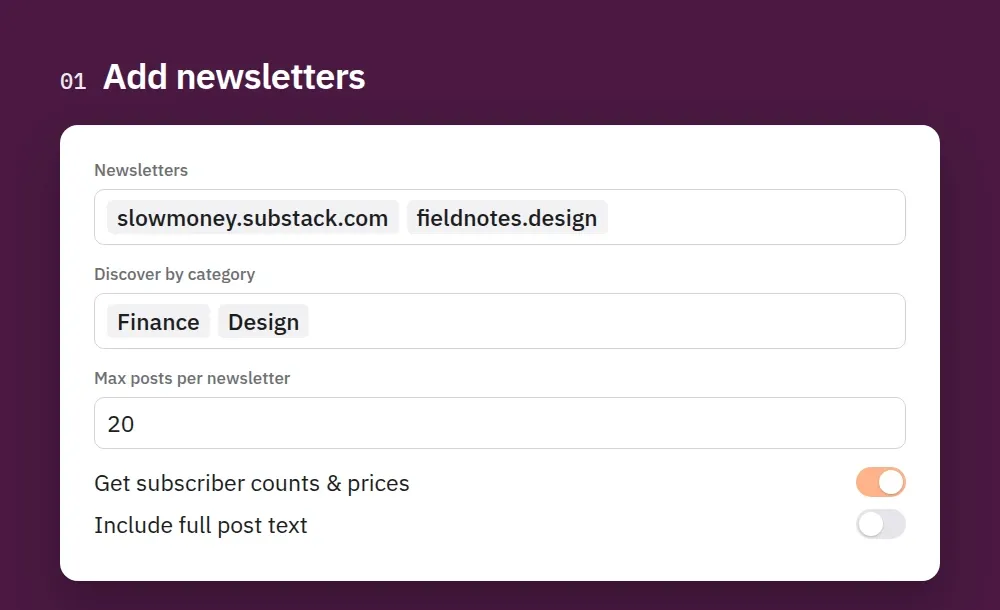
1. Add newsletters. Paste newsletter URLs or pick Substack categories to discover new ones, and choose how many posts to read.
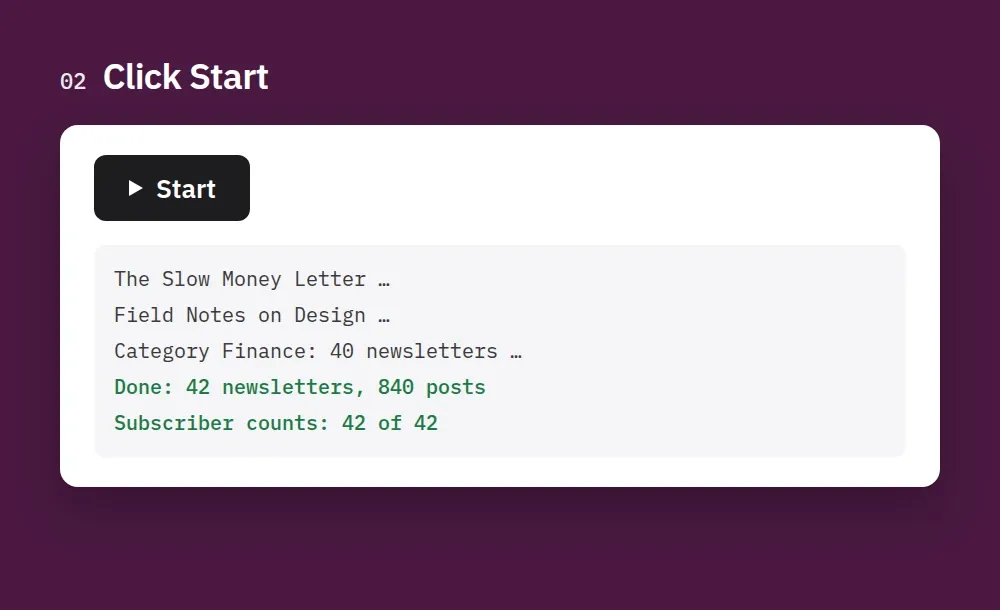
2. Click Start. Each newsletter's profile comes first, then its latest posts.
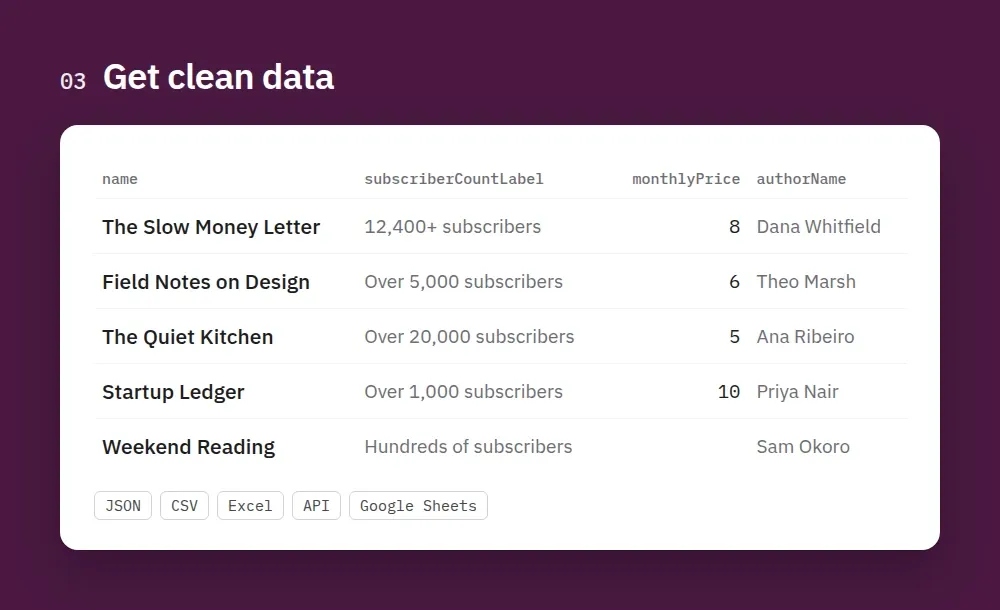
3. Get clean data. One row per newsletter with subscriber count, prices and author, plus one row per post. Export it as JSON, CSV or Excel, or read it through the API.
How to scrape Substack
- Create a free Apify account (no credit card needed to start) and open this Actor.
- Pick the newsletters. Paste newsletter links or names in Newsletters, or use Discover by category to find the top newsletters of a topic.
- Get the numbers. Leave Get subscriber counts & prices on to see subscriber counts and paid-plan prices.
- Add posts (optional). Turn on Include posts, set Max posts per newsletter and Posts published after. Add Include full post text if you want the article body for AI or analysis.
- Click Start. Results appear in the Output tab while it runs.
- Download or connect. Export as JSON, CSV, Excel or HTML, or read the dataset through the API, Make, Zapier, n8n, Google Sheets or a webhook.
- Automate it. Open Schedules and run weekly with Posts published after set to last week to track new posts.
Tips
- Subscriber counts are only shown by newsletters that make them public; the rest return no count.
- Substack now shows subscriber counts as ranges ("Over 266,000 subscribers", label
266K+).freeSubscriberCountis that lower bound; usesubscriberCountLabelfor the public label. - Combine Discover by category with subscriber counts to build a lead list of newsletters in a niche.
- Paid posts return their free preview only.
Output: newsletter
Output: post
Input
| Field | Description |
|---|---|
publications | Subdomains (lenny), *.substack.com URLs or custom domains |
categories | Discover newsletters from Substack category leaderboards |
maxPublicationsPerCategory | How many newsletters per category |
enrichPublications | Subscriber counts, prices and author socials (recommended) |
includePosts / maxPostsPerPublication / postsSince | Which posts to return |
includePostContent | Full HTML + clean text (paid posts: free preview only) |
Pricing
Pay per result, no monthly rental:
| Event | Price |
|---|---|
| Newsletter (with subscriber count, prices, author socials) | $3.00 per 1,000 newsletters |
| Post | $1.00 per 1,000 posts |
Example: 200 newsletters from a category with their last 10 posts each cost $2.60. Set "Maximum cost per run" in the run options to stay within budget. The Actor stops cleanly at your limit.
Use with AI agents (Claude, ChatGPT, Cursor, MCP)
Add the Actor as a tool through the Apify MCP server: https://mcp.apify.com?actors=smoldesk/substack-scraper. Then paste this into your agent's system prompt or tool notes, so it knows when to call it:
Questions an agent can answer with it:
- Which Substack newsletters in the tech category have the most subscribers, and what do they charge?
- Summarize Lenny's last 10 posts and which ones got the most likes.
- Find the Twitter and LinkedIn links of these newsletter authors.
Your agent can pay for its own runs. This Actor is approved for agentic payments on Apify, so an agent with a Skyfire token or an x402 wallet can call it and pay per result without an Apify account. Skyfire: use https://mcp.apify.com?payment=skyfire. x402: buy a prepaid Apify token with USDC. Setup: Apify agentic payments docs.
Use with AI (LangChain / LlamaIndex / CrewAI)
Turn on includePostContent and each post's contentText is clean plain text, ready for summarization, trend analysis or RAG. With LangChain (pip install langchain-apify):
Already have a run? Load its dataset with ApifyDatasetLoader(dataset_id="<run's dataset ID>", dataset_mapping_function=...). LlamaIndex: ApifyActor from llama-index-readers-apify. CrewAI / Claude / MCP clients: add it as a tool via the Apify MCP server: https://mcp.apify.com?actors=smoldesk/substack-scraper.
Limitations
- Subscriber counts are what Substack shows publicly (e.g. "1.2M+"). Some newsletters hide them.
- Paid posts only include the free preview text.
- Only public data is collected. No login, emails or private subscriber lists.
FAQ
Does Substack have an API? Not an official public one. This Actor reads the same public pages and endpoints any visitor's browser loads, so you get structured data without an API key or login.
Can I get subscriber emails? No. Subscriber lists are private. You get the public subscriber count and the author's public profile and X/Twitter.
Do I need proxies? No. It works without a proxy.
Is it legal? This Actor only collects data that Substack publishes openly to every visitor. Respect copyright when reusing post content, and follow privacy laws when contacting creators.
Feedback
Found a bug or missing a field? Open an issue in the Issues tab. If the Actor saved you time, a short review on this page helps other people find it.
Code examples and a quick reference are also on GitHub: smoldesk/substack-scraper.
More Actors from Smoldesk Studios
- Contact Details Scraper: emails, phone numbers, social profiles and contact forms from any list of websites, with email domains checked and junk removed, charged only when contacts are found
- Google Maps Scraper: places with phones, websites, ratings and hours from any search, plus emails and social profiles from each business website, lead filters and new-place monitoring
- WeChat Articles Scraper: WeChat Official Account (公众号) articles from keyword search, full text as Markdown, images, account IDs and publish dates, no login
- Toutiao Scraper: Toutiao (今日头条) news search with date ranges, reads and likes, comments and the hot board (热榜), no login
- YouTube Scraper: videos, Shorts, channels and comments from search, channels and playlists — exact views, likes, publish dates and durations, no API key
- YouTube Comments Scraper: comments and replies from videos, channels, playlists or keyword searches, with likes, pinned/hearted flags and authors
- YouTube Channel Scraper: subscribers, exact total views, join date, country and social links of any channel, plus its latest videos
- Google Ads Transparency Scraper: every ad a competitor runs on Google Search, YouTube and Shopping — creatives, landing pages, countries, EU impressions and new-ad alerts
- Weibo Scraper: keyword and hashtag search, posts, comments, profiles and the hot-search board from China's biggest microblog, no login
- Tennis Scraper: ATP, WTA, Challenger and ITF results and fixtures with odds from 15 bookmakers, H2H, players and rankings, back to the 2000s
- Google Hotels Scraper: hotel prices for your dates in any currency, ratings, review aspects and booking-site prices, worldwide
- Google Hotels Price Calendar: the cheapest nightly rate for every check-in date up to a year ahead, for any hotel, with taxes and booking-site prices
- Bilibili Scraper: videos, danmaku, comments and creator stats from China's YouTube (哔哩哔哩)
- Google Trends Scraper: interest over time, by region and city, related queries and Trending now — no API key
- Telegram Channel Scraper: public channel posts, views, reactions and subscribers
- Shopify Store Analyzer: apps, contacts and products of any Shopify store
- SEEK, JobStreet & JobsDB Scraper: jobs and salaries across Australia and Southeast Asia
- Career Site Jobs Scraper: live jobs from 12,000+ company career sites (Greenhouse, Lever, Workday, Ashby) with salary and seniority


