
Toutiao Scraper – News, 微头条 Posts, Comments & Hot Board
Pricing
from $2.00 / 1,000 article or videos
Toutiao Scraper – News, 微头条 Posts, Comments & Hot Board
Scrape Toutiao (今日头条) without login: keyword search of news and 微头条 posts with date ranges, reads, likes, comments and shares, comment threads and the hot board (热榜). Articles $2 per 1,000, posts $4 per 1,000.
Pricing
from $2.00 / 1,000 article or videos
Rating
0.0
(0)
Developer
Smoldesk Studios
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 hours ago
Last modified
Categories
Security
Limited permissionsShare
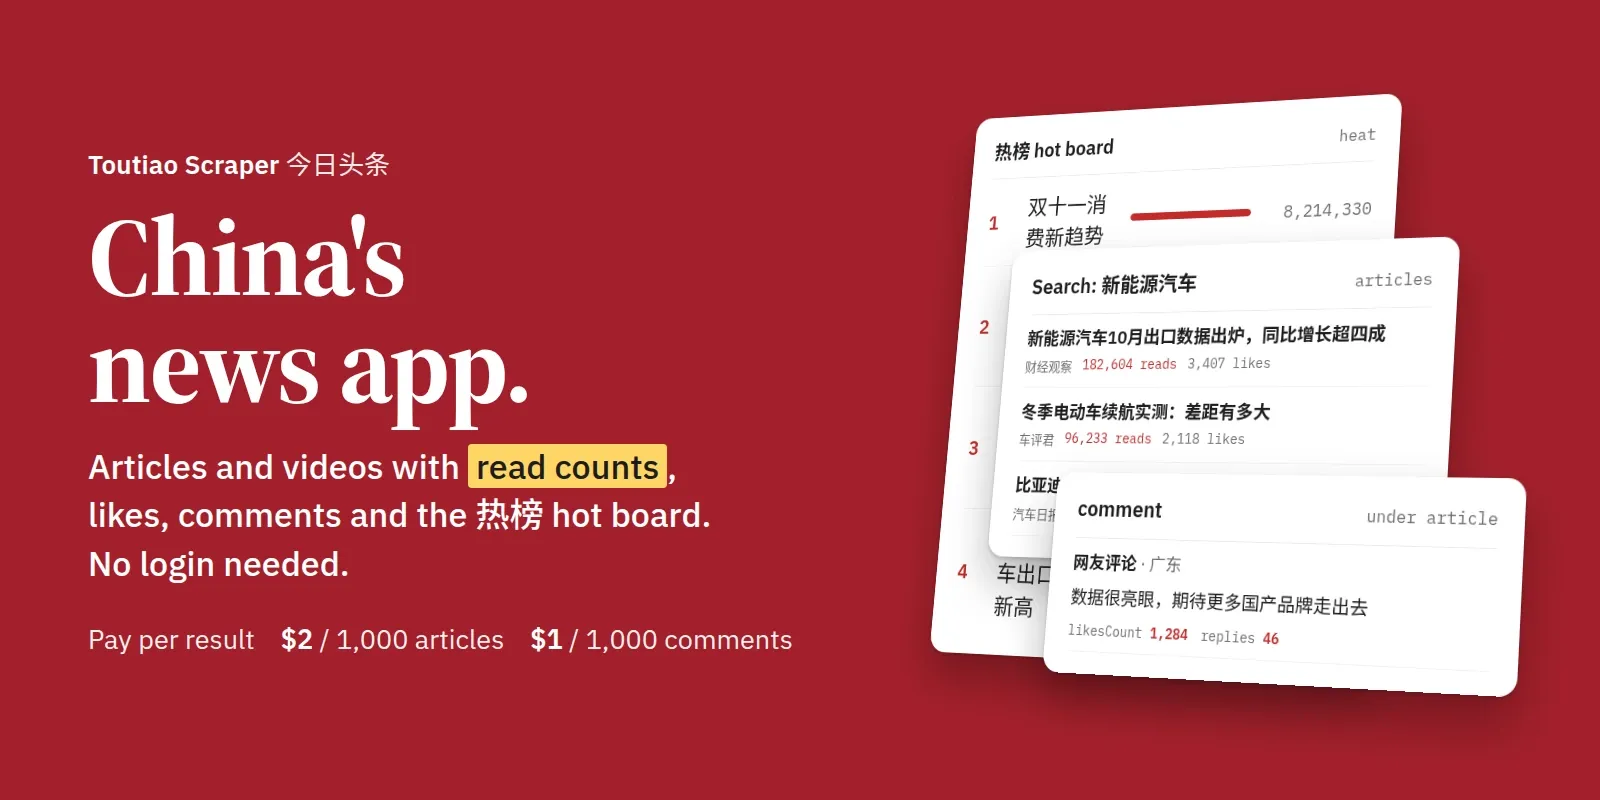
Scrape Toutiao (今日头条), China's biggest news app, without login, cookies or an API key. Search any keyword with date ranges and get articles and videos with title, summary, publish time, author and verification, reads, plays, likes, comments, shares and saves, cover images and Toutiao's content categories. Switch the search to 微头条 posts (Toutiao's short posts, like Weibo) and get the full post text, images, hashtags, author, reads, likes, comments and shares. Add the comments and reply threads under any article or post, and the Toutiao hot board (头条热榜) with rank and heat score.
Mix sources in one run: keywords (news, posts or both), article and post links and the hot board together. Results found twice are saved once. Articles and videos cost $2 per 1,000, 微头条 posts $4 per 1,000, comments and hot-board topics $1 per 1,000. No monthly fee.
**中文用户:**本页下方有完整的「中文使用说明」。
What you can use it for
- Brand and PR monitoring in China: every Toutiao article that mentions your brand, product or competitor, with reads and comment counts so you see what spreads.
- Market and sentiment research: Chinese news coverage and reader comments (with the commenter's province) for any topic.
- Social listening on 微头条: what users, creators and media accounts post about your brand in their own words, with hashtags, images and engagement, the way you would track Weibo.
- Trend tracking: snapshot the hot board every hour and watch which stories rise and fall.
- Media and KOL research: find which accounts (官方账号, 创作者) write about a niche and how much engagement they get.
- AI / NLP datasets: each article has a clean
markdownfield (title, summary, source, date, link) for RAG pipelines and LLM prompts. - Scheduled feeds: turn on Only new results to get only the articles you haven't seen yet for a keyword.
How to use it
1. Add what to follow. Type keywords, pick a date range and switch on comments or the hot board (热榜) if you want them.
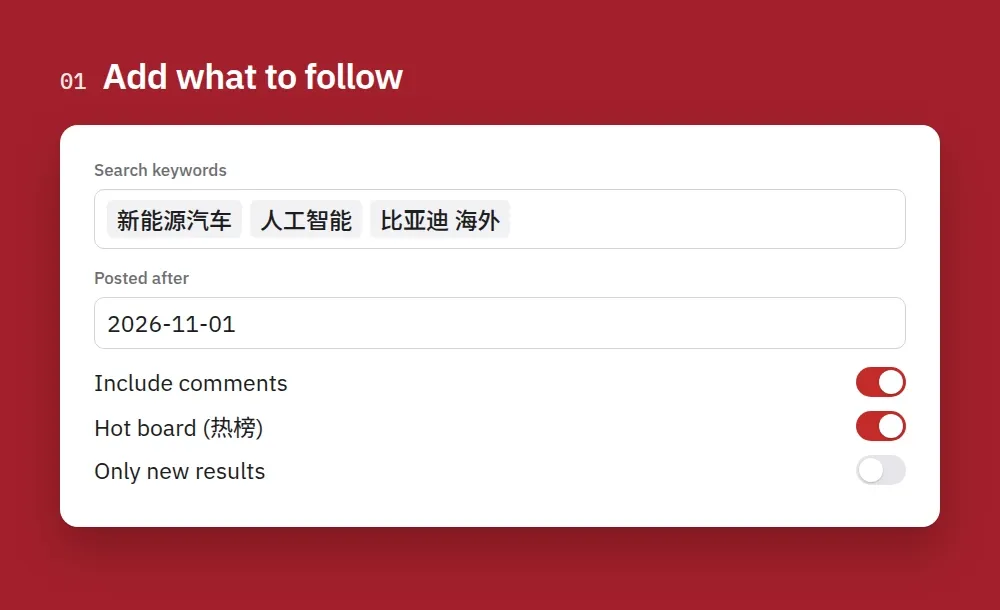
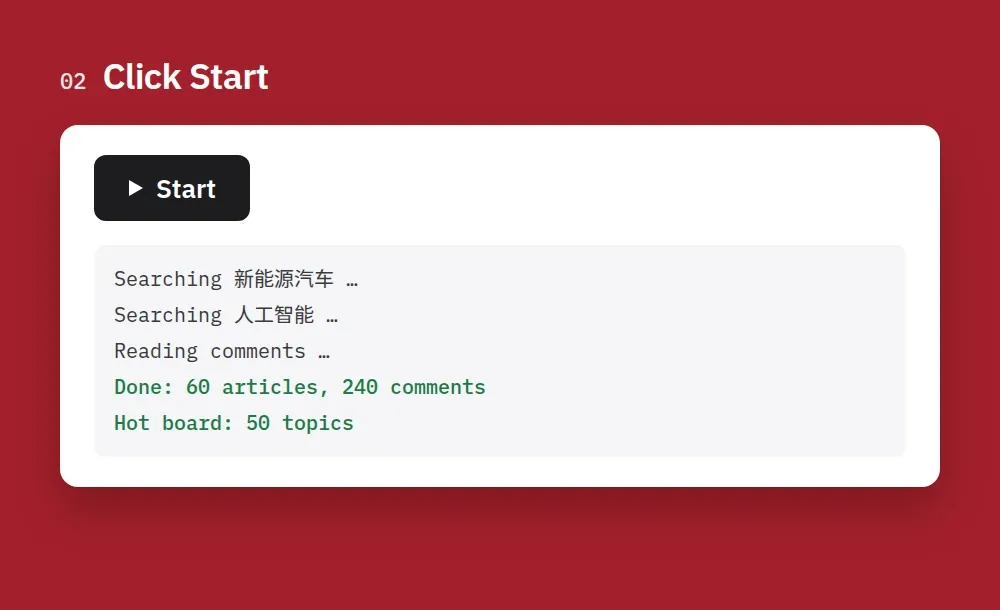
2. Click Start. Six keywords with 100 results each plus their comments take about 2 minutes.
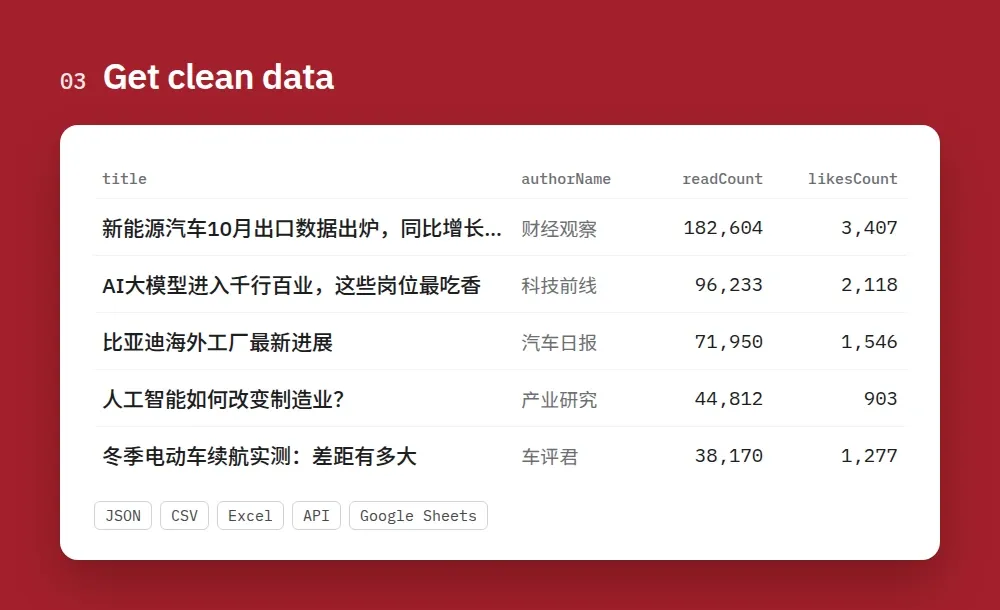
3. Get clean data. Every article comes with title, author, reads, likes, comments and shares. Export it as JSON, CSV or Excel, or send it to Google Sheets or your app through the API.
How to scrape Toutiao
- Create a free Apify account (no credit card needed to start) and open this Actor.
- Pick what you want in the input form. Add Search keywords and choose Search in: News (articles and videos), Posts (微头条) or Both. Switch on Hot board for trending topics, or paste Article, video or post URLs to collect their comments. You can fill several at once.
- Set the limits. Max results per search is how many articles each keyword returns. Use Posted after / Posted before to focus on a period. Turn on Include comments for search results if you want the discussion too.
- Click Start. Six keywords with 100 results each plus their comments take about 2 minutes. Results appear in the Output tab while it runs.
- Download or connect. Export as JSON, CSV, Excel or HTML, or read the dataset through the API, Make, Zapier, n8n, Google Sheets or a webhook.
- Automate it. Open Schedules, add a daily or hourly schedule, and switch on Only new results so each run returns only articles and posts it hasn't seen before.
Ready-made tasks you can run, save and schedule in one click: Monitor a brand on Toutiao (news + 微头条 posts, new only) · 微头条 posts + comments for sentiment research · Toutiao hot board (头条热榜), top 50.
Tips
- Search in Chinese for the best results (小米汽车, not "Xiaomi car"). English brand names also work.
- Toutiao asks logged-out visitors to solve a captcha for a few very broad brand names on their own (比亚迪, sometimes 华为). The Actor skips those keywords without charging and tells you in the log; a more specific keyword works (比亚迪汽车, 华为手机, 华为Mate80).
- Toutiao returns about 100 results per keyword, and fewer when you set a date range. To cover a whole month, run one search per week with Posted after / before.
- The hot board changes all day. Schedule it hourly and compare
rankandheatover time. Each topic has asearchUrlyou can feed back in as a keyword.
中文使用说明
无需登录、Cookie 或 API 密钥,即可采集今日头条的公开数据:按关键词搜索文章和视频(标题、摘要、发布时间、作者及认证信息,以及阅读/播放、点赞、评论、分享和收藏数)、微头条(全文、图片和话题)、文章和微头条下的评论与回复,以及头条热榜。输入表单中的字段名为英文,下文以粗体标出,方便对照。
- 注册免费的 Apify 账号(开始使用无需绑定信用卡),然后打开本 Actor。
- 选择要采集的内容(可同时填写多项):
- Search keywords:搜索关键词,并在 Search in 中选择 News(文章和视频)、Posts (微头条) 或 Both(两者都要)。
- Hot board (热榜):打开后采集头条热榜。
- Article, video or post URLs (comments):粘贴文章、视频或微头条的链接,采集其评论。
- 设置数量和时间范围:Max results per search 是每个关键词返回的结果数量;Posted after / Posted before 用于限定发布时间段。如需同时采集搜索结果下的评论,请打开 Include comments for search results。
- 点击 Start。6 个关键词、每个 100 条结果并含评论,大约需要 2 分钟。运行期间结果会实时显示在 Output 标签页中。
- 导出或对接数据:可导出为 JSON、CSV、Excel 或 HTML,也可以通过 API、Make、Zapier、n8n、Google Sheets 或 Webhook 获取数据。
- 定时监测:在 Schedules 中添加每天或每小时运行的定时任务,并打开 Only new results (monitor mode)。之后每次运行只返回此前未采集过的文章和微头条。
提示:用中文搜索效果最好(例如用“小米汽车”,而不是“Xiaomi car”)。少数非常宽泛的品牌词(如“比亚迪”,有时还有“华为”)会要求未登录访客完成验证码。本 Actor 会跳过这些关键词,不收费,并在日志中说明;请改用更具体的关键词,例如“比亚迪汽车”“华为手机”。
价格(每 1,000 条):文章或视频 $2,微头条 $4,评论或回复 $1,热榜话题 $1。无月费,未保存的数据不收费。可在运行选项中设置单次运行的最高费用,达到上限后 Actor 会自动停止。
限制:不提供文章正文(头条的文章页面设有浏览器验证),但会提供标题、摘要、各项互动数据和链接;微头条和评论均为完整内容。每个关键词在每个类型下约返回 100 条结果。无法获取作者的发布列表和粉丝列表。
Output: article or video
Videos have "type": "video", a /video/ URL, playCount and durationSeconds.
Output: 微头条 post
text is the full post text with line breaks. hashtags are the topics the author tagged (without #), links any web links in the post. readCount is Toutiao's read/view count.
Output: comment or reply
Comments under a post have the post's /w/ link in articleUrl.
Output: hot-board topic
Input
Leave the input empty to get a small sample.
Pricing
You pay per result, plus a tiny start fee. No monthly fee, and you are never charged for items that were not saved.
| Result | Price per 1,000 |
|---|---|
| Article or video | $2.00 |
| 微头条 post | $4.00 |
| Comment or reply | $1.00 |
| Hot-board topic | $1.00 |
Set the maximum cost per run in the run options and the Actor stops there. Example: 6 keywords (475 articles) plus 1,414 comments and replies and the 50-topic hot board is about $2.40. The same 6 keywords on the posts tab (600 posts) add about $2.40.
Use with AI agents (Claude, ChatGPT, Cursor, MCP)
Add the Actor as a tool through the Apify MCP server: https://mcp.apify.com?actors=smoldesk/toutiao-scraper. Then paste this into your agent's system prompt or tool notes, so it knows when to call it:
Questions an agent can answer with it:
- How did Chinese news media cover BYD's overseas sales this month? List the most-read articles.
- What are people posting on Toutiao about Luckin Coffee's latest collab? Summarize the complaints.
- What's trending on Toutiao's hot board today? Translate the top 10.
- Collect the reader comments under this Toutiao article and summarize the reaction.
Your agent can pay for its own runs. This Actor is approved for agentic payments on Apify, so an agent with a Skyfire token or an x402 wallet can call it and pay per result without an Apify account. Skyfire: use https://mcp.apify.com?payment=skyfire. x402: buy a prepaid Apify token with USDC. Setup: Apify agentic payments docs.
Use with AI (LangChain / LlamaIndex / CrewAI)
Each article and post has a markdown field (text or title and summary, images, source, date and link) and each comment has a text field, ready for LLMs. With LangChain (pip install langchain-apify):
Already have a run? Use ApifyDatasetLoader(dataset_id="<run's dataset ID>", dataset_mapping_function=...). LlamaIndex: ApifyActor from llama-index-readers-apify. CrewAI: use the Apify MCP server above.
Limitations
This Actor never logs in and reads only what Toutiao shows any visitor, so:
- No full article body. Toutiao protects article pages with a browser check, so you get the title, summary, counts and link, not the full text. 微头条 posts and comments come in full.
- About 100 results per keyword and tab (fewer with a date range). Split long periods with Posted after / Posted before.
- Date ranges on posts are applied by the Actor. Toutiao's 微头条 search ignores dates and sorts by relevance, so the Actor keeps only the posts inside your range (the rest are skipped, not charged). Narrow ranges far in the past may return few posts.
- A few very broad brand names are captcha-gated for logged-out visitors (see Tips). They are skipped without charge; use a more specific keyword.
- No author timelines or follower lists. To follow an account, search its name or the topics it covers.
- If Toutiao starts answering with bot checks, the Actor slows down and stops early with what it has (shown in the status message), rather than hammering the site.
FAQ
Does Toutiao have a public API? No open API for search, comments or the hot board. This Actor reads the same public pages and JSON the Toutiao website loads for any visitor, and returns clean, English-named JSON.
Do I need a Toutiao account, cookies or a Chinese phone number? No. Nothing to log in to, nothing to configure.
Do I need a proxy or VPN? No. It works from Apify's servers as is.
How do I scrape Toutiao 微头条 posts? Add keywords and set Search in to Posts (微头条) or Both. Each post comes with its full text, images, hashtags, author and verification, reads, likes, comments and shares. Turn on comments to get the discussion under each post too.
How do I scrape Toutiao comments? Paste article, video or post links into Article, video or post URLs, or turn on Include comments for search results. Set how many comments per article and how many replies per comment. Each comment comes with its author, likes and the province Toutiao shows.
How do I get the Toutiao hot list (头条热榜)? Switch on Hot board. You get up to 50 ranked topics with heat score, label, image and link.
Is it legal? It collects only data Toutiao shows publicly to every visitor, with no login. Follow copyright and privacy laws (e.g. PIPL, GDPR) when you reuse it.
Feedback
Found a bug or missing a field? Open an issue in the Issues tab. If the Actor saved you time, a short review on this page helps other people find it.
Code examples and a quick reference are also on GitHub: smoldesk/toutiao-scraper.
More Actors from Smoldesk Studios
- Contact Details Scraper: emails, phone numbers, social profiles and contact forms from any list of websites, with email domains checked and junk removed, charged only when contacts are found
- Google Maps Scraper: places with phones, websites, ratings and hours from any search, plus emails and social profiles from each business website, lead filters and new-place monitoring
- WeChat Articles Scraper: WeChat Official Account (公众号) articles from keyword search, full text as Markdown, images, account IDs and publish dates, no login
- Weibo Scraper: Weibo search with date ranges, posts, comments, profiles and hot search (热搜), no login
- Bilibili Scraper: videos, stats, danmaku, comments and creators from China's video site, no login
- YouTube Scraper: videos, Shorts, channels and comments from search, channels and playlists — exact views, likes, publish dates and durations, no API key
- YouTube Comments Scraper: comments and replies from videos, channels, playlists or keyword searches, with likes, pinned/hearted flags and authors
- YouTube Channel Scraper: subscribers, exact total views, join date, country and social links of any channel, plus its latest videos
- Google Ads Transparency Scraper: every ad a competitor runs on Google Search, YouTube and Shopping — creatives, landing pages, countries, EU impressions and new-ad alerts
- Tennis Scraper: ATP, WTA, Challenger and ITF results and fixtures with odds from 15 bookmakers, H2H, players and rankings, back to the 2000s
- Google Hotels Scraper: hotel prices for your dates in any currency, ratings, review aspects and booking-site prices, worldwide
- Google Hotels Price Calendar: the cheapest nightly rate for every check-in date up to a year ahead, for any hotel, with taxes and booking-site prices
- Google Trends Scraper: interest over time, by region and city, related queries and Trending now — no API key
- Telegram Channel Scraper: public channel posts, views, reactions and subscribers
- Substack Scraper: newsletters, subscriber counts and posts
- Shopify Store Analyzer: apps, contacts and products of any Shopify store
- Career Site Jobs Scraper: live jobs from 12,000+ company career sites (Greenhouse, Lever, Workday, Ashby) with salary and seniority
- SEEK, JobStreet & JobsDB Scraper: jobs and salaries across Australia and Southeast Asia


