
Instagram Mentions Scraper
Pricing
from $1.40 / 1,000 results
Instagram Mentions Scraper
Instagram Mentions Scraper — Extract Instagram mentions, usernames, profile URLs, post captions, hashtags, timestamps, media links, and engagement metrics. Useful for brand monitoring, influencer research, audience insights, competitor analysis, and social media tracking.
Pricing
from $1.40 / 1,000 results
Rating
0.0
(0)
Developer

Social Data API
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
21 hours ago
Last modified
Categories
Share
Instagram Mentions Scraper — Author, Caption and Engagement Data
Instagram Mentions Scraper returns public Instagram posts where a different account tagged or @-mentioned a chosen handle — not that handle's own posts, but who is talking about it. Each row carries the mentioning author, caption, hashtags, likes count, comments count, and media details. Every response is structured JSON — ready to pass directly to an LLM, index into a vector store, or feed a social-listening pipeline. No Instagram account is needed by default; an optional cookie helps on rate-limited handles. Start with one handle, then add more.
What data can I extract with Instagram Mentions Scraper?
Using this Instagram mentions API, you will be able to extract the following Instagram mention data:
| 👤 Author username | 📝 Caption | #️⃣ Hashtags | @️⃣ @Mentions |
|---|---|---|---|
| 💬 Comments count | ❤️ Likes count | ▶️ Video play count | 🖼️ Display image URL |
| 📐 Media dimensions | 🎞️ Carousel images (when present) | 🧩 Child posts (carousel items) | 📍 Location name (if tagged) |
| 🏷️ Tagged users (list) | 🔗 Post URL | 🆔 Post ID and short code | 🎬 Media type (Image, Video, Carousel) |
| 📦 Product type | ✅ Author verified status | 🕒 Posted at (or empty when Instagram's feed omits it) | ⏱️ Scraped at |
How to use Instagram Mentions Scraper
Social-listening and brand-monitoring teams use it to answer who mentioned me on Instagram and to track inbound Instagram mentions of a handle, one run at a time.
Copy to your AI assistant:
Instagram Mentions Scraper MCP Server: use this Actor from ChatGPT, Claude or Cursor
Add Apify's MCP server with this actor preloaded as a tool, and your AI assistant can call it on its own — no glue code, no scraping logic in your prompts.
Step by step
- Create a free Apify account.
- Open the actor in the Apify Store.
- Enter the Instagram handle(s) (or profile URLs) you want to track inbound mentions of.
- Click Start (or send your API request).
- Download or stream your results in JSON, CSV or Excel.
How to scale Instagram Mentions Scraper to bulk
username takes an array, so one run can process many handles at once — each handle's mentions land in the same dataset, distinguished by targetUsername. There's no separate bulk-upload input: add every handle you want to the same list and set resultsLimit for how many mentions you need per handle.
✨ Features
Instagram Mentions Scraper fetches clean, structured inbound-mention posts from Instagram, working as an instagram social listening scraper and an instagram brand mention monitoring tool. It's ideal for influencer-tag audits, reputation tracking, and sourcing user-generated content.
It extracts, per mention post:
- Author username – the account that tagged or mentioned the target, never the target itself
- Caption – the full text of the mentioning post
- Hashtags and @mentions – parsed straight from the caption
- Likes and comments count – engagement as shown by the feed
- Media URLs and dimensions – main image/video plus carousel images when present
- Tagged users – everyone tagged in the post, not just the target
⚡ Every row is structurally filtered so the author is always a different account than the target — never the handle's own feed relabeled as "mentions."
Use cases 💡
- Brand monitoring analyst — scan author and caption to see who's talking about a brand.
- Reputation manager — build instagram mention analytics from comments and likes count.
- Influencer marketing manager — use it as an instagram mention tracker to spot organic tags.
- UGC sourcing team — export instagram mentions to csv for creator outreach and approvals.
- AI agent builder — feed captions into a RAG pipeline or your own instagram @mention alerts.
Building an AI agent? Connect it over MCP and let it call the actor on its own.
Why choose this actor?
- Two handles, one run, done in under 20 seconds. A recorded run returned 24 inbound-mention posts from 2 handles (
nasa,gopro) in 19.1 seconds, with the first row stored after 2.3 seconds. - Every mention carries 26 data points. A recorded row came back with author username, caption, comment count, like count, image dimensions, and product type, all in one JSON object.
- Genuinely inbound, never the handle's own feed. Every row is structurally guaranteed to be authored by a different account than the target, so results are never the handle's own tagged or reshared posts relabeled as mentions.
⬇️ Input
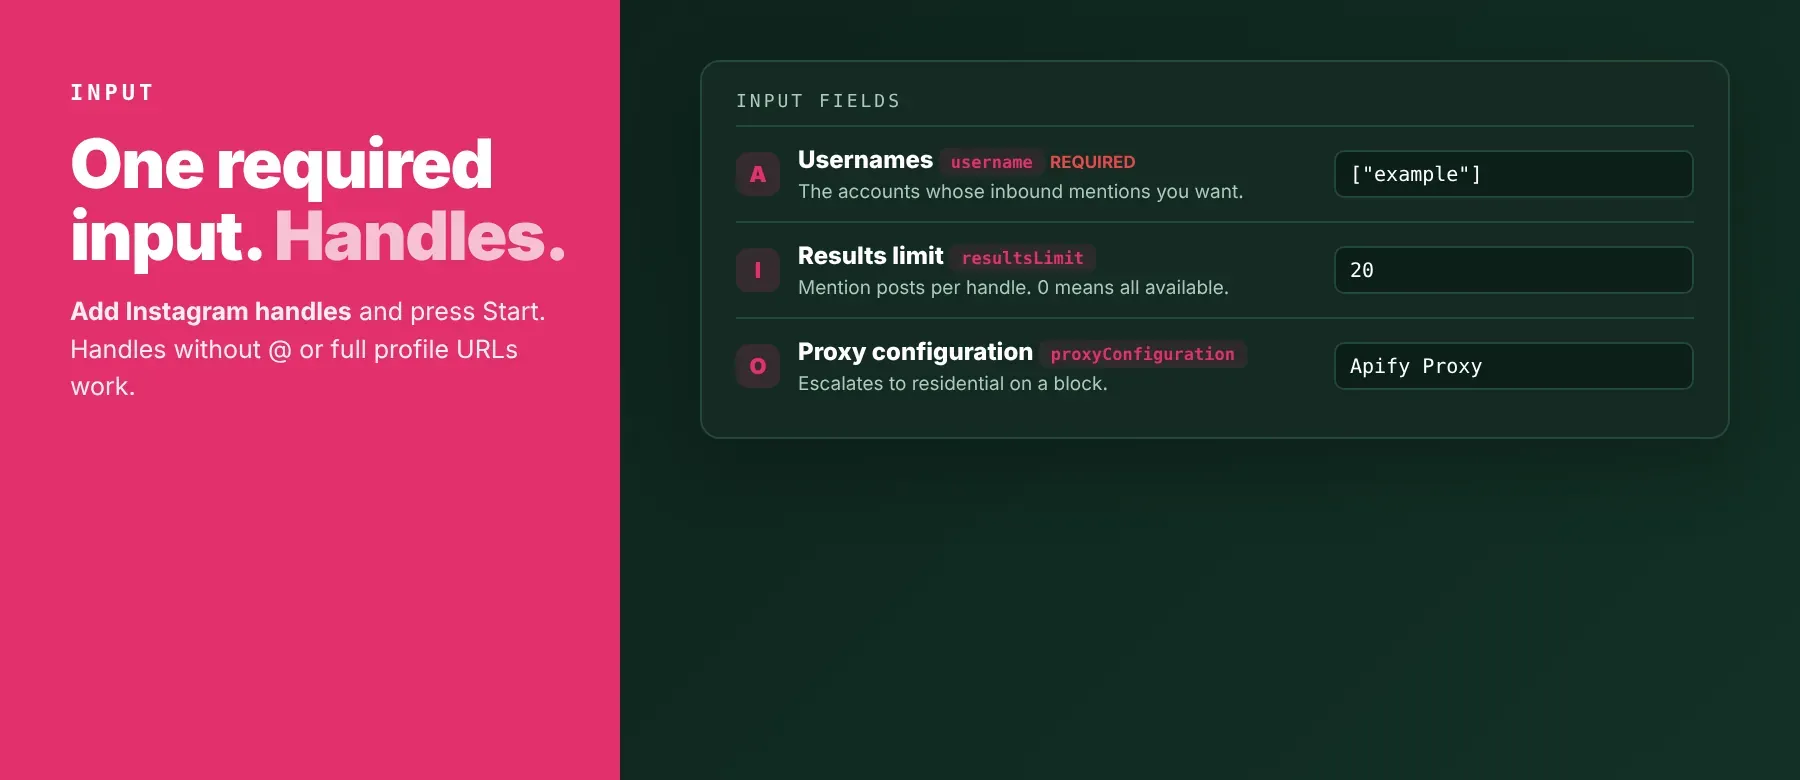
Instagram Mentions Scraper accepts one or more Instagram handles or profile URLs (username, required) plus a few optional settings.
| Parameter | Required | Type | Description | Example Value |
|---|---|---|---|---|
username | Yes | array | One handle per line — the accounts whose inbound mentions you want. Handles only (no @) or full profile URLs. | ["nasa", "gopro"] |
resultsLimit | No | integer | How many inbound mention posts to collect per handle. 0 (or 10000+) means all available. Values 1–11 are bumped to 12. Default 20. | 12 |
sessionId | No | string (secret) | Optional Instagram sessionid cookie. The actor works logged out by default; a cookie can help on rate-limited handles/IPs. Never written to the dataset. | (left empty) |
proxyConfiguration | No | object | Apify Proxy configuration. On a block, the actor escalates to a residential proxy automatically. | { "useApifyProxy": true, "apifyProxyGroups": ["RESIDENTIAL"] } |
Free plan limits
Users on the Apify free plan can fetch up to 20 inbound mention posts per run (all handles together) and 200 inbound mention posts per month. When the limit is reached, the run finishes successfully with a status message explaining the limit. Upgrade to any paid Apify plan to remove these limits.
Example input
⬆️ Output
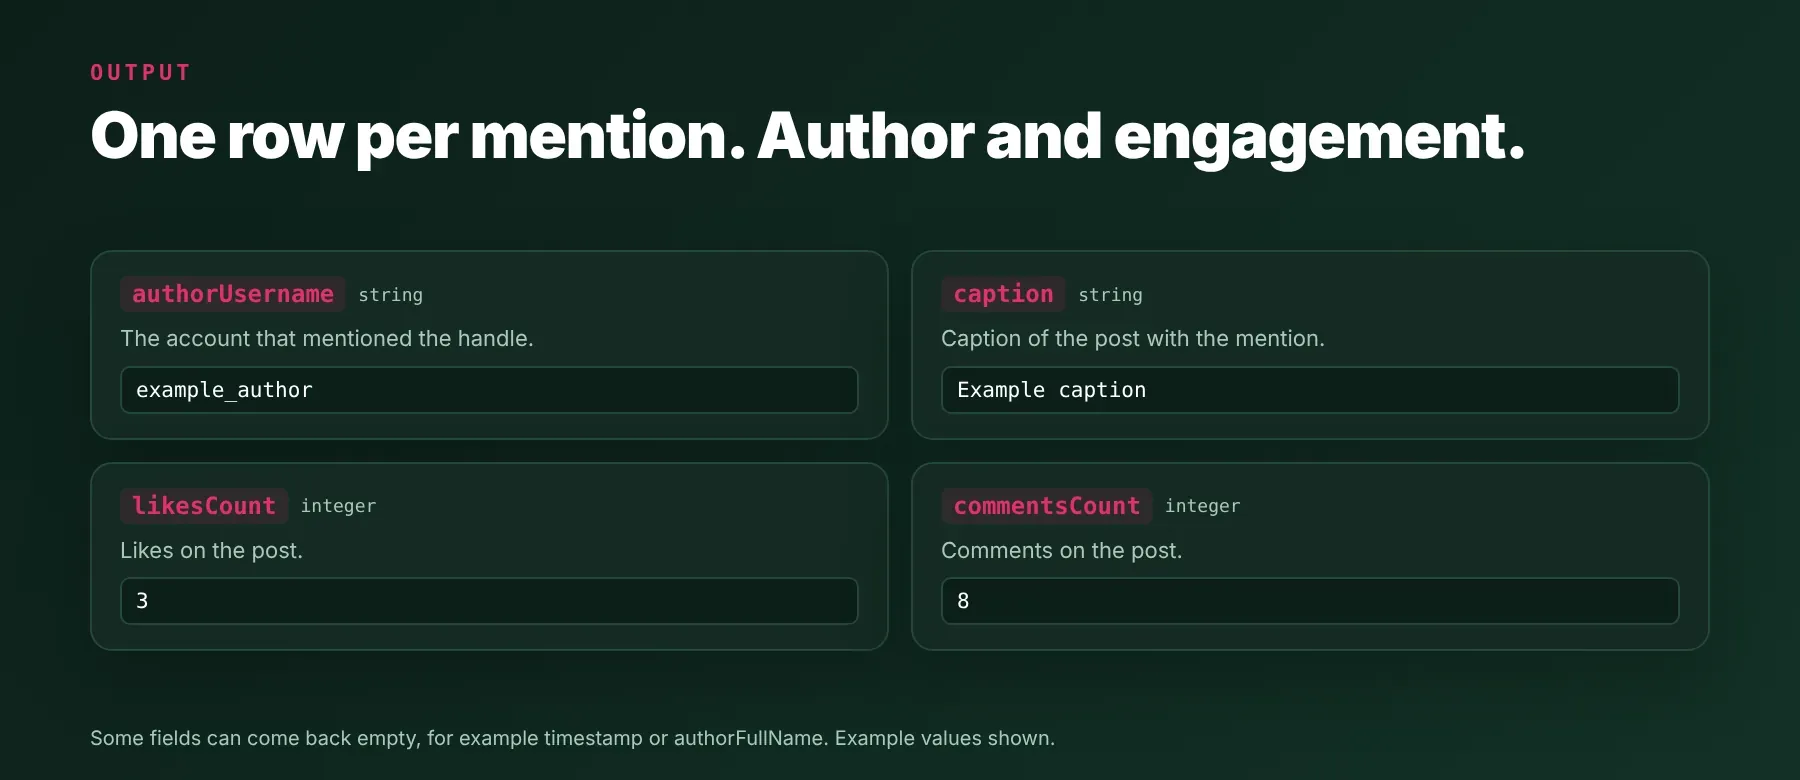
Every inbound mention is one typed, normalized JSON item with the same schema on every run, exportable as JSON, CSV, Excel, or via the Apify API/dataset endpoint. The actor doesn't push any summary or error rows — what lands in the dataset is exactly what's billed.
Example output
timestamp comes back as null on posts where Instagram's feed omits the post time, rather than a fabricated date.
How does it work?
Instagram Mentions Scraper reads the same public tagged-posts information any visitor can see on Instagram, without needing an Instagram account. For each handle, it first looks up the handle's public numeric ID, then reads through the posts other accounts have tagged it in, page by page, until it reaches the requested count or runs out of pages. Requests can be routed through Apify's proxy network, and the actor automatically switches to a residential proxy if a connection gets blocked, retrying with a fresh IP. Only publicly visible data is returned — nothing behind a login wall. The output schema (author, caption, hashtags, engagement, media) stays the same even as Instagram changes its layout, so your integration keeps working without changes on your end.
How do you integrate Instagram Mentions Scraper into your stack?
It works with what you already use: a REST API from any language, Apify's MCP server for AI agents, and no-code automation tools.
MCP integration for AI agents
Add Apify's MCP server with the command below. This registers the actor as a tool your agent can call directly from Claude Code, Cursor, or Windsurf.
No-code tools (n8n, Make, LangChain)
In n8n, use the Apify node ("Run an Actor"), or the HTTP Request node pointed at this Actor's run-sync endpoint with your Apify API token. In Make, add the Apify app's "Run an Actor" module, then "Get Dataset Items" to pull the results into your scenario. In LangChain, use langchain-apify and wrap the Actor as an ApifyActorsTool with its Actor ID socialdataapi/instagram-mentions-scraper, so an agent can call it directly and pass the returned items into a chain or vector store.
Is it legal to scrape Instagram mentions?
Scraping publicly visible Instagram data is generally lawful. It only collects posts, captions, and author details that Instagram displays to any visitor without a login. Scraping public data is generally permissible under GDPR and similar laws, but storing and using it — including the author usernames, full names, and IDs that appear in mention rows — must still comply with local data-protection law. Consult legal counsel if your use case involves bulk storage of personal data.
Frequently asked questions
What fields does Instagram Mentions Scraper return?
It returns author username, caption, hashtags, likes count, and comments count, among other fields — see the data fields section above for the full list.
Does Instagram Mentions Scraper require an Instagram account or login?
No. It runs against Instagram's public tagged-posts feed without an account. An optional session cookie can be added only to help on rate-limited handles — it's never required to start a run.
How fast does Instagram Mentions Scraper run?
Live data, not cached. A recorded run returned 24 inbound mentions from 2 handles in 19.1 seconds, with the first row written to the dataset after about 2.3 seconds.
What happens if a handle's user ID can't be resolved?
The actor retries resolution up to 5 times with proxy rotation. If it still can't resolve the handle, it logs that handle as failed and moves on to the next one in the list — returning 0 rows for that handle rather than stopping the whole run.
Can I scrape multiple Instagram handles at once?
Yes. Add multiple handles to the username array — each is processed in turn and its mentions are written to the same dataset, distinguished by targetUsername.
Does Instagram Mentions Scraper work with Claude, ChatGPT, and other AI agent tools?
Yes — Instagram Mentions Scraper is available as an MCP tool. Run claude mcp add --transport http apify "https://mcp.apify.com?tools=socialdataapi/instagram-mentions-scraper" to register it in Claude Code, Cursor, or Windsurf. Any agent that can call an HTTP endpoint can also use the REST API directly.
Does Instagram Mentions Scraper return data in a format LLMs can use directly?
Yes. Output is typed, normalized JSON with consistent field names across runs — no HTML parsing, no selectors. Pass it straight to an LLM, index it into a vector store, or feed it to an agent tool.
What happens when Instagram changes its layout or updates its anti-bot system?
The actor is maintained to keep returning the same JSON schema. When Instagram changes, the actor is updated — your calls keep returning the same fields with no changes on your end.
Can I use Instagram Mentions Scraper without managing proxies or browser infrastructure?
Yes. Proxy rotation runs on the actor's side — it automatically switches to a residential proxy on a block. You send one request and get structured JSON back; no proxy accounts or browser setup needed on yours.
Which Instagram mention fields work best for AI training data and RAG indexing?
For RAG: the caption and author username are the richest text fields. For training data: likes count, comments count, and video play count are the most consistently structured numeric fields. All fields are typed primitives — strings, integers, booleans, arrays — no normalization needed.
Your feedback
Found a bug or a missing field? Open an issue from this Actor's Issues tab in Apify Console. Every report is read and used to keep the output schema accurate as Instagram changes.


