
Instagram Likes Scraper
Under maintenancePricing
from $1.16 / 1,000 results
Instagram Likes Scraper
Under maintenanceInstagram Likes Scraper — Extract Instagram post like data including usernames, profile URLs, post URLs, timestamps, and engagement details. Useful for audience research, influencer analysis, competitor monitoring, lead generation, and social media insights.
Pricing
from $1.16 / 1,000 results
Rating
0.0
(0)
Developer

Social Data API
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
20 hours ago
Last modified
Categories
Share
Instagram Likes Scraper — Likers, Commenters and Profile Details
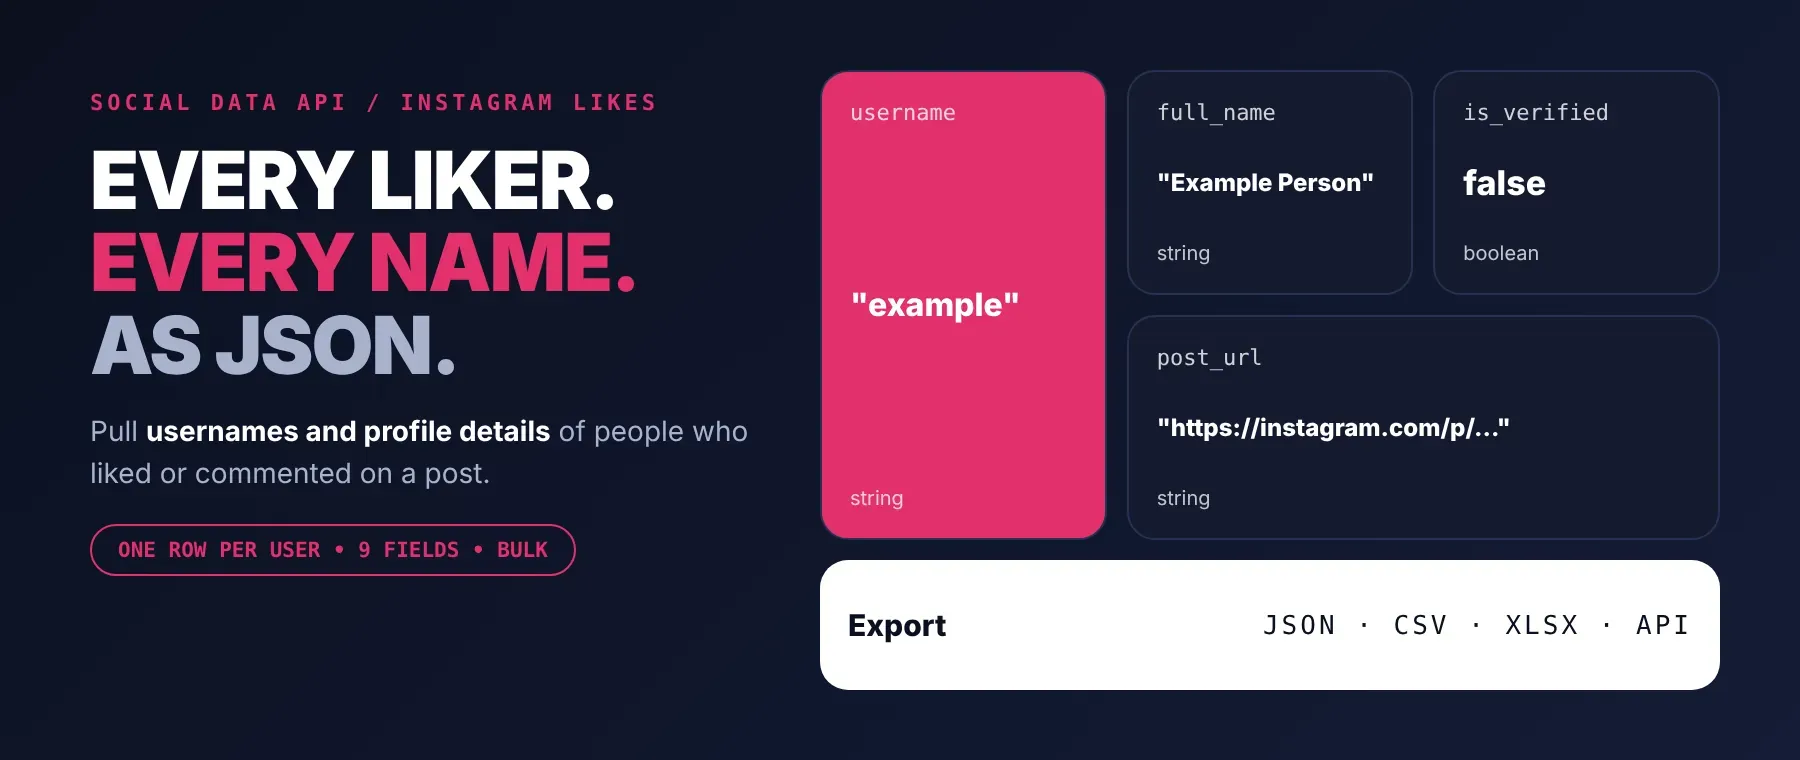
Instagram Likes Scraper collects the people who liked an Instagram post, plus the people who commented on it, and returns each user's username, full name, profile picture, user ID, verified and private flags and the post's like count. Every response is structured JSON — ready to pass directly to an LLM, index into a vector store, or feed an influencer marketing pipeline. It needs only the session ID of your own Instagram account, no browser. Start with one post, then map the engaged audience of every campaign.
What data can I extract with Instagram Likes Scraper?
Using this Instagram Likes API, you will be able to extract the following Instagram user data:
| 👤 Username | 🪪 Full name | 🆔 User ID | 🖼️ Profile picture link |
|---|---|---|---|
| ✅ Verified badge | 🔒 Private account flag | ❤️ Post like count | 🔗 Post the user was found on |
| 📸 Profile picture ID (if available) | 🎬 Latest story time (if available) |
How to use Instagram Likes Scraper
Marketers and analysts who want to scrape Instagram likes get one clean row per engaged user from a single run, to see who liked an Instagram post.
Copy to your AI assistant:
Instagram Likes Scraper MCP Server: use these Actors from ChatGPT, Claude or Cursor
Point your AI assistant at Apify's MCP server with this Actor already added as a tool, and it can run it on its own. No glue code, no scraping logic in your prompts.
Step by step
- Create a free Apify account.
- Open Instagram Likes Scraper in the Apify Store.
- Paste the Instagram post URL (one per line for several posts) and your Instagram session ID.
- Click Start (or send your API request).
- Download or stream your results in JSON, CSV or Excel, for example to move Instagram likers to CSV.
How to get your Instagram session ID
- Log in to instagram.com in Chrome, Edge or Firefox. A secondary account is a good choice.
- Open the developer tools (F12) and go to Application (Firefox: Storage) → Cookies →
https://www.instagram.com. - Find the cookie named
sessionidand copy its value. - Paste it into the Instagram session ID field. It is stored encrypted and never shown in the log.
- If the run stops with a message about the session ID, log in again and copy a fresh value.
How to scale Instagram Likes Scraper to bulk
Put every post you need into the post list: the actor reads them one after another in the same run, first the likers and then the commenters of each post, and saves every user as soon as it is read. Set the maximum number of users to cap the whole run. To build an Instagram post likers list for a full campaign, schedule the run in Apify or start it from your own code through the Apify API and loop over batches of posts. Only saved user rows are billed.
✨ Features
Instagram Likes Scraper fetches clean, structured users from Instagram posts and reels ⚡. It's ideal for influencer vetting, audience research, lead lists and feeding AI agents with real engagement data. As an Instagram likes extractor, it returns per user:
- Username – the Instagram handle
- Full name – the display name on the account
- User ID – Instagram's numeric ID, stable even when the handle changes
- Verified badge – whether the account is verified
- Private account flag – whether the account is private
- Profile picture – a link to the profile picture and its ID
- Post like count – the total likes of the post the user was found on
- Latest story time – when the user last posted a story, when Instagram provides it
⚡ A recorded run returned 1,000 users from one post in 21.0 seconds, with plain HTTP requests and no browser.
Use cases 💡
- Influencer marketer — check how many verified accounts liked a creator's sponsored post.
- Brand manager — export Instagram likers of a launch post to find real fans.
- Community manager — use it as an Instagram commenters scraper to thank active commenters.
- Growth marketer — run this Instagram likers scraper on rival posts to spot overlapping fans.
- AI engineer — feed liker usernames and flags into an agent that scores audience quality.
Building an AI agent? Connect Instagram Likes Scraper over MCP and let it call the actor on its own.
Why choose this actor?
- About 1,000 to 2,000 likers per post in one run. A recorded run returned 1,000 users from one post in 21.0 seconds: 948 likers plus 52 commenters. A second run returned 20 users in 1.8 seconds.
- Clear audience signals. In that recorded run, 89 of the 1,000 users had a verified badge and 338 had a private account, on a post with 42,263 likes.
- 13 fields, 3 link types, likers and commenters. Every row has the same 13 fields, and post, reel and tv links all work, so one Instagram engagement scraper covers the whole post.
⬇️ Input
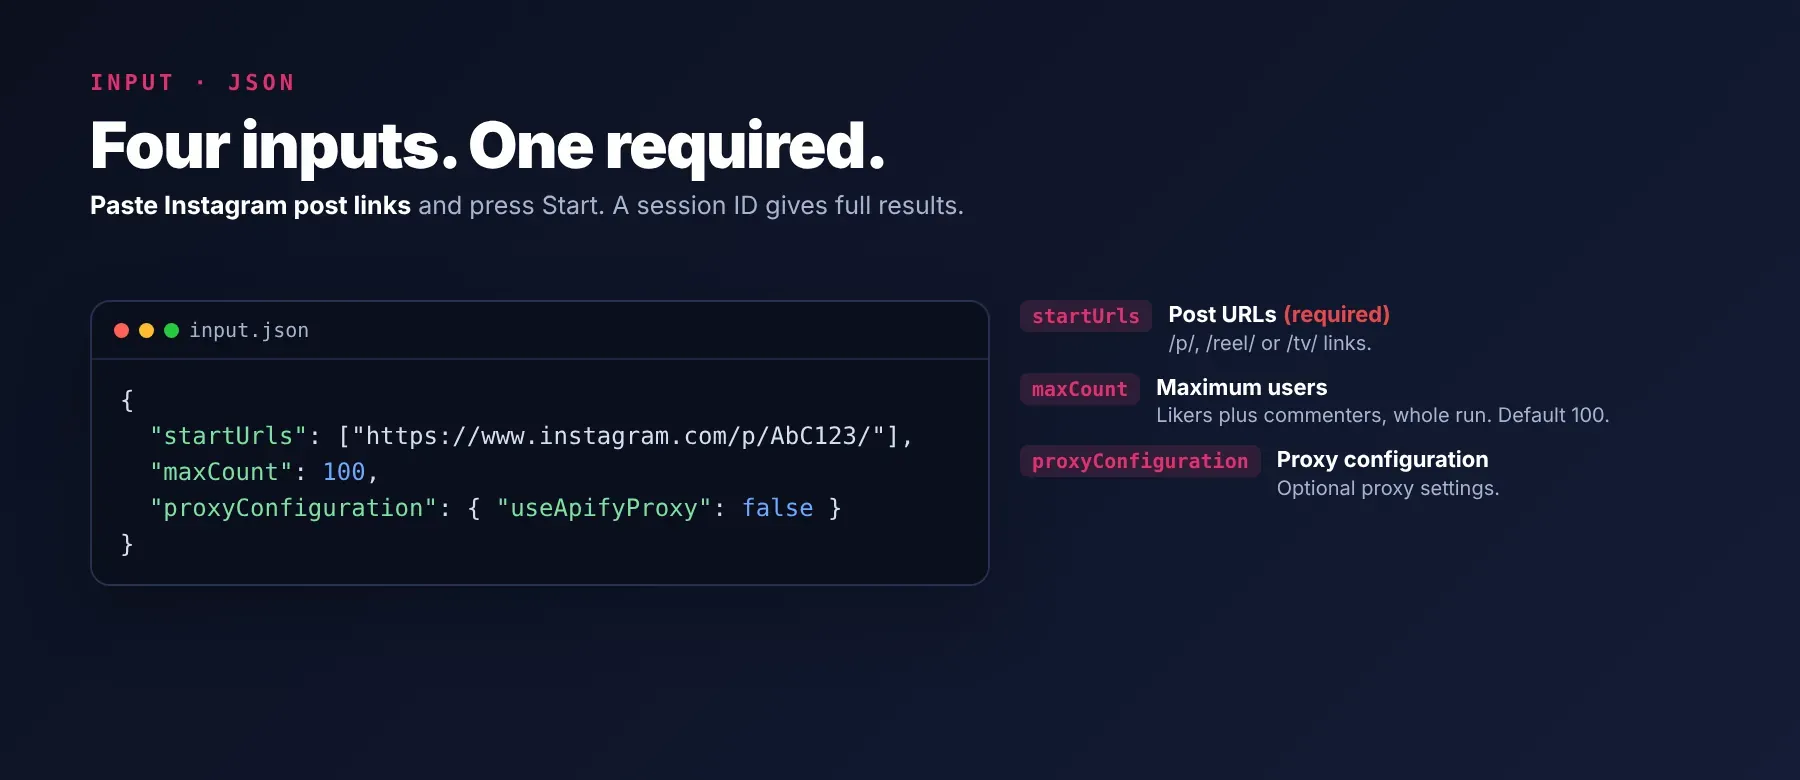
The actor accepts one Instagram post link or a list of them, plus the session ID of a logged-in Instagram account. The post list is the only field the form requires. Add your session ID for full results: without one, the run is a short demo (first post only, up to 20 users) when a default session is available, and otherwise it stops at once with a message.
| Parameter | Required | Type | Description | Example value |
|---|---|---|---|---|
startUrls | Yes | array | Instagram post links, one per line: /p/, /reel/ or /tv/ links. Read one after another. | ["https://www.instagram.com/p/DLm63qQpxvw/"] |
maxCount | No | integer | Maximum unique users (likers + commenters) for the whole run, across all posts. 1–10,000. Default 100. | 1000 |
sessionId | Recommended | string | The value of the sessionid cookie of a logged-in Instagram account. Secret input: stored encrypted, never logged. | (your own cookie value) |
proxyConfiguration | No | object | Apify Proxy settings. Default: no proxy; your proxy is used first when set, and the actor switches to a proxy on its own when Instagram blocks requests. | {"useApifyProxy": false} |
Accepted post link formats:
https://www.instagram.com/p/SHORTCODE/https://www.instagram.com/reel/SHORTCODE/https://www.instagram.com/tv/SHORTCODE/
Free plan limits
Users on the Apify free plan can fetch up to 20 users per run (all post URLs together) and 200 users per month. When the limit is reached, the run finishes successfully with a status message explaining the limit. Upgrade to any paid Apify plan to remove these limits.
Example input
The session ID below is a description of what to paste, not a real value.
⬆️ Output
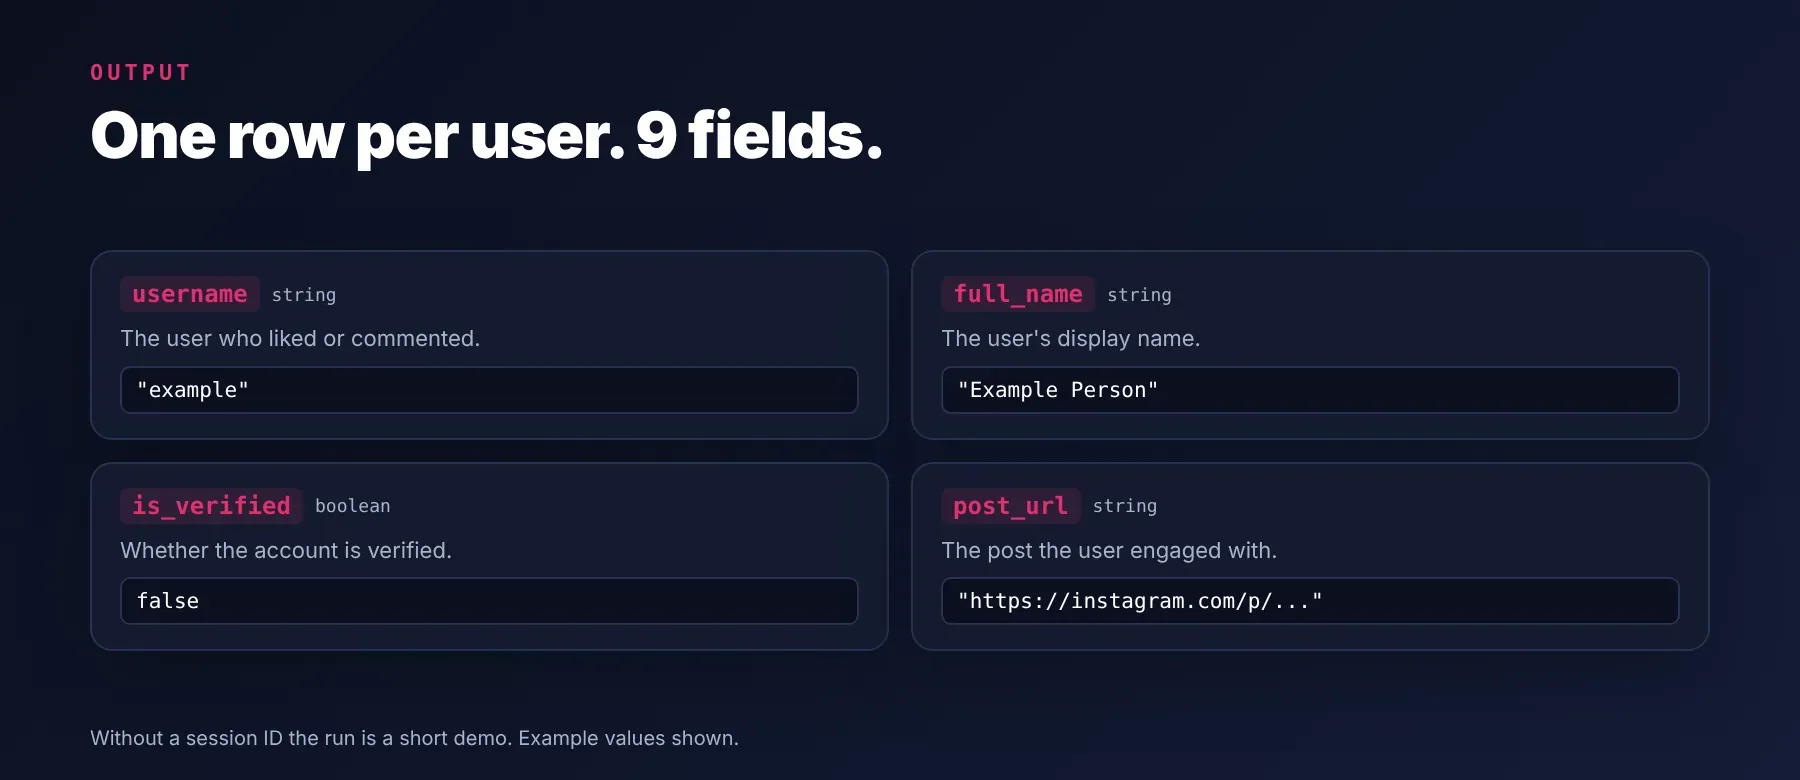
Every user is one typed, normalized JSON item with the same 13 fields on every run; there are no summary or error rows. Rows include the people who liked the post and, after them, the people who commented on it; both carry the post link they were found on, and a user is listed only once per run. Export as JSON (default), CSV or Excel.
Example output
Two fields are kept for compatibility and are currently always empty (null), because Instagram does not provide them: the "is new" flag and the UTC story time. The post link appears twice, as the liked post and as the post link.
How does it work?
The actor uses the session ID you provide to read the same data the Instagram website shows to you when you are logged in. It sends plain HTTP requests, with no browser, and reads your posts one after another: likers first, then commenters, until your user limit is reached. If you turn on a proxy, it is used first; if Instagram blocks requests, the actor retries and switches to a proxy on its own, and it keeps one IP address per proxy for the rest of the run instead of changing it on every request. When the session ID is expired or not accepted, the run stops at once with a message telling you to copy a fresh one, and it never switches proxies for that reason, which protects your account. When you leave the session ID empty, the run is a short demo (first post only, up to 20 users) if a default session is available, and otherwise it stops with a message. It returns only what a logged-in Instagram user can see on the post. Every row has the same 13 fields, and a value Instagram does not provide comes back as null instead of a made-up value.
How do you integrate Instagram Likes Scraper into your stack?
It works with what you already use: the REST API from any language, MCP for AI agents, and no-code tools.
MCP integration for AI agents
Register Apify's MCP server once with this Actor as a tool, and your agent can call it with a list of posts and your session ID, then read the user rows it returns.
This registers Apify's MCP server with Instagram Likes Scraper already loaded as a tool, so the agent can call it right away. Compatible clients include Claude Code, Cursor and Windsurf.
No-code tools (n8n, Make, LangChain)
- n8n — add the Apify node, choose "Run an Actor", pick this Actor (
socialdataapi/instagram-likes-scraper) and pass the post list and session ID as input. The next node receives the user rows from the run's dataset. - Make — use the Apify app's "Run an Actor" module with your post list, then the "Get Dataset Items" module to load the users into the rest of your scenario.
- LangChain — install
langchain-apifyand wrap the Actor withApifyActorsTool, passing this Actor's IDsocialdataapi/instagram-likes-scraper. Your agent can then request the likers of any post it is working on.
Is it legal to scrape Instagram data?
Collecting data that Instagram shows to logged-in users is lawful in many jurisdictions when it is done for legitimate purposes, but it also falls under Instagram's terms of use, which you accept with your account. This Actor returns only what a logged-in Instagram user can see on the posts you list; it cannot read anything your account has no access to. Likers and commenters are personal data (handles, names, profile pictures), so storing and using them must comply with data-protection laws such as the GDPR and CCPA. Consult legal counsel if your use case involves bulk storage of personal data.
Frequently asked questions
What fields does Instagram Likes Scraper return?
It returns the username, full name, user ID, verified badge and private account flag of every user, plus the profile picture and the post's like count. See the data fields section for all 13.
Does Instagram Likes Scraper require an Instagram account or login?
Yes — it needs the session ID (the sessionid cookie) of a logged-in Instagram account, because Instagram shows the list of likers only to logged-in users. The field is a secret input: Apify stores it encrypted, the actor never writes it to the log, and it is used only to read the posts you list. A secondary account is recommended, and if the session expires the run stops with a message instead of retrying. Without a session ID, a run is at most a short demo of up to 20 users from the first post.
How fast does Instagram Likes Scraper run?
A recorded run returned 1,000 users from one post in 21.0 seconds; another returned 20 users in 1.8 seconds. Every run reads live data from Instagram, nothing is cached.
What happens if a post is private or doesn't exist?
A link that is not an Instagram post, reel or tv link is skipped with a warning and adds no rows. A post that cannot be read is skipped with a warning and the run continues with the next post, so it adds no billed rows. In code, compare the post links in the results with your input list.
Can I scrape multiple Instagram posts at once?
Yes. Put as many post links as you like in the post list; the actor reads them one after another, and the maximum number of users applies to the whole run.
Does Instagram Likes Scraper work with Claude, ChatGPT, and other AI agent tools?
Yes — Instagram Likes Scraper can be used as an MCP tool through Apify's MCP server. Register it in Claude Code, Cursor or Windsurf with claude mcp add --transport http apify "https://mcp.apify.com?tools=socialdataapi/instagram-likes-scraper"; the server starts with this Actor as a tool, so the agent can run it right away. Any agent that can call an HTTP endpoint can also use the Apify REST API directly.
Does Instagram Likes Scraper return data in a format LLMs can use directly?
Yes. Every row is typed, normalized JSON with the same field names on every run. There is no HTML to parse and no selectors to maintain, so you can pass it straight to an LLM, index it into a vector store or hand it to an agent tool.
What happens when Instagram changes its layout or updates its anti-bot system?
The row format does not change: you keep getting the same 13 fields. If Instagram changes how a value is delivered, that field can come back empty or null until the actor is updated; the actor was last checked against Instagram on 2026-10-15, and you can report breakage in the Issues tab.
Can I use Instagram Likes Scraper without managing proxies or browser infrastructure?
Yes. No browser is involved, and the actor retries and switches to a proxy on its own when Instagram blocks requests. You send your post list and session ID and get structured JSON back, with no proxy accounts or headless browser setup to maintain.
Which Instagram user fields work best for AI training data and RAG indexing?
For RAG, use the username, full name and the post link, which tell who engaged and where. For training data, use the verified badge, private account flag, post like count and latest story time as consistent true/false and numeric signals. All fields are plain strings, integers, booleans or null, so no normalization is needed.
Your feedback
Found a bug or missing a field? Let us know in the Issues tab on this Actor's page in Apify Console. Reports help keep the user fields accurate as Instagram changes.


