
LinkedIn Job Search & Job Details Scraper - URL, ID or Keyword
Pricing
from $5.00 / 1,000 job postings
LinkedIn Job Search & Job Details Scraper - URL, ID or Keyword
Get LinkedIn job details from a job URL, a job ID or a keyword and location search: title, company, location, full description, seniority, employment type, salary, applicants, posted date. No login. New-jobs-only mode for schedules. $10 per 1,000 jobs; failed jobs are free.
Pricing
from $5.00 / 1,000 job postings
Rating
0.0
(0)
Developer

Tenfold Fleet
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
a day ago
Last modified
Categories
Features
Share
What does LinkedIn Job Details Scraper do?
LinkedIn Job Details Scraper returns the full public details of job postings on LinkedIn: the complete job description, company, location, seniority, employment type, salary when shown, applicant count and posting date. Give it job URLs, job IDs or a keyword and location search, in any mix, and it works like a simple LinkedIn job details API: one clean JSON row per job, no login and no cookies.
Not affiliated with LinkedIn. This Actor is an independent tool that reads only the job pages LinkedIn shows to visitors who are not signed in.
Why use it?
- One Actor for three starting points. Paste links you already have, pass IDs from your own database, or let a search find the jobs. You don't need a second tool to turn a search into full descriptions.
- New-jobs-only mode for schedules. Turn on
onlyNew, schedule the Actor daily, and each run delivers and charges only the postings you haven't received before. - Job market research. Collect descriptions for a role and location to study skills in demand, salaries and hiring volume.
- Recruiting and sales signals. See which companies are hiring for which roles, as an input for lead lists or talent mapping.
- AI agents and job alerts. Feed complete job text into an LLM for matching, summaries or alerts.
What data can it extract?
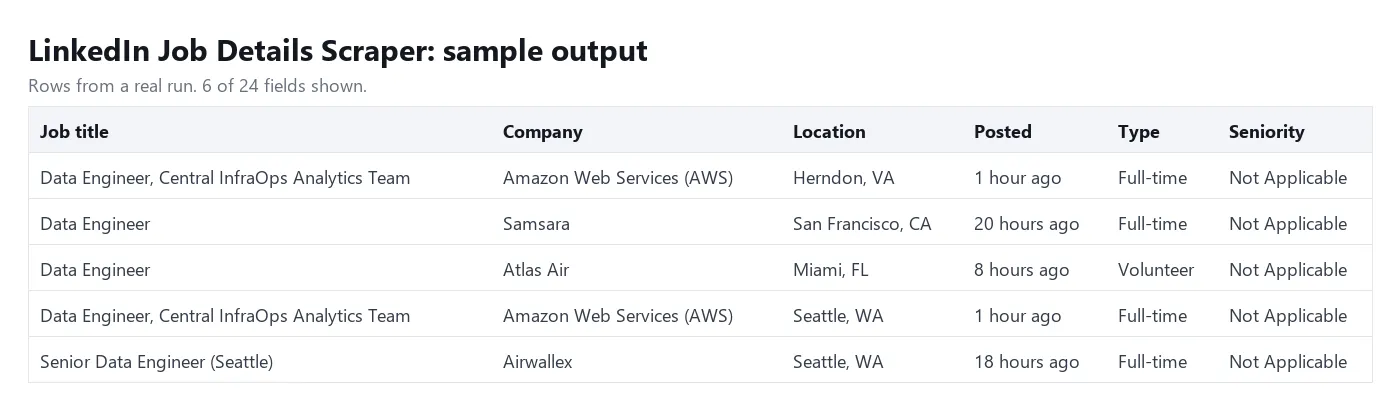
| Field | Description |
|---|---|
jobId, url | LinkedIn job ID and the public job link |
title | Job title |
companyName, companyUrl | Hiring company and its LinkedIn page |
location | Job location as shown |
descriptionText, descriptionHtml | Full job description as plain text and as HTML |
seniorityLevel, employmentType, jobFunction, industries | The job criteria block (jobFunction only when LinkedIn shows it) |
salaryText | Salary range, when the posting shows one |
applicantsText, applicantCount | Applicant line and the number in it (e.g. "Over 200 applicants" gives 200) |
postedTimeText, postedAt | Relative age ("9 hours ago") and the date derived from it |
applyUrl, isEasyApply | Where to apply and whether it is LinkedIn Easy Apply |
searchKeywords, searchLocation | The search that found the job, if any |
isNew | true for a first-time delivery in new-only mode |
scrapedAt, error | Time of scraping; error is null on success |
How to scrape LinkedIn job details
- Open the Actor and go to the Input tab.
- Add a search (keywords, location, how recent, how many jobs), or paste job URLs or job IDs.
- Optional: switch on Only new jobs and choose a monitor name if you plan to run it on a schedule.
- Click Start. Results appear in the Output tab as each job is fetched.
- Download the dataset as JSON, CSV or Excel, or read it through the Apify API.
How much does it cost to scrape LinkedIn job details?
$10 per 1,000 job postings ($0.01 per job returned with its full description), plus $0.00005 per run start. Proxy and compute are included.
You are never charged for failures: expired or removed jobs, IDs that don't exist, blocked fetches, invalid inputs, searches without results and, in new-only mode, jobs you already received are all free rows with an error note. On the Apify free plan, the $5 monthly credit covers roughly 500 jobs. Set a maximum cost per run and the Actor stops when it is reached.
Input
At least one of searches, jobUrls or jobIds is required. postedWithin accepts 24h, week or month; leave it out for any time. maxJobs defaults to 50 per search and can go up to 1,000, the most LinkedIn shows for one search. A job that appears twice in the input, or in two searches, is fetched and charged once.
Output
You can download the dataset as JSON, CSV, Excel, XML or HTML.
Tips
- For a daily job alert, use one search with
postedWithin: "24h", turn ononlyNewand schedule the Actor once a day. - Use a different
monitorNamefor each schedule, so their lists of delivered jobs stay separate. - In new-only mode, filter the dataset on
isNew = trueto keep only the fresh postings. postedAtis calculated from LinkedIn's relative text, so "2 weeks ago" is accurate to about a week. Recent jobs are accurate to the hour.applyUrlis the employer's link when LinkedIn exposes it on the public page, and the LinkedIn job page otherwise.- Narrow searches return better results than broad ones: add a city or a more specific title.
FAQ
Do I need a LinkedIn account or cookies?
No. The Actor reads only what LinkedIn shows to visitors who are not signed in, so there is no account to risk.
Why did a job come back with an error?
LinkedIn removes postings when they are filled or expire. Those rows say expired or not-found and cost nothing. A blocked row means LinkedIn refused the request six times in a row; run that job again later. If LinkedIn refuses 25 jobs in a row, the run stops early instead of burning time, and the jobs it did not try come back as free skipped rows.
What happens if a run is interrupted?
Progress is saved while the Actor works. If Apify moves the run to another server, or you resurrect a stopped run, it continues where it left off and does not fetch or charge the same job twice.
Which proxy does it use?
Apify datacenter proxy, with a new IP address for every request. It is included in the price. A residential group chosen in the proxy field is replaced by the datacenter pool; your own proxy URLs are used as given.
How many jobs can one search return?
Up to 1,000, which is LinkedIn's own limit for a single search. For more, split the search by location or by posting date.
Can I use it as a LinkedIn jobs API?
Yes. Start runs and read results through the Apify API, or call the Actor from an AI agent through the Apify MCP server.
Is scraping LinkedIn jobs legal?
The Actor collects only publicly visible job postings, which are business information published by employers. Job descriptions can occasionally name a recruiter or contact person; if you process personal data, make sure you have a lawful basis under GDPR or the rules that apply to you. Consult a lawyer if you are unsure.
More tools from Tenfold Fleet
All 122 tools: apify.com/tenfoldfleet. If this Actor saves you time, save it (the bookmark on its Store page) and leave a review: both help other people find it. Found a bug or need another field? Tell us on the Issues tab of this page.


