
Website Contact Extractor: Email & Phone Scraper, Socials $2/1k
Pricing
Pay per event
Website Contact Extractor: Email & Phone Scraper, Socials $2/1k
Bulk-extract emails, phone numbers and social profiles from business websites. Crawls home + contact, about, team, impressum and privacy pages; one clean row per site with role/named email tags, E.164 phones, 8 socials and address. $0.002 per site.
Pricing
Pay per event
Rating
0.0
(0)
Developer
Open Data Actors
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
an hour ago
Last modified
Share
Website Contact Extractor: Emails, Phones, Socials
- In short: Website Contact Extractor (Apify actor
transparent_meteorite/website-contact-extractor) crawls each website's home, contact, about, team, impressum and privacy pages and returns one clean row of contact details per site. - Who it is for: lead-generation agencies, sales teams enriching domain lists, marketers building outreach lists from their own site lists.
- Input: start URLs or domains, max pages per site, include named (personal) emails, same domain only, only with contacts, default country for phones.
- Output: emails tagged role or named, phones in E.164, LinkedIn, Facebook, Instagram, X, TikTok, YouTube and other socials, address, source page for each value.
- Price: $0.002 per site crawled plus $0.00005 per run start; sites that fail to load are not charged. Pay per result, no subscription; Apify's free plan credit covers a first test.
- Limits: finds only contacts published on the site; no guessing or verification of email addresses.
Key facts
- Actor name: Website Contact Extractor
- Actor ID:
transparent_meteorite/website-contact-extractor - Store page: https://apify.com/transparent_meteorite/website-contact-extractor
- Data source: the public website itself
- Pricing model: pay per event (
apify-actor-start$0.00005,site-crawled$0.002) - Output formats: JSON, CSV, Excel, XML, HTML table, RSS (Apify dataset)
- Access: Apify Console, REST API, JavaScript/Python clients, schedules, webhooks, Apify MCP server
- Login or third-party API key needed: no, only an Apify account
- Also known as: email extractor, contact details scraper, website email scraper, phone number extractor, social media links finder
- Maintainer: transparent_meteorite (independent developer)
- Last updated: 2026-10-07
Turn a list of business websites into a clean contact sheet: one row per site with every email (tagged role or named, with the page it was found on), phone numbers normalized to E.164, 8 social profiles, the contact page URL, company name and street address. $0.002 per site, all pages included.
What does it do
For each website you give it, the actor:
- Fetches the homepage (plain HTTP, no browser, robots.txt respected).
- Finds the pages where businesses actually publish contact details, by link text and URL in 10+ languages: contact, impressum/imprint, about, team, privacy, and crawls the best ones (default 5 pages per site, configurable 1-20).
- Extracts and merges everything into one row:
- Emails from
mailto:links, visible text, schema.org data, Cloudflare-protected addresses (cfemail decoded) and obfuscated forms likejane [at] acme [dot] com,info(at)acme.de,sales AT acme DOT com. - Each email is tagged
role(info@, sales@, support@, bookings@...) ornamed(jane.doe@...), withfoundOnpage URL, page type and how it was found. - Phones from
tel:links, schema.org and page text, validated and normalized to E.164 (+13135550142) with country. - Socials: LinkedIn, Facebook, Instagram, X/Twitter, YouTube, TikTok, Pinterest, GitHub (share buttons and post links filtered out).
- Company name (schema.org, og:site_name or cleaned page title), address (schema.org PostalAddress), contact page URL.
- Emails from
- Flags dead, blocked and parked sites with a clear
statusso you never pay for them.
Why use it
- Priced per site, not per page. Contact scrapers that charge per page cost 5x more for the same 5-page crawl. Here a site is $0.002 no matter how many of its pages are crawled.
- One row per site. No stitching per-page rows back together; CSV/Excel ready with flat
emailsList,phonesList,linkedin,facebook... columns. - Role vs named emails so you can route info@ to cold outreach and personal addresses to careful, compliant handling (or switch named emails off entirely).
- Source page for every email and phone so you can verify where it came from.
- E.164 phones ready for dialers, CRMs and SMS tools.
- Fair billing: unreachable, blocked (403/captcha), parked-domain and robots-disallowed sites are returned with a status and never charged.
- Fast and light: plain fetch + cheerio, 5 sites in about 12 seconds on 512 MB.
How to use
- Click Try for free and paste website URLs or bare domains into Websites (or upload a CSV/TXT file of URLs).
- Optionally set Max pages per site, turn Include named emails off for role-only output, or set Default phone country for local numbers.
- Click Start. Each site appears as a row as soon as it finishes.
- Download as CSV, Excel or JSON, or open the Emails view for one row per email with its type and source page.
Input example
Sample output
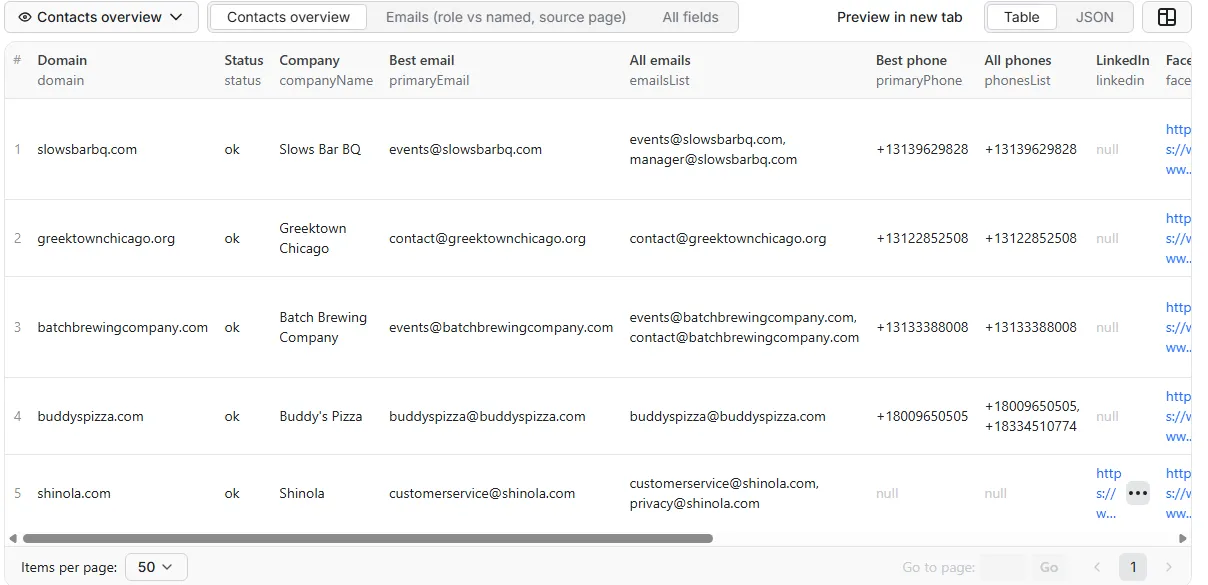
Real rows from a platform run (5 sites, 12 s, default input):
| Domain | Company | Emails | Phones | Socials | Contact page | Pages |
|---|---|---|---|---|---|---|
| shinola.com | Shinola | customerservice@shinola.com, privacy@shinola.com | linkedin, facebook, instagram, x, youtube, tiktok, pinterest | 4 | ||
| buddyspizza.com | Buddy's Pizza | buddyspizza@buddyspizza.com | +18009650505, +18334510774 | facebook, instagram, x | buddyspizza.com/contact/ | 4 |
| slowsbarbq.com | Slows Bar BQ | events@slowsbarbq.com, manager@slowsbarbq.com | +13139629828 | facebook, instagram | 1 | |
| batchbrewingcompany.com | Batch Brewing Company | events@batchbrewingcompany.com, contact@batchbrewingcompany.com | +13133388008 | facebook, instagram, tiktok | batchbrewingcompany.com/contact | 2 |
| greektownchicago.org | Greektown Chicago | contact@greektownchicago.org | +13122852508 | facebook, instagram, x | greektownchicago.org/contact/ | 4 |
One item (shortened):
status values: ok, blocked (403/429/bot challenge), http_error, unreachable (DNS/timeout), parked (domain for sale), robots_disallowed, not_html. Only ok sites with at least one crawled page are charged.
Pricing
Pay per event, no subscription:
| Event | Price |
|---|---|
| Actor start | $0.00005 per run |
| Site crawled | $0.002 per site (up to 20 pages included) |
Example: 1,000 websites = 1,000 x $0.002 + $0.00005 = about $2.00, whether you crawl 1 or 5 pages per site. If 120 of them are dead, parked or blocked you pay about $1.76. Set a max charge in the run options and the actor stops cleanly when it is reached.
Use from AI agents (MCP, ChatGPT, Claude, Perplexity)
Website Contact Extractor works as a tool for AI assistants through the official Apify MCP server. Add this server URL to any MCP client (Claude Desktop, Claude Code, Cursor, ChatGPT connectors, VS Code):
Claude Desktop / Cursor config:
Then ask in plain language, for example: "How do I get emails and phone numbers from a list of websites?"
Call it directly over HTTP (runs the actor and returns the dataset items in one request):
Python:
The same actor works in n8n, Make, Zapier, LangChain, LlamaIndex and CrewAI through their Apify integrations.
Questions people ask
How do I get emails and phone numbers from a list of websites? Paste the URLs into startUrls; you get one row per site with emails, phones and social profiles.
Does it guess or verify emails? No, it only returns emails published on the site, with the page it was found on.
Am I charged for sites that are down? No, only sites that were crawled are charged.
Integrations
API (cURL)
Python
JavaScript
No-code: Make, Zapier, n8n, Google Sheets and Airtable via Apify integrations; webhooks on run finish; schedules to re-check a lead list weekly. A common chain: Google Maps or directory scraper -> this actor -> CRM.
FAQ
Is it legal to extract contact details from websites? The actor only reads public pages that businesses publish themselves, without logins, captcha bypass or proxies, and it obeys robots.txt. Business contact data is generally public, but named personal emails can be personal data under GDPR, CCPA and similar laws. You are responsible for having a lawful basis for how you store and use the results (e.g. B2B legitimate interest, honoring opt-outs, CAN-SPAM). Turn Include named emails off if you only want role addresses.
Why did a site return no emails? Many sites only offer a contact form, or render contacts with JavaScript. The row still includes phones, socials and the contact page URL when found. Sites that load everything with JavaScript may need a browser-based scraper.
What does role vs named mean?
role = a function mailbox such as info@, sales@, support@, bookings@ or brand@brand.com. named = an address that looks like a person (jane.doe@, jsmith@).
Which pages are crawled?
The homepage, then links classified as contact, impressum/imprint, about, team and privacy (English, German, French, Spanish, Italian, Dutch, Portuguese), in that priority. If no contact link exists, /contact and /contact-us are tried.
Do I pay for failed sites? No. Invalid input, DNS failures, timeouts, 403/429/captcha pages, parked domains and robots.txt-disallowed sites are returned with a status and are not charged.
How are phones normalized?
With libphonenumber. International numbers are parsed as written; local numbers use the site's country-code domain (.de, .co.uk...) or the Default phone country input. Numbers that cannot be validated are dropped from text, and kept unnormalized when they come from an explicit tel: link.
Can it crawl a whole website? It is built for contact discovery, not full-site crawling: up to 20 targeted pages per site keeps it fast and cheap.
Does it use proxies? No. Requests go out directly with an honest user agent at polite speed (pages of one site are fetched one by one).
Limits
- JavaScript-only sites and sites behind Cloudflare/bot challenges return
blockedor few results. - Up to 50 emails and 15 phones per site are kept (most relevant first: same-domain, mailto/schema, role).
- Addresses are taken from schema.org markup only (no free-text address guessing).
Changelog
- 2026-10-07: added plain-language summary, key facts, AI-agent (MCP) section and question-style FAQ; refreshed Store SEO metadata.
- 0.1 (2026-10-07): first release. Emails with role/named tags and source page, cfemail and [at]/(dot) de-obfuscation, E.164 phones, 8 socials, schema.org address, impressum/team discovery, per-site pricing, no charge for failed sites.
Support
Found a site that should have worked, or need a field added? Open an issue on the actor's Issues tab with the URL and what you expected; we usually reply within a day.


