X (Twitter) Video Transcript Scraper: Timestamps, SRT avatar

X (Twitter) Video Transcript Scraper: Timestamps, SRT

Pricing

from $0.69 / 1,000 transcripts

Go to Apify Store
X (Twitter) Video Transcript Scraper: Timestamps, SRT

X (Twitter) Video Transcript Scraper: Timestamps, SRT

Transcribe X (Twitter) videos to text in bulk: post links, profiles, keyword searches or another run's dataset. Creator captions first, else speech-to-text with segment and word timestamps, SRT/VTT, plus views, likes and author data. No login needed.

Pricing

from $0.69 / 1,000 transcripts

Rating

0.0

(0)

Developer

Zen Studio

Zen Studio

Maintained by Community

Actor stats

0

Bookmarked

2

Total users

1

Monthly active users

a day ago

Last modified

Share

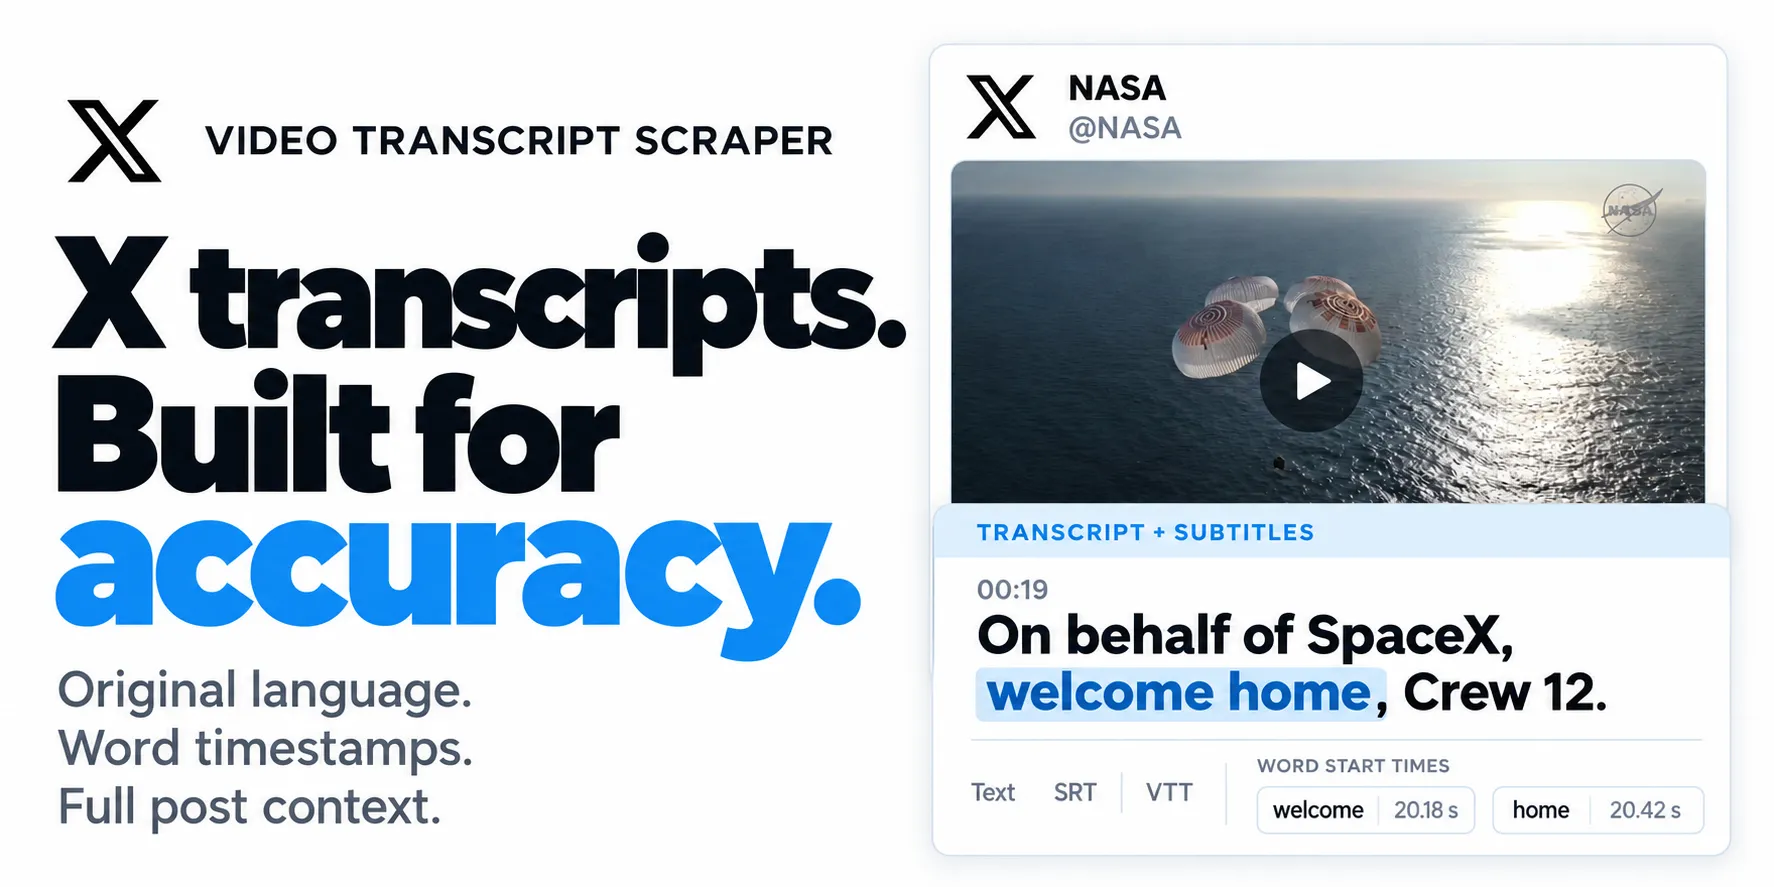
X transcripts. Built for accuracy.

From Zen Studio, creators of the TikTok and Douyin transcript scrapers. Also behind Douyin Search and RedNote Search, with 210,000+ combined lifetime runs.

Why choose this actor?

  • Creator captions first. Use the captions published by the creator when available, preserving their wording. Other videos are transcribed from speech.
  • Original language and word timings. Speech stays in its original language. Timed speech-to-text results include the start and end of each word, plus SRT and VTT subtitles.
  • Full post context. Keep post text, author details, views, likes, replies and reposts, plus video URLs, in the same record. Values are included where published.

Use post links, profiles, search terms or another run's dataset. Duplicate videos are processed once. Some fallback transcripts contain text without timestamps or subtitle files.
Transcribe X videos

Try one video

Open the actor input, switch to JSON and paste:

{
"postUrls": [
"https://x.com/NASA/status/2108221043743793212"
],
"mode": "auto",
"includeSubtitles": true,
"includeWordTimestamps": true
}

This example requests the NASA video shown above, with subtitles and word timestamps enabled. Transcript charges apply; speech-to-text also incurs an audio charge per started minute. Creator-caption results have no audio-minute charge. See current pricing.

Zen Studio Video Transcripts
  X Transcripts
You are here
  TikTok Transcripts
TikTok videos to text
  Douyin Transcripts
Douyin videos to text

Copy to your AI assistant

zen-studio/twitter-video-transcript-scraper on Apify turns X (Twitter) videos into original-language transcripts, one row per video, from postUrls (links or IDs), profiles (profileFeed=latest newest or highlights; maxVideosPerProfile default 20), searchQueries (maxVideosPerSearch default 20, searchSort Latest|Top) or datasetId (each item's own post: tweetId/id_str/postId, else its url/postUrl/tweetUrl/twitterUrl field; links inside post text are ignored). mode=auto uses creator captions else speech-to-text; nativeOnly never charges audio minutes but skips videos without captions; transcribe always uses speech. Segment timings, srt/vtt (includeSubtitles=true) and word timings (includeWordTimestamps=true, speech rows only) come by default; rows with hasTimestamps=false have text only. chunkWords>0 adds timed chunks. Videos over maxDurationSeconds (max 1800) are skipped; protected, age-restricted and login-only posts are unsupported; no translation. Charges: one Transcript per delivered transcript plus one Audio minute per started minute of speech-to-text; no_speech, no_video, skipped and error rows are free. Check status per row. Contract: https://api.apify.com/v2/actors/zen-studio~twitter-video-transcript-scraper/builds/default and https://apify.com/zen-studio/twitter-video-transcript-scraper; prices: https://apify.com/zen-studio/twitter-video-transcript-scraper/pricing. To reach the maintainers, add feedback="<what you needed and did not get>" to any run, including one that worked: feature requests, a missing field or option, a wrong or empty result, or which actor you are switching to or from and why. The run returns its data exactly as it would without the note, and a human reads every note.

How to transcribe X (Twitter) videos to text

  1. Add what you want transcribed: post links, profiles, search terms, a dataset ID, or any mix.
  2. Keep Transcript source on Automatic: creator captions are used when the video has them, the speech is transcribed otherwise.
  3. Start the run. Rows appear as videos finish; download them as JSON, CSV, Excel or HTML, or read them through the Apify API.
ParameterTypeDefaultMeaning
postUrlsarraynonePost links or numeric post IDs. x.com, twitter.com, mobile and /video/1 links work. Up to 1,000.
profilesarraynoneHandles (NASA, @NASA) or profile links. Public profiles only.
maxVideosPerProfileinteger20Video posts taken from each profile (1 to 500).
profileFeedstringlatestlatest: newest video posts. highlights: the profile's popular and highlighted posts.
searchQueriesarraynoneKeywords, hashtags or X search operators such as from:NASA. Up to 100.
maxVideosPerSearchinteger20Video posts taken from each search term (1 to 500).
searchSortstringLatestLatest or Top results first.
datasetIdstringnoneDataset from another run, for example a Twitter search or profile scraper. Each item's own post is used: a tweetId, id_str or postId field, else its post link field (url, postUrl, tweetUrl, twitterUrl). Links inside the post text or to quoted posts are not. Up to 5,000 items.
modestringautoauto: creator captions, else speech-to-text. nativeOnly: captions only, never charges audio minutes. transcribe: always speech-to-text.
languagestringautomaticTwo-letter code of the spoken language when you know it, for example en.
maxDurationSecondsinteger1800Longer videos are skipped without charge. Maximum 30 minutes.
includeSubtitlesbooleantrueAdds srt, vtt and timestampedText.
includeWordTimestampsbooleantrueAdds words with per-word times on speech-to-text rows.
chunkWordsinteger0Above 0, splits transcripts into timed chunks of about this many words for embeddings and search.

A larger example: the newest 50 videos from two profiles plus 20 videos about a topic, with chunks for a retrieval pipeline.

{
"profiles": ["NASA", "TEDTalks"],
"maxVideosPerProfile": 50,
"searchQueries": ["artemis"],
"maxVideosPerSearch": 20,
"chunkWords": 150
}

What data do you get from X (Twitter) videos?

One row per video. A post with three videos gives three rows (videoIndex, videoCount).

  • Transcript: transcript, language, transcriptSource, hasTimestamps, segments, words, timestampedText, srt, vtt, chunks, wordCount, confidence, audioType, and captionTracks (every creator caption track with its language, name and default, forced and shown-when-muted flags).
  • Post: postId, postUrl, text (long posts in full), lang, createdAt, conversationId, postClient, isReply, inReplyToPostId, inReplyToAuthor, possiblySensitive, links (resolved), hashtags, cashtags, mentions, postEntities (positions in the text), images (with alt text), card (link, broadcast or promotion card), edit history and state (editHistoryPostIds, isEdited, editableUntil), hasAiGeneratedMedia, isTranslatable.
  • Quoted and reposted posts: quotedPost and repostedPost with their text, author, stats and media. A post that only quotes a video gets that video's transcript, marked videoFromQuotedPost.
  • Engagement: stats with views, likes, reposts, replies, quotes and bookmarks.
  • Author: handle, name, profile link, verification type and reason, blue, legacy and identity verification, organization badge, avatar, banner, bio, location, website, followers (with their split), following, posts, media, likes and listed counts, account creation date, birthdate as the account shows it, affiliate and highlighted-post counts, professional category, pinned posts, bio language, subscriptions, tipping settings and profile flags.
  • Video: videoUrl (best MP4), videoQuality, all videoVariants, thumbnailUrl, thumbnailSizes, durationSeconds, width, height, aspectRatio, downloadAllowed, mediaTitle, mediaDescription, mediaAltText, mediaTags, monetizable, and mediaSourcePostId / mediaSourceAuthor when the video was shared from another post.
  • Run context: status, input, discoveredVia, chargedAudioMinutes, warnings, error, processedAt.

A real speech-to-text row. The words array is cut to its first 6 of 34 entries here; every other value is complete.

{
"status": "transcript",
"input": "https://x.com/NASA/status/2108221043743793212",
"discoveredVia": null,
"postId": "2108221043743793212",
"postUrl": "https://x.com/NASA/status/2108221043743793212",
"text": "They're back! Crew-12 splashed down off the coast of California at 11:34am ET (1534 CT), wrapping up their mission of scientific exploration and discovery. \n\nStay tuned for continuing live coverage as Crew-12 and their SpaceX Dragon spacecraft are retrieved from the Pacific. https://t.co/aSQqR3mLj5",
"lang": "en",
"createdAt": "2026-10-08T15:40:40Z",
"isReply": true,
"inReplyToPostId": "2108201013681303933",
"possiblySensitive": false,
"links": [],
"hashtags": [],
"cashtags": [],
"mentions": [],
"postEntities": {
"urls": [],
"hashtags": [],
"cashtags": [],
"mentions": []
},
"displayTextRange": [
0,
275
],
"longPostId": null,
"longPostExpandable": null,
"quotedPostId": null,
"quotedPostUrl": null,
"quotedPost": null,
"videoFromQuotedPost": false,
"repostedPostId": null,
"repostedPost": null,
"inReplyToAuthor": {
"id": "11348282",
"handle": "NASA"
},
"conversationId": null,
"postClient": null,
"postClientUrl": null,
"editHistoryPostIds": [
"2108221043743793212"
],
"isEdited": false,
"isStaleEdit": false,
"editOfPostId": null,
"editableUntil": null,
"editsRemaining": null,
"editEligible": null,
"hasAiGeneratedMedia": null,
"aiDisclosureEditable": null,
"isTranslatable": false,
"images": [],
"card": null,
"author": {
"id": "11348282",
"handle": "NASA",
"name": "NASA",
"url": "https://x.com/NASA",
"verified": true,
"verifiedType": "Government",
"blueVerified": true,
"avatarUrl": "https://pbs.twimg.com/profile_images/1321163587679784960/0ZxKlEKB_400x400.jpg",
"avatarShape": "square",
"description": "Making the seemingly impossible, possible. ✨",
"descriptionLinks": [],
"followersCount": 92310841,
"followingCount": 115,
"postsCount": 74449,
"protected": false,
"createdAt": "2007-12-19T20:20:32Z",
"bannerUrl": "https://pbs.twimg.com/profile_banners/11348282/1788992290",
"location": "Pale Blue Dot",
"website": "http://www.nasa.gov/",
"websiteLinks": [
{
"url": "https://t.co/9NkQJKAnuU",
"expandedUrl": "http://www.nasa.gov/",
"displayUrl": "nasa.gov",
"indices": [
0,
23
]
}
],
"mediaCount": 28205,
"likesCount": 17039,
"accountLabel": null,
"professional": null,
"pinnedPostIds": [],
"descriptionLanguage": null,
"translatorType": "regular",
"affiliationLabel": null,
"subscriptionsEligible": false,
"legacyVerified": false,
"identityVerified": false,
"birthdate": {
"day": 1,
"month": 10,
"year": 1958,
"visibility": "public",
"yearVisibility": "public"
},
"affiliatesCount": 85,
"highlightedPostsCount": 286,
"canHighlightPosts": true,
"creatorSubscriptionsCount": 0,
"fastFollowersCount": 0,
"normalFollowersCount": 92310841,
"profileFlags": {
"defaultProfile": false,
"defaultProfileImage": false,
"hasCustomTimelines": true,
"isTranslator": false,
"possiblySensitive": false,
"needsPhoneVerification": false,
"hasHiddenSubscriptions": false,
"profileTranslatable": false
},
"tipping": {
"enabled": false,
"bandcamp": null,
"bitcoin": null,
"cashApp": null,
"ethereum": null,
"goFundMe": null,
"patreon": null,
"payPal": null,
"venmo": null
},
"verificationReasonLinks": [
{
"url": "https://help.twitter.com/en/rules-and-policies/profile-labels",
"start": 91,
"end": 101
}
],
"timeZone": null,
"profileNotice": null,
"withheldScope": null,
"withheldDescription": null,
"verifiedReason": "This account is verified because it is a government or multilateral organization account.",
"verifiedSince": "2009-08-07T19:53:50Z",
"listedCount": 96859
},
"stats": {
"likeCount": 1028,
"replyCount": 41,
"repostCount": 174,
"quoteCount": 23,
"bookmarkCount": 32,
"viewCount": 144331
},
"videoIndex": 1,
"videoCount": 1,
"mediaId": "2108220806966792192",
"mediaType": "video",
"videoUrl": "https://video.twimg.com/amplify_video/2108220806966792192/vid/avc1/3840x2160/zpOIRkvfAMFxp679.mp4?tag=29",
"videoQuality": "3840x2160",
"videoVariants": [
{
"url": "https://video.twimg.com/amplify_video/2108220806966792192/vid/avc1/3840x2160/zpOIRkvfAMFxp679.mp4?tag=29",
"contentType": "video/mp4",
"bitrate": 25128000,
"quality": "3840x2160"
},
{
"url": "https://video.twimg.com/amplify_video/2108220806966792192/vid/avc1/1920x1080/kk7lZB3T0bEKx0uU.mp4?tag=29",
"contentType": "video/mp4",
"bitrate": 10368000,
"quality": "1920x1080"
},
{
"url": "https://video.twimg.com/amplify_video/2108220806966792192/vid/avc1/1280x720/2BPCJNRPtVk1cQGf.mp4?tag=29",
"contentType": "video/mp4",
"bitrate": 2176000,
"quality": "1280x720"
},
{
"url": "https://video.twimg.com/amplify_video/2108220806966792192/vid/avc1/640x360/51z3dWM9SerJSjC-.mp4?tag=29",
"contentType": "video/mp4",
"bitrate": 832000,
"quality": "640x360"
},
{
"url": "https://video.twimg.com/amplify_video/2108220806966792192/vid/avc1/480x270/fqgKLj222hitX_bO.mp4?tag=29",
"contentType": "video/mp4",
"bitrate": 256000,
"quality": "480x270"
}
],
"thumbnailUrl": "https://pbs.twimg.com/amplify_video_thumb/2108220806966792192/img/-SwTDu49BUef0cv1.jpg",
"durationSeconds": 21.995,
"width": 3840,
"height": 2160,
"downloadAllowed": true,
"aspectRatio": null,
"mediaKey": null,
"mediaAltText": null,
"mediaTitle": null,
"mediaDescription": null,
"monetizable": false,
"mediaAvailability": "available",
"mediaPostUrl": "https://x.com/NASA/status/2108221043743793212/video/1",
"mediaTextRange": [
276,
299
],
"mediaSourcePostId": null,
"mediaSourceAuthor": null,
"mediaTags": [],
"thumbnailSizes": null,
"dominantColors": [],
"transcriptSource": "speech_recognition",
"transcript": "And as you can see on your screen, we have visual confirmation of Splashdown. Jack and Freedom has returned home, and Jessica, Jack, Sophie, and Andre. On behalf of SpaceX, welcome home, Crew 12.",
"language": "en",
"confidence": 0.74,
"wordCount": 34,
"hasTimestamps": true,
"segments": [
{
"start": 0,
"end": 15,
"text": "And as you can see on your screen, we have visual confirmation of Splashdown.",
"avgLogprob": -0.3014,
"noSpeechProb": 0,
"compressionRatio": 1.315
},
{
"start": 15,
"end": 19,
"text": "Jack and Freedom has returned home, and Jessica, Jack, Sophie, and Andre.",
"avgLogprob": -0.3014,
"noSpeechProb": 0,
"compressionRatio": 1.315
},
{
"start": 19,
"end": 21.995,
"text": "On behalf of SpaceX, welcome home, Crew 12.",
"avgLogprob": -0.3014,
"noSpeechProb": 0,
"compressionRatio": 1.315
}
],
"words": [
{
"word": "And",
"start": 7.88,
"end": 7.9
},
{
"word": "as",
"start": 7.9,
"end": 8.16
},
{
"word": "you",
"start": 8.16,
"end": 8.3
},
{
"word": "can",
"start": 8.3,
"end": 8.44
},
{
"word": "see",
"start": 8.44,
"end": 8.6
},
{
"word": "on",
"start": 8.6,
"end": 8.84
}
],
"timestampedText": "[00:00] And as you can see on your screen, we have visual confirmation of Splashdown.\n[00:15] Jack and Freedom has returned home, and Jessica, Jack, Sophie, and Andre.\n[00:19] On behalf of SpaceX, welcome home, Crew 12.",
"srt": "1\n00:00:00,000 --> 00:00:15,000\nAnd as you can see on your screen, we have visual confirmation of Splashdown.\n\n2\n00:00:15,000 --> 00:00:19,000\nJack and Freedom has returned home, and Jessica, Jack, Sophie, and Andre.\n\n3\n00:00:19,000 --> 00:00:21,995\nOn behalf of SpaceX, welcome home, Crew 12.\n",
"vtt": "WEBVTT\n\n00:00:00.000 --> 00:00:15.000\nAnd as you can see on your screen, we have visual confirmation of Splashdown.\n\n00:00:15.000 --> 00:00:19.000\nJack and Freedom has returned home, and Jessica, Jack, Sophie, and Andre.\n\n00:00:19.000 --> 00:00:21.995\nOn behalf of SpaceX, welcome home, Crew 12.\n",
"chunks": [],
"captionLanguage": null,
"captionName": null,
"captionTracks": [],
"audioType": "speech",
"chargedAudioMinutes": 1,
"warnings": [],
"error": null,
"processedAt": "2026-10-21T17:20:00Z"
}

When the creator uploaded captions, the row uses them word for word and charges no audio minutes. Excerpt of a real caption row (selected keys, first two segments):

{
"status": "transcript",
"postUrl": "https://x.com/NASA/status/2104593672624886205",
"transcriptSource": "native_captions",
"language": "en",
"captionLanguage": "en",
"captionName": "Promo Vid Version 6 - Planetary Defenders - This Is Not an Exercise",
"captionTracks": [
{
"language": "en",
"name": "Promo Vid Version 6 - Planetary Defenders - This Is Not an Exercise",
"default": false,
"forced": false,
"autoSelect": true,
"showWhenMuted": true
}
],
"hasTimestamps": true,
"chargedAudioMinutes": 0,
"durationSeconds": 38.605,
"segments": [
{
"start": 0,
"end": 3.37,
"text": "This asteroid\n2024 YR4 might get interesting."
},
{
"start": 3.403,
"end": 6.406,
"text": "There was a chance that it could impact\nEarth."
}
]
}

A post without a video still gets a row, free of charge:

{
"status": "no_video",
"input": "https://twitter.com/jack/status/20",
"postId": "20",
"postUrl": "https://x.com/jack/status/20",
"error": {
"code": "no_video",
"message": "This post has no video with sound.",
"retryable": false
},
"chargedAudioMinutes": 0
}

Creator captions or speech-to-text?

Automatic mode checks each video for captions the creator uploaded. When present, you get their exact wording and timing and pay only the transcript event. Otherwise the speech is transcribed in its original language, with segment and word timings. Music-only and silent videos, and videos uploaded without sound (audioType: no_audio_track), return no_speech and are free. In rare cases timings are not available for a speech-to-text row; it then says hasTimestamps: false and carries a warning, and the text is still complete.

How does it compare?

Measured on 2026-10-21 by running the four most-used X transcript actors on the Apify Store with the same three videos and one profile.

This actorMost-used alternativeOther three tested
Inputs per runMany links, profiles, searches, a datasetOne linkLinks; profiles in one; a dataset in one
Keyword searchYesNoNo
Word-level timestampsYesNoNo
SRT and VTT subtitlesYesNoOne of three
Video inside a promoted post (the most-used alternative's own example)TranscribedFailed, still chargedTranscribed by one of three
Transcript and audio-minute charges per one-minute speech video, Free plan$0.00398$0.004$0.005 to $0.055
Posts without speech or videoFreeCharged in our testVaries

How much does it cost to transcribe X videos?

Pay per result, no subscription:

EventWhen chargedFree plan price
TranscriptEach delivered transcript$0.99 per 1,000
Audio minuteEach started minute of speech-to-text audio$2.99 per 1,000

Free and Bronze plans pay $0.99 and $0.89 per 1,000 transcripts, Silver $0.79, Gold and above $0.69; audio minutes cost $2.99 per 1,000 on Free, $2.69 Bronze, $2.49 Silver and $1.99 Gold and above. Creator-caption rows pay no audio minutes. no_speech, no_video, skipped and failed rows are free.

Example on the Free plan: 100 one-minute videos transcribed from speech cost 100 × $0.00099 + 100 × $0.00299 = $0.40. The same 100 videos with creator captions cost $0.10.

FAQ

Does it work for videos without captions? Yes. Without creator captions, the speech is transcribed. Use nativeOnly if you only want existing captions.

Can I transcribe every video from a profile? Yes, add the handle to profiles and set maxVideosPerProfile (up to 500). latest takes the newest video posts; highlights takes the popular and highlighted ones.

Can I chain it after another Twitter scraper? Yes. Put that run's dataset ID in datasetId; each item's own post ID or post link is used, and posts without video get a free no_video row.

Which languages? Speech is transcribed in the language spoken, detected per video; set language if you know it. Transcripts are not translated.

Which posts are not supported? Protected accounts, age-restricted and login-only posts, deleted posts, live broadcasts and videos longer than 30 minutes. They return an error, no_video or skipped row explaining why, free of charge.

Do I need an X account or cookies? No.

How fast is it? About 3 seconds per video on average across a 100-video run, with videos processed in parallel.

Can AI agents and automations use it? Yes, through the Apify API, MCP, Make, Zapier, n8n and the other Apify integrations. The block above under "Copy to your AI assistant" gives an agent the settings it needs.

Is it legal? It reads publicly visible posts. You are responsible for how you use the data, including copyright and privacy rules that apply to you.

Support

Found a problem or need a field? Open an issue on the Issues tab.