

WeChat Official Account Scraper 公众号 | Articles & Read Counts
Pricing
from $4.99 / 1,000 article results
WeChat Official Account Scraper 公众号 | Articles & Read Counts
Extract WeChat Official Account (公众号) data: search articles and accounts by keyword, pull read counts, likes, shares and comments, resolve the verified company behind an account, and track WeChat Index (微信指数) keyword trends. 15 operations, up to 52 fields per result, 50 entries per run.
Pricing
from $4.99 / 1,000 article results
Rating
5.0
(1)
Developer

Zen Studio
Maintained by CommunityActor stats
1
Bookmarked
1.3K
Total users
622
Monthly active users
3.3 hours
Issues response
2 days ago
Last modified
Categories
Share
WeChat Official Account (公众号 / Weixin MP) Scraper | Articles, Read Counts & WeChat Index (2026)
From Zen Studio, creators of Douyin Search and RedNote Search, with 100,000+ combined lifetime runs across those two Actors. This Actor has ranked #1 for “公众号” in Apify Store relevance results.
Why choose this actor?
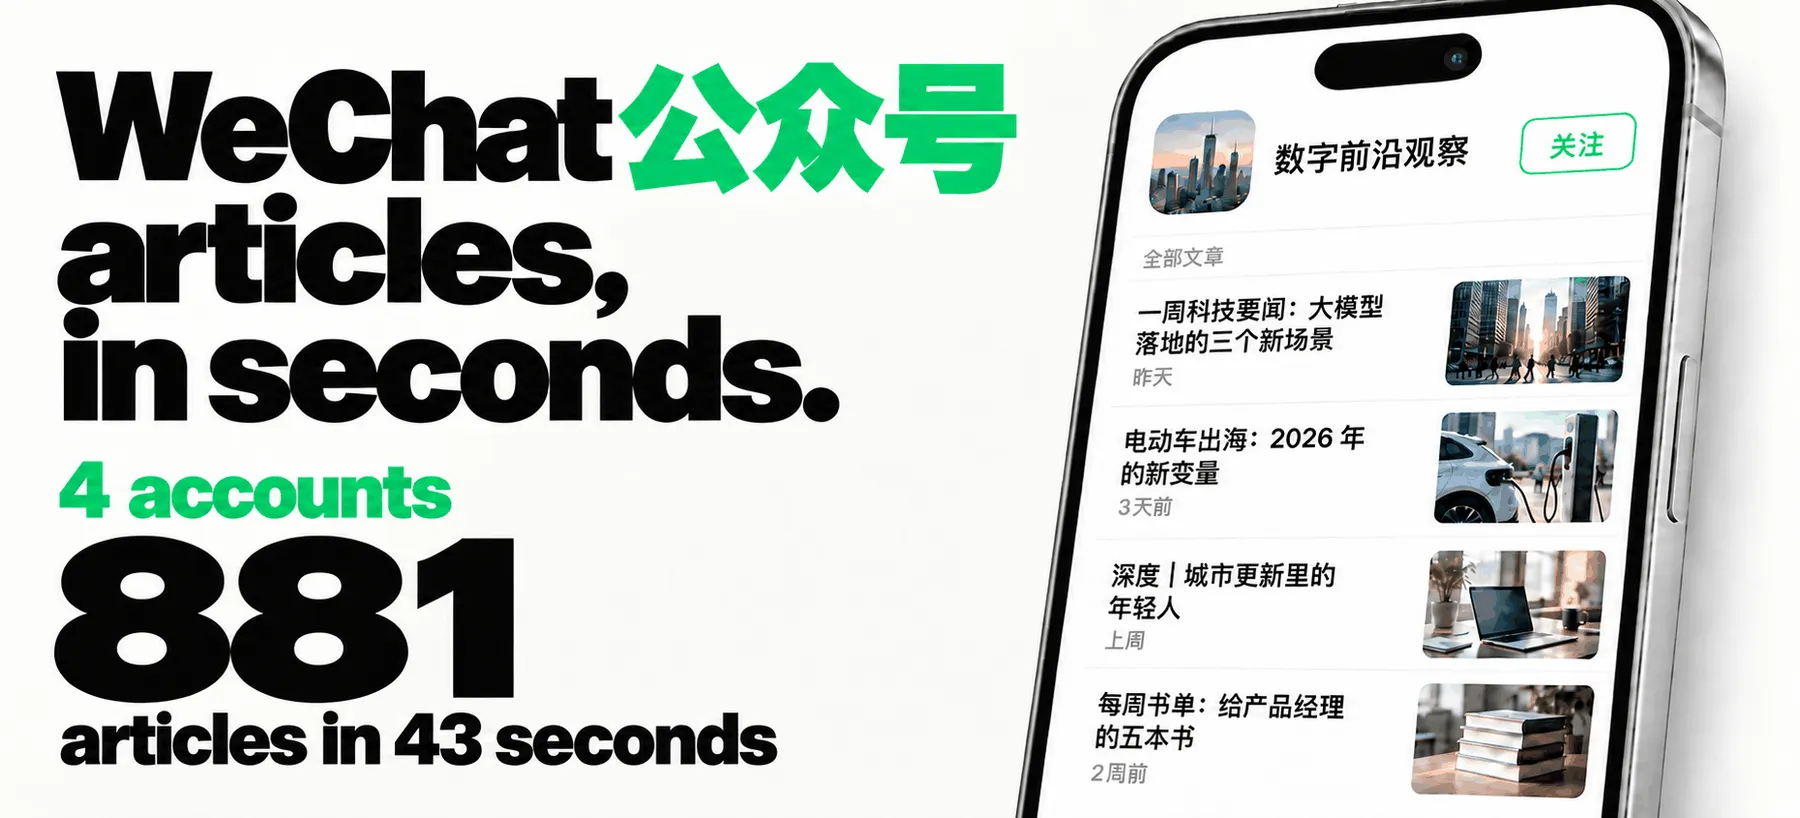
- Every article an account publishes, fast. A recorded run returned 881 articles from 4 accounts in 43 seconds, each with the full body text, the HTML and every in-article image. Deeper histories carry on across runs from where the last one stopped.
- The numbers behind each article. A recorded article came back with 28,509 reads, 978 shares, 34 favourites and 28 comments. Read counts live inside WeChat, not on the public article page, and they come from their own operation, one call per article.
- 15 operations, one Actor. Article and account search, article detail, metrics, comments and replies, account profiles, verified owners, today's articles, full history, mini programs, autocomplete and 微信指数 keyword trends.
Try one account
Open the Actor's input page, switch to JSON and paste this, then start the run.
An account can be named four ways and all of them work: the display name above, the short WeChat id, the gh_ id, or a link to any one of its articles. Add up to 50 accounts to a run. To put read counts on those articles, run articleMetrics over the article links afterwards, which is charged per article.
Apify Free plan: 25 lifetime preview runs, one page for the first entry. Mini program search, WeChat Index trends and autocomplete run on paid plans only. A paid plan removes every limit.
Continue your research
| Zen Studio Chinese Social • The platforms 1.4 billion people actually post on | |||
 WeChat Channels 视频号 Short video, creators, comments |
 WeChat Official Accounts 公众号 ➤ You are here |
 RedNote Search 小红书 Notes, images, video |
 Douyin Search 抖音 Videos and creators |
Copy to your AI assistant
Key Features
- 15 operations in one Actor: article search, account search, article detail, read counts, comments, replies, account profiles, owners, original counts, today's articles, article history, mini programs, autocomplete, and WeChat Index trends.
- Up to 52 fields per result: the complete record, not a hand-picked subset. Account profiles carry the linked WeChat Channels account; article metrics carry read counts, like counts, share counts and favourite counts inline.
- Long histories across several runs: an account's article history can run deeper than one run returns, so a single toggle lets the next run continue where the last one stopped.
- Batch input: pass up to 50 keywords, article links or accounts per run. Entries are processed in parallel and de-duplicated.
- Free tier: 25 lifetime runs, one page of results each, on every operation except mini program search, WeChat Index trends and autocomplete. No credit card required.
How to Scrape WeChat Official Account Articles
Pick one operation per run. Each one reads a different part of WeChat Official Accounts.
Basic: find articles by keyword
Chinese keywords return the richest results. English terms and brand names work too.
Several keywords at once
sortBy accepts relevance, latest or hot. publishTime narrows to day, week or halfYear.
Read counts and engagement for a specific article
An account's publishing history
Accounts accept a short id (rmrbwx), a gh_ id (gh_363b924965e9), the display name (人民日报), or any article link from that account. All four resolve automatically.
Input Parameters
| Parameter | Type | Default | Description |
|---|---|---|---|
operation | string | articleSearch | Which of the 15 capabilities to run |
keywords | array | Search terms. Used by article, account, mini program, suggestion and Index operations | |
articleUrls | array | Article links. Used by detail, metrics, comments and replies | |
accounts | array | Short id, gh_ id, display name or an article link | |
links | array | Short links to expand | |
maxPages | integer | 3 | Depth per entry. For comment replies, how many threads to expand |
sortBy | string | relevance | relevance, latest, hot |
publishTime | string | all | all, day, week, halfYear |
businessType | string | ALL | Autocomplete scope: accounts, articles, channels, mini programs and more |
continuePreviousRun | boolean | false | For account history and today's articles: carry on from where the last run stopped |
Collecting a long publishing history across several runs
An account's history can run far deeper than one run returns. Switch on Continue where the last run stopped and each run picks up where the previous one finished instead of starting again from the most recent articles:
Switch it on from the first run: only runs with it enabled record a position. If a saved position cannot be used, the run says so and starts that account from the beginning rather than continuing silently. Available to paying users, and applies to the account feeds rather than to searches.
What Data Can You Extract from WeChat Official Accounts?
Every row carries the operation that produced it and the queryTarget it came from, so batched runs stay traceable.
Articles: title, digest, cover image, publish time and timestamp, author, account name and gh_ id, full body text, album (合集) membership, IP region, hashtags and topics.
Engagement: read count, like count, "wow" count, share count, favourite count, comment count, star count.
Accounts: display name, avatar, signature, verified owner (the registered company), original-article count, service type, IP region, custom menus, and the linked WeChat Channels account.
Comments: content, author nickname and avatar, like count, IP region down to province, pinned and featured flags, and reply threads.
Trends: daily WeChat Index (微信指数) values per keyword, and autocomplete suggestion sets.
Stable fields for automations
Article detail rows carry a guaranteed set of top-level fields. These keep the same name and the same kind of value in every release, so an n8n, Make, Zapier or RAG pipeline can bind to them and stay bound:
| Field | What it is |
|---|---|
articleUrl | Canonical article link, ready to fetch |
title | Article title |
author | Byline, where the article sets one |
digest | Short summary shown in feeds |
accountName | Official Account display name |
accountUserName | Official Account ID (gh_...) |
publishTime | Publish time, Beijing time, to the minute |
publishTimestamp | Publish time as a Unix epoch |
coverUrl | Cover image |
contentText | Article body as plain text |
contentHtml | Article body as HTML |
images | In-article images, each with url, width, height |
ipRegion | Publishing region, country and province |
album | The album (合集) the article belongs to, when it is in one |
commentId | Key for fetching this article's comments |
Every URL in this set is ready to use as sent. The cover image is not repeated inside
images.
Each row also carries a content object with the article's full record as WeChat
publishes it, which is far richer than the table above. Treat content as a bonus, not as an interface. Its
field names come straight from WeChat and can change without notice. If you need
something from it in a production pipeline, tell us and we will promote it to the stable
set.
The examples below are abridged the same way: besides the stable set and content, an
article-detail row carries about 15 more top-level fields straight from WeChat. Nothing is
dropped on the way to your dataset — the full column list per operation is on the Actor's
Output tab.
Output example: article detail
Output example: article search
Output example: article metrics
Output example: account search
Output example: WeChat Index trend
Advanced Usage
Ready-made configurations for brand monitoring, competitor benchmarking, KOL discovery and content trend research.
Brand monitoring: track a keyword's popularity over time
Schedule this daily and each run appends a fresh 30 day trend series per brand. Plot the result against your campaign dates to see which pushes moved the needle.
Competitor benchmarking: what did their account publish, and did it land
Feed the resulting article links back in with articleMetrics to attach read and share counts to each one.
KOL discovery: find and vet accounts in a niche
Every hit already carries the verified owning company and the original-article count, so you can filter out reposting accounts without a second lookup.
Content research: what is trending on a topic this week
sortBy: hot ranks by likes rather than relevance, so the top of the list is what actually travelled this week.
Daily monitoring: what an account posted today
Run this on a daily schedule. Results are filtered to the current day in China time.
Integrations
Results land in a standard Apify dataset, so they flow into Google Sheets, Make, Zapier, Slack, or any HTTP webhook without extra work. Schedule runs from the Apify console for recurring monitoring.
New to scheduling on Apify? This walkthrough covers it:
Pricing: Pay Per Event (PPE)
$5.99 per 1,000 article search results. Volume discounts apply automatically as your Apify tier rises.
| Event | Per result | Per 1,000 |
|---|---|---|
| Article result | $0.00599 | $5.99 |
| Comment | $0.00299 | $2.99 |
| Account result | $0.00799 | $7.99 |
| Article detail, metrics or account info | $0.02999 | $29.99 |
Mini programs are $0.01499 each, and WeChat Index trends and autocomplete sets $0.29999 each.
Free tier: 25 lifetime runs, one page of results per run. Mini program search, WeChat Index trends and autocomplete are paid-plan operations. No credit card required.
FAQ
What is a WeChat Official Account (公众号 / Gongzhonghao)? A WeChat Official Account is the publishing channel brands, media and government bodies use inside WeChat (Weixin, 微信), China's largest messaging platform. Accounts push articles to subscribers, and those articles are the main long-form content format in the Chinese internet. This Actor covers the Official Account side, sometimes called WeChat MP; the short-video side is WeChat Channels (视频号), which is a separate product.
Which operations can I run? Fifteen: article search, account search, mini program search, autocomplete suggestions, WeChat Index, article details, article metrics, article comments, comment replies, link conversion, account profile, account owner, original article count, today's articles and article history.
How many results can I extract? Up to 50 entries per run, each paginated up to 50 pages. Article search returns roughly 20 results per page, account history 10 per page.
How fresh is the data? Live. Every run reads WeChat at request time, with no cached layer in between. Read counts and comment counts reflect the moment you run it.
How do I get the read count of an article?
Use the articleMetrics operation with the article link. It returns reads, likes, "wow" reactions, shares, favourites and comment count in one row.
What is WeChat Index (微信指数) and what is it used for?
WeChat Index is WeChat's own keyword popularity measure, drawn from in-app searches, Official Account articles and Moments shares. It works like Google Trends for the Chinese market. Brands use it to size their share of attention, measure campaign lift, and spot rising topics. The wechatIndexSearch operation returns 30 daily values per keyword.
Can I find who owns an account?
Yes. The accountPrincipalInfo operation returns the verified registered company or organisation behind an account. It is also included free on every accountSearch hit.
Do I need a WeChat account or cookies? No. Provide a keyword, an article link or an account id and run it. No account, cookie export or QR login is involved.
Do I need a proxy or a China IP address? No. Everything is handled for you.
How far back does article history go?
As far as the account's public history page goes, 10 articles per page. Set maxPages higher to go deeper.
Can I get WeChat Channels (视频号) videos too?
Not in this Actor. Channels is a separate product with a different data shape. In the meantime, accountBasicInfo returns the Channels account linked to an Official Account, which is the join key between the two.
How do I export the data?
JSON, CSV, Excel, XML or HTML from the run's Storage tab, or through the Apify API. JSON preserves the nested fields such as dataPoints, menus and source best; CSV flattens them.
What happens if an article or account is unavailable? That entry is skipped and the run continues with the rest. Deleted, private and region-restricted articles are the usual causes.
Is it legal to scrape WeChat Official Account data? This Actor reads only publicly visible content, nothing behind a login. You are responsible for complying with WeChat's terms of service and with applicable data protection law, including GDPR, CCPA and China's PIPL. Comments and account profiles contain personal data such as nicknames, avatars and IP regions, so treat those fields accordingly.
What is the free tier? 25 lifetime runs, each capped at one page of results for the first entry, on every operation except mini program search, WeChat Index trends and autocomplete, which need a paid plan. No credit card required.
More Zen Studio scrapers for Chinese platforms
💬 WeChat 微信
- WeChat Official Account Scraper — articles, read counts, WeChat Index
- WeChat Channels Scraper — short video, creators, comments
🎬 Short-video & social
 Douban 豆瓣
 Weibo 微博
 Kwai (Brazil)
 Kuaishou 快手
 RedNote 小红书
- Douyin 抖音
 Xigua 西瓜视频
 Bilibili 哔哩哔哩
🛒 E-commerce
 Naver Search 네이버 검색
 AliExpress 全球速卖通
 Shopee
 Taobao 淘宝
 JD.com 京东
 1688 阿里巴巴
 Weidian 微店
 Goofish 闲鱼
 Coupang 쿠팡
🏠 Real estate & autos
 Naver 부동산
 Anjuke 安居客
 58.com 58同城
 Autohome 汽车之家
✈️ Travel & stays
 Ctrip 携程
🧭 Travel & maps
 Mafengwo 马蜂窝
Support
- Bugs: Issues tab
- Features: Issues tab
Legal Compliance
Extracts publicly available data. Users must comply with WeChat terms and data protection regulations (GDPR, CCPA, PIPL).
Sixteen WeChat Official Account operations in one Actor: search articles and accounts, pull read counts and comments, resolve account owners, and track WeChat Index keyword trends.


