
Job Scraper for Greenhouse, Lever, Ashby & Workable | JobsRadar
Pricing
from $0.72 / 1,000 job posting returneds
Job Scraper for Greenhouse, Lever, Ashby & Workable | JobsRadar
Job scraper for company career pages: search Greenhouse, Lever, Ashby, SmartRecruiters, Workable, Personio and Pinpoint job boards in one run. Deduplicated rows with the full job description, salary, seniority and employment type, filtered by title, location, remote and posting date.
Pricing
from $0.72 / 1,000 job posting returneds
Rating
0.0
(0)
Developer
AgentToolWorks
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
4 days ago
Last modified
Categories
Share
What is JobsRadar, the job board scraper?
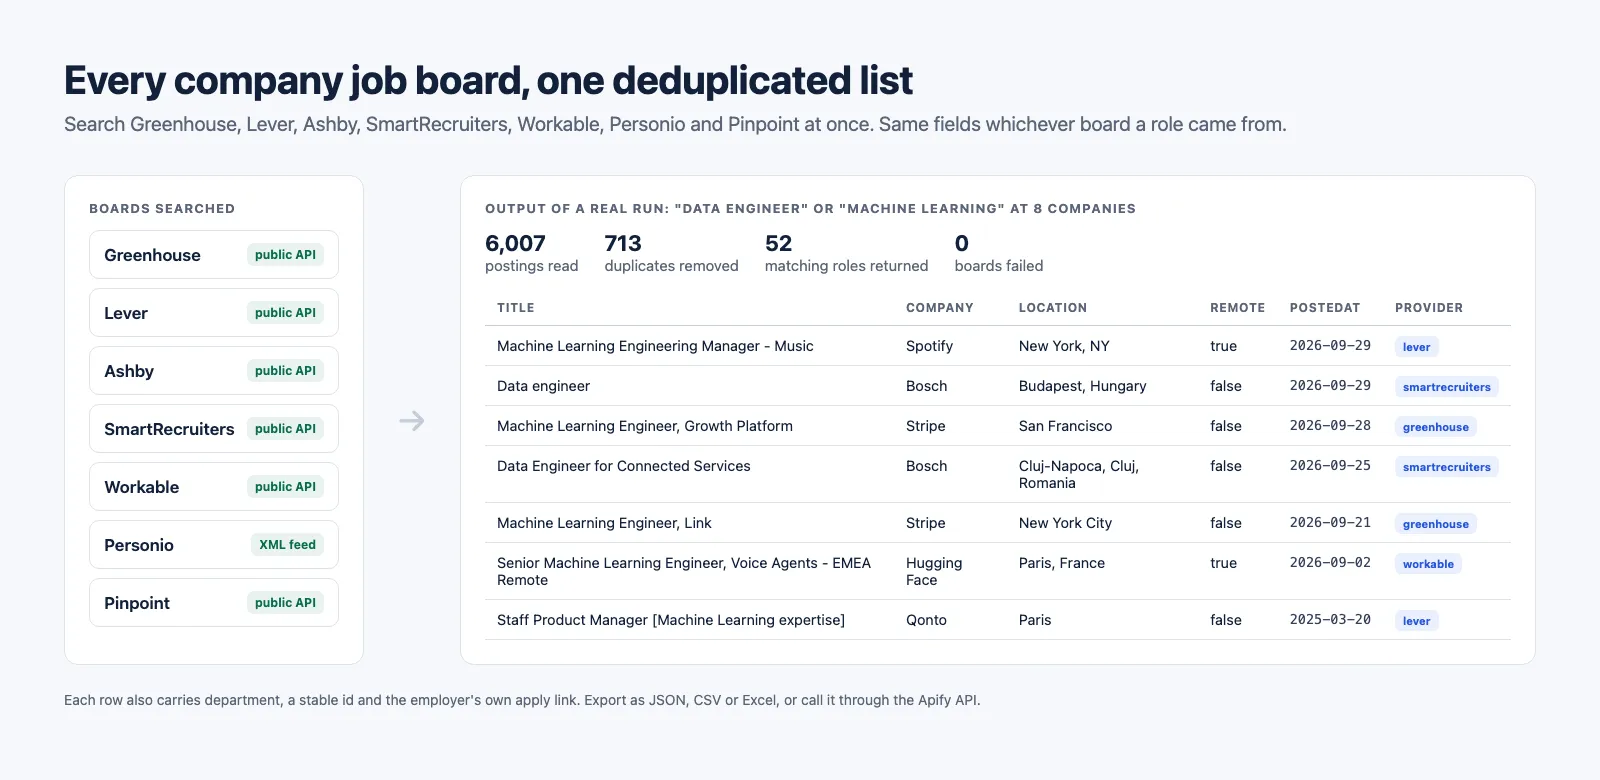
JobsRadar is a job scraper for company career pages. Every company runs its own job board on an applicant tracking system (ATS). JobsRadar searches Greenhouse, Lever, Ashby, SmartRecruiters, Workable, Personio and Pinpoint at once and gives you back one deduplicated, normalized list of open roles, with the full job description and the salary wherever the employer publishes one, and filters on title, location, remote and posting date.
In short
- What you get: every open role on seven applicant tracking systems in one run, one row per role in the same format: title, company, location, posting date, the employer's own apply link, the full description (text and HTML), the salary as published and parsed into min, max, currency and period, and seniority, employment type and workplace type wherever the board publishes them.
- What it costs: $0.90 per 1,000 roles ($0.72 on Apify Business plans), description and salary included, charged per role delivered.
- Why this one (prices read from the Apify Store API on 2026-10-13): $0.90 per 1,000 where bovi/greenhouse-lever-ashby-job-scraper charges $1.50 ($1.455 on Business plans) and fantastic-jobs/greenhouse-jobs-api $2.00 ($1.20 from Apify's Silver tier up); seven systems in one run, where bovi's reads six (Recruitee, which JobsRadar does not read, but not Workable or Pinpoint) and fantastic-jobs' reads Greenhouse only; the salary as numbers from each board's own pay fields, where bovi documents one salary text field and fantastic-jobs fills its numeric salary fields with an LLM reading the description (its README says those fields "might contain mistakes"), next to a raw salary object it calls "often partial"; and every board read live when you run it, where fantastic-jobs serves its own database (new jobs added twice an hour, expired ones removed daily, per its README).
It reads the official public job board APIs and feeds these platforms publish so employers can distribute their openings: no login, no cookies, and apply links that point at the employer's own page.
What data can you extract from company job boards?
One row per open role, with the same fields whichever board it came from:
| Field | Example | Notes |
|---|---|---|
id | greenhouse:stripe:8224915 | Stable across runs: provider, board and the board's own job id |
title | Machine Learning Engineer, Growth Platform | |
company | Stripe | |
location | San Francisco | As the employer published it |
remote | false | Only true when the board itself marks the role remote |
department | Engineering | When the board publishes one |
postedAt | 2026-09-28T15:58:13.000Z | ISO 8601 in UTC for every board (a bare date when the board publishes only a day). Empty for Pinpoint, which publishes none |
applyUrl | https://stripe.com/jobs/search?gh_jid=8224915 | The employer's own application page |
provider | greenhouse | Which ATS the role came from |
workplaceType | remote | remote, hybrid or onsite, only from a field the board fills for it, never from the location text |
employmentType | Full-time | As the board words it (Permanent, Full-time on Personio, which publishes both) |
seniority | Mid-Senior Level | As the board words it, where it publishes one |
salaryText | $140.8K - $231K | The board's own wording, or its pay range written out (120,000 - 220,000 USD per year) |
salaryMin, salaryMax | 140800, 231000 | Numbers from the board's own pay fields. A one-sided range leaves the other side empty |
salaryCurrency | USD | ISO 4217 code |
salaryPeriod | year | year, month, week, day or hour. Empty when the board names no period (many Greenhouse ranges are titled "Base Salary Range") |
description | Summary\n\nThe Cloud Capacity team... | The full description as plain text |
descriptionHtml | <h1><strong>Summary</strong></h1>... | The same, as HTML, with each section under its own heading |
Where a board publishes nothing for a field, it is null, never guessed. What each board actually filled, in a run over the whole directory (2026-10-13, 4,924 roles whose title contains "engineer"):
| Board | Roles | Description | Salary (numbers) | Seniority | Employment type | Workplace type |
|---|---|---|---|---|---|---|
| Greenhouse | 2,584 | 100% | 48.8% | 10.3% | 9.2% | 7.2% |
| SmartRecruiters | 1,624 | 100% | 4.5% | 84.7% | 100% | 28.6% |
| Ashby | 368 | 100% | 48.9% | not published | 100% | 81.5% |
| Pinpoint | 181 | 100% | 83.4% | not published | 100% | 100% |
| Lever | 70 | 100% | 1.4% | not published | 94.3% | 100% |
| Workable | 58 | 100% | no salary field | 86.2% | 96.6% | 19.0% |
| Personio | 39 | 100% | 5.1% | 100% | 100% | not published |
A salary appears only where the employer chose to publish one in the board's pay fields: 34% of these roles. Employers who write pay into the description text instead (Workable has no pay field at all) have it in description, as written, not parsed.
What can you use job posting data for?
- Recruiting and talent mapping: watch hiring at a list of competitors and see which teams are growing.
- Salary research: published pay ranges as numbers, per company, role, location and period.
- Sales prospecting: companies hiring for a role are often buying the tools that role uses.
- Job search apps and AI agents: one source that covers many employers, instead of one scraper per careers site.
- Labor market research: track demand for a skill or a title across a sector over time.
- Job alerts: schedule a run with
postedAfterand get only new roles.
How to scrape jobs from Greenhouse, Lever, Ashby and more
- Click Try for free (or Start) on this page and sign in to Apify.
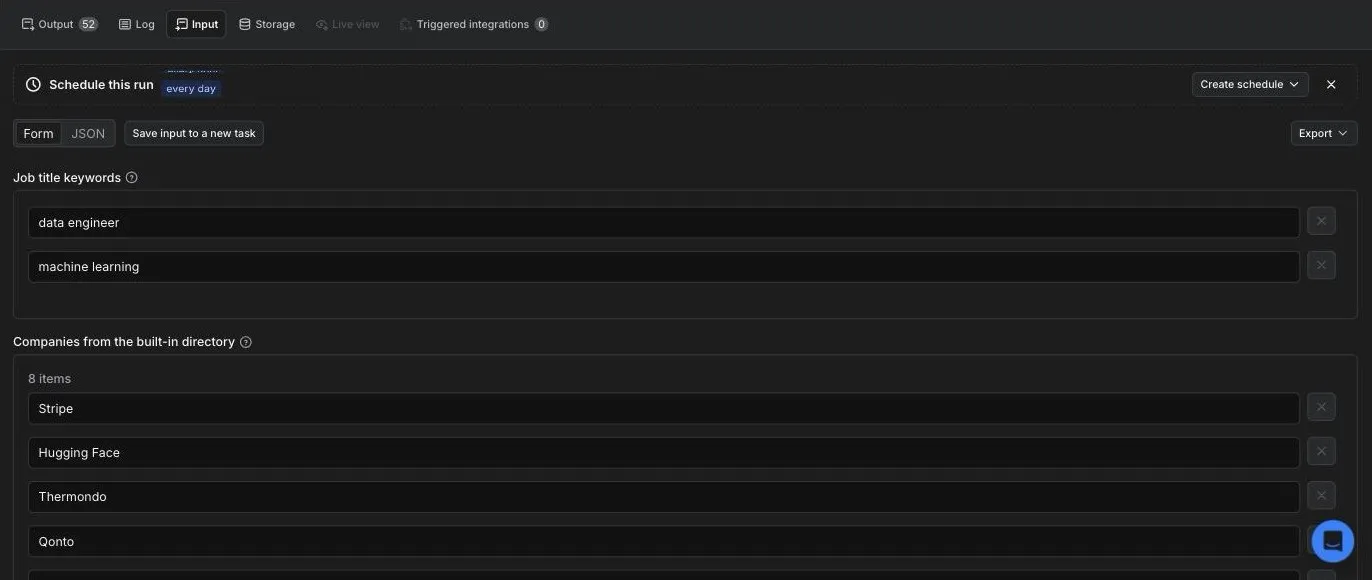
- Type the titles you care about in Title keywords, for example
data engineer. - Pick companies from the built-in directory in Companies, or add any company's board in Board slugs (see Input for where to find a slug). Leave both empty to search the whole directory of 116 companies.
- Optionally filter on Location, Remote only or Posted after, and set Max results.
- Click Start. Open the Output tab when the run finishes and export as JSON, CSV, Excel or XML, or read it through the API.
Input
| Field | What it does |
|---|---|
titleKeywords | Keep roles whose title contains any of these, for example ["data engineer", "machine learning"]. Empty keeps every role. |
companies | Names from the built-in directory, for example ["Stripe", "Hugging Face", "Bosch"]. Empty searches all 116. |
boardSlugs | Any company's board, by the slug in its careers page URL: [{ "slug": "acme" }]. The ATS is detected for you; add "provider" to skip detection and "company" to set the name shown in results. |
location | Keep roles whose published location contains this text, for example London or Germany. |
remoteOnly | Keep only roles the board itself marks remote, rather than guessing from the location. |
postedAfter | ISO date, for example 2026-09-01. Roles published without a date are kept rather than hidden. |
maxResults | Upper bound on returned postings (default 200, up to 5,000). You pay per posting returned. |
includeDescription | The full description on every row (default on). Same price either way. Off gives smaller rows and a faster run when many roles come from SmartRecruiters (see How fast is it?); salary, seniority and the types stay, except SmartRecruiters' salary, which comes with its description. |
Where to find a board slug:
| ATS | Careers page URL | Slug |
|---|---|---|
| Greenhouse | boards.greenhouse.io/acme | acme |
| Lever | jobs.lever.co/acme | acme |
| Ashby | jobs.ashbyhq.com/acme | acme |
| SmartRecruiters | jobs.smartrecruiters.com/Acme | Acme |
| Workable | apply.workable.com/acme | acme |
| Personio | acme.jobs.personio.de | acme |
| Pinpoint | acme.pinpointhq.com | acme |
Example: remote engineering roles at two directory companies and one company tracked by its slug.
Output
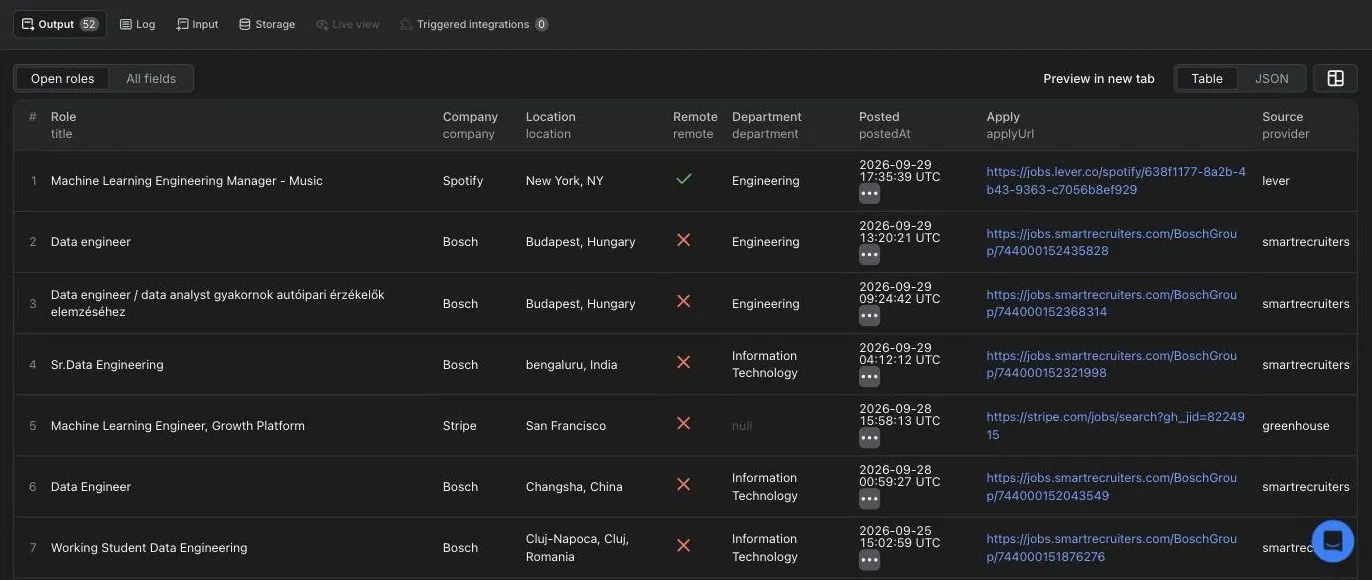
The Open roles, Salaries and Descriptions views show the columns that matter for each use; the full row has every field. A row from a real run (2026-10-13, the description shortened here):
The run's key-value store also holds a SUMMARY record, so a board that failed never silently shrinks your results, and you can see what each board filled (here, the whole directory):
boardsFailed names each board that did not answer, with the reason. boardsTruncated names a board read in part, with how many postings it has in total. descriptionsNotRead counts SmartRecruiters roles returned without their description because the posting itself could not be read (after one retry).
How much does it cost to scrape job postings?
Pay per event, no subscription, platform usage included:
| Event | Price |
|---|---|
| Posting returned | $0.90 per 1,000 postings ($0.0009 each), full description and salary included ($0.72 on Apify Business plans) |
| Run start | $0.00005 |
Examples:
- 200 postings (the default maximum): $0.18.
- The whole directory, every role with "engineer" in its title (4,924 roles on 2026-10-13): $4.43.
- Apify's free plan includes $5 of monthly usage (apify.com/pricing), enough for about 5,500 postings a month.
- A run whose filters match nothing costs only the start fee: postings that do not match your filters are read but never charged.
Set a maximum cost per run in the run options and the Actor stops cleanly when it is reached.
Use JobsRadar through the Apify API
Run it and get the postings in one HTTP call (your token is in Apify Console under Settings > API & Integrations):
Node.js, with the official apify-client:
Python, with the official apify-client:
The API tab on this page has ready-made snippets for every language and endpoint.
FAQ
Which companies are in the built-in directory?
116 companies across the seven systems. Type any of these names in Companies: 1KOMMA5°, Accor, Affirm, Airbyte, Airtable, Algolia, Amplitude, Anthropic, Asana, AssemblyAI, Blueground, BMT, Bosch, Brex, Calendly, Canva, CERN, CFC, Chainguard, CLARK, ClickHouse, Cloudflare, Cockroach Labs, Coinbase, Contentful, Databricks, Datadog, Delivery Hero, Discord, Duolingo, Elastic, Epignosis, ESSS, Experian, Fastly, Figma, Fivetran, Future plc, getquin, GitLab, GoCardless, Grasshopper Bank, Gusto, Hex, HOLOPLOT, Hugging Face, idealworks, IFS, Impulse Space, inMusic, Instacart, Intercom, Intigriti, Lattice, LearnWorlds, Linear, LinkedIn, Lyft, Marqeta, Mercury, meteocontrol, Miro, Mixpanel, Modal, MongoDB, Monzo, Neon, Netlify, Nielsen, Nothing, Notion, Okta, Orfium, ottonova, Oura, Patreon, Penta, Persado, PETER PARK, Pinpoint, Pinterest, PlanetScale, PostHog, Princess Cruises, Qonto, Ramp, Ravelin, Redis, Reverion, Robinhood, Rowden, Scale AI, Secureframe, Semgrep, Sentry, ServiceNow, Skroutz, Sodexo, Spotify, Stripe, Supabase, Swile, tado, Tailscale, Temporal, Thermondo, TP-Link Systems, Ubisoft, Unmind, Vanta, Vercel, Vivid Money, Webflow, Western Digital, Wise, Zapier.
Any other company works through Board slugs.
How do I get only new jobs every day?
Save your input as a task, set Posted after to a recent date, and schedule the task daily in Schedules. Use the stable id field to skip roles you have already seen.
How fast is it?
Measured on Apify on 2026-10-13, at the default memory: a run over the whole directory (116 boards) read 19,614 postings in 28 seconds and returned the 4,924 whose title contained "engineer", with descriptions, in 4 minutes 33 seconds. Most of that is SmartRecruiters: it publishes a description only on each posting, so its 1,624 roles took one request each, paced under SmartRecruiters' documented rate limit. With Full description off, the same search took 32 seconds. A handful of companies takes a few seconds.
Does it include jobs from aggregators like LinkedIn Jobs or Indeed?
No, by design. JobsRadar reads employers' own job boards, which is where roles are published first and where the apply link leads.
How large a board can it read?
SmartRecruiters boards are read 100 postings a page, up to 5,000 postings a board. A larger board is listed in boardsTruncated with its full count, never cut silently. The other systems return the whole board in one response. SmartRecruiters' descriptions and pay are read posting by posting, only for the roles you get back, after your filters and Max results.
Does it return the full job description and the salary?
Yes, on by default, at the same price. The description comes as text (description) and as HTML (descriptionHtml), as the employer published it, with each section under its own heading. The salary comes as the board words it (salaryText) and as numbers (salaryMin, salaryMax, salaryCurrency, salaryPeriod), read from each board's own pay fields: Greenhouse pay ranges, Lever salary ranges, Ashby compensation, Personio salary information, Pinpoint compensation and SmartRecruiters compensation.
Why is the salary empty for many roles?
Because the employer did not publish one. Pay ranges are optional on every one of these systems, and in the whole-directory run above 34% of roles had one (half of Greenhouse and Ashby roles, 83% of Pinpoint's, under 6% elsewhere). Workable has no pay field: employers who state pay there write it in the description, which you get in full. JobsRadar never guesses a salary, and leaves salaryPeriod empty when the board does not name the period, rather than assuming a year.
Why is postedAt empty for some roles?
Pinpoint publishes no posting date, so it stays empty rather than guessed. Those roles are kept when you filter on Posted after.
Can I use it with Make, Zapier, n8n or Google Sheets?
Yes, through Apify's integrations: the dataset works with every Apify integration, and a webhook can fire when a run finishes.
Can AI agents use it through MCP?
Yes, two ways. Apify's hosted MCP server exposes it to MCP clients such as Claude or Cursor: https://mcp.apify.com?tools=agenttoolworks/jobsradar-multi-board-job-search. JobsRadar is also a hosted MCP server and API of its own, billed per search rather than per posting, at agenttoolworks.com/servers/jobsradar.
Is it legal to scrape job postings?
JobsRadar reads only the role listings employers chose to publish, through the public job board APIs the platforms document for career sites. It collects no candidate data.
Something is missing or broken?
Open an issue in the Issues tab. Companies asked for by users get added to the directory.
Other Actors by AgentToolWorks
- Shopify & WooCommerce Scraper and Price Tracker: every product of any Shopify or WooCommerce store, with variants, barcodes and stock, plus price and stock change tracking.
- Facebook Ad Library Scraper: ads from the Meta, Google and Microsoft ad libraries in one table.
- LinkedIn Jobs and Indeed Scraper: public job listings of both boards in one row format.
- Google Maps Scraper: every place inside a city's real boundary, with phone, website, rating, review count, opening hours and emails.
- Google Trends Scraper: interest over time, by region and related queries for terms and comparisons, plus each country's Trending now list.
Built by AgentToolWorks. Not affiliated with any of the job board platforms named here.


