
Facebook Ads Library Scraper
Pricing
from $2.72 / 1,000 ads
Facebook Ads Library Scraper
Facebook Ads Library scraper: export the ads of any Facebook page, keyword or Meta Ad Library URL (filters kept) without a Facebook account. Ad copy, creatives, CTA, links, platforms, dates, and optionally the products behind each ad. Exact limit, pay per ad.
Pricing
from $2.72 / 1,000 ads
Rating
0.0
(0)
Developer
Badr Bouargan
Maintained by CommunityActor stats
0
Bookmarked
3
Total users
2
Monthly active users
5 hours ago
Last modified
Categories
Features
Share
Facebook Ads Library Scraper – Meta, Instagram Ads & Spend
What it does. It exports the ads of any Facebook page, keyword or Meta Ad Library search into a clean table: ad copy, creatives (images, videos, carousels), CTA, destination links, platforms (Facebook, Instagram, Messenger, Threads, WhatsApp, Audience Network), start and end dates, spend and reach when Meta publishes them, advertiser details, and optionally the products and prices behind each ad.
The problem it solves. The Ad Library website shows ads one card at a time and has no export; Meta's official Ad Library API requires identity verification and returns mainly political and social-issue ads (plus ads delivered in the EU). This Actor reads what the Ad Library shows logged-out visitors, for every ad type, without a Facebook account or cookies.
Who it is for. Performance marketers and media buyers doing competitor research, agencies building creative swipe files, e-commerce and dropshipping teams watching products and prices, and researchers or journalists tracking political and EU ads.
What you get. One row per ad: pageName, adArchiveID, isActive, startDateFormatted, endDateFormatted, publisherPlatform, snapshot.body.text, snapshot.ctaText, snapshot.linkUrl, snapshot.images / videos / cards, spend, reachEstimate, plus ad_details, pageInfo and ecommerceData when you switch them on. Sample (real run, shortened):
| pageName | adArchiveID | isActive | startDateFormatted | publisherPlatform | ctaText | linkUrl |
|---|---|---|---|---|---|---|
| Sephora | 1570487428042958 | true | 2026-08-01T07:00:00.000Z | FACEBOOK, INSTAGRAM, MESSENGER, THREADS | Shop now | http://www.sephora.com/ |
Start in 3 steps
- Open the Actor on the Store: apify.com/badr_xba/facebook-ads-library-scraper and click Try for free (or start from a ready-made task on the same page when one is listed).
- Paste a Facebook page URL (
https://www.facebook.com/nike), any Meta Ad Library URL (set your filters on facebook.com/ads/library and copy the address bar), or type keywords such asrunning shoes. Set the results limit (for example 50). - Click Start. Ads appear in the Ads table during the run; export them to CSV, Excel or JSON.
The prefilled example (20 Sephora ads) finished in about 10 seconds in the author's tests and costs about $0.09.
Why choose this one
- No Facebook account, cookies or Meta API token.
- Paste the Ad Library URL as it is: every filter in it (country, language, media type, active status, ad category) is kept. Page URLs in any form (
m.,web.,fb.com,profile.php?id=) and@pagenames work too. - The results limit is exact: you never get, or pay for, more ads than you asked for. Inputs that give nothing are listed in
FAILED_INPUTSand never billed. - Products behind the ads (optional add-on): name, price, currency, brand and rating read from the ad's landing page, billed only per product found.
- Advertiser and EU transparency data (optional): Instagram username and followers, page likes and category, and for EU ads the audience, reach by country, age and gender, payer and beneficiary.
- Market sizing in one row per page with Get only the total ad count.
- Familiar input names (
startUrls,resultsLimit,onlyTotal,isDetailsPerAd,includeAboutPage,activeStatus…), so an input written for the Store's reference Facebook Ads scraper works as it is.
How much it costs
Pay per event. Platform usage is included. From November 24, 2026, a tiny $0.00005 start fee per run is added (one event per GB of memory); before that date there is no start fee.
| Event | Free | Starter | Scale | Business |
|---|---|---|---|---|
Ad (or one total with onlyTotal) | $4.64 / 1,000 | $4.00 / 1,000 | $3.36 / 1,000 | $2.72 / 1,000 |
| Add-on: E-commerce enrichment (per product found) | $4.56 / 1,000 | $2.56 / 1,000 | $2.24 / 1,000 | $1.92 / 1,000 |
Worked examples (Free plan): 1,000 ads = $4.64. 20 ads ≈ $0.09. 100 ads with the e-commerce add-on finding 40 products ≈ $0.46 + $0.18 = $0.65. You can also cap any run with a maximum cost per run: the Actor stops cleanly before going over it.
What can it do?
- 🧩 Ads published across Meta platforms: Facebook, Instagram, Messenger, Threads, WhatsApp and Audience Network
- 🔎 Any Ad Library search: brand, keyword, country, language, media type, active or inactive, ad category. Paste the URL and every filter in it is kept
- 🔤 Keyword search without building a URL: type
black fridayand choose a country (or ALL) - 🎯 A single ad: paste
https://www.facebook.com/ads/library/?id=… - 🌍 Every country at once (
ALL) or one country - 📅 Date range, sorting (impressions or most recent) and active status
- ⏱️ Minimum days running (
minDaysRunning): keep only ads that ran at least N days, the long-running ones that usually work. Shorter ads are skipped and not billed. Each row hasdaysRunning - 🏷️ Run tag (
runTag): a label copied to every row, to tell clients or weekly runs apart when you merge datasets - 🏢 Advertiser details: Instagram username and followers, page likes, category, verification, page spend, related pages in other countries
- 💸 Spend, reach, impressions and EU audience (age, gender, country, payer and beneficiary) when Meta publishes them
- 🛒 E-commerce enrichment: the product, price, brand and rating behind each ad's link
- 🔢 Only the total number of ads of a page, for quick market sizing
- 📤 Export to JSON, CSV, Excel, XML or HTML, or use the API, webhooks, Make, Zapier, n8n or the Apify MCP server
Use cases
- Media buyers: pull a competitor's active ads sorted by impressions and see which hooks, formats and CTAs they keep running (
startDateFormatted,isActive). - Agencies: build a creative swipe file for a niche with a keyword search (
running shoes,meal kit) in one country, images and videos included. - E-commerce and dropshipping: switch on the e-commerce add-on to see which products and prices brands push in their ads.
- Market sizing: Get only the total ad count for a list of pages to compare advertising activity across competitors.
- Researchers and journalists: collect political, social-issue and EU ads with the spend, reach and audience data Meta publishes.
What you can paste
| You paste | What you get |
|---|---|
https://www.facebook.com/SHEINOFFICIAL (also m., web., fb.com, /pg/…) | All ads of that page |
https://www.facebook.com/profile.php?id=100064… or /people/Name/100064…/ | All ads of that page |
https://www.facebook.com/ads/library/?…&view_all_page_id=… | That advertiser, with the URL's filters |
https://www.facebook.com/ads/library/?…&q=shoes&country=FR | That search, with the URL's filters |
https://www.facebook.com/ads/library/?id=1106694961565426 | That one ad |
Keyword: running shoes (in Search keywords / page names) | Ads whose text matches, in the chosen country |
Page name: @nike | All ads of that page |
Several URLs pasted on one line (separated by commas or new lines), duplicates and extra spaces are cleaned up automatically. Anything that is not Facebook (an Instagram link, a Facebook group) is skipped and listed in FAILED_INPUTS, never billed. With an empty input, the Actor runs the Sephora example and says so in the log.
Input example
The input uses the same field names as the Store's reference Facebook Ads scraper (startUrls, resultsLimit, onlyTotal, isDetailsPerAd, includeAboutPage, activeStatus, …), so an existing input works as it is.
Output example
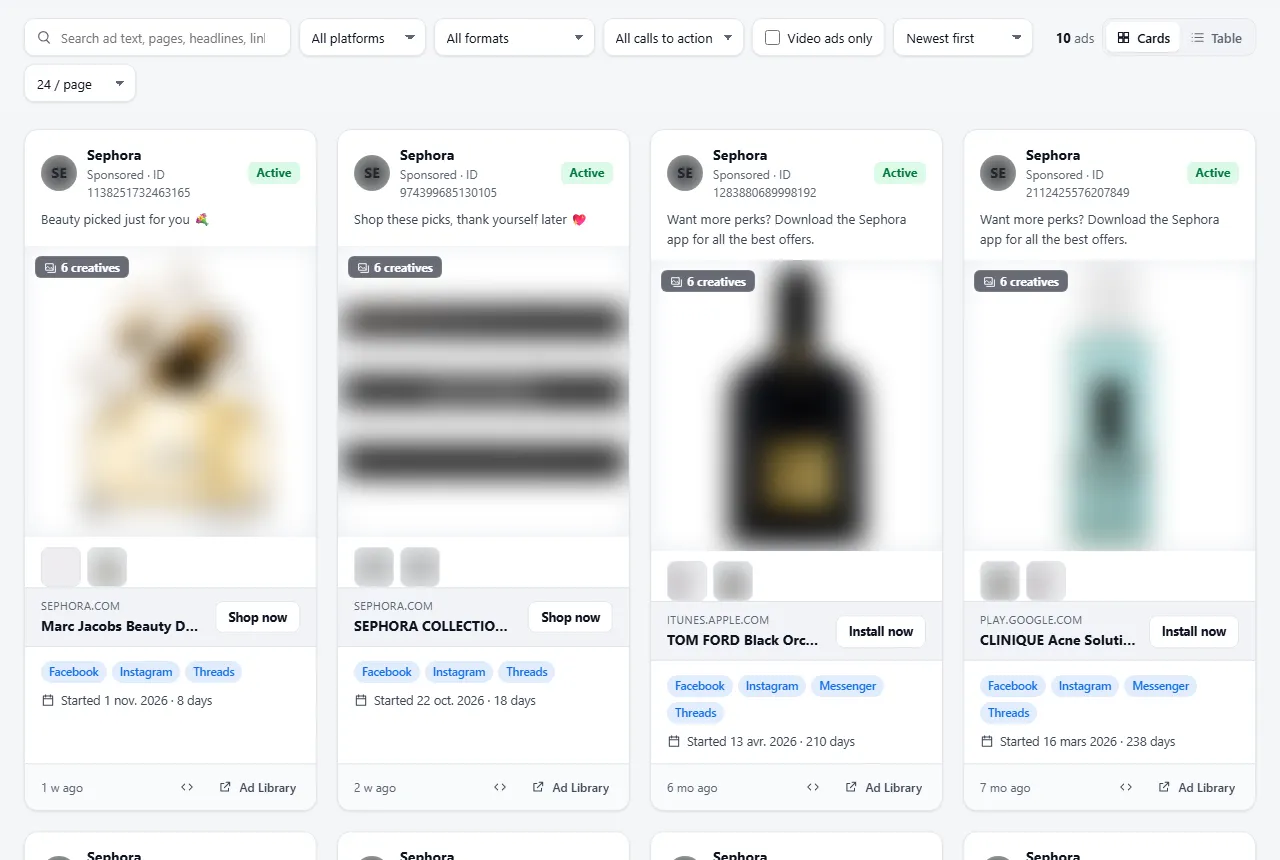
Screenshots from a real platform run. Photos of people are blurred in this screenshot.
One row per ad (shortened; real row from a run):
With extra ad details, each row gets ad_details (advertiser page and Instagram data, page spend, EU audience and reach). With About, it gets pageInfo. With e-commerce, it gets ecommerceData:
With Get only the total ad count, you get one row per URL: { "inputUrl": "…", "pageID": "16453004404", "totalCount": 1680, "url": "…" }.
Every run also writes two records in the key-value store:
- RUN_SUMMARY:
{ "status": "SUCCEEDED", "adsSaved": 13, "productsBilled": 0, "urls": 7, "failedInputs": 2, "stoppedByBudget": false, … } - FAILED_INPUTS: what gave nothing, with the reason (never billed), e.g.
{ "input": "https://www.instagram.com/nike/", "type": "invalidInput", "reason": "Skipped: not a Facebook page URL or Meta Ad Library URL. …" }
Visual report
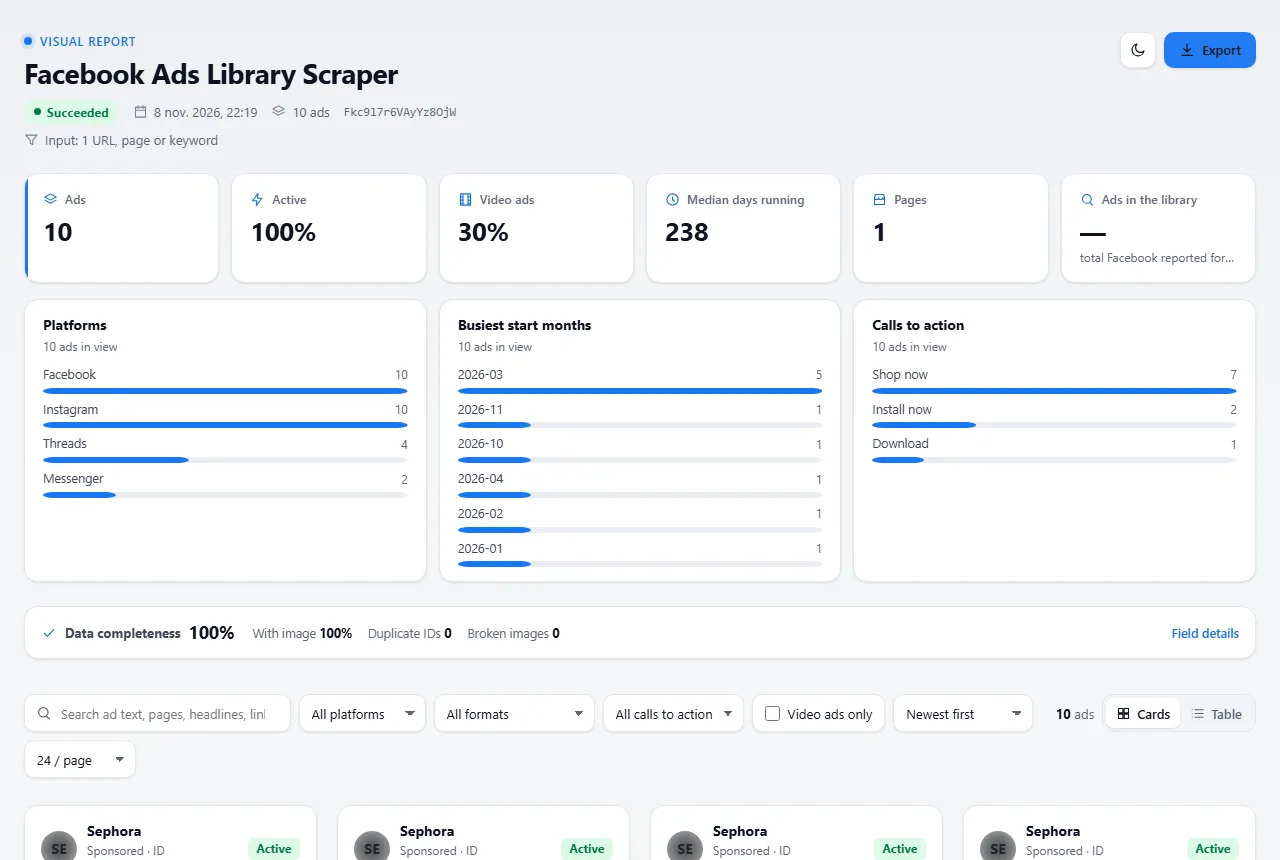
Every run also saves a visual report: one HTML page that shows your ads as cards, the way they look in the library.
- One card per ad: page picture and name, active/inactive status, ad text, creative preview (video badge; carousel, dynamic and catalog ads open as a gallery of up to 3 creatives; the badge tells the real number of creatives), link caption, headline, call-to-action button, platforms and start date with the number of days it ran.
- Search totals (when you ask for the total only): the number of ads Facebook reports for each search.
- Key figures and charts: ads, share of active and video ads, median days running, pages, ads in the library; platforms, busiest start months, calls to action. They follow your filters.
- Search, filters and sorting: ad text/page/headline/link search, filters by status, page, platform, format, call to action and video ads; sort by start date, days running or number of similar ads. Card or table view.
- Viewer: click a creative to see it full size, with arrows, keyboard (← → Esc) and swipe on mobile.
- Export: download the filtered rows as JSON or CSV, or the full dataset as JSON, CSV or Excel.
- Live progress: while the run works, the page shows a progress bar (URLs and keywords done / total) and the ads saved so far, and refreshes itself every 30 s.
- Data quality: a panel shows how complete the key fields are (advertiser, ad text, headline, call to action, link, platforms, dates, format).
- Inputs that failed are listed at the top, grouped by reason (they are not billed), with run notes such as ads skipped by the minimum days running.
How to open it: in the run, go to the Output tab and choose Visual report (or open the REPORT record of the key-value store). The page works in any browser, offline included, except for the pictures.
Creatives are shown straight from Facebook in your browser; nothing is re-hosted. Facebook signs these links and they expire after a few days, so an older report shows neutral placeholders where creatives used to be — the data stays. The report holds the first 1,000 ads of a run; the full dataset is always one click away. Saving the report is never billed and can never make a run fail.
What it can and cannot do
| ✅ Can | ❌ Cannot |
|---|---|
| Every ad Meta shows logged-out visitors in the Ad Library, in every country | Ads Meta does not show in the Ad Library |
| Spend, reach and impressions when Meta publishes them (political, social-issue and EU-targeted ads) | Spend or reach of ordinary commercial ads outside the EU: Meta publishes none |
| Page name, URL, photo, description, related pages (About) | Confirmed owner, address and page history (shown only to signed-in users) |
| Products behind real product pages | Catalog templates ({{product.name}}), sign-up pages and app links (skipped, not billed) |
| Keyword search exactly like the Ad Library search box | Better relevance than Meta's own search (keywords match words anywhere in the ad) |
FAQ
Do I need a Facebook account, cookies or the Meta API? No.
Can I scrape all countries? Yes: country is ALL by default, or paste an Ad Library URL with any country.
How many ads can I get? Everything the Ad Library lists for your search. Leave the limit empty for all ads; a big brand can have thousands.
Why is totalCount 50001? The Ad Library stops counting at 50,000: 50001 means "more than 50,000 ads".
How fast is it? About 30 ads every few seconds. Extra ad details add one request per ad.
Why do some keyword results look unrelated? Meta's keyword search matches the words anywhere in the ad (text, page, links). For exact results, open the Ad Library, search with quotes ("running shoes"), and paste that URL.
Is it legal? The Actor scrapes only publicly available data that Meta shows logged-out visitors in the Ad Library. You are responsible for complying with Meta's terms and with data-protection law: some fields (payer and beneficiary names, page details) may be personal data under the GDPR, so use them for a legitimate purpose only.
Can I monitor a competitor every day? Yes: save your input as a task, add an Apify Schedule, and set Scrape ads newer than to 1 day (relative values such as 7 days, 2 weeks or 3 months are accepted).
Do I pay for the e-commerce add-on when no product is found? No. It is billed per product found; sign-up pages, app links and catalog templates are free.
Troubleshooting
- A URL is in FAILED_INPUTS with "not found": the page has no ads in the Ad Library, or its alias is different. Open the page in the Ad Library, select it, and paste that URL (it contains
view_all_page_id). - "No ads match these settings": your filters (active status, dates, country) exclude every ad. Try
activeStatus= Active and inactive, or country ALL. - "Partial: Facebook rate-limited": Facebook slowed the run down after many pages. You keep (and pay for) only what was saved; run again later for the rest.
- The run stopped early: check RUN_SUMMARY:
stoppedByBudget: truemeans your maximum cost per run was reached. - Something else? Open an issue on the Issues tab with your run ID.
Use it via API
Python (pip install apify-client)
JavaScript (npm install apify-client)
cURL (runs the Actor and returns the ads in one call)
Integrations
- API: run the Actor and download results as JSON, CSV or Excel with the Apify API or the Python/JavaScript clients (see above).
- Make, Zapier, n8n: push new ads into Google Sheets, Airtable, Notion or Slack when a run finishes.
- Webhooks: call your own endpoint when a run succeeds or fails; branch on
RUN_SUMMARY.status. - Schedules: a daily run with Scrape ads newer than =
1 daytracks competitors' new ads. - MCP / AI agents: add the Actor to Claude, Cursor or any MCP client through the Apify MCP server (
https://mcp.apify.com) and ask, for example, "get the 30 latest active ads of Nike in the US".
Support
Bug, missing field, or a page that should have worked? Open an issue on the Actor's Issues tab with the run ID.
Did this Actor do the job? A short review on its Store page helps other marketers find it.
Feedback and reviews
If this Actor saved you time, a short review on its Store page helps other users find it. If something did not work as expected, please open an issue on the Issues tab with your run ID: we read every issue.


