
AI Document & Web Analyzer — powered by Claude
Pricing
from $1.50 / 1,000 item analyzed (own key)s
AI Document & Web Analyzer — powered by Claude
Run Claude on web pages, PDFs, DOCX, images, texts or any Apify dataset: summarize, extract to your JSON schema, classify, compare or report. Bring your own Anthropic API key. Cost caps, token estimates, visual report. Not affiliated with Anthropic.
Pricing
from $1.50 / 1,000 item analyzed (own key)s
Rating
0.0
(0)
Developer
Badr Bouargan
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
12 hours ago
Last modified
Categories
Features
Share
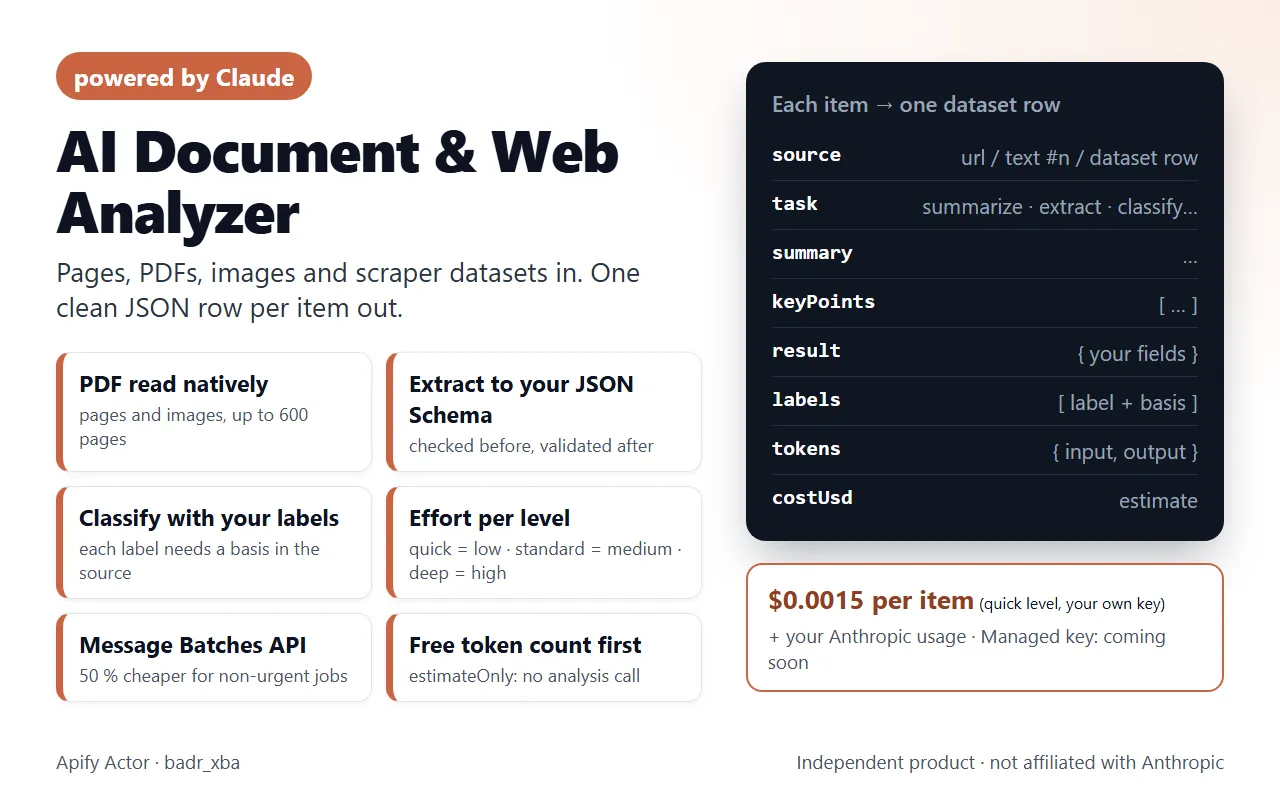
Turn web pages, PDFs, Word files, images, raw texts and the output of any other Apify Actor into clean, structured JSON with Claude (Anthropic). Pick a task (summarize, extract to your JSON Schema, classify with your labels, detect key information, compare, report or your own instructions) and get one dataset row per item, plus a visual REPORT page.
Independent product, not affiliated with or endorsed by Anthropic. "Claude" is used only to say which AI model powers this Actor.
Why use it
- One step after any scraper. Pass the dataset of Website Content Crawler, Google Maps, Amazon, LinkedIn Jobs or Facebook Ads scrapers (
datasetIds+datasetFields) and add an AI column to every row. - Structured, checkable output.
extractfollows your JSON Schema (checked before the run, validated after).classifyuses your labels, and every label comes with its basis in the source. - Cost under control.
estimateOnlycounts tokens with Anthropic's free token-counting endpoint before you spend anything;maxCostUsdandmaxTotalTokensstop the run before a request could go over. - Honest rows. Long sources are never cut silently (
truncated+truncationReason), images are the source's own (never generated), and confidence values are labelled as model-reported.
What Claude brings to this Actor
These are the Claude API features the code actually uses (see src/provider.py, src/prompts.py):
| Claude feature | What it means for you |
|---|---|
| Effort setting per analysis level (low / medium / high) | Deeper reasoning when you need it (deep), cheap and fast when you don't (quick). Thinking tokens count as output. |
| Native PDF reading (text and page images, up to 32 MB / 600 pages) | Tables, charts and scanned pages are read by Claude, not only the extracted text. |
Vision (imageUrls, optional page images) | Screenshots, receipts, charts and product photos. |
Structured JSON output (output_config.format) | Every answer is parsed JSON; extract is validated against your schema. |
Message Batches API (useBatchApi) | 50 % cheaper for big, non-urgent jobs (most batches finish within an hour, up to 24 h). |
Token counting (count_tokens) | Free, exact input counts for estimateOnly. |
Prompt caching (cache_control on the shared system prompt) | Repeated instructions across items are read from cache at a lower price. |
Server-side refusal fallback (fallbacks: "default") | On Opus 5.5, Sonnet 5.5 and Fable 5.1, another Claude model may answer a declined request; the row says which one (servedBy). |
Accepted sources
Mix them freely in one run. Items are taken in this order: texts, pages, documents, images, dataset rows (up to maxItems).
| Source | Input field | Details |
|---|---|---|
| Web pages | startUrls | One plain HTTP request per page (honest User-Agent, robots.txt respected, no JavaScript, no proxy, no anti-bot bypass). Readable text, title and up to 3 real images are kept. A URL that returns a PDF is read as a document. |
| Raw texts | texts | Emails, reviews, notes, transcripts. One entry = one item. |
| Documents | documentUrls | PDF (read natively by Claude, up to 32 MB / 600 pages; beyond that the extracted text is used and a warning says so), DOCX, TXT, MD, CSV. |
| Images | imageUrls | JPEG, PNG, GIF, WebP, analysed with Claude's vision. |
| Apify datasets | datasetIds + datasetFields | Each row becomes one item. Dot notation for nested fields (metadata.title). Empty datasetFields = every text and number field of the row. |
Use cases
- Content teams: summarize every page of a Website Content Crawler run, with key points and entities.
- Finance / ops: extract supplier, totals and due dates from invoice PDFs into your own schema.
- Recruiting / market research: pull salary, seniority and required skills out of LinkedIn job descriptions.
- Local lead generation: classify Google Maps places into your own segments, each label with its basis.
- E-commerce: turn Amazon product descriptions and feature bullets into a clean specs table.
- Ad research: classify Facebook Ads Library creatives by angle (price, urgency, social proof…).
- Legal / compliance first pass:
detect_key_infolists dates, amounts, deadlines, contacts, obligations and risks.
How it works
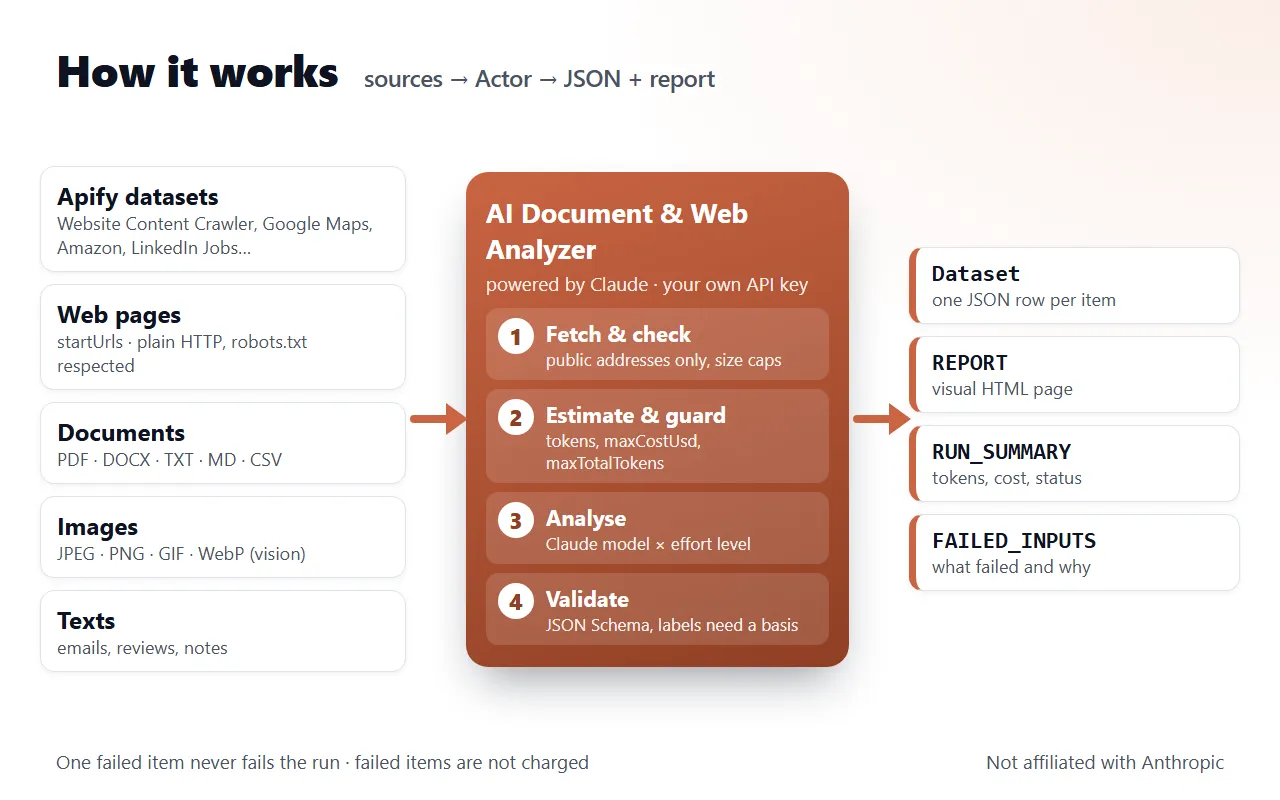
- Fetch and check every source (public addresses only, size caps, robots.txt).
- Estimate and guard: tokens are estimated (or counted) and checked against your caps before each request.
- Analyse with the chosen Claude model at the effort of your analysis level.
- Validate the JSON (your schema for
extract; labels without a basis in the source are dropped) and write one row per item, thenREPORT,RUN_SUMMARYandFAILED_INPUTS.
Tasks
task | What you get |
|---|---|
summarize (default) | title, summary, key points, entities, important info |
extract | the fields of your JSON Schema (outputSchema), in result |
classify | your labels (one, or several with multiLabel), each with its basis and a model-reported confidence |
analyze | findings in result |
detect_key_info | dates, amounts, deadlines, contacts, obligations, risks in importantInfo |
compare | ONE analysis across all sources (2 to 10), in one request |
report | report sections in result |
custom | the answer to your instructions (required for this task) |
Analysis levels and models
analysisLevel sets Claude's effort on the chosen model and the default output limit (from src/models.json):
analysisLevel | Effort | Max output tokens (thinking included) |
|---|---|---|
quick | low | 8,000 |
standard (default) | medium | 16,000 |
deep | high | 32,000 |
model chooses the Claude model (default Claude Opus 5.5). Anthropic list prices per 1M tokens, as stored in src/models.json (read 2026-11-09):
model | Input / output per 1M tokens | When |
|---|---|---|
claude-opus-5-5 (default, also "") | $4 / $20 | best quality and cost balance |
claude-sonnet-5-5 | $2 / $10 | high volume, still strong |
claude-haiku-5-5 | $0.10 / $0.50 (prompts up to 100K tokens) | large datasets, classification, simple extraction |
claude-fable-5-1 | $10 / $50 | most capable; needs 30-day data retention on your Anthropic organization |
All four have a 1M-token context window and up to 128K output tokens. As an estimate at list prices (not a measured run), a typical web page costs about $0.04 with Opus 5.5 quick and about $0.001 with Haiku 5.5. Your Anthropic invoice is the reference.
Pricing
- Your own Anthropic API key (available now): $0.0015 / $0.003 / $0.006 per analysed item for quick / standard / deep (one
item-analyzedevent × 1, 2 or 4), plus Apify's start event of $0.00005 per run. Anthropic bills you directly for the AI tokens. - Failed items, refusals and estimates are never charged.
- Managed key (no API key needed): coming soon. It is not open yet: a run with
apiKeyMode: "managed"stops before any AI call with a clear message, and nothing is charged.
API key setup
- Create a key in the Anthropic Console at platform.claude.com (API keys page). It starts with
sk-ant-. - Paste it into the Anthropic API key field (
apiKey). It is an Apify secret input: stored encrypted, never logged, never written to the output. - Leave API key (
apiKeyMode) onown_key.
Without a key, the run only estimates tokens and cost. Only the apiKey field is encrypted: a key put in any other field (for example anthropicApiKey through the API) is stored in plain text in the run input, and the run log tells you to rotate it (the value is never shown).
Input
Every field of the input schema (.actor/input_schema.json). No field is required, but a run needs at least one source.
| Field | Type | Default | Description |
|---|---|---|---|
startUrls | array | — | Web pages to analyse (plain HTTP, robots.txt respected, no JavaScript). |
texts | array | — | Raw texts, one item per entry. |
documentUrls | array | — | Public links to PDF, DOCX, TXT, MD or CSV files. |
imageUrls | array | — | Public JPEG, PNG, GIF or WebP images (vision). |
includePageImages | boolean | false | Also send up to 3 images of each web page to Claude (about 1,600 input tokens each). Off: images are only listed. |
datasetIds | array | — | Dataset IDs from any Actor run; each row becomes one item. |
datasetFields | array | — | Fields of each row to send (dot notation). Empty = every text and number field. |
task | string | "summarize" | summarize, extract, classify, analyze, detect_key_info, compare, report, custom. |
instructions | string | — | Extra instructions; required for custom. They cannot override the Actor's rules (no invented facts, source treated as data). |
outputSchema | object | — | JSON Schema for extract. Supported keywords: type, properties, required, items, enum, const, anyOf, description, title, format, default. |
labels | array | — | Allowed labels for classify (at least 2). |
multiLabel | boolean | false | classify: every label that applies instead of the single best one. |
language | string | "English" | Language of the texts Claude writes. |
analysisLevel | string | "standard" | quick, standard, deep (effort low / medium / high). |
model | string | "" | "" (= Claude Opus 5.5), claude-opus-5-5, claude-sonnet-5-5, claude-haiku-5-5, claude-fable-5-1. |
estimateOnly | boolean | false | Count tokens and estimate the cost, no analysis call. |
maxCostUsd | number | 0 | Stop before a request whose worst case would take the estimated AI cost above this (USD). 0 = no limit. |
maxTotalTokens | integer | 0 | Same check on tokens (input + output). 0 = no limit. |
maxInputTokensPerItem | integer | 150000 | Longer sources are split into parts (2,000 to 860,000). |
maxOutputTokensPerItem | integer | 0 | 0 = the analysis level's limit (max 128,000). |
maxItems | integer | 100 | Items analysed in this run (1 to 10,000). |
useBatchApi | boolean | false | Use the Message Batches API (50 % cheaper, slower; no server-side refusal fallback in batches). |
batchMaxWaitSecs | integer | 3600 | How long the run waits for a batch before canceling unfinished requests (60 to 86,400). |
concurrency | integer | 3 | Items processed at the same time (1 to 10). |
itemTimeoutSecs | integer | — | Per-item timeout (30 to 3,600). Empty = fits the output limit (see Cost control). |
apiKeyMode | string | "own_key" | own_key (available) or managed (coming soon, not open yet). |
apiKey | string (secret) | — | Your Anthropic API key. |
Output
One dataset row per item (views: Overview, Structured results, Tokens and costs). Fields from .actor/dataset_schema.json:
| Field | Type | Description |
|---|---|---|
source | string | URL of the page / document / image, text #N, or the dataset row. |
sourceType | string | web, text, document, image, dataset or comparison. |
task | string | Task run on the item. |
model | string | Claude model requested. |
servedBy | string | Model that produced the answer (differs only when a refusal fallback answered). |
analysisLevel | string | quick, standard or deep. |
effort | string | Effort setting used (low, medium, high). |
title | string | Real title of the source, else the one Claude wrote. |
summary | string | Summary written by Claude. |
keyPoints | array | Key points, one sentence each. |
result | object / array / string | Task result (extracted JSON, findings, sections, answer, comparison). |
labels | array | classify: {label, confidence, confidenceSource, basis}; labels without a basis are dropped. |
confidence | number | Highest label confidence, as reported by the model (not computed by the Actor). |
entities | array | People, organisations, products, places {name, type}. |
importantInfo | array | Risks, deadlines, amounts, dates, contacts, obligations {kind, text}. |
language | string | Language of the source (ISO 639-1), detected by Claude. |
outputLanguage | string | Language requested for the output. |
images | array | Up to 3 real image URLs from the source (nothing generated). |
tokens | object | {input, cachedInput, output} as reported by Claude (output includes thinking). |
costUsd | number | Estimated AI cost at Anthropic list prices. |
billedEvents | object | Apify pay-per-event events charged for this item. |
durationMs | integer | Processing time of the item. |
truncated | boolean | True when part of the source or the answer could not be used. |
truncationReason | string | Why. |
chunks | integer | Number of parts when a long source was analysed in parts. |
stopReason | string | Claude stop_reason (end_turn, max_tokens, refusal). |
refusalCategory | string | Refusal category reported by Claude when it declined. |
keyMode | string | own_key or managed. |
batchApi | boolean | Processed through the Message Batches API. |
estimate | object | estimateOnly: input tokens, method (count_tokens or heuristic), typical / worst-case cost. |
members | array | compare: the sources compared. |
warnings | array | Notes about this item (long source split, fallback, schema mismatch…). |
error | string | Why the item has no analysis. |
errorCode | string | Short error code. |
analyzedAt | string | ISO date-time of the analysis. |
The run's key-value store also holds REPORT (visual page: cards, tables for extracted JSON, comparison table, run stats, errors panel), RUN_SUMMARY and FAILED_INPUTS.
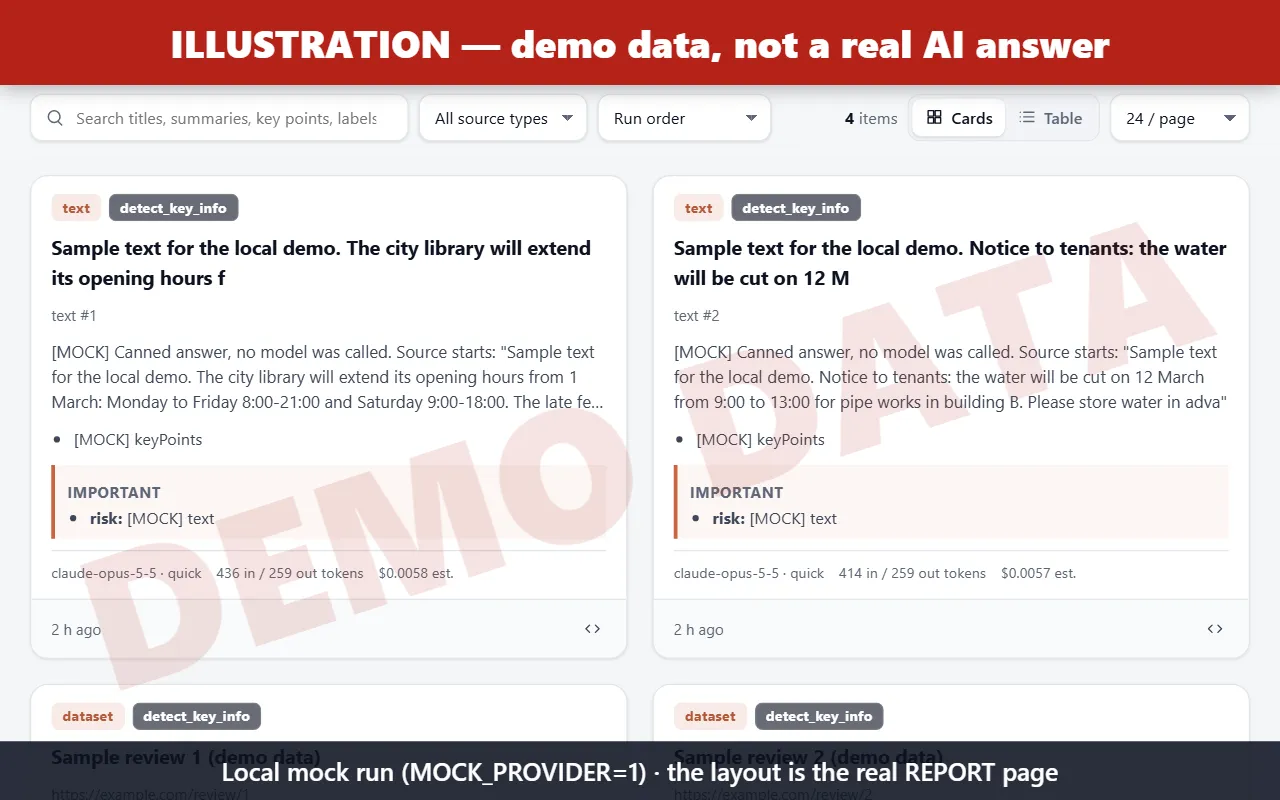
Illustration — demo data, not a real AI answer. Screenshot of the real REPORT page layout, rendered from a local mock run (MOCK_PROVIDER=1): every text marked [MOCK] is canned, no model was called.
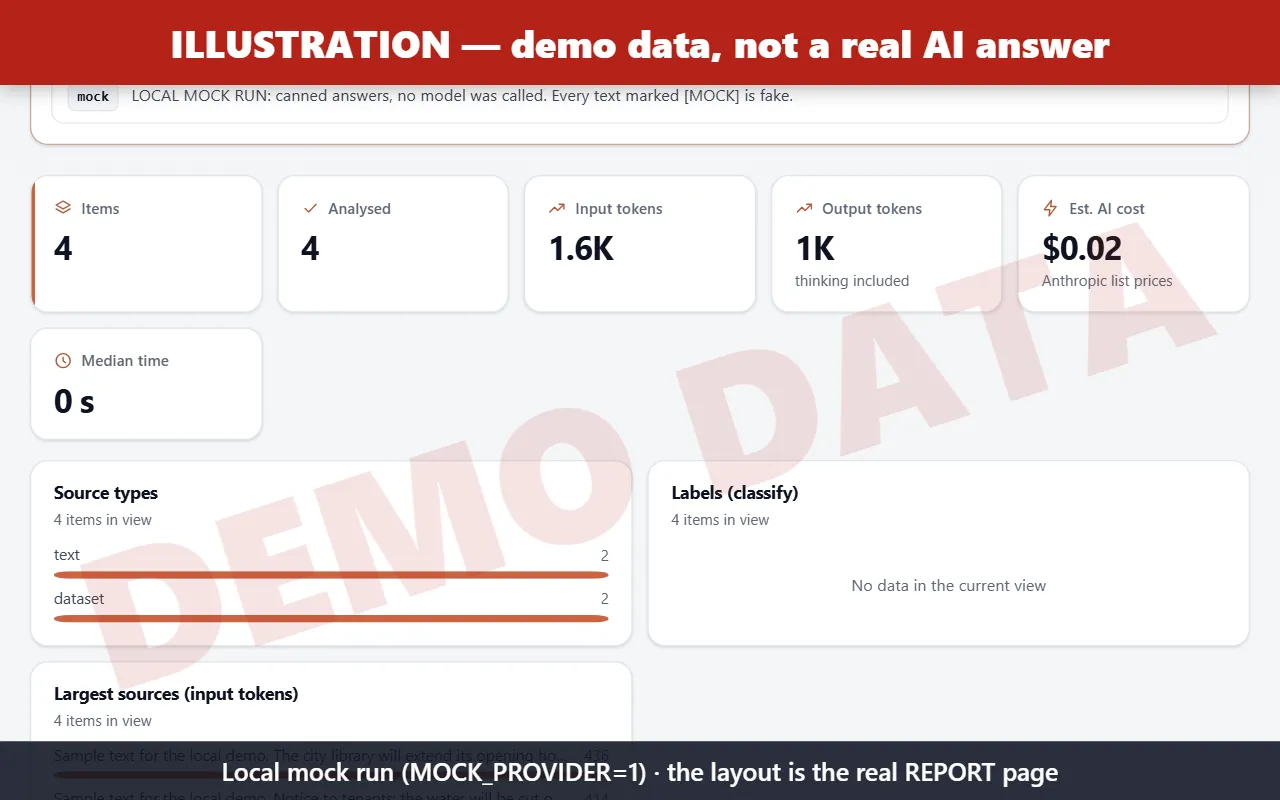
Illustration — demo data, not a real AI answer. Run statistics and charts of the same local mock run.
Examples
Summarize a few pages, cheapest settings:
Extract invoice data from PDFs to your schema:
Classify reviews with your labels:
Estimate first, spend nothing:
Integrations: chain it after a scraper
Every Apify Actor writes its results to a dataset. Pass that dataset's ID in datasetIds and choose the fields with datasetFields. The field names below are the real output fields of each scraper.
In the Apify Console (no code): open the scraper (or its task) → Integrations → Connect Actor or task → choose this Actor and use an input such as {"datasetIds": ["{{resource.defaultDatasetId}}"], ...}. Each finished scraper run then starts an analysis of its own results.
Website Content Crawler (apify/website-content-crawler) — summarize every crawled page:
Google Maps Scraper (badr_xba/google-maps-scraper) — segment places with your labels:
LinkedIn Jobs Scraper (badr_xba/linkedin-jobs-scraper) — extract structured requirements:
Amazon Product Scraper (badr_xba/amazon-product-scraper) — compare up to 10 products in one analysis:
Facebook Ads Library Scraper (badr_xba/facebook-ads-library-scraper) — classify ad angles:
From code (apify-client for JavaScript): run a scraper, then analyse its dataset.
Cost control
estimateOnly: counts the input tokens of every item with Anthropic's free token-counting endpoint and estimates the cost per item and in total. No analysis call is made.maxCostUsd(estimate) andmaxTotalTokensper run: checked before every request against a worst case (input plus the full output limit, including a possible refusal-fallback model).maxInputTokensPerItem: longer sources are split into parts, each part is summarised, and the task runs on the combined notes. Never cut silently: anything that still does not fit is markedtruncated: truewith the reason.maxOutputTokensPerItem: a cut answer is retried once with twice the limit, then reported.useBatchApi: the Message Batches API halves the token price for big, non-urgent jobs.- Cheaper models: Haiku 5.5 costs about 1/40 of Opus 5.5 per item for high-volume classification or simple extraction.
itemTimeoutSecsdefaults to the time the item's output limit (×2, for the one retry) needs at a slow 30 tokens/s, plus 60 s. Anthropic bills tokens generated before a timeout, so a short timeout can cost money for nothing; a lower value is kept but warned about.- Pre-call estimates without counting are conservative for non-Latin scripts (CJK, emoji… are counted at 1.5 to 3 tokens per character).
Limits and errors
- Web pages are fetched with one plain HTTP request: no JavaScript, no proxy, no anti-bot bypass, robots.txt respected. For pages that need a browser, crawl them first with Website Content Crawler and pass the dataset.
- PDF: up to 32 MB and 600 pages natively. Beyond that, the extracted text is used (stated in
warnings). compare: 2 to 10 sources, in one request.- 429, 5xx, 529 and network errors are retried with back-off, honouring
retry-after. One failed item never fails the run; it goes toFAILED_INPUTSwith a code (for exampleinvalidInput,emptyDataset,datasetError,timeout). A wrong key stops the run at the first request. - Claude's safety classifiers can decline a request (
stopReason: refusal). On Opus 5.5, Sonnet 5.5 and Fable 5.1 the Actor turns on Anthropic's server-side fallback; a request that is still declined gets a row witherrorand no invented content. Haiku 5.5 has no server-side fallback. - Quality of the AI output: Claude writes it. Check important facts against the source. The Actor computes no score.
Troubleshooting
| Status message / FAILED_INPUTS code | Cause | Fix |
|---|---|---|
"Stopped: Anthropic rejected the API key — nothing was analysed or billed." / invalidApiKey | The key in "Anthropic API key" is wrong, revoked, expired or mistyped. The run stops after the first refused request (no other item is sent), lists every item in FAILED_INPUTS, sets stoppedReason in RUN_SUMMARY and ends FAILED so that schedules and integrations notice it. Only Apify's run start event is charged. | Create or copy a key at https://platform.claude.com/settings/keys and paste it, without spaces or quotes, in the "Anthropic API key" field (apiKey). |
Same message / apiKeyNoAccess | The key is known but has no access (HTTP 403 / permission denied). | Check at https://platform.claude.com/settings/keys that the key's workspace may use the chosen model. |
rateLimited, serverError (or similar) | Rate limit (429) or provider outage (5xx): retried with back-off, never treated as a key error; the other items continue. | Run again later or lower concurrency. |
| No key at all | Not an error: the run is an estimate-only demo (SUCCEEDED, nothing billed). | Add your key to analyse. |
Privacy and security
- Your key is an Apify secret input. It is never logged or written to the output. Key-looking strings are removed from error messages and from every log line, including the traceback of an unexpected crash.
- Source content goes only to Anthropic's API and to this run's own storages. Logs contain ids, sizes and counts, not your content.
- Private, local, link-local and cloud-metadata addresses are refused, after DNS resolution and after every redirect (at most 5 redirects; responses capped at 32 MB). Each host is resolved once per request and the connection goes to the exact IP that passed the check, while the real host name is kept for the
Hostheader and TLS, so a DNS-rebinding answer cannot reach an internal address. - Source content is treated as data: instructions hidden in a page or document are not followed.
- Requests use Anthropic's default data-retention settings. Fable 5.1 requires 30-day retention on the Anthropic organization.
FAQ
Do I need an Anthropic account? Yes, for now: own-key mode is the only mode available. The managed key is coming soon.
Are the answers in the screenshots real? No. The report screenshots come from a local demo run with canned answers, to show the page layout.
Can it read pages behind a login or JavaScript? No. Use a crawler or scraper first, then pass its dataset.
Feedback and reviews
Found a bug, or an output that looks wrong? Please open an issue on the Issues tab, with the run ID if possible. If the Actor saves you time, a short review on the Store helps others find it.
Local development
MOCK_PROVIDER=1 apify run gives canned [MOCK] answers with no API call. Mock mode is ignored on the Apify platform. Tests: python -m pytest tests/ (offline; the Anthropic client is always faked). On local runs, a named local dataset is opened by its folder name (a crawlee 1.11 local-path quirk; the platform is not affected).


