
Greenhouse Jobs Scraper: Workday, Lever + Visa Flags
Pricing
from $1.00 / 1,000 jobs
Greenhouse Jobs Scraper: Workday, Lever + Visa Flags
Greenhouse jobs and Workday jobs scraper, plus Lever, Ashby and 4 more ATSs in one schema. Visa sponsorship, US citizenship, ITAR and clearance flags, salary, remote, job alerts. No login. Export data, run via API, schedule and monitor runs, or integrate with other tools.
Pricing
from $1.00 / 1,000 jobs
Rating
0.0
(0)
Developer

Mohamed Bahaa
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Share
What does Greenhouse & Workday Jobs Scraper do?
Career site job scraper: Greenhouse jobs scraper, Workday jobs scraper and job listing API in one. Every job is flagged for visa sponsorship, US citizenship, ITAR and security clearance, with filters that skip those jobs before you pay.
| What you can extract | Features & integrations |
|---|---|
| 💼 Job basics: title, company, department, team | 8 ATSs, one schema: board URLs, careers pages or company slugs |
| 📍 Location: locations, remote flag, employment type | Filters: keywords, departments, locations, remote only |
| 💰 Salary range: when the board publishes one | Skip before you pay: drop no-sponsorship or clearance jobs |
| 📅 Posted date & apply URL: link straight to the application | Only new jobs: daily job alerts with posted-within filter |
| 📝 Description: plain text and Markdown | Scheduling: run it hourly, daily or weekly with Apify schedules |
| 🛂 Visa sponsorship flag: offered or not offered, with the evidence sentence | Export anywhere: JSON, CSV, Excel, XML or HTML from the dataset |
| 🇺🇸 Citizenship / ITAR / clearance flags: each with the sentence it came from | API & SDKs: Apify REST API plus JavaScript and Python clients |
| 🏢 Source ATS: Greenhouse, Lever, Ashby, Workday and 4 more | AI agents (MCP): call it from Claude or other agents via Apify's MCP server |
Try it free in 1 click: open this ready-made example and press Start. Apify's free plan includes $5 of usage every month, no credit card needed. The Input example below returned 16 records and costs about $0.02 at list price.
It is a jobs scraper that pulls job postings straight from company career boards, then flags each job for visa sponsorship, US citizenship, ITAR and security clearance.
- Greenhouse jobs scraper, Lever jobs scraper, Ashby jobs scraper and Workday jobs scraper, plus Workable, SmartRecruiters, Recruitee and Personio, all in one normalized schema
- One job API across 8 ATSs: instead of calling and parsing each board's own API yourself, you send board URLs, careers pages or bare company slugs (
stripe,ramp,notion) and get one format back - Visa sponsorship jobs filter:
workAuthorizationon every job (sponsorshipoffered/not_offered, US citizenship, US person / ITAR, export control, security clearancerequired/preferred) with theevidencesentence.excludeNoSponsorshipandexcludeCitizenshipOrClearancedrop those jobs before they are charged. In our test on 6 boards, 19 of 72 engineering jobs were dropped by those switches - Workday career sites: paste a
*.myworkdayjobs.comURL (NVIDIA, Target, CrowdStrike, Workday…) and get the same clean schema, with full description, exact post date and every location - Auto-detect: a bare company slug is matched to the ATS the company uses (Workday needs its careers-site URL). Careers-page detection: paste
https://ramp.com/careersand it finds the linked or embedded board - Salary / compensation: structured pay from Ashby and Lever, plus pay ranges found in the description text for Greenhouse and others (
compensation.sourcetells you which) - Job alerts with only new jobs: turn on
onlyNewJobsand scheduled runs return just the openings you haven't seen yet, so you only pay for new jobs - Filters: title keywords (include and exclude), location contains, remote only, department/team, posted within N days, max jobs per company
- No duplicates: the same job reached through two inputs (say
stripeandboards.greenhouse.io/stripe) is saved once - No login, no browser, no proxies: uses each ATS's public JSON job-board API and runs in 256 MB, with retries, backoff and polite per-host rate limiting
- LLM- and AI-agent-ready: descriptions as clean Markdown, callable through the Apify MCP server
The work-authorization flags come from plain-text rules on the job description, not AI, so check evidence before you rely on a flag. Jobs without a description get workAuthorization: null.
What data can Greenhouse & Workday Jobs Scraper extract?
🏷️ type: job or error | 🧩 ats: Which ATS the board runs on | 🏢 company: Company name |
🔤 companySlug: Company slug on the ATS | 🆔 jobId: The ATS's own job ID | 💼 title: Job title |
🗂️ department: Department | 👥 team: Team | 📍 location: Main location |
🗺️ locations: Every listed location | 🌍 country: Country when the ATS gives one | 🏠 remote: Remote flag (true/false) |
🏢 workplaceType: On-site, hybrid or remote, as the ATS says | ⏱️ employmentType: Full-time, contract and so on | 💰 compensation: Salary range: summary, min, max, currency, interval, source |
📅 postedAt: Date posted | 🔄 updatedAt: Last updated, when given | 🔗 jobUrl: Job page |
✅ applyUrl: Direct apply link | 📋 boardUrl: The company's job board | 📝 descriptionText: Description as plain text |
🧾 descriptionMarkdown: Description as Markdown | 🧱 descriptionHtml: Original HTML (with includeHtml) | 🕒 scrapedAt: When it was scraped |
🛂 workAuthorization.sponsorship: Visa sponsorship: offered, not_offered or null | 🇺🇸 workAuthorization.usCitizenshipRequired: US citizenship required | 🛡️ workAuthorization.usPersonRequired: US person / ITAR required |
📦 workAuthorization.exportControlled: Export-controlled role | 🔐 workAuthorization.securityClearance: Clearance: required, preferred or null | 🔎 workAuthorization.evidence: The sentences each flag came from |
How to use Greenhouse & Workday Jobs Scraper in 5 steps
- Create a free Apify account.
- Open Greenhouse & Workday Jobs Scraper.
- Add your input: board URLs (
https://boards.greenhouse.io/stripe,https://nvidia.wd5.myworkdayjobs.com/NVIDIAExternalCareerSite), careers pages or slugs likenotion, plus optional filters. Need visa sponsorship, or can't hold a clearance? Switch on Skip jobs that say no visa sponsorship and/or Skip jobs that need US citizenship, US-person (ITAR) status or a clearance. For alerts, switch on Only new jobs since last run. - Click Start.
- Download the results as JSON, CSV or Excel (or use the API), or schedule the run daily so each run brings only the new openings.
Input
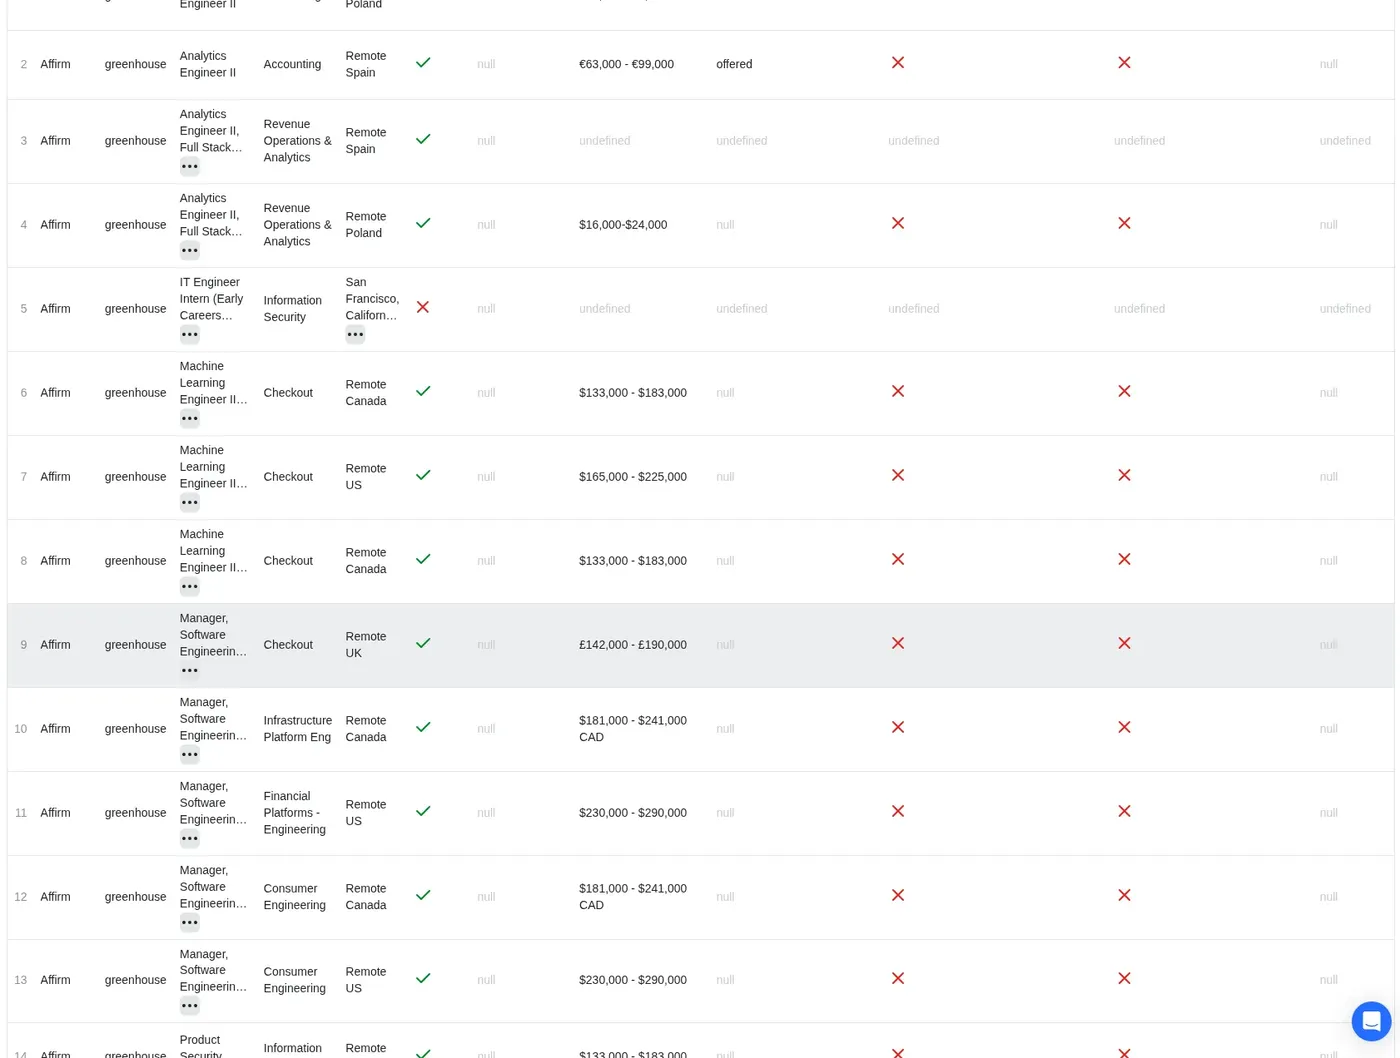
This exact input was run on Oct 19 2026 (256 MB): one real Greenhouse board and one board that doesn't exist, to show both a job and an error item. Paste it into the Input tab (JSON view) and click Start.
Ready-made example Tasks (open one and click Start):
- Find remote frontend jobs at top startups
- Track new engineering jobs posted this week
- Benchmark product manager salaries from job boards
- Scrape Workday jobs from a company career site
- New job alerts from company career pages
Supported inputs
| ATS | Accepted formats |
|---|---|
| Greenhouse | boards.greenhouse.io/stripe, job-boards.greenhouse.io/airbnb, .../jobs/<id>, embed ?for=<slug>, ?gh_jid=<id> |
| Lever | jobs.lever.co/spotify, jobs.lever.co/<slug>/<postingId>, jobs.eu.lever.co/<slug> |
| Ashby | jobs.ashbyhq.com/ramp, jobs.ashbyhq.com/<slug>/<jobId> |
| Workable | apply.workable.com/<slug>, apply.workable.com/<slug>/j/<shortcode>, <slug>.workable.com |
| SmartRecruiters | jobs.smartrecruiters.com/<CompanyId>, careers.smartrecruiters.com/<CompanyId> |
| Recruitee | <slug>.recruitee.com, <slug>.recruitee.com/o/<offer> |
| Personio | <slug>.jobs.personio.de, <slug>.jobs.personio.com, .../job/<id> |
| Workday | <tenant>.wd5.myworkdayjobs.com/<Site> (any wdN, with or without /en-US/), .../job/<location>/<title>_<id>, wd1.myworkdaysite.com/recruiting/<tenant>/<Site> |
| Any except Workday | bare slug, e.g. stripe, notion, Ubisoft2 (tries Greenhouse → Lever → Ashby → SmartRecruiters → Workable → Recruitee → Personio) |
| Company site | a careers page URL such as https://ramp.com/careers (scanned for a linked or embedded board, including Workday) |
Input fields
| Field | Description |
|---|---|
companies | Board URLs, job URLs, careers pages or bare slugs (required) |
keywords / excludeKeywords | Title must contain any keyword / none of the excluded ones (case-insensitive) |
locations | Any location of the job contains any of these strings |
remoteOnly | Only jobs flagged remote |
departments | Department or team contains any of these |
postedWithinDays | Only jobs first published in the last N days (0 = any) |
maxJobsPerCompany | Cap per company after filters (default 500, 0 = no limit) |
includeDescription | Description as descriptionText + descriptionMarkdown (default on) |
includeHtml | Also keep the original description HTML |
atsToTry | Which ATSs to try for bare slugs, in order |
detectFromCareerPage | Scan non-ATS URLs for an embedded board (default on) |
excludeNoSponsorship | Skip jobs whose description says visa sponsorship is not available |
excludeCitizenshipOrClearance | Skip jobs that need US citizenship, US-person (ITAR) status or a security clearance |
onlyNewJobs | Output only jobs not returned by an earlier run with the same memory (default off). The first run returns everything and saves the baseline |
stateKey | Optional name for that memory, e.g. frontend-alerts. Empty = one memory per company list |
Output
Every record has a type: job or error. A real record from the run above (description shortened):
A clearance example from an earlier test run (SpaceX board, Oct 18 2026, trimmed):
You can download the dataset as JSON, CSV, Excel, XML or HTML.
How can I use the data?
- Job aggregation: build a niche job board (remote, AI, climate, frontend, startups) from hundreds of company boards
- Visa sponsorship job search: keep only jobs that don't rule out sponsorship, or that need no clearance
- HR tech and recruiting: hiring signals, competitor hiring trends, headcount by department and location
- Sales intelligence: find companies hiring for roles that signal they need your product
- Salary research: collect pay ranges for a role across companies
- AI agents and job-search copilots: feed fresh, structured postings to an LLM to match candidates to jobs
- Personal job search: watch your dream companies on a schedule and get only new matching roles
More Actors from the same developer
| Actor | What it does |
|---|---|
| Telegram Channel Scraper | Public Telegram channel posts with a keyword monitor and only-new mode |
| Substack Scraper | Substack newsletters to clean Markdown, plus podcast transcripts |
| App Store & Google Play Reviews Scraper | Reviews from both stores in one run, only new reviews on schedules |
| Website to Markdown Crawler | Any website to Markdown for RAG, with incremental sync and llms.txt |
| Government Bids & RFP Scraper | Open bids and RFPs from 500+ US city and county portals on OpenGov |
| State Bids Scraper | Open bids from COMMBUYS, BidBuy, NJSTART, OregonBuys and NevadaEPro |
| PERM Green Card Sponsors | Companies that sponsor green cards, from official DOL PERM data |
Error items
The run never silently returns nothing for an input: every input that can't be scraped gets one record with type: "error". The real error item from the run above:
Fields: type, input, error, errorMessage, scrapedAt, plus ats and companySlug when known, or tried (the ATSs checked) for bare slugs.
error | When |
|---|---|
BOARD_NOT_FOUND | No public board (or job) found for that URL or slug |
NO_OPEN_JOBS | The board exists but has no open jobs right now |
JOB_NOT_FOUND | A job URL whose job is not open on that board |
UNSUPPORTED_URL | Not a supported job board, and no board was found on the page |
FETCH_FAILED | A request failed, a page couldn't be loaded, or an unexpected error |
Filter them out with type = job. Error items are charged as dataset items (one per failed input). A RUN_SUMMARY record in the key-value store gives boards, jobs, errors, duplicatesSkipped, skippedSeenBefore and droppedByWorkAuthFilter. If the run reaches your maximum cost per run, it stops cleanly and logs it (no error item).
Tips
- Company slugs can differ from the company name (
palantiron Lever,Ubisoft2on SmartRecruiters). If a bare slug isn't found, paste the board URL or the company's careers page. - For daily monitoring, schedule the actor with
onlyNewJobs: trueand your keywords: every run returns only openings it hasn't returned before. The memory lives in your own key-value store namedats-jobs-scraper-state; delete a key there (or changestateKey) to start fresh. - Workday's list only says "3 Locations" for multi-location jobs. Keep
includeDescriptionon (the default), or use a location filter, and the actor opens each kept job to fill in every location and the exact post date. Workday's public list shows at most 2,000 jobs per site, so add a keyword for very large employers. - With exactly one keyword, SmartRecruiters is searched server-side, so even 5,000-job boards stay fast.
- Workable rate-limits aggressive traffic; the actor backs off automatically and reports
FETCH_FAILEDonly if Workable keeps refusing.
FAQ
How much does it cost? Pay per event, no subscription: $0.001 per job saved to the dataset (error records are charged as dataset items too, one per failed input) and $0.00005 per run start. 1,000 jobs ≈ $1. Platform usage is included, so you don't pay compute on top. Set a maximum cost per run and the Actor stops cleanly when it's reached. See the Pricing tab.
Which integrations work? Any Apify integration: Make, Zapier, n8n, Google Sheets, Slack, webhooks, or schedules that run it hourly, daily or weekly.
Can I call it from the API? Yes. Node.js with apify-client:
Python with apify-client:
Can I use it from an AI agent (MCP)? Yes. Add it to Claude or another MCP client through the Apify MCP server (https://mcp.apify.com?actors=chimey_forearm/ats-jobs-scraper). Output is flat JSON with Markdown descriptions, ideal for LLM tools.
Does it support Workday? Yes. Paste the company's Workday careers-site URL (for example https://nvidia.wd5.myworkdayjobs.com/NVIDIAExternalCareerSite); it uses Workday's public JSON endpoint, no browser. Bare slugs can't be guessed for Workday because each company picks its own site name. iCIMS and Taleo are not supported.
How does "only new jobs" work? The Actor saves the IDs of jobs it returned in a key-value store in your Apify account. The next run with the same company list (or the same stateKey) skips those IDs, so you only get, and only pay for, new postings. Changing filters can surface jobs that were filtered out before, as "new".
How do the visa / citizenship / clearance flags work? The Actor reads each job description for phrases like "visa sponsorship is not available", "unable to sponsor", "must be a US citizen", ITAR "US person" rules and "active TS/SCI clearance". Clearance mentioned as "beneficial" or "preferred" is marked preferred and is not dropped by the filter. It is rule-based text matching, not AI, so it can miss unusual wording; every flag carries the sentence it came from in evidence. Jobs without a description (for example Lever or Workday with includeDescription: false) get workAuthorization: null and are never dropped. Greenhouse descriptions are always read, so Greenhouse jobs are flagged even with descriptions turned off.
Is it legal? It reads public job-board data that companies publish for job seekers and aggregators through official public APIs. No login. Follow the terms of the sites you use and local law. Our Actors are ethical and do not extract any private user data, such as email addresses, gender, or location. They only extract what the user has chosen to share publicly. However, your results could contain personal data, which is protected by the GDPR in the European Union and by other regulations around the world. You should not scrape personal data unless you have a legitimate reason to do so. If you're unsure whether your reason is legitimate, consult your lawyers.
Found a bug or need a field? Open an issue in the Issues tab and I'll usually reply within a day.
If it saved you time, a quick review on the Store helps a solo developer keep improving it. Bugs or ideas? Open an Issue.


