
Google Trends Scraper & API
Pricing
from $0.80 / 1,000 term results
Google Trends Scraper & API
Google Trends API alternative for any number of terms: interest over time by country, region, city or metro, related queries and topics, Trending Now, and calibrated comparisons beyond 5 terms. Daily data across years. Compact JSON for AI agents.
Pricing
from $0.80 / 1,000 term results
Rating
0.0
(0)
Developer
CleanPull
Maintained by CommunityActor stats
0
Bookmarked
3
Total users
2
Monthly active users
2 days ago
Last modified
Categories
Features
Share
This Google Trends scraper gets Google Trends data for any number of search terms in one run: interest over time, interest by country, region, city or metro area, related queries, side-by-side comparisons, and Trending Now with search volumes. Rank more than 5 terms on one calibrated scale, and get daily points across multi-year ranges. Clean, typed JSON or flat rows, built for AI agents and data teams; run it once, on a schedule or through the API.
How to scrape Google Trends
- Open Google Trends Scraper & API on Apify and go to its input form.
- Pick a Mode: Explore for each term's data, Calibrated comparison to rank many terms on one scale, or Trending Now.
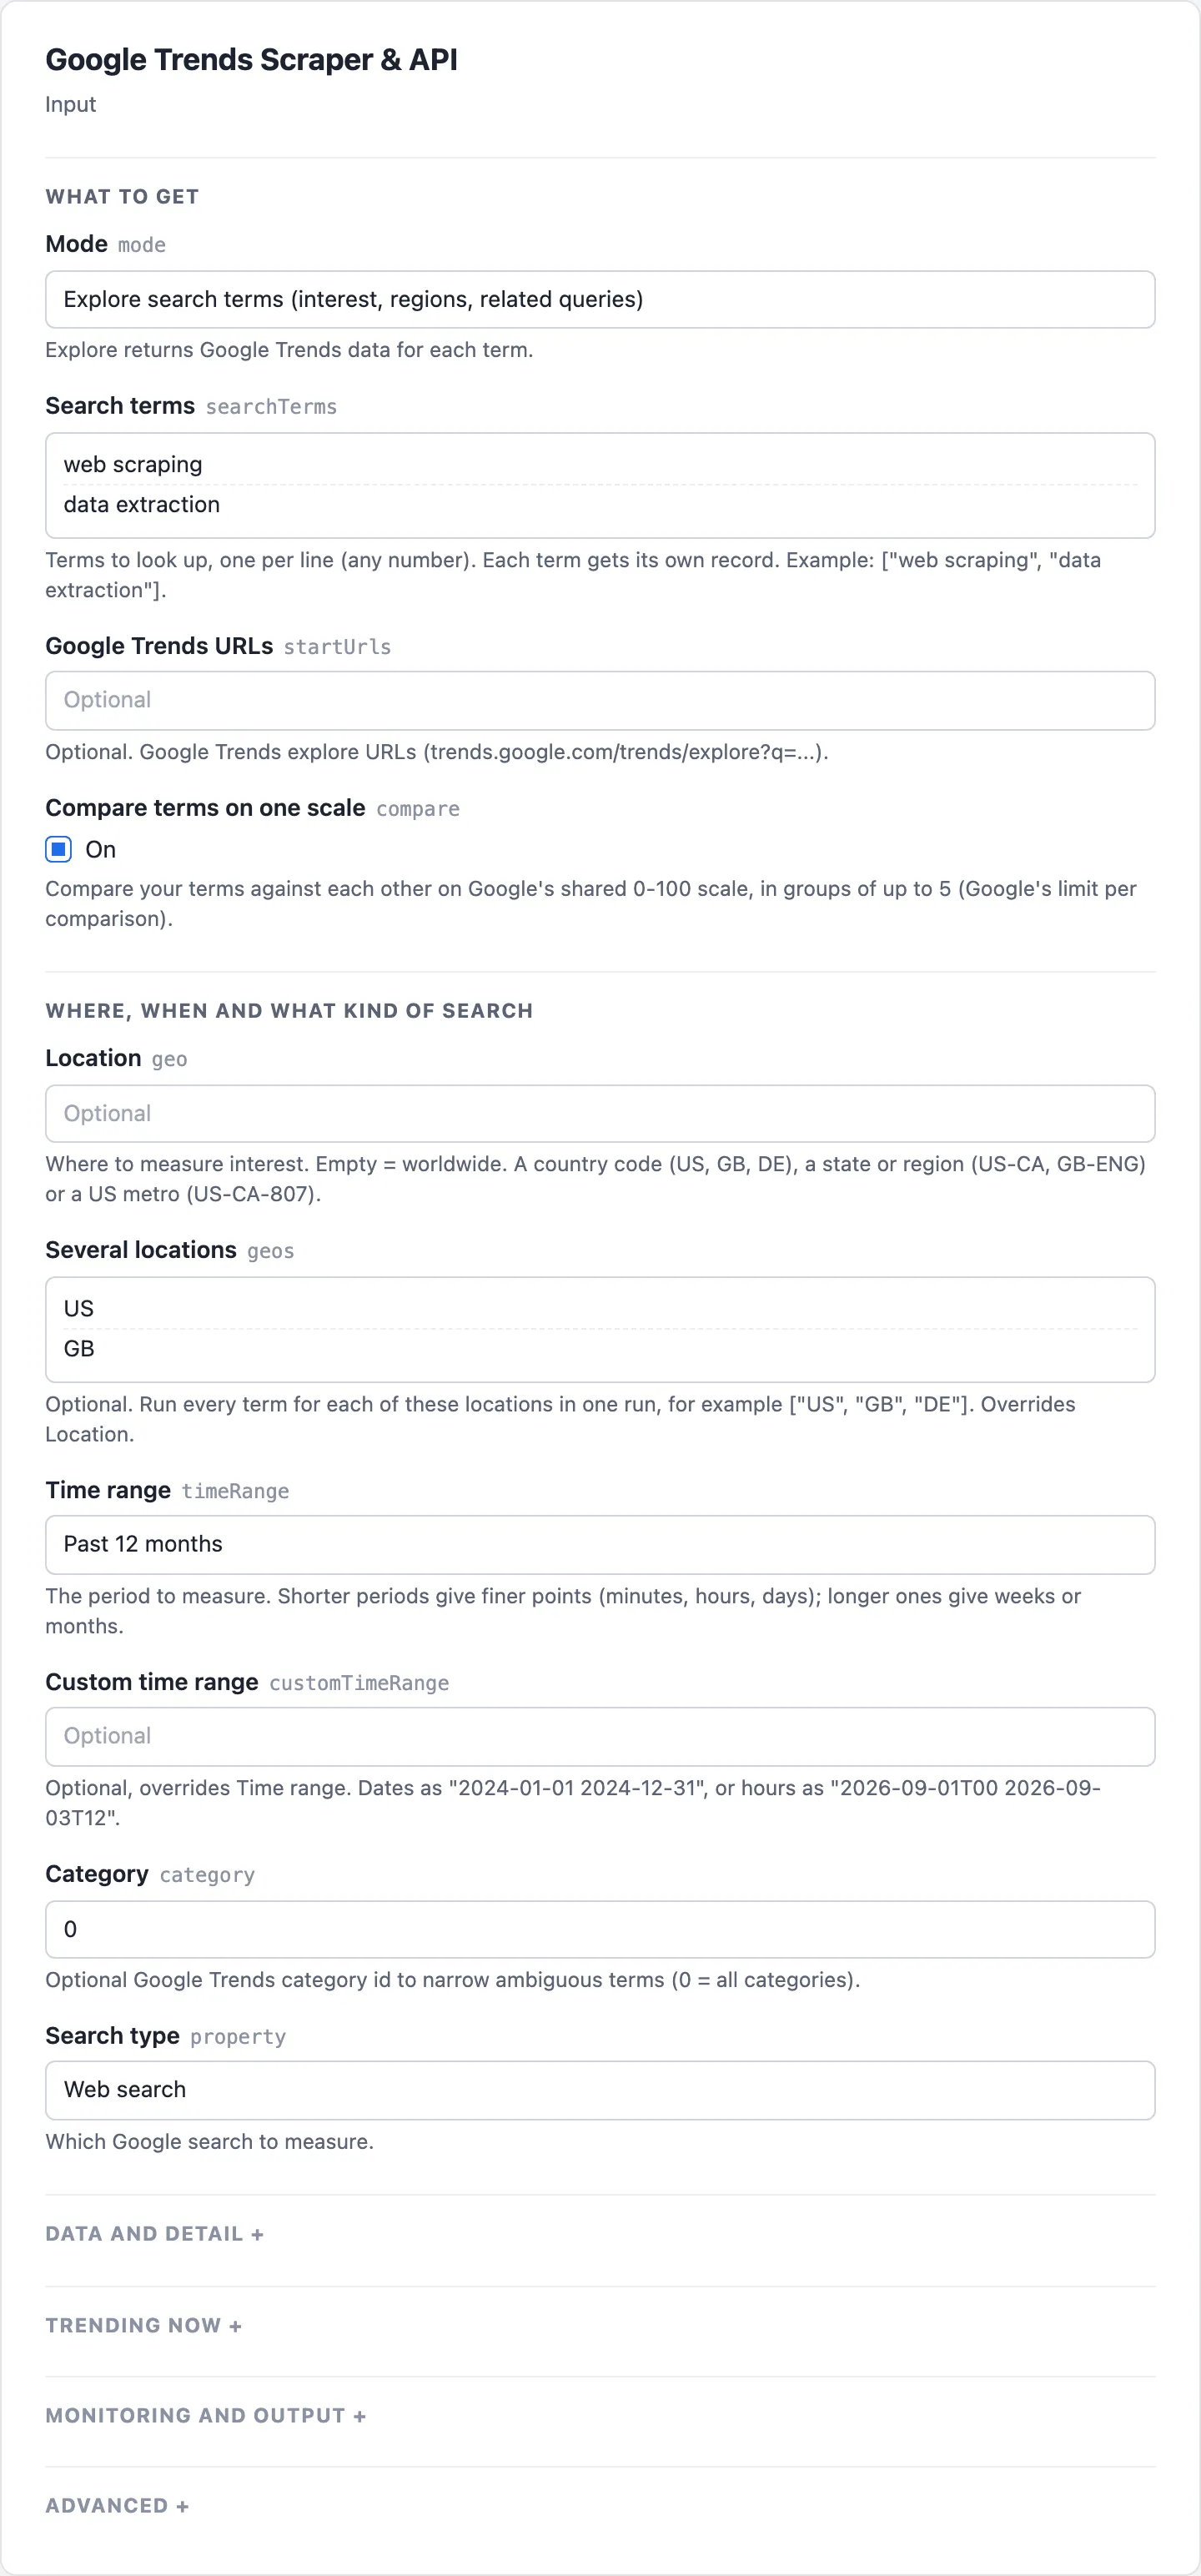
- Enter words in Search terms, one per line, or paste links in Google Trends URLs. Turn on Compare terms on one scale to see them side by side.
- Set Location (or Several locations), Time range and Data to collect; turn on Daily points for long ranges for one point per day across years.
- Start the run. Open the Term overview view to read each term's Summary and Average interest, the Calibrated ranking view for Relative interest with its Low and High bounds, or the Trending Now view for Searches and Growth %.
- To follow new rising queries or new trends, turn on Monitor mode, give it a Monitor name, save it as a task and schedule it daily.
What the Google Trends scraper gives you
- Track a keyword portfolio: "Get Google Trends interest for these 50 keywords in the US over the past 12 months."
- Rank many terms against each other: "Which of these 30 product names gets the most searches?" Calibrated comparison puts every term on one 0-100 scale with error bounds, beyond Google's 5-term limit.
- Compare across countries: "How does interest in electric cars compare in the US, UK and Germany?" One run, any number of locations.
- Find rising topics: "What related searches are breaking out around web scraping?" Rising queries are flagged with
isBreakout. - Watch what is trending: "What is trending in the UK in sports right now?" Hundreds of trends with search volume, growth and start time, not just the top 10.
- Monitor on a schedule: Monitor mode returns only new trends or new rising queries since the last run.
- Feed an AI agent or dashboard: choose only the fields you need, or get one flat row per data point.
Google Trends data accuracy
- Reliable and fast. Plain HTTP requests with automatic session rotation and proxy escalation; no browser, no hanging runs. A blocked data type is reported in
missingDataTypesinstead of failing the run. - Every data type in one record per term, plus a computed
summary: average, peak and date, latest value, change in percent and direction (rising, falling, stable), andlowVolumewhen Google had too few searches to report at least one week (or day) in five. - Calibrated comparison of any number of terms with low and high bounds, so you know how precise each value is.
- Daily points for long ranges. Google returns weekly or monthly points beyond about 9 months; turn on Daily points for long ranges for one point per day across years.
- Field names that follow Google Trends' own data (
interestOverTime_timelineData,interestBySubregion,relatedQueries_risingand so on), the same in every run. - Built for AI agents: typed inputs with defaults and examples, a declared output schema,
fieldsselection, and aRUN_SUMMARYwith the outcome of every lookup. Works through Apify's MCP server.
Google Trends scraper modes
| Mode | What you get | Billed per |
|---|---|---|
explore (default) | One record per term (and per location): interest over time, by region, related queries, optional topic suggestions; with Compare terms on one scale, an extra comparison record per group of up to 5 terms | Term record, comparison record |
calibrated-comparison | One record per term with its rank, relativeInterest (largest term = 100), low and high bounds, and its time series on the shared scale | Calibrated term |
trending | Trending Now for a country: term, search volume, growth percent, start and end time, active flag, categories, related searches | Trending item |
Google Trends scraper input
| Field | Key | What it does |
|---|---|---|
| Mode | mode | explore, calibrated-comparison or trending (default explore) |
| Search terms | searchTerms | Terms to look up, one per line, any number |
| Google Trends URLs | startUrls | Explore URLs; terms, locations, period, category and search type are read from each |
| Compare terms on one scale | compare | Compare terms on one scale in groups of up to 5, with a comparison record |
| Location | geo | US, GB, US-CA, GB-ENG or a US metro such as US-CA-807; empty = worldwide |
| Several locations | geos | Run every term for each location, e.g. ["US", "GB", "DE"]; overrides Location |
| Time range | timeRange | Preset period, past-hour … all-time (default past-12-months) |
| Custom time range | customTimeRange | "2024-01-01 2024-12-31" or hourly "2026-09-01T00 2026-09-03T12"; overrides Time range |
| Category | category | Google Trends category id (0 = all) |
| Search type | property | web, images, news, youtube or shopping |
| Data to collect | dataTypes | interestOverTime, interestByRegion, relatedQueries, relatedTopics, suggestions |
| Region detail | regionResolution | auto, country, region, city or metro |
| Include low-volume regions | includeLowVolumeRegions | Include regions Google hides for low volume |
| Daily points for long ranges | dailyResolution | Daily points across ranges longer than about 9 months (one extra request per 7 months of range) |
| Trending country | trendingGeo | Country for Trending Now (default US) |
| Trending window | trendingHours | How far back Trending Now looks: 4, 24, 48 or 168 hours (default 24) |
| Trending categories | trendingCategories | Only trends in these categories |
| Active trends only | trendingActiveOnly | Only trends that are still rising (not ended) |
| Max trending items | trendingMaxItems | How many trends, highest volume first (default 100; 0 = all Google lists) |
| Monitor mode | monitorMode | Only new trends or new rising queries since the last run with the same monitor name |
| Monitor name | monitorName | Keeps separate memories for separate monitors (default default) |
| Output format | outputFormat | nested (one record per term) or flat (one row per date, region or related query) |
| Fields to return | fields | Return only these fields (dotted paths allowed, such as summary.average) |
| Max results | maxItems | Stop after this many billed results (default 1,000); caps the cost of a run |
| Language | language | Language for names and labels, such as en-US or de |
| Timezone offset (minutes) | timezone | Minutes west of UTC for hourly data (0 = UTC, 300 = New York in winter) |
| History store | stateStoreName | The key-value store Monitor mode remembers in (default: its own store, cleanpull-monitor); pick one when you run with a scoped API token |
Example inputs
Two terms compared in the US and the UK over the past 12 months, with interest by region and related queries:
Twelve terms ranked on one scale in the US:
New UK trends in sports since the last run (schedule it hourly or daily):
Google Trends scraper output
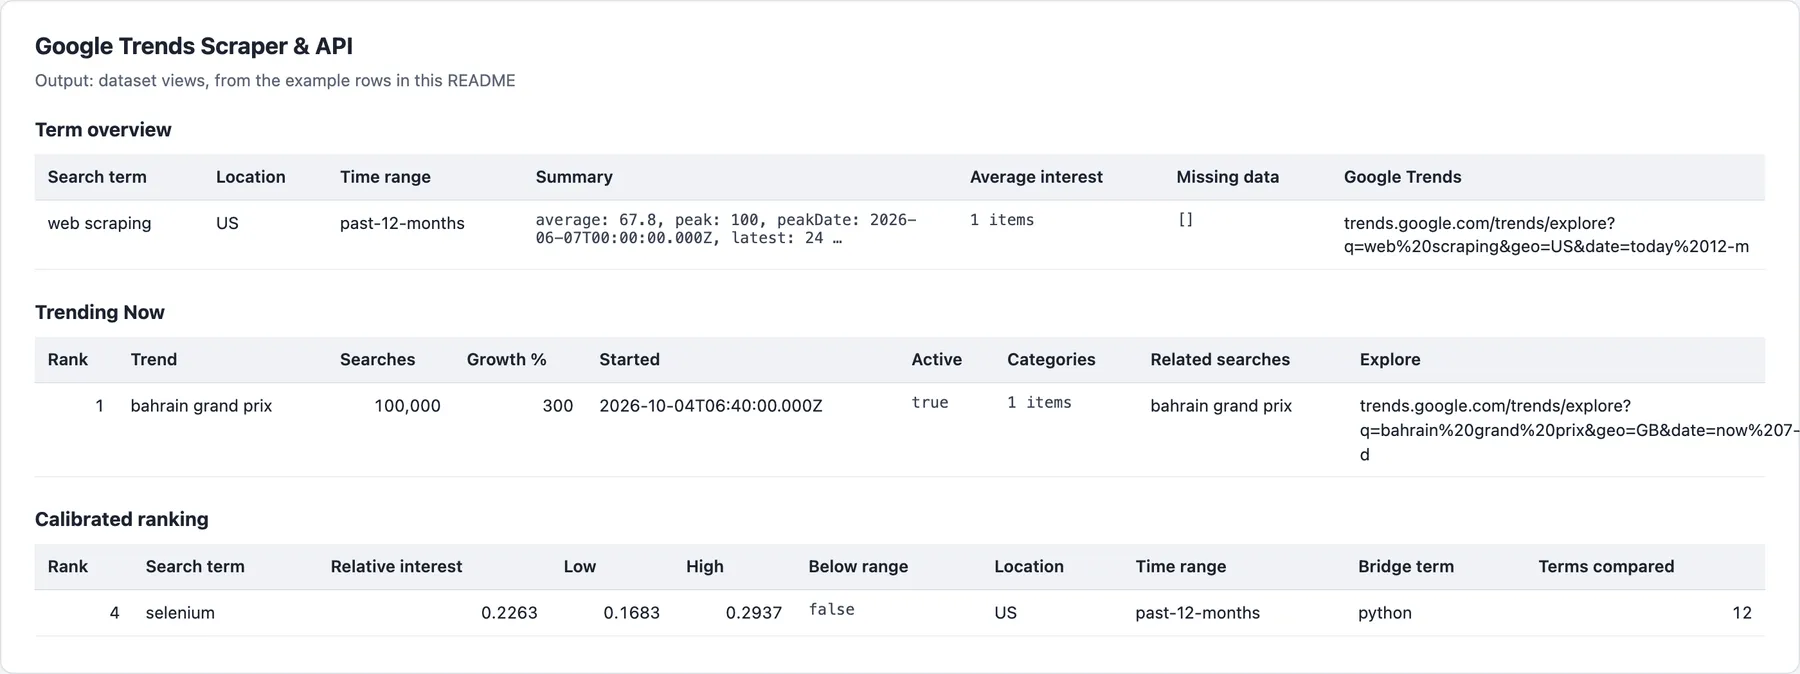
Records carry type: term, comparison, calibrated-term or trending.
Term record (explore mode, shortened)
Calibrated term
An illustrative calibrated record (values not from a real run). Each calibrated record also carries timeline: the term's series rescaled onto the shared scale (left out here).
Trending item
Run summary and status message
Every run also writes RUN_SUMMARY to the key-value store: the outcome (COMPLETE, PARTIAL, NO_NEW_DATA, EMPTY or FAILED), counts, and the reason for any failed lookup.
The run's final status message summarises the key numbers in plain text: each term's direction, change, peak with its date and latest value, the comparison's averages and the top rising searches ("Done: 2 results. "phone stand" (US): rising +42%, peak 100 on 2022-12-04, latest 63 on 2026-11-01 …"), ending "More in the dataset." when not everything fits.
Google Trends calibrated comparison
Google compares at most 5 terms at a time, each group on its own 0-100 scale rounded to whole numbers. The actor first sizes every term against one anchor, then chains groups from the most popular term down, each group sharing a "bridge" term with the previous one and holding only terms of similar size, so no value is lost to rounding. Bounds carry Google's rounding through the chain: a niche term 30,000 times smaller than the top one still comes back with a value and a range.
Pricing
Pay only for results delivered. Blocked or failed lookups are never charged.
| Result | Free and Bronze | Silver | Gold |
|---|---|---|---|
| Term record (all requested data types for one term and location) | $1.00 | $0.90 | $0.80 |
| Comparison record | $1.50 | $1.30 | $1.10 |
| Calibrated term | $10.00 | $9.00 | $8.00 |
| Trending item | $1.00 | $0.90 | $0.80 |
Prices are per 1,000 results; your tier depends on your Apify plan. Each run also has a $0.00005 start fee.
Flat mode is billed per term record, not per row.
Limits
- Related topics are returned only when Google provides them to logged-out visitors, which is often not the case. When they are missing, the record says so in
missingDataTypes. - Google Trends values are relative (0-100), not absolute search counts. Trending Now volumes are Google's own approximate figures.
- Low-volume terms: Google reports a week (or day) only when enough people searched; the rest come back without data, drawn as 0. The summary and the average count them as 0, as Google's own averages do; the in-progress point counts only once Google reports it.
pointsWithoutDatasays how many complete points were unreported, andlowVolume: truemarks a term with at least one in five unreported (ordinary terms miss only a stray day). A term Google reported nowhere has no average (interestOverTime_averagesis[]); its term record is still delivered and billed. Change and direction run from the first reported point, so a term that only appears later is not called rising from nothing; a term unreported for the whole first quarter that now holds at least half its peak is a breakout (direction: rising, no percent), and fewer than 4 reported points give no change or direction. On a term near that threshold, peaks, dates and rising queries rest on a small sample and can be noise. Each term is scaled to its own peak, so two niche terms can show similar numbers; compare them with Compare terms on one scale to see their real sizes (it keeps which weeks Google left unreported). - Calibrated values are only as precise as their bounds; terms far apart in popularity have wider bounds.
- Memory: explore runs fit in 512 MB at any size tested (2,000 terms); calibrated comparisons of up to about 500 terms fit in 512 MB (5 years of daily points), larger ones need the default 4,096 MB.
- No data for a term: in Explore mode, a term Google has no interest data for is still delivered as a term record and billed like any other, with the types Google did not give in
missingDataTypes(andinterestOverTime_averagesempty). In Calibrated comparison mode, a location where Google gives no interest data for the terms is a miss: when the whole run delivers nothing, the run still succeeds with one freerecordType: "unreadable"row per location giving thereason, and nothing is charged; otherwise it is listed inRUN_SUMMARY. Input naming nothing to look up ends with one freeunreadablerow, and nothing is charged. A run near its time limit stops starting lookups, delivers what it read and lists the rest inRUN_SUMMARY. A run whose every lookup Google blocked fails.
FAQ
How much does Google Trends data cost per keyword per day?
A keyword looked up once a day in one location costs $0.001 a day on the Free and Bronze plans (about $0.03 a month), whatever data types you collect: 50 keywords cost $0.05 a day. Each extra location is another term record. Compare terms on one scale adds $0.0015 per group of up to 5 terms, so 50 compared keywords add $0.015. A calibrated comparison costs $0.01 per term ($0.12 for 12 terms), and Trending Now $0.001 per trend ($0.10 for the default 100). With Monitor mode, only term records with new rising queries and new trends are billed, so a day with nothing new costs only the start fee. Monitor mode does not apply to Calibrated comparison: every calibrated term is delivered and billed on every run. Blocked or failed lookups are never charged, Max results caps a run's results, and higher Apify plans pay less (see Pricing above).
How often should I check Google Trends?
Weekly suits most keyword portfolios: over the past 12 months Google gives one point per week. Trending Now changes by the hour, so check it hourly or daily. With Monitor mode and a schedule, each run returns only the trends or rising queries that are new since the last run with the same Monitor name.
What is the difference between a term record, a comparison and a calibrated term?
A term record scales each term to its own peak (100), so it shows the term's shape over time but not its size next to other terms. A comparison record (with Compare terms on one scale) puts up to 5 terms on one shared 0-100 scale, as Google does, with the winner and each term's average. A calibrated term (Calibrated comparison mode) ranks any number of terms on one scale, the largest = 100, with low and high bounds.
Why is a value, a breakout or related topics missing?
- Related topics: Google often does not show them to logged-out visitors; the record lists them in
missingDataTypes. - Low volume: weeks Google did not report count as 0,
lowVolume: truemarks the term, and a term Google reported nowhere has no average (its record is still delivered and billed). - Change and direction: fewer than 4 reported points give no
changePercentordirection. - Comparison in Monitor mode: comparison records are not made in Monitor mode, and a term with no new rising query is left out.
- Calibrated term below range:
belowRange: truemeans Google rounded it to 0 next to the smallest bridge, so only an upper bound is known.
Which countries and regions does it support?
Explore and calibrated comparison take worldwide (empty Location), any country code (US, GB, DE), a state or region (US-CA, GB-ENG) or a US metro (US-CA-807). Trending Now takes any country in the Trending country list. Language sets the language of names and labels.
Can I use the Google Trends scraper through the API?
Yes. Start runs through the Apify API or an API client, and read the dataset through its Term overview, Trending Now and Calibrated ranking views, or the RUN_SUMMARY record with the outcome of every lookup. Fields to return (fields) trims each record to the keys you need, and Output format flat gives one row per date, region or related query.
Does it work with Google Sheets, Make, Zapier or Claude?
Yes. Apify's integrations send each run's results to Google Sheets, Make, Zapier, webhooks and other tools, and a schedule keeps them updated. From Claude, the MarketMage plugin reads Google Trends demand and rising searches when it finds and checks product ideas, in a chat.
Is it allowed to scrape Google Trends?
The actor reads public Google Trends pages as a signed-out visitor sees them: no login, no account and no personal data; Google Trends gives only relative interest and approximate volumes, never who searched. How you use the data, and following the laws and terms that apply to you, is your responsibility. This is not legal advice.
Related actors
Other CleanPull actors for market research:
- Amazon Best Sellers Scraper & Rank Tracker: Amazon Best Sellers, New Releases and Movers & Shakers with rank changes.
- TikTok Shop Scraper & Sales Tracker: TikTok Shop units sold per day, revenue and rising products.
- Ad Library Monitor: competitors' new and stopped ads on Facebook, Google and TikTok.
Use it from Claude
The MarketMage plugin runs these actors from a Claude chat.
Found it useful? A rating on the Store helps others find it.
Changelog
- 0.1.14, status summary (2026-11-06): the final status message now summarises the key numbers after "Done: N results." (each term's direction, change, peak and latest, the comparison, rising searches), so a reader can often skip the dataset read. Prices and events unchanged.
- Price lowered on 5 Nov 2026: a term record now costs $1.00 / $0.90 / $0.80 per 1,000 (Free and Bronze / Silver / Gold), down from $1.50 / $1.30 / $1.10. Other events unchanged.
- 0.1.x, low volume (2026-10-27): a week Google could not report counts as 0 in
summaryand the computed average, matching Google's averages (a term reported in 10 of 52 weeks no longer averages as if searched every week); change runs from the first reported point;summarygainspoints,pointsWithoutDataandlowVolume(one point in five or more unreported); a breakout from below the threshold isrising, and fewer than 4 reported points give no direction; a term Google reported nowhere now hasinterestOverTime_averages[](was[0]). Prices and events unchanged. - 0.1.x, reliability (2026-10-24): runs that find nothing (terms without data, input naming nothing to look up) end SUCCEEDED with a free
unreadablerow saying why, instead of FAILED; custom time ranges and Trends URLs are checked in the input form; a run stops starting lookups before its time limit, never TIMED-OUT. A run whose every lookup Google blocked still fails. Prices and events unchanged. - 0.1 (October 2026): explore, comparison, multiple locations, calibrated comparison of any number of terms, daily points for long ranges, Trending Now, monitor mode, flat output and field selection.


