
Reddit Trending Topics Finder
Pricing
from $10.00 / 1,000 trending topic results
Reddit Trending Topics Finder
Discover what is starting to trend on Reddit. Analyse recent posts across Reddit or selected communities, measure score and comment velocity, cluster repeated themes, and get ranked trending topics with evidence posts, subreddit spread and momentum scores. No Reddit login or API key.
Pricing
from $10.00 / 1,000 trending topic results
Rating
0.0
(0)
Developer
Delowar Munna
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Share
Find what Reddit communities are starting to talk about, not just which individual posts are popular right now. The Actor reads recent posts from Reddit's popular feed, the communities you choose and searches for your seed topics, then measures score and comment velocity, spots breakout posts, groups related posts into topics, and ranks each topic by its momentum and how widely it is spreading. Every topic comes with its evidence posts and plain-language reasons. No Reddit account, cookies or API key needed.
Trending topics, not trending posts.
What it does
- Reads Reddit's own feeds: the popular feed and any community's Hot, Rising, New and Top lists, plus Reddit search for seed topics. Any mix, up to 100 communities and 25 seed topics.
- Analyses each post's momentum: score per hour, comments per hour, and whether it is breaking out compared with its own community.
- Groups related posts into topics from repeated names and phrases in their titles, so "Steam Machine price leak", "Valve confirms Steam Machine launch" and "Is the Steam Machine worth it?" become one topic.
- Scores every topic from 0 to 100, gives it a tier (BREAKOUT, RISING, ACTIVE, WEAK) and a confidence level, and lists the signals behind the score.
- Returns one row per topic, ranked, with the posts that support it nested inside.
- Writes a run summary and a per-source status record, so you can see what was read and what was not.
Quick start
The popular feed only, last 24 hours:
Selected communities over a week:
Discover the sub-topics inside broad themes:
Only themes spreading across several communities:
FAQ
What is a Reddit trending topic?
A subject that several recent posts are about at once, posted by different people, and moving faster than the rest of what was analysed. A topic is reported only when multiple posts support it (3 by default) from multiple authors (2 by default). One viral post with nothing related to it is not a trend, and is not reported.
How is this different from Reddit's Hot feed?
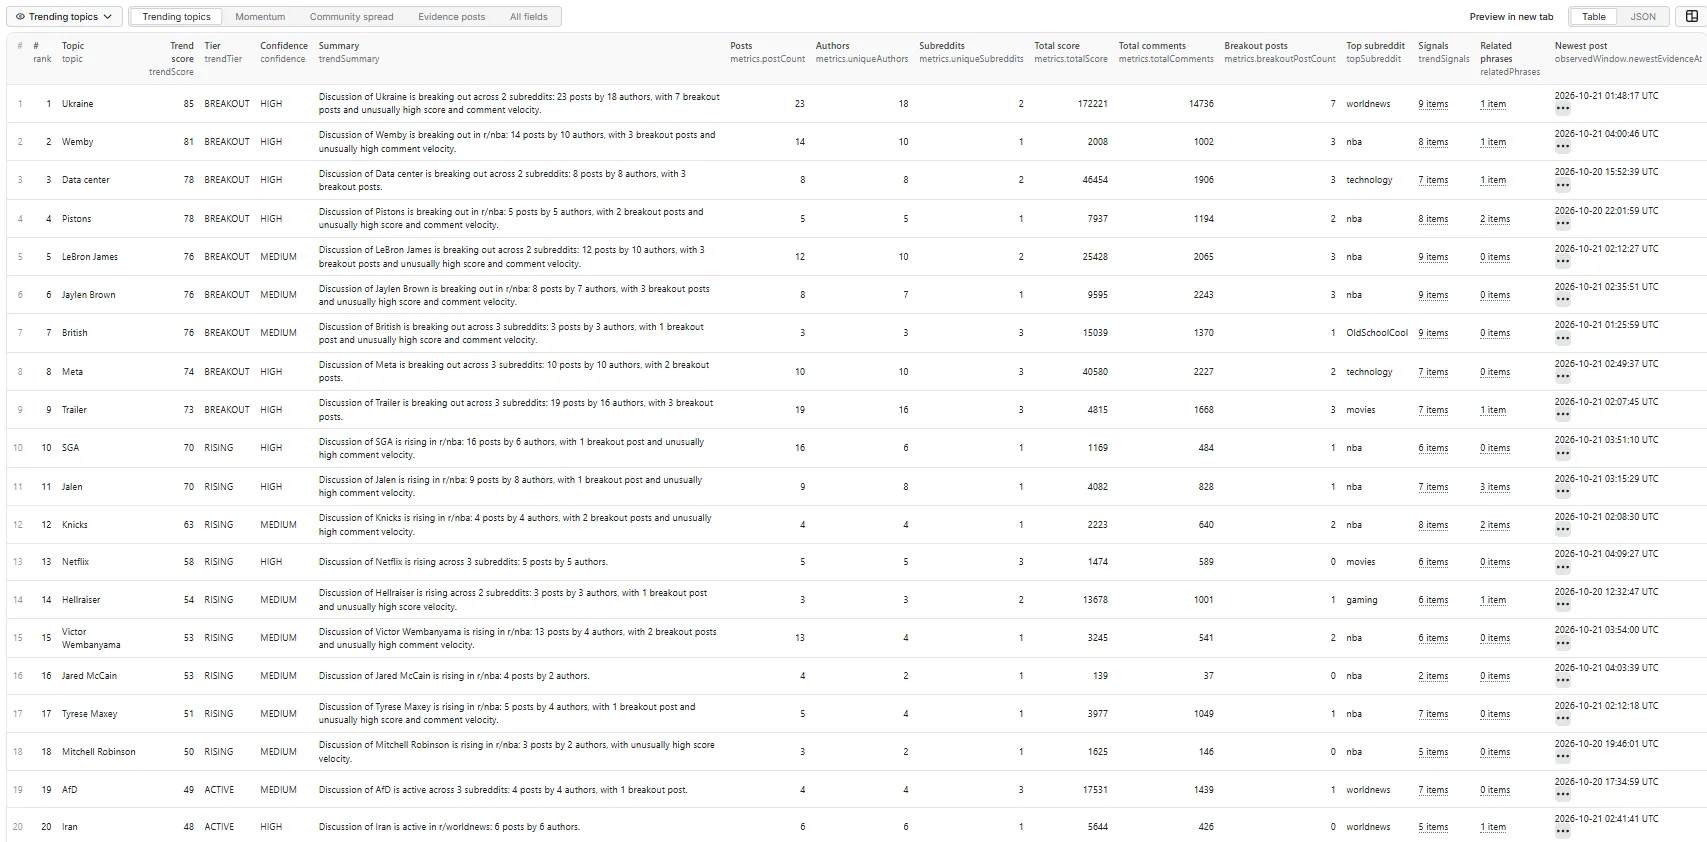
Hot ranks individual posts. This Actor reads Hot (and Rising, New and Top) as evidence, then asks which subjects keep coming up across many posts and communities. You get "Data center — BREAKOUT, 8 posts by 8 authors in 2 subreddits", not a list of the eight posts.
How is this different from a Reddit search scraper or a keyword monitor?
A search scraper returns the posts that match words you already know. A keyword monitor tells you when words you already know appear. This Actor is for the topics you do not know yet: you give it a scope — Reddit-wide, some communities, or broad seed themes — and it discovers what is rising inside it. A seed topic is only a starting point and is never itself returned as a topic.
Which feeds are analysed?
The ones you choose in Reddit feeds to read: Hot, Rising, New and Top (Hot, Rising and New by default; the Console form starts with Hot and Rising, so add New there for the newest posts too). Rising shows early momentum, Hot strong current engagement, New recency, and Top the most engaged posts of the window. Top alone is not recommended — high past engagement is not current momentum. Reddit's search has no Rising sort, so seed topics are searched with the others.
Can I select subreddits? Can I use seed topics?
Yes. List communities in Subreddits (technology, r/technology and full URLs all work) and
broad themes in Seed topics. HYBRID mode combines the popular feed with both; SUBREDDITS
and SEEDS use only one; POPULAR reads only the popular feed. A community that does not exist,
is private or is banned is reported as SUBREDDIT_UNAVAILABLE in the source summary and does not
stop the run.
What is score velocity? Comment velocity?
Score per hour since the post was created (score / max(age in hours, 1)), and comments per hour
the same way. A topic's engagement velocity and discussion velocity are how its posts rank on
these two rates against everything else analysed in the same run — so a quiet community and the
popular feed are each judged against their own sample, with no fixed thresholds. A breakout post
is in the top 10% of its own community on either rate (top 5% of the run when the community has
too few posts in the sample) and has real engagement behind it.
How are crossposts handled?
A crosspost and its original are one piece of content: they count once towards a topic's post
count, so copied content cannot inflate a trend. Each copy's community still counts towards the
topic's reach (uniqueSubreddits, crosspostSubreddits). Identical titles posted to several
communities are treated the same way. Turn on Exclude crossposts to leave them out entirely.
What does subreddit spread mean?
How many different communities a topic appears in, and how concentrated it is
(topSubreddit, topSubredditShare). A topic in r/technology, r/OpenAI and r/LocalLLaMA is
spreading; a topic in one community is still reported — single-community trends are often the most
useful — but it carries SINGLE_SUBREDDIT_DOMINANCE. Set Minimum subreddits per topic to 2 or
more to see only cross-community themes.
Why require multiple posts and authors?
So that one viral post, or one account posting the same thing repeatedly, is not mistaken for a trend. Both minimums are adjustable.
What do BREAKOUT, RISING, ACTIVE and WEAK mean?
| Tier | Meaning |
|---|---|
| BREAKOUT | Score 70+ with strong recent acceleration, and at least two breakout posts or three communities |
| RISING | Score 50+: clear positive momentum with enough evidence |
| ACTIVE | Score 30+: current discussion, limited evidence of acceleration |
| WEAK | Below 30: low momentum or low confidence |
The trend score adds up named parts — engagement velocity (25), discussion velocity (20), breakout
posts (15), recency (15), post count (10), author diversity (5), subreddit spread (5) and Reddit feed
presence (5) — minus penalties for single-post, single-author, crosspost and old-post dominance.
Every row carries the parts in scoreBreakdown, so you can re-weight them yourself. The weights are
a first calibration, not a benchmark result.
Confidence (HIGH / MEDIUM / LOW) reflects the evidence: how many posts and authors, how many communities, whether one post or author dominates, and whether score, comment count and timestamp were available for the posts.
Is AI required?
No. Topics are built with deterministic metrics and phrase clustering (
analysisMode: RULES_CLUSTERINGAre comments scraped?
No, unless you switch on Add a comment signal. Then the Actor reads up to
maxCommentsPerEvidencePost top comments on each of the fastest-moving posts (at most 60 posts)
and uses them to strengthen phrase discovery; each topic reports how many comments it drew on. It
is a small sample, never a full comment tree. For whole comment threads use a comment scraper.
How is pricing calculated?
Pay per result: one trending-topic-result event per topic delivered to your dataset. A topic summarises many posts, and its evidence posts come with it at no extra charge. Never charged: the posts that were analysed, topics below your minimums or minimum tier, topics beyond Max topics, sources that could not be read, runs that find no topic, and the run summaries. A run that finds nothing costs nothing. This README deliberately quotes no figures — the live price is on the Pricing tab and in the Console. If your spending limit cannot pay for every topic found, the highest-ranked topics are the ones delivered.
Does it need a Reddit login or API key?
No. The Actor reads public Reddit pages as a logged-out visitor. You never provide credentials.
Can it be scheduled? Called through the API or MCP?
Yes. Schedule it in the Apify Console (for example, a daily 24_HOURS run of your communities),
call it through the Apify API, or use it from AI agents through the Apify MCP server:
In an MCP client connected to https://mcp.apify.com, add the Actor
coregent/reddit-trending-topics-finder and ask, for example, "what topics are rising in r/startups
this week?".
What are the sampling limitations?
See Limitations below.
Input reference
| Field | Default | What it does |
|---|---|---|
mode | HYBRID | POPULAR, SUBREDDITS, SEEDS or HYBRID |
subreddits | — | Communities to analyse (up to 100) |
seedTopics | — | Broad themes to search for (up to 25) |
timeWindow | 7_DAYS | 6_HOURS … 30_DAYS; only posts created inside it are analysed |
postsPerSource | 100 | Recent posts read from each source (10–500) |
sortSources | Hot, Rising, New | Which of Reddit's feeds to read |
minimumPostsPerTopic | 3 | Distinct posts a topic needs (2–50) |
minimumAuthorsPerTopic | 2 | Different authors a topic needs |
minimumSubredditsPerTopic | 1 | Communities a topic needs; 2+ for cross-community trends |
minimumTrendTier | ACTIVE | Lowest tier returned |
maxTopics | 50 | Most topics returned, best first (1–200) |
minimumScore, minimumComments | 0 | Post-level filters; an unknown value never fails them |
excludeNSFW | on | Leave out posts marked NSFW |
excludeCrossposts | off | Leave crossposts out entirely (otherwise they count once) |
includeEvidencePosts | on | Attach supporting posts to each topic |
maxEvidencePosts | 5 | Supporting posts per topic |
includeCommentsSignal | off | Sample top comments on the fastest posts |
maxCommentsPerEvidencePost | 10 | Comments read per sampled post |
maxConcurrency | 5 | Sources read in parallel |
proxyConfiguration | Apify Datacenter | See the proxy policy below |
A source is one feed of one scope: the popular feed's Hot list, one community's Rising list, one seed topic's search results. HYBRID with 3 communities, 1 seed topic and the default three sorts is 3 + 9 + 2 = 14 sources. The form's starting input (Hot and Rising) is 2 + 6 + 1 = 9.
Output
One row per topic, in five views. Below is one real topic from a HYBRID run (r/technology, r/gaming, r/worldnews, r/movies, r/personalfinance, r/nba, the popular feed and two seed topics, 20 topics delivered), shown as each view returns it. Usernames are replaced.
Trending topics
The ranked list: score, tier, confidence, a one-line summary, and the size and reach of each topic.
Momentum
The velocity and feed signals behind the score, with the score broken into its named parts.
Community spread
How many communities a topic reached, and how concentrated it is in one community or one author.
Evidence posts
The posts that support the topic, with each post's own velocity, breakout flag and the feeds it was found on.
All fields
The complete row. evidencePosts is shortened here to 2 of its 5 posts; the Evidence
posts view above shows them all.
discoveredVia names every feed a post was found on — POPULAR_HOT, SUBREDDIT_RISING,
SEED_SEARCH and so on. A post seen on several feeds is analysed once.
Signals. trendSignals can include HIGH_SCORE_VELOCITY, HIGH_COMMENT_VELOCITY,
MULTIPLE_BREAKOUT_POSTS, MULTIPLE_AUTHORS, MULTIPLE_SUBREDDITS, CROSS_COMMUNITY_SPREAD,
RISING_FEED_PRESENCE, HOT_FEED_PRESENCE, RECENT_POST_CLUSTER, REPEATED_TITLE_THEME,
REPEATED_KEYPHRASE and RAPID_DISCUSSION_GROWTH. weakeningSignals can include
SINGLE_POST_DOMINANCE, SINGLE_AUTHOR_DOMINANCE, SINGLE_SUBREDDIT_DOMINANCE,
LOW_EVIDENCE_COUNT, OLD_POST_DOMINANCE, LOW_ENGAGEMENT and DUPLICATE_CROSSPOST_DOMINANCE.
Run records in the key-value store:
RUN_SUMMARY— sources requested and read, communities unavailable, posts collected and analysed, duplicates removed, crossposts canonicalised, exclusions by reason, metadata coverage, breakout posts, topics detected by tier, topics rejected by which minimum, topics delivered.SOURCE_SUMMARY— one status per source:SUCCESS,NO_RESULTS,SUBREDDIT_UNAVAILABLE,FEED_FAILED,SEARCH_FAILED,BLOCKED,RATE_LIMITED,PARTIAL_RESULTorPROVIDER_ERROR. One failed source never fails the run.
Proxy and reliability
The Actor paces itself to Reddit's published logged-out request budget on every proxy session, rests
any session Reddit challenges, and retries transient errors. A source Reddit blocks is read again
through an alternative route where one is available, and is reported in SOURCE_SUMMARY when it is
not. Posts pinned by moderators and AutoModerator posts are left out of the analysis — a weekly
thread is not a trend.
🚦 Proxy policy
Use Apify Datacenter proxy or no proxy for normal runs — both work for Reddit's public feeds and search at this Actor's paced request rate.
Apify Residential proxy is not supported. The Actor fails at startup if apifyProxyGroups
includes RESIDENTIAL. Reason: in pay-per-event Actors, residential bandwidth is billed to
the developer, not the run user, and Reddit feed pages are large, so a bandwidth-heavy run could
exceed what it earns.
If you genuinely need residential routing, supply your own residential provider via the proxy editor's Custom proxy URLs field — that traffic goes through your provider, not Apify, and is unaffected:
Limitations
- A sample, not all of Reddit. Topics are found in the posts the run reads —
postsPerSourceposts from each feed you choose — not in every post on Reddit. More sources and more posts per source find smaller topics. - Trend scores are this Actor's own analytical metric. They are not Reddit's ranking, which is not reproduced, and they do not predict future virality. Scores are relative to the run's own sample.
- Scores and comment counts change after the run; the row records them as they were read.
- Clustering is phrase-based. Ambiguous themes can be merged or split, and a topic whose posts share no common name or phrase in their titles is not found. Very generic words ("AI", "news", "game") are not returned as one-word topics, though they appear inside longer ones ("AI agents").
- The analysis is tuned for English titles.
- Reddit's logged-out feeds leave out most NSFW posts, so
excludeNSFWrarely has anything to remove; a post whose NSFW status Reddit does not publish is kept. - Seed-topic searches stop at about 250 results per seed and sort — Reddit's own search limit.
- Rising lists are short. A community's Rising feed often ends after one or two pages.
- Feeds Reddit refuses to serve are read another way, within a per-run allowance that grows with
Max topics. A small Max topics with very many sources can use it up; a feed read after that is
reported
PROVIDER_ERROR, orPARTIAL_RESULTif part of it was read, and the run analyses the rest. - The popular feed is Reddit's global popular feed, not localised. No region or audience geography is inferred.
- No official Reddit trend data and no exact count of people discussing a topic — posts and authors in the sample are what is counted.
Related Coregent Actors
- Reddit Posts & Search Scraper — raw post rows for known queries and communities.
- Reddit Comments Scraper — whole comment threads, one row per comment.
- Reddit Keyword Monitor — alerts when words you already track appear.
This Actor is for discovering the topics you do not know yet; the others extract or monitor what you already know.
Responsible use
This is an unofficial tool, not affiliated with or endorsed by Reddit. It reads only publicly available Reddit content as a logged-out visitor. You are responsible for how you use the output, including compliance with Reddit's terms and applicable law.
Changelog
- 1.0 — First release: popular, community and seed-topic discovery; score and comment velocity; breakout detection; crosspost-aware phrase clustering; trend score, tier, confidence, signals and evidence posts; optional comment signal.


