
Reddit Scraper | Posts, Comments, Subreddits & Users
Pricing
from $2.13 / 1,000 reddit results
Reddit Scraper | Posts, Comments, Subreddits & Users
Get Reddit posts, comments, subreddits and users as flat rows: title, text, score, upvote ratio, comment count, author and publish date. Subreddit feeds, full comment threads, search for posts, comments, communities or people, and user feeds in one run. No login or API key.
Pricing
from $2.13 / 1,000 reddit results
Rating
0.0
(0)
Developer
Flowo
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
4 days ago
Last modified
Categories
Features
Share
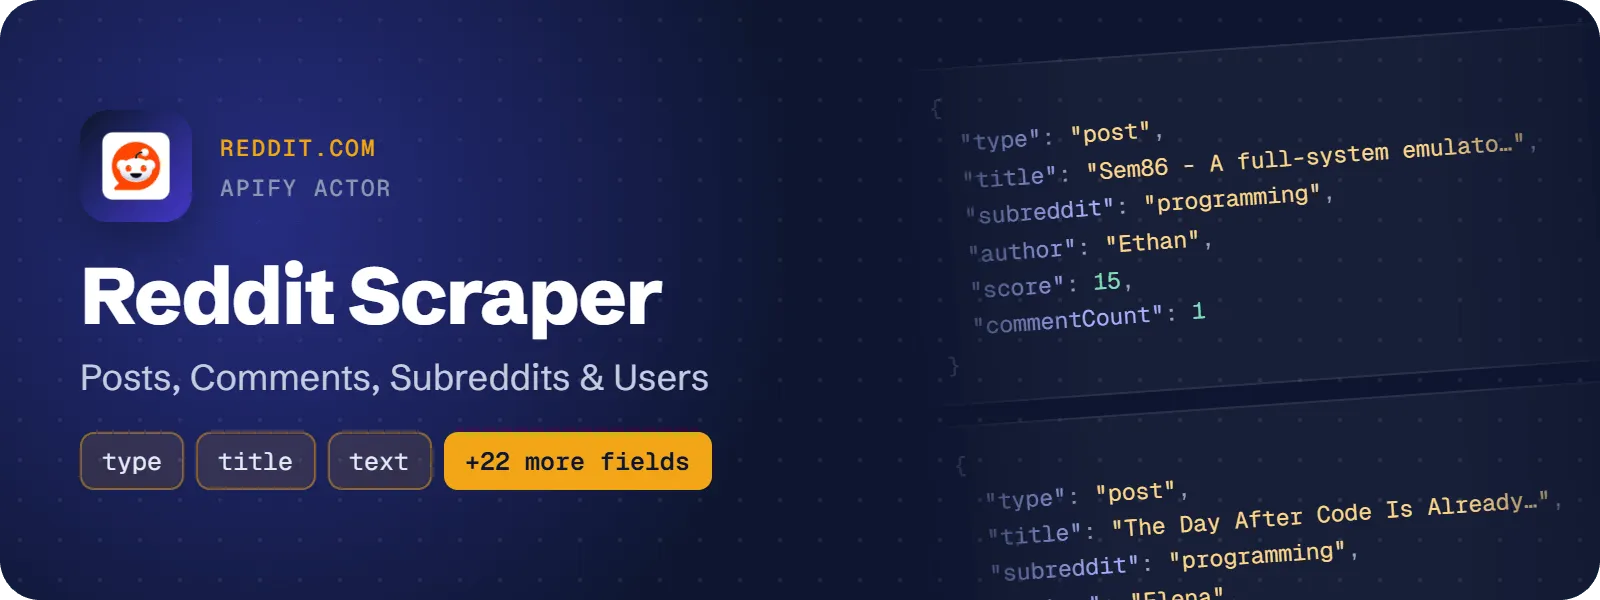
Get public Reddit data as flat rows: post title, text, score, upvote ratio, comment count, flair, author and publish date, plus full comment threads with the parent comment and nesting depth. One run can mix subreddit feeds, post URLs, Reddit search (posts, comments, communities or people) and user feeds. No login, no Reddit account and no API key.
What does Reddit Scraper do?
You give it subreddit names, search terms, usernames or any reddit.com URLs. It returns one row per item, and the type column says what the row is: post, comment, subreddit or user. Because every row is flat, the dataset opens directly in Excel, Google Sheets, a BI tool or an AI pipeline. It is built for marketers tracking brand mentions, founders and analysts looking for pain points in a community, data teams collecting discussion text, and AI agents that need to know what Reddit says about a topic.
How to scrape Reddit posts and comments
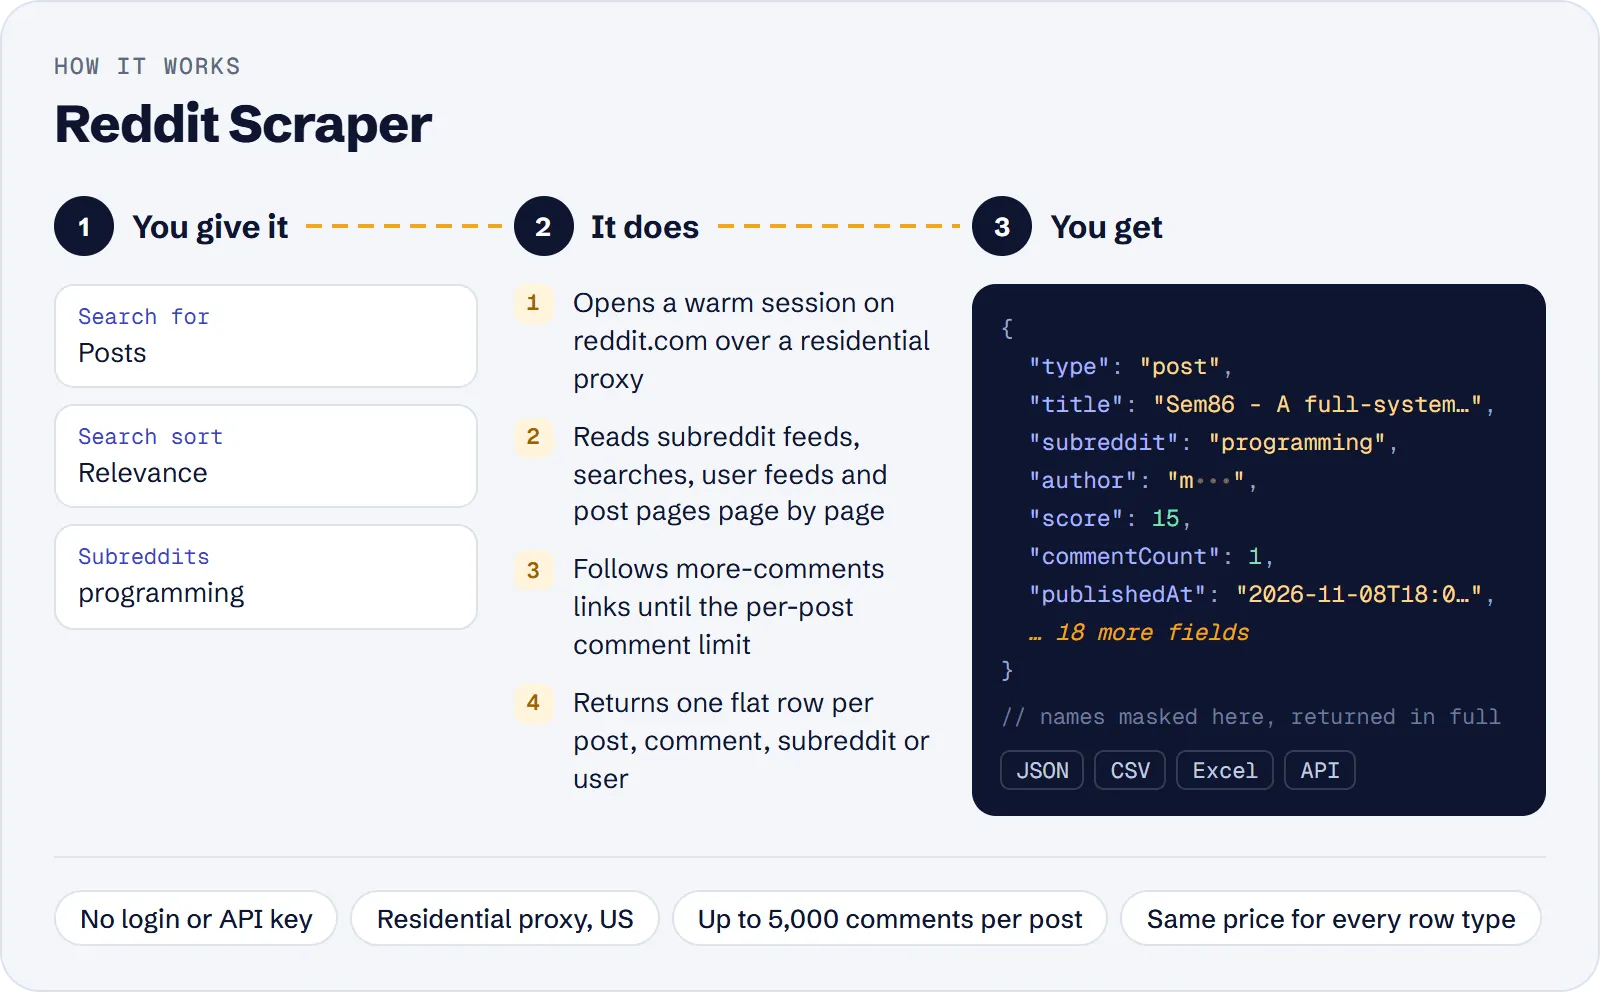
- Open the actor in Apify Console and click Try for free.
- Add at least one source: Reddit URLs, Search terms, Subreddits or Users. You can combine them in one run.
- Choose the order: Subreddit sort for feeds, Search for and Search sort for search terms, User content for users. Set Time range for Top and Controversial feeds and for post and comment searches.
- Optionally switch on Add comments of every post and set Max comments per post (up to 5,000).
- Set limits with Max results per source and Max results in total, and filter with Only posted after and Include NSFW.
- Click Start. When the run finishes, download the dataset as JSON, CSV, Excel or HTML, or read it through the API.
How much does it cost to scrape Reddit?
Price per event by Apify plan:
| Event | Free | Bronze | Silver | Gold and above |
|---|---|---|---|---|
| Actor start | $0.00005 | $0.00005 | $0.00005 | $0.00005 |
| Reddit result | $2.50 per 1,000 | $2.375 per 1,000 | $2.25 per 1,000 | $2.125 per 1,000 |
A test run with the API example input below returned 30 rows in 14 s.
You pay per result: one paid event is one row saved to the dataset — a post, a comment, a subreddit or a user. Every row type has the same price. On top of that, Apify charges the default Actor start event once per run (per GB of memory; the actor runs on 256 MB).
Not charged:
- duplicates (the same post found by two sources is saved once);
- NSFW posts and communities skipped because Include NSFW is off;
- posts and comments skipped by Only posted after;
- empty, banned, private or nonexistent subreddits and users — they give a log warning and no rows.
Example costs on the Free plan ($0.0025 per result, start $0.00005):
| Scenario | Paid results | Cost |
|---|---|---|
| 100 newest posts of one subreddit | 100 | $0.25005 |
| The prefilled example input (one post with comments, one search, one subreddit), about 200 rows | ~200 | ~$0.50005 |
| 25 top posts of the week with 50 comments each | 25 + 1,250 = 1,275 | $3.18755 |
| One post URL with 1,000 comments | 1 + 1,000 = 1,001 | $2.50255 |
Input
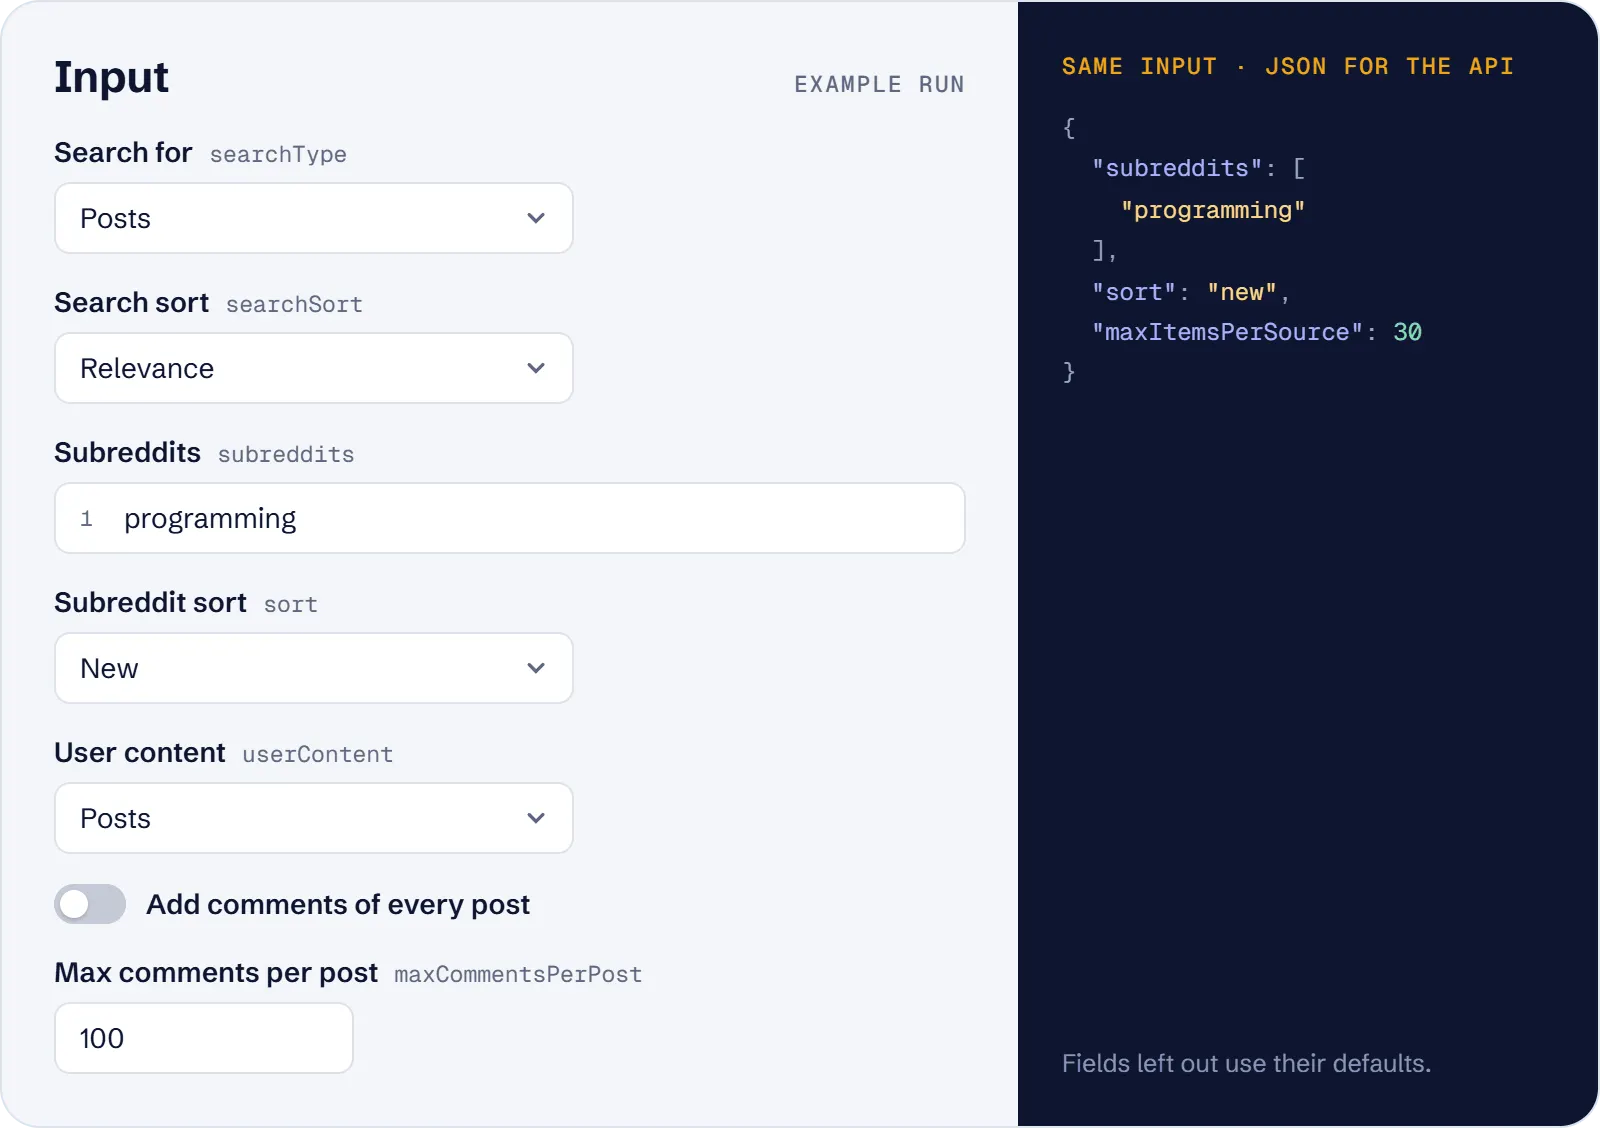
At least one source field is required: startUrls, queries, subreddits or users. Sources run in this order: URLs, subreddits, search terms, users.
| Field | What it does |
|---|---|
startUrls | reddit.com URLs: a subreddit (optionally with /top/?t=week), a post (/r/<sub>/comments/<id>/<slug>/ — the post and its comments), a user (/user/<name>/, /submitted/ = posts, /comments/ = comments) or a search (/search/?q=…&type=…, /r/<sub>/search/?q=…). Sort, time and type in the URL override the fields below. old., np., m. and new.reddit.com are accepted. |
queries | Search terms, one per line |
searchType | posts (default), comments, communities or people |
searchSort | relevance (default), new, top, comments (most comments) or hot — for post and comment searches only |
searchSubreddit | Limit post and comment searches to one subreddit; with communities or people the run stops with an input error |
subreddits | Subreddit names (a leading r/ or a full URL is accepted) |
sort | Feed order: hot (default), new, top, rising, controversial or best |
time | hour, day, week, month, year or all — for Top and Controversial feeds and for post and comment searches; ignored with a warning for other feeds; empty = Reddit's default |
users | Usernames (a leading u/ or a profile URL is accepted) |
userContent | posts (default), comments or overview (both). User feeds are always newest first. |
includeComments | Add the comment thread of every post found in feeds, user feeds and post searches (default off). Post URLs always get their comments. |
maxCommentsPerPost | 0–5,000 comments per post (default 100); 0 = only the post row of a post URL |
commentSort | best (default), top, new, controversial or old |
postedAfter | Keep only posts and comments newer than an absolute date (2026-01-31) or a relative one (7 days, 12 hours); not applied to communities and people |
includeNsfw | Keep NSFW posts and communities (default off) |
maxItemsPerSource | 1–1,000 posts, search results or user items per source (default 100) |
maxItems | Rows in the whole run (default 1,000) |
proxyConfiguration | Residential proxy, US, by default |
Example — the top posts of the week in r/rust with up to 50 comments each:
Example — the newest comments that mention pricing in r/SaaS:
What data can you extract from Reddit?
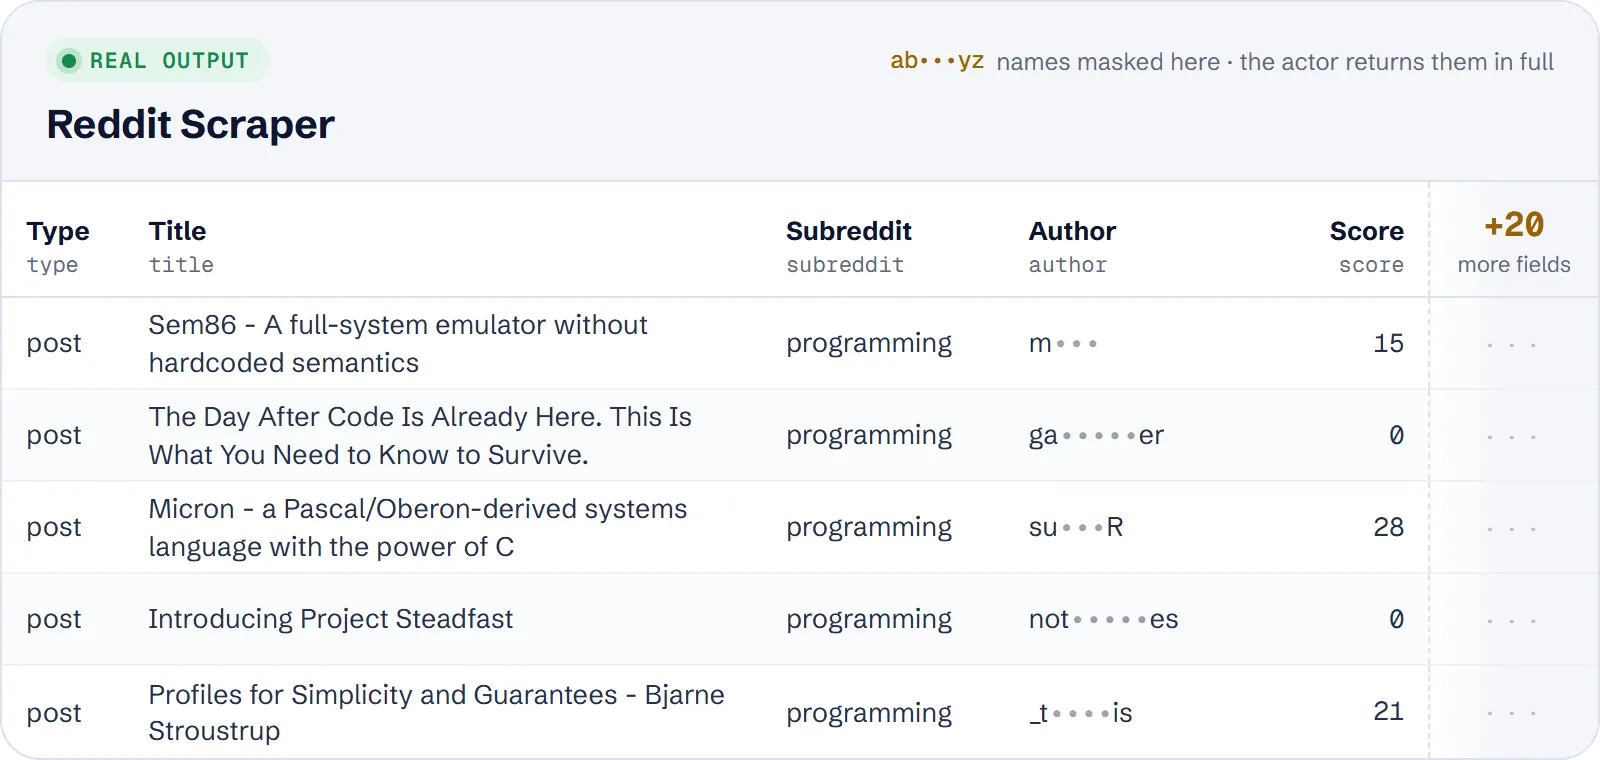
Every row has type, id, url, source and scrapedAt. The other fields depend on the row type and are null when they do not apply. Ids have no Reddit prefix, except subredditId (t5_…) and authorId (t2_…).
| Field | Rows | Description |
|---|---|---|
type | all | post, comment, subreddit or user |
id, url | all | Reddit id and reddit.com permalink |
source | all | The input that produced the row: r/<name>, u/<name>, search:<type>:<term> or the start URL |
query | search rows | The search term |
title | posts | Post title |
text | posts, comments | Plain text of a self post or comment (null for link, image and video posts without a body) |
postType | posts | e.g. text, link, image, gallery, video, crosspost, multi_media |
linkUrl, domain | posts | Link or media URL and its domain |
imageUrl | posts, users | Post thumbnail or user avatar |
flair | posts | Post flair text (depends on the subreddit) |
score | posts, comments | Upvotes minus downvotes |
upvoteRatio | posts | Share of upvotes, 0–1 (feed posts and post pages) |
commentCount, awardCount | posts | Number of comments and awards |
subreddit, subredditId | posts, comments from search, subreddits | Subreddit name without r/ and its id |
author, authorId, authorUrl | posts, comments | Author username, id and profile URL (null for [deleted]) |
language | posts | Language code detected by Reddit |
publishedAt | posts, comments | Publish date, ISO 8601 |
isNsfw, isSpoiler | posts (isNsfw also subreddits) | NSFW and spoiler flags |
postId, postTitle | comments | The post a comment belongs to (postTitle in comment search rows) |
parentId, depth | comments in threads | Parent comment id (null for top-level) and nesting level (0 = top-level) |
isDeleted | comments in threads | The author deleted the comment or account |
description, subscribers | subreddits | Community description and member count |
username, karma | users | Username and total karma (people search) |
scrapedAt | all | When the row was extracted |
A real post row from r/programming:
A comment row carries postId, parentId, depth, author, authorUrl, text, score, publishedAt and isDeleted. A subreddit row carries subreddit, subredditId, description, subscribers and isNsfw. A user row carries username, karma and imageUrl.
Use cases
- Monitor subreddits: scrape
r/programmingandr/desorted by New with Only posted after = 1 day and get yesterday's posts with score, upvote ratio, comment count, flair and link. - Brand mentions and keyword research: search posts or comments for "notion alternative", sorted by Top over the past month, optionally only inside r/productivity.
- Full discussion of a post: give a post URL with up to 1,000 comments sorted by Top, and rebuild the thread from
parentIdanddepth. - Find communities and people: search communities for "python" to get subreddit names, descriptions, member counts and NSFW flags, or search people to get usernames and karma.
- User activity: collect the posts, comments or both of a user such as
spez, newest first.
Limitations
- Reddit lists (feeds and search) stop at about 1,000 items, so Max results per source is capped at 1,000.
- r/all and r/popular, short
redd.itlinks,/comments/<id>URLs without/r/<sub>/, wiki, media and settings pages are not supported and stop the run with an input error. - User profile details such as karma breakdown or trophies are not scraped; users appear as people-search rows (username, karma, avatar) and through their post and comment feeds.
- User feeds are always newest first; Subreddit sort does not apply to them.
- Fields can be empty:
flairdepends on the subreddit,languageis missing on some posts,textis null for link and media posts, andupvoteRatio,postType,linkUrlandawardCountare not available on post search rows. - If Reddit blocks the main method for a subreddit feed or user posts, the actor reads them via RSS; those rows have no score, comment count, flair or NSFW flag, and the log says so.
- Banned, private, quarantined and nonexistent subreddits, and nonexistent or suspended users, return 0 rows with a warning naming the source.
- Reddit's page structure is undocumented and can change; a source that can no longer be read fails with a clear error while the other sources keep their rows.
Tips and troubleshooting
- Keep the residential proxy. Reddit blocks most datacenter IPs; with another proxy the log warns and runs often fail.
- Only new posts: use
sort: "new"with Only posted after — the feed stops at the first older post, so you pay only for new rows. With other sorts and with search, older rows are skipped while paging continues. - More comments: raise Max comments per post (up to 5,000) and remember that every comment is a paid row and counts toward Max results in total.
- Time range does nothing? It applies only to Top and Controversial feeds and to post and comment searches; Hot, New, Rising and Best feeds ignore it with a warning, and so do communities and people searches.
- 0 rows from a subreddit? Check the log: the subreddit may not exist, be banned, private or quarantined, or all its posts were NSFW (switch on Include NSFW) or older than your date filter.
- includeComments has no effect on communities and people searches or on
userContent: "comments", because those rows are not posts.
API, MCP and integrations
Run the actor from your code with the same JSON input as in Console. Your API token is in Console → Settings → API & Integrations.
Python (pip install apify-client):
Node.js (npm install apify-client):
HTTP — one request runs the actor and returns the results (runs up to 5 minutes; longer ones: run asynchronously):
AI agents (MCP). Add the actor as a tool of the Apify MCP server. Claude Code:
Claude Desktop, Cursor or VS Code: {"mcpServers": {"apify": {"url": "https://mcp.apify.com?tools=genial_candlestand/reddit-posts-comments-scraper"}}}. Then ask, for example:
- "Get the newest posts from r/programming and r/de published in the last day"
- "Find Reddit comments from the past month that mention notion alternative, sorted by top"
- "Find subreddits about python with their member counts, descriptions and NSFW flags"
Integrations. Run it on a schedule with Apify Schedules and send the results to Google Sheets, Slack, Zapier, Make, n8n or your webhook — see Apify integrations.
FAQ
Do I need a Reddit account or API key?
No. The actor reads only public pages without a login, an account or a developer token.
Can I get every comment of a large thread?
The actor follows Reddit's "more comments" links, top-level and nested, until Max comments per post is reached (up to 5,000 per post). Each comment is its own row with parentId and depth.
How is it different from other Reddit actors?
It returns all four row types (posts, comments, subreddits, users) with one price per row, searches posts, comments, communities and people, and can search inside one subreddit. Banned or private sources give no placeholder rows and cost nothing. It charges no extra start fee beyond Apify's default start event; the most-used Reddit actor in the Store charges $4.00 per 1,000 results.
What happens if one source fails?
Each source runs on its own. A failed subreddit, search or user becomes a warning in the log and the run keeps the rows of the other sources.
Is it legal to scrape Reddit?
The actor collects only publicly visible data, the same a logged-out visitor sees. It does not log in or bypass access controls. Reddit content can include personal data such as usernames; you are responsible for using the data in line with Reddit's terms, data-protection laws such as the GDPR, and your local regulations.
Also useful
- YouTube Comments Scraper — compare Reddit threads with YouTube comments and replies: text, likes, reply counts and dates
- Google Search Scraper — find which pages and Reddit threads rank on Google for the same keywords
- Google Trends Scraper — check whether a topic discussed on Reddit is rising in Google search interest
- Google News Scraper — add news coverage of the same topic: titles, sources and publish times
- Trustpilot Reviews Scraper — add customer reviews of the brand you track: ratings, text and company replies


