
Google Images Scraper — Image URLs, Sizes & Source Pages
Pricing
from $0.0015 / image scraped
Google Images Scraper — Image URLs, Sizes & Source Pages
Scrape Google Images by keyword: full-size image URL, width and height, thumbnail, title, source page and domain. Filter by size, type, color and usage rights. Bulk searches, any country and language, for datasets, research and AI.
Pricing
from $0.0015 / image scraped
Rating
0.0
(0)
Developer
Hipersoft
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
6 hours ago
Last modified
Categories
Share
Google Images Scraper extracts image results from Google Images in bulk: full-size image URL, width and height, thumbnail, title, source page and domain, file size and dominant color. Filter by size, type, color and usage rights, run many searches at once, and export to JSON, CSV or Excel.
What does Google Images Scraper do?
Give it search terms and it returns one row per image result, with the link to the original image and the page it came from. It returns links and details, not the image files. To save the files, feed imageUrl into Bulk Image Downloader.
What data can you scrape from Google Images?
| Data | Fields |
|---|---|
| Image | imageUrl, imageWidth, imageHeight, fileSize, dominantColor |
| Thumbnail | thumbnailUrl, thumbnailWidth, thumbnailHeight |
| Source | title, sourcePageUrl, sourceDomain, sourceName |
| Context | query, position, googleImageId, collectedAt |
Use cases
- AI and computer vision: build image datasets from many searches.
- Brand monitoring: see which sites show your products or logo.
- Market research: study how a product is shown across shops.
- SEO: see which pages rank for your image searches.
- Content research: find reference images and where they come from.
How to scrape Google Images
- Open Google Images Scraper.
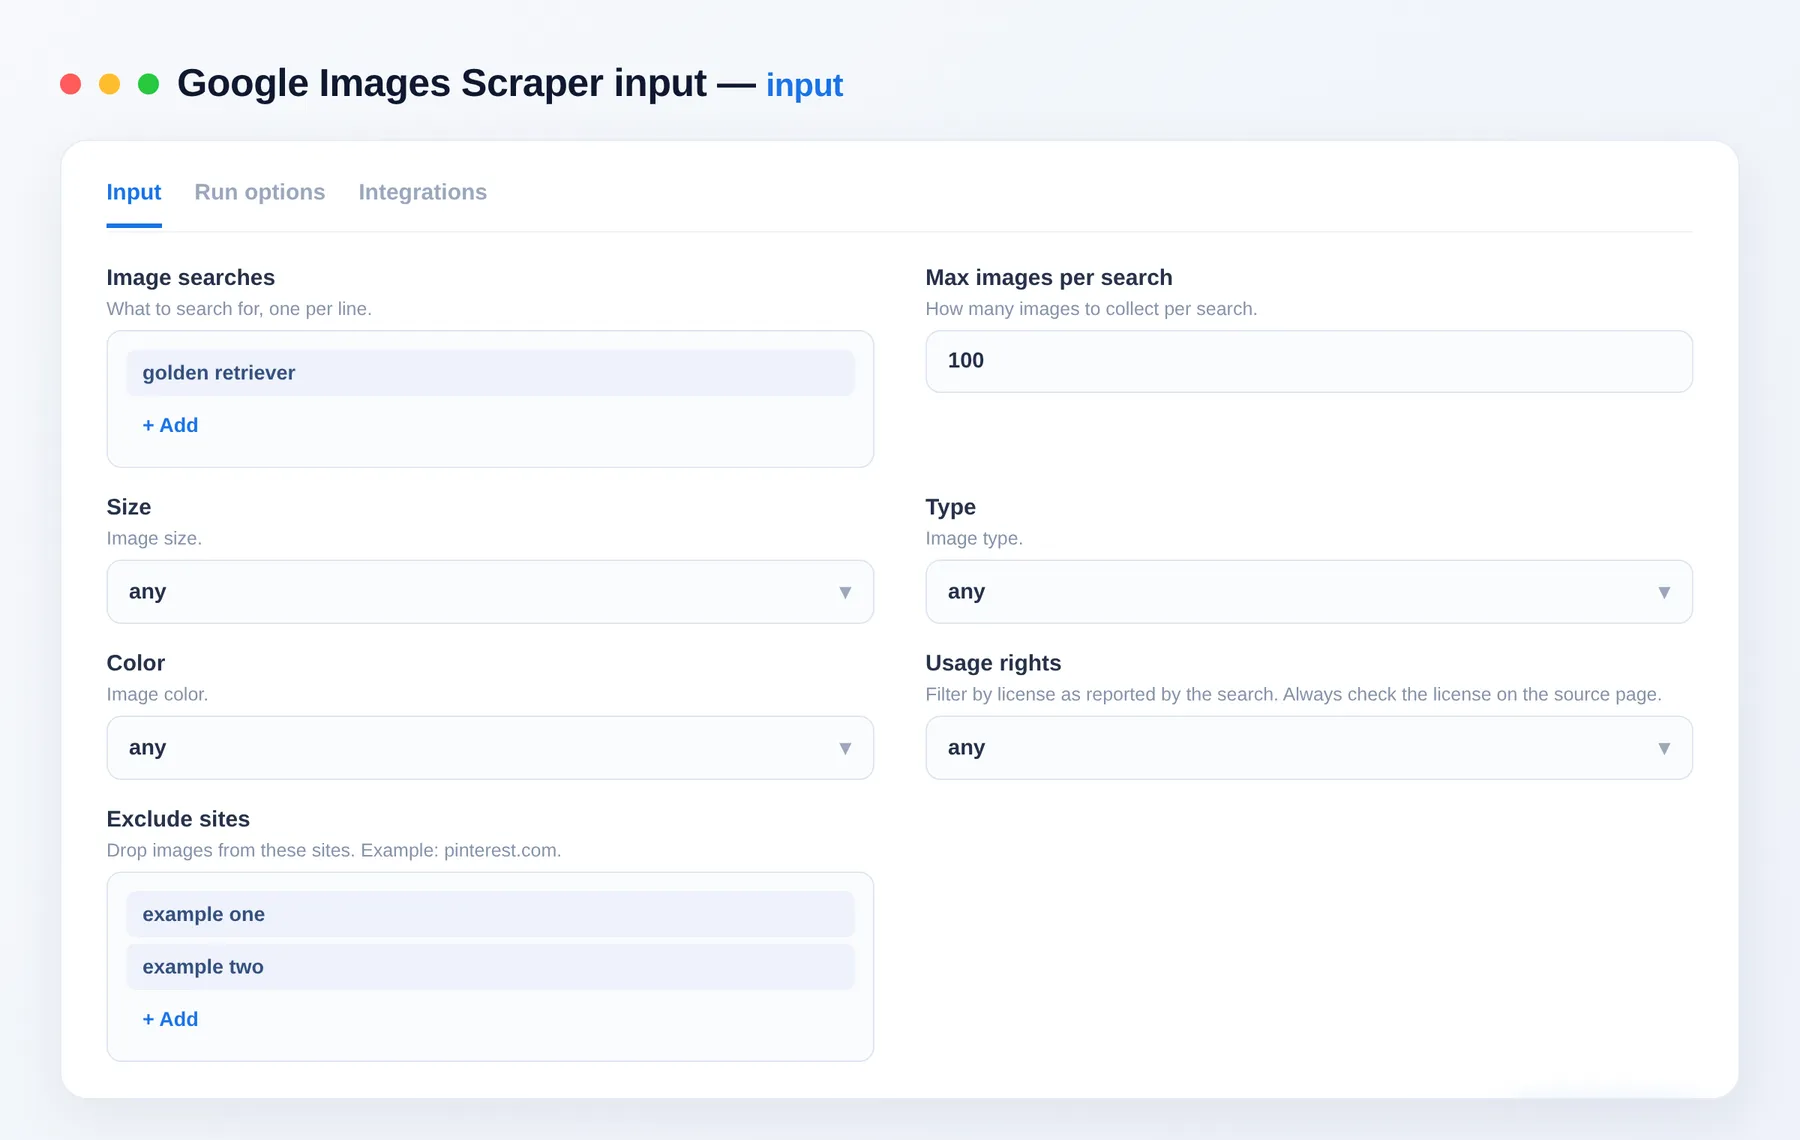
- Add your image searches.
- Pick any filters, and a country and language if you need them.
- Click Start.
- Export the results, or send
imageUrlto a downloader.
How many images do I get per search?
Up to about 200 images per search. A test asking for 600 returned 191 unique images, because Google stops offering new ones after that. To collect more, use more specific searches or combine filters. You pay only for images delivered.
Input
| Field | Description |
|---|---|
queries | What to search for. |
maxResultsPerQuery | Images per search (default 100, about 200 at most). |
size | any, large, medium or icon. |
imageType | any, photo, clipart, lineart or animated. |
color | any, color, grayscale, transparent, or a color such as red or blue. |
usageRights | any, creative_commons or commercial. |
excludeDomains | Sites to leave out. |
safeSearch | Filter explicit results. |
country / language | Two-letter codes (default us, en). |
Output
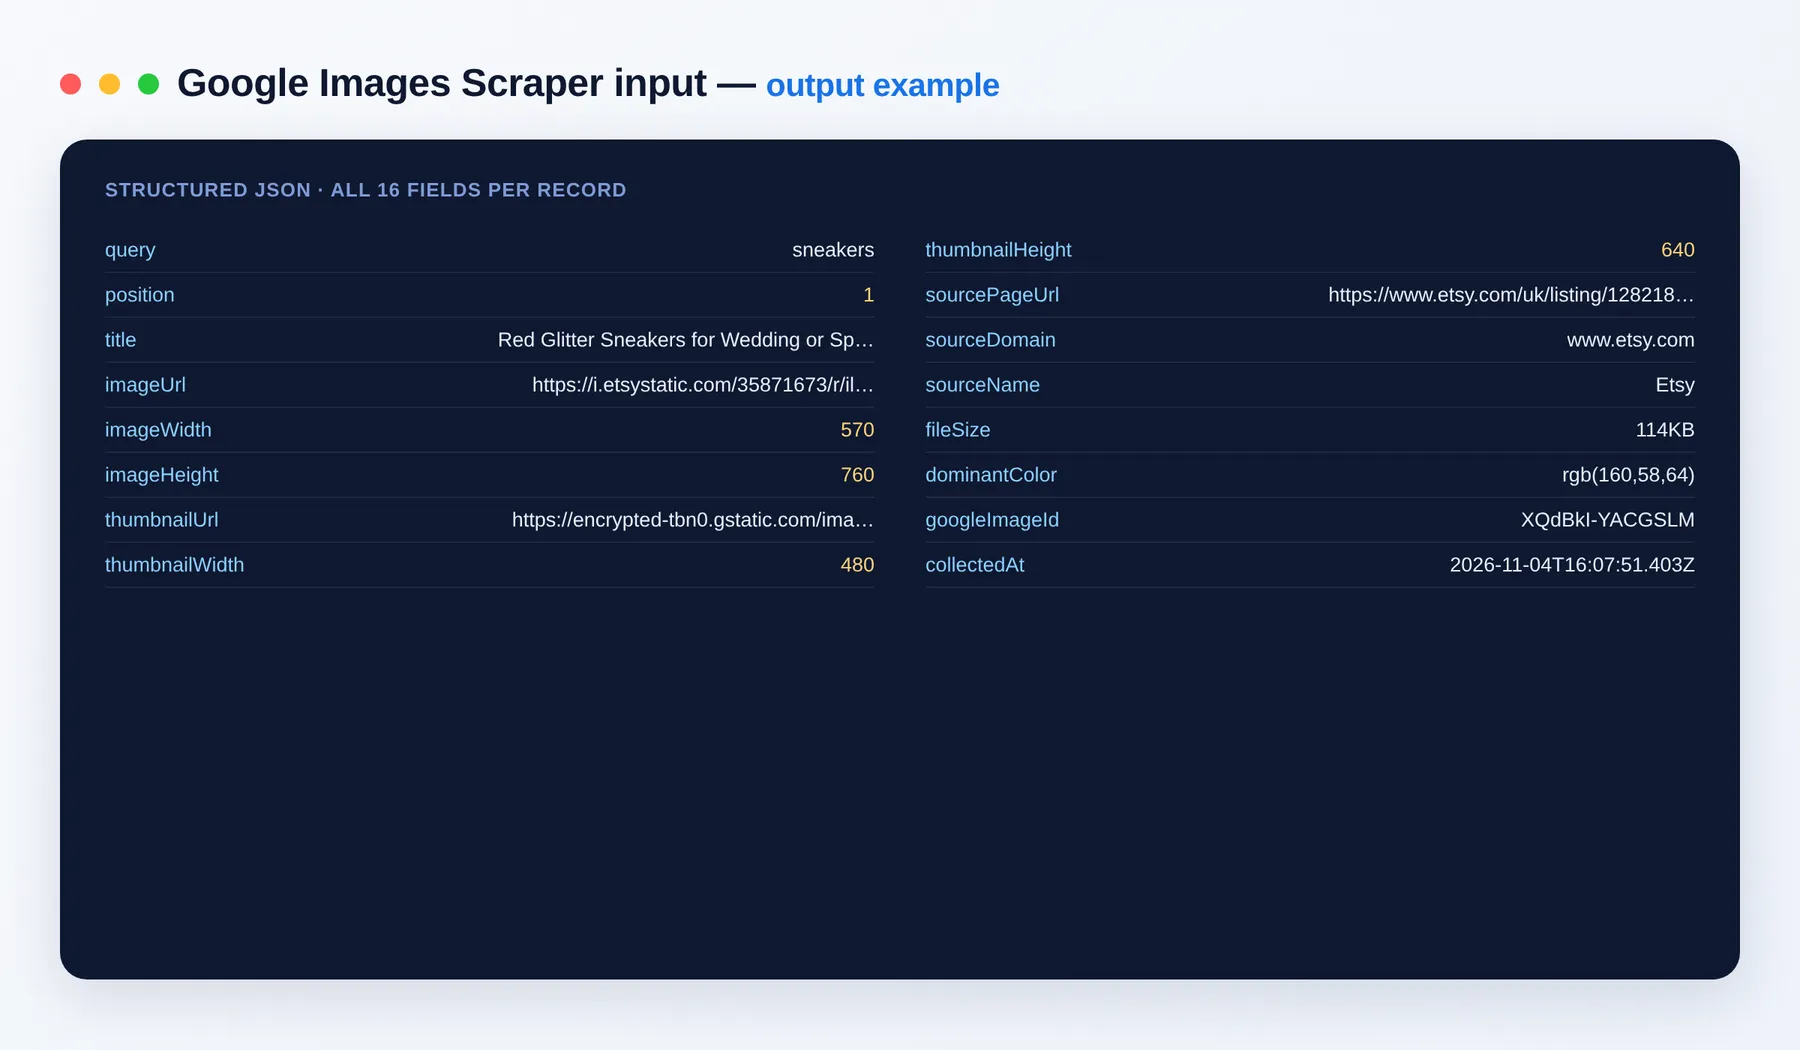
A real row from a test run.
Output schema
| Field | Type | Description |
|---|---|---|
query | string | The search. |
position | integer | Position in the results for this search. |
title | string | Title of the source page. |
imageUrl | string (URL) | Link to the original image. |
imageWidth / imageHeight | integer | Original size in pixels. |
thumbnailUrl | string (URL) | Small preview image. |
thumbnailWidth / thumbnailHeight | integer | Preview size in pixels. |
sourcePageUrl | string (URL) | Page the image appears on. |
sourceDomain | string | Site of that page. |
sourceName | string | Site name, when shown. |
fileSize | string | File size as shown. |
dominantColor | string | Main color of the image. |
googleImageId | string | Google's ID for this result. |
collectedAt | string (ISO date) | When the row was collected. |
Need the image files too?
- Bulk Image Downloader: download image URLs to stored files.
- Website Image Downloader: download every image from a web page or site.
- Google Search Scraper: web results, ads and more.
FAQ
How much does it cost? You pay per image delivered, shown on the Pricing tab. Set a maximum cost per run and it stops cleanly at that limit, storing only what you paid for.
Can I use these images freely? Not automatically. Images belong to their owners. The Usage rights filter uses what the search reports, so always check the license on the source page before reusing an image.
Does it download the images? No, it returns links and details. Use Bulk Image Downloader for the files.
Why did I get fewer images than my maximum? Each search reaches about 200 images at most. Very specific filters can return fewer.
Can I connect this to other tools? Yes, through integrations on the Apify platform: Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API and webhooks.
Is it legal to scrape Google Images? It returns publicly listed results. You are responsible for how you use them, including copyright and each site's terms.
Feedback
How did it go? Good or bad, a review helps other users decide and tells us what to improve. Something broken or missing? Open an issue and we'll look at it.
Related Actors
Notes
Independent tool, not affiliated with Google. Returns only public data; you are responsible for how you use it.


