
LinkedIn Ads Scraper
Pricing
from $1.27 / 1,000 results
LinkedIn Ads Scraper
LinkedIn Ads Scraper collects ads from the public LinkedIn Ad Library for the companies you name, by country and time range: ad copy, format, creative image links, call to action, advertiser and paying entity. No login needed. Export to JSON, CSV or Excel, or use the API.
Pricing
from $1.27 / 1,000 results
Rating
0.0
(0)
Developer

Social Data API
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Share
LinkedIn Ads Scraper — Ad Copy, Creatives and Advertiser Data
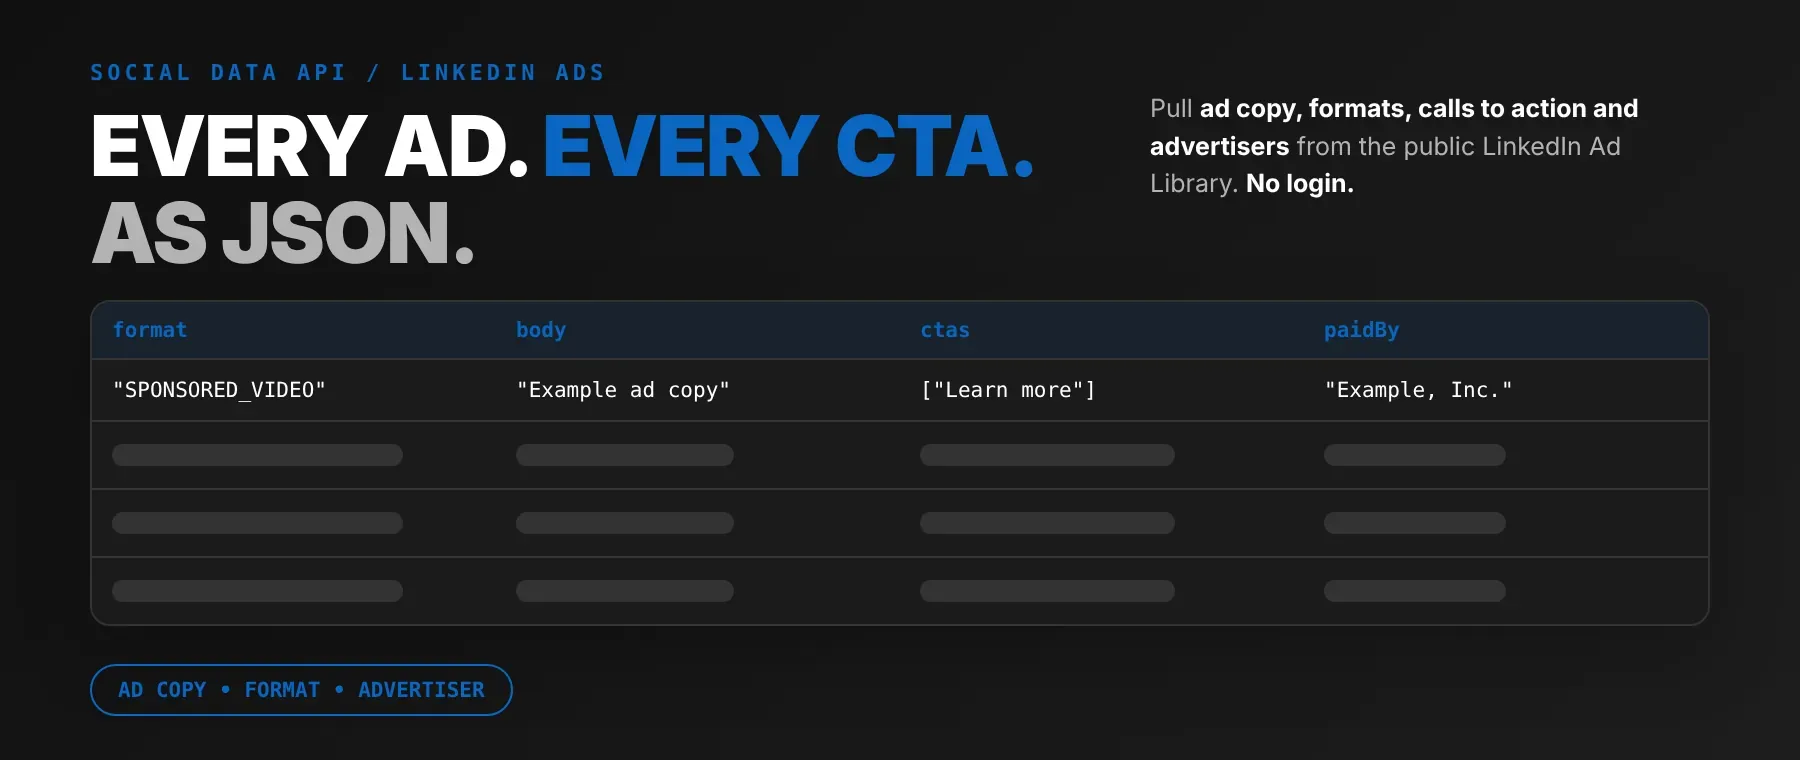
LinkedIn Ads Scraper collects the ads companies run on LinkedIn from the public LinkedIn Ad Library: the ad copy, LinkedIn's ad format, creative image links, call-to-action labels, the advertiser and the paying entity, filtered by country and time range. Every response is structured JSON — ready to pass directly to an LLM, index into a vector store, or feed a competitor research or ad-intelligence pipeline. No LinkedIn account, login or cookies needed. Start with one competitor, then track every advertiser in your market.
What data can I extract with LinkedIn Ads Scraper?
Using this LinkedIn Ad Library API, you will be able to extract the following LinkedIn ad data:
| 📝 Ad copy (with line breaks) | 🎞️ Ad format | 🖼️ Creative image links | 🔘 Call to action |
|---|---|---|---|
| 🏢 Advertiser name | 🔗 Advertiser LinkedIn page | 🪪 Advertiser logo | 💳 Paid for by |
| 🆔 Ad ID | 📎 Ad Library link | 🔎 Search that found the ad | 🕒 Time collected |
How to use LinkedIn Ads Scraper
Built for marketers, agencies and competitive analysts: one run turns a list of competitors into a table of the ads they are running on LinkedIn.
Copy to your AI assistant:
LinkedIn Ads Scraper MCP Server: use these Actors from ChatGPT, Claude or Cursor
Point your AI assistant at Apify and it can read the LinkedIn Ad Library on its own: a company's current ads, their copy, formats and calls to action. No glue code, no scraping logic in your prompts.
Step by step
- Create a free Apify account.
- Open LinkedIn Ads Scraper in the Apify Store.
- Add the companies you want to see ads for, one per line, then pick a country and a time range.
- Click Start (or send your API request).
- Download or stream your results in JSON, CSV or Excel.
How to scale LinkedIn Ads Scraper to bulk
Put any number of companies in one run and set maxItems up to 1,000, shared evenly between the companies; a company with fewer matching ads passes its unused share to the others. LinkedIn shows 24 ads per page, and the actor reads further pages only as far as each company's share needs. A recorded run returned 150 ads for three companies in 390 seconds, with the first row saved after 4.9 seconds, and rows are saved one by one as they are read, so you can watch the dataset fill while the run is going. To export LinkedIn ads for a whole market, list every competitor, then schedule the same run weekly in Apify Console.
✨ Features
LinkedIn Ads Scraper fetches clean, structured ad data from the LinkedIn Ad Library ⚡. It's ideal for competitor research, campaign benchmarking, creative inspiration and B2B market tracking — a LinkedIn ad library scraper, LinkedIn ad copy scraper and LinkedIn sponsored content scraper in one, and a simple LinkedIn ad spy tool for your competitors. It extracts, per ad:
- Ad copy – the full text, with its paragraphs and line breaks
- Format – LinkedIn's own format name, such as
SPONSORED_VIDEO,SPONSORED_UPDATE_CAROUSELorSPONSORED_INMAILS - Creatives – image and video cover links, without the advertiser's own logo or photo
- Call to action – button labels such as "Learn more", "Register" or "Download"
- Advertiser – name, LinkedIn page (company or member) and logo
- Paid for by – the paying entity LinkedIn shows
⚡ Filters are the ones the LinkedIn Ad Library itself offers: country and time range (last 30 days, this month, this year, last year or any time).
Use cases 💡
- B2B marketer — see which offers and calls to action competitors push this month.
- Agency — build a swipe file of LinkedIn competitor ads for a client pitch.
- Product marketer — compare ad formats and messaging across a category.
- Market researcher — track which companies advertise in a country and who pays for the ads.
- AI engineer — feed ad copy into an LLM to summarize a market's messaging.
Building an AI agent? Connect LinkedIn Ads Scraper over MCP and let it call the actor on its own.
Why choose this actor?
- Beyond the first page. LinkedIn listed 1,308 Google ads in the US for the last 30 days in October 2026; the actor keeps reading LinkedIn's next pages, 24 ads at a time, up to 1,000 ads per run.
- Fair across companies. A recorded run with three companies and
maxItems150 returned exactly 50 ads for each. - Clean, complete rows. Ad copy keeps its line breaks, advertiser links come without tracking parameters, and missing values are
nullinstead of empty strings.
⬇️ Input
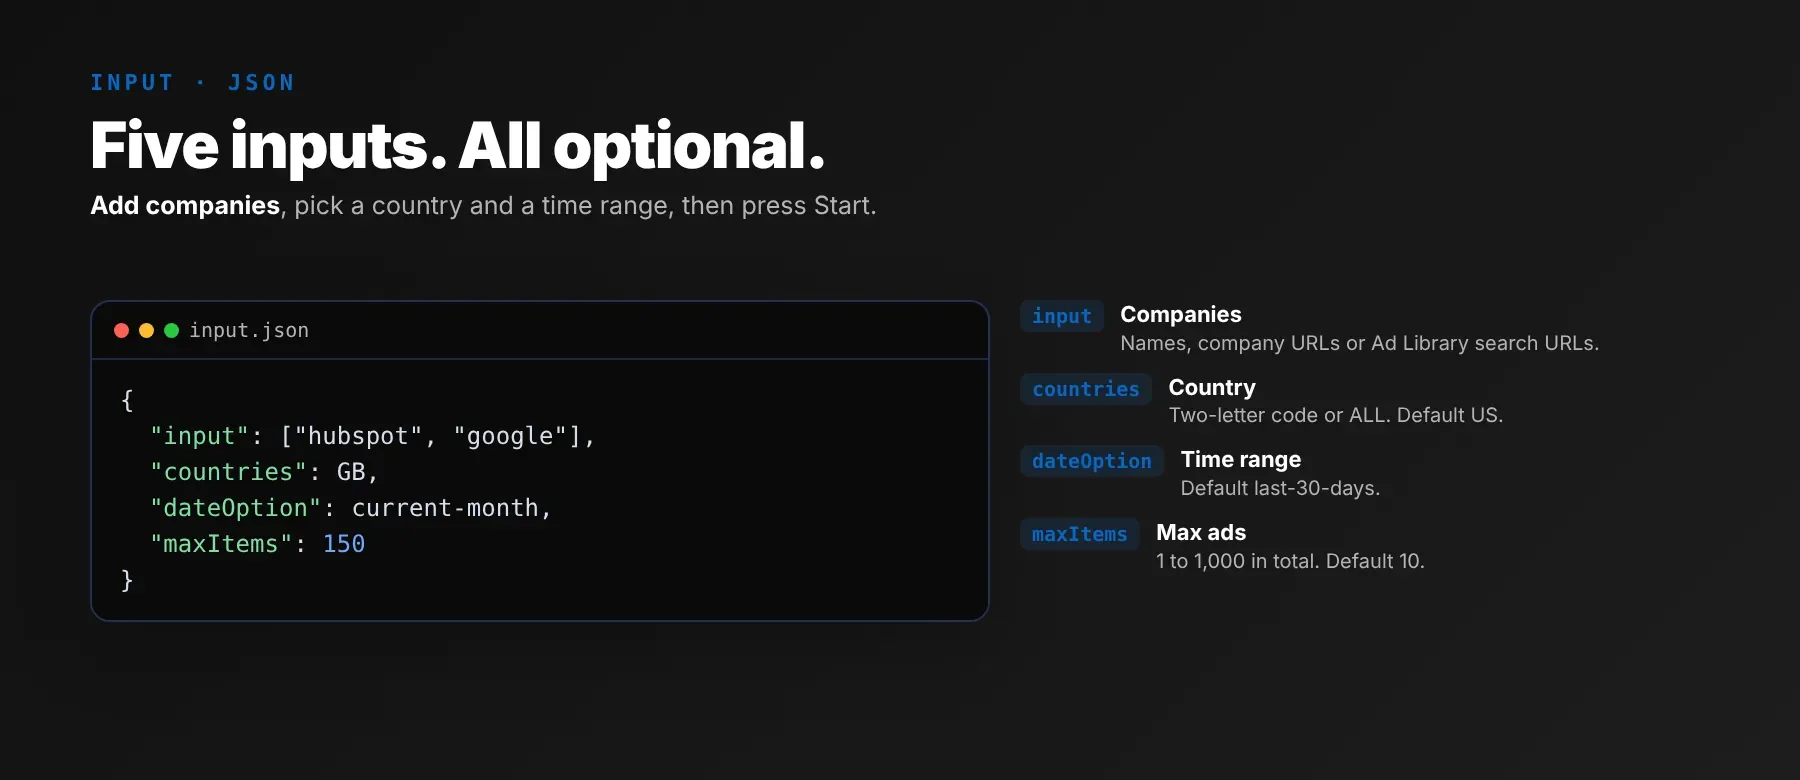
All parameters are optional — a default run uses the prefilled example company.
| Parameter | Required | Type | Description | Example value |
|---|---|---|---|---|
input | No | array | Companies to search, one per line: a company name, a LinkedIn company URL, or a ready-made LinkedIn Ad Library search URL (used as is). Repeated entries are searched once. | ["hubspot", "https://www.linkedin.com/company/salesforce/"] |
countries | No | string | Country the ads ran in, as a two-letter code, or ALL for every country. Default US. | "GB" |
dateOption | No | string | Time range: "" (any time), last-30-days, current-month, current-year, last-year. Default last-30-days. | "current-month" |
maxItems | No | integer | Total ads across all companies, 1–1,000, shared evenly. Default 10. | 150 |
proxyConfiguration | No | object | Optional — leave it off. Every request already goes through Apify residential proxy with a new address each time. A proxy you select is used instead; if it cannot be used or LinkedIn refuses it 12 times in a row, the run switches to Apify residential proxy. | {"useApifyProxy": false} |
LinkedIn answers about 23 ad pages a minute for one run, so 150 ads take about six minutes and 1,000 ads about 45 minutes.
Free plan limits
Free plan: up to 20 ads per run (all companies together) and 200 per month; paid plans have no limit.
Example input
⬆️ Output
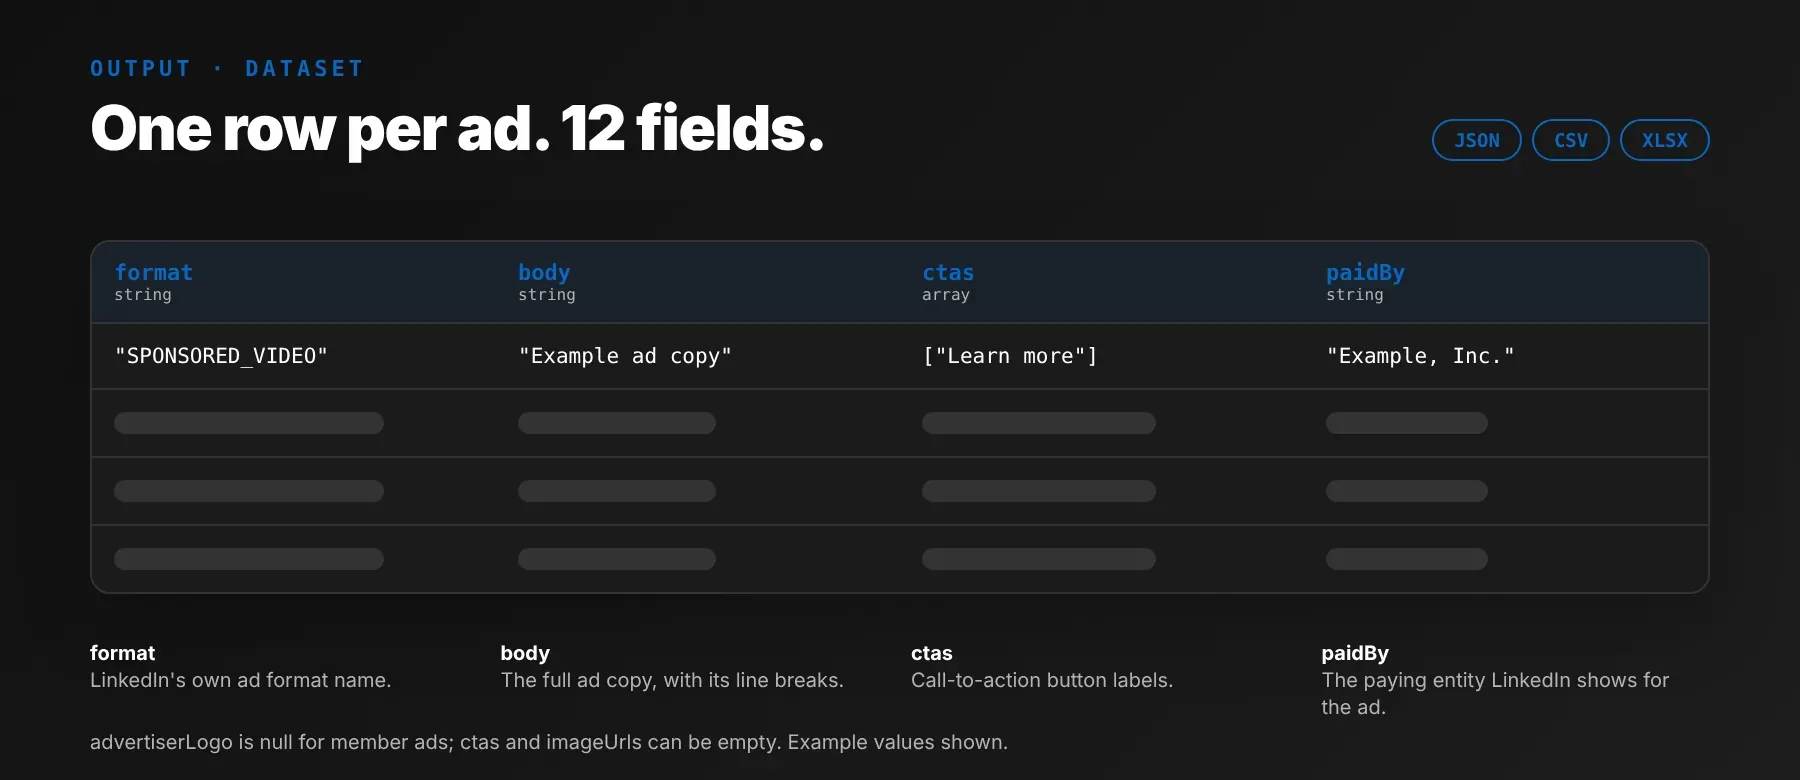
Every ad is one typed, normalized JSON item with the same twelve fields on every run; values LinkedIn does not show are null, and empty lists are []. Export the dataset as JSON (default), CSV or Excel.
Example output
Two recorded rows, a HubSpot video ad and a Google document ad:
advertiserLogo is null for ads posted from a member's profile, where LinkedIn shows the member instead of a company logo; ctas and imageUrls are empty when the ad has no button or image (document ads, for example).
How does it work?
The actor opens the public LinkedIn Ad Library search for each company with your country and time range — the same pages any visitor sees without logging in — and reads the ad list page by page until each company's share of maxItems is reached or LinkedIn has no more ads. Each ad's own Ad Library page is then read and saved as one row. Every request goes through Apify residential proxy with a new address, and a page LinkedIn does not answer is retried up to three more times on new addresses, then again after short pauses. It returns only publicly visible data, and the output fields stay the same from run to run, so your code and spreadsheets keep working when LinkedIn changes its pages.
How do you integrate LinkedIn Ads Scraper into your stack?
It works with what you already use: the REST API from any language, MCP for AI agents, and no-code tools.
Using LinkedIn Ads Scraper with the Apify API
Works in Go, Ruby, Node.js, cURL — any language that can make an HTTP request.
MCP integration for AI agents
Add the Apify MCP server to your AI client with one command:
This registers LinkedIn Ads Scraper as a tool your agent can call directly: the agent finds it through the server's search, adds it and runs it, then reads the ads back as JSON. Ask for "the LinkedIn ads HubSpot ran in the US this month, with their calls to action" and it does the rest. It works in Claude Code, Cursor and Windsurf.
No-code tools (n8n, Make, LangChain)
n8n: add the Apify node and choose "Run an Actor", or use the HTTP Request node pointed at the run-sync endpoint with your token. Send new ads to a Google Sheet or Slack in the next node.
Make: use the Apify app's "Run an Actor" module, then "Get Dataset Items" to pull the ads into the rest of your scenario.
LangChain: install langchain-apify and wrap the actor with ApifyActorsTool("linkedin-ads-scraper") so your agent can look up a company's LinkedIn ads.
Is it legal to scrape LinkedIn ads?
The LinkedIn Ad Library is a public transparency database: LinkedIn publishes these ads so anyone can see who advertises and who pays. This actor returns only publicly available data — what any visitor sees without logging in — and never reads private profiles, messages or account data. GDPR: scraping public data is generally permissible, but storing and using it must comply with local data-protection law. Consult legal counsel if your use case involves bulk storage of personal data.
Frequently asked questions
What fields does LinkedIn Ads Scraper return?
It returns each ad's ID, Ad Library link, ad copy, LinkedIn's ad format, call-to-action labels and creative image links, plus the advertiser's name, page and logo, the paying entity, the search that found the ad and the time it was collected. See the data fields section for the full list.
Does LinkedIn Ads Scraper require a LinkedIn account or login?
No. Only the public LinkedIn Ad Library is read, and no credentials, cookies or API key are needed.
How many ads can I extract in one run?
Up to maxItems — at most 1,000 — shared evenly between the companies you list, and limited by how many ads LinkedIn lists for your filters. LinkedIn keeps ads that ran after 1 June 2023 and removes them one year after they were last shown.
How fast does LinkedIn Ads Scraper run?
About 23 ads a minute: a recorded run returned 150 ads for three companies in 390 seconds, and another 60 ads for two companies in 143 seconds. That is the pace LinkedIn allows one visitor, so a bigger run takes longer rather than failing. Every run reads live data, not a cache.
What happens if a company has no ads, or LinkedIn does not answer?
You get no rows for that company and are not charged for it; the run log and status name the company, and its share goes to the other companies. An ad whose page cannot be read is left out without charge and replaced by the company's next ad. In code, group rows by startUrl to see how many each company returned.
Can I scrape ads for multiple LinkedIn companies at once?
Yes. List any number of companies; they are searched at the same time and maxItems is shared evenly between them. The same ad found under two companies is saved once.
Does LinkedIn Ads Scraper work with Claude, ChatGPT, and other AI agent tools?
Yes — LinkedIn Ads Scraper is available as an MCP tool. Register it in Claude Code, Cursor or Windsurf with claude mcp add --transport http apify "https://mcp.apify.com?tools=socialdataapi/linkedin-ads-scraper". Any agent that can call an HTTP endpoint can use the REST API directly.
Does LinkedIn Ads Scraper return data in a format LLMs can use directly?
Yes. Each ad is typed, normalized JSON with consistent field names, so there is no HTML parsing and no selectors. Pass it straight to an LLM, index it into a vector store, or feed it to an agent tool — no transformation step.
What happens when LinkedIn changes its Ad Library layout or updates its anti-bot system?
The actor is maintained, and when LinkedIn changes, it is updated so your calls keep returning the same JSON fields with no changes on your end.
Can I use LinkedIn Ads Scraper without managing proxies or browser infrastructure?
Yes. A default run already uses Apify residential proxy, with retries handled on the actor's side, and no browser is needed. You send one request and get structured JSON back, with no proxy accounts and no maintenance.
Which LinkedIn ad fields work best for AI training data and RAG indexing?
For RAG, use the ad copy, the advertiser name and the call-to-action labels. For training data and analytics, use the ad format, the paying entity and the creative image links. All fields are plain strings and lists, so no normalization is needed — a simple LinkedIn ads data extractor for any pipeline.
Your feedback
Found a bug or missing a field? Let us know in the actor's Issues tab. Every report is read, and fixes ship as new versions of the actor.


