
Patent Assignee Period Rollup
Pricing
from $24.50 / 1,000 portfolio assessments
Patent Assignee Period Rollup
Summarize patent datasets by observed assignee. Deduplicate patent records, separate date bases, surface conflicting metadata and report batch-scoped portfolio assessments with source evidence.
Pricing
from $24.50 / 1,000 portfolio assessments
Rating
0.0
(0)
Developer

Tim Zinin
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
21 hours ago
Last modified
Categories
Share
Patent Assignee Period Rollup — turn a patent-record batch into one portfolio assessment per assignee
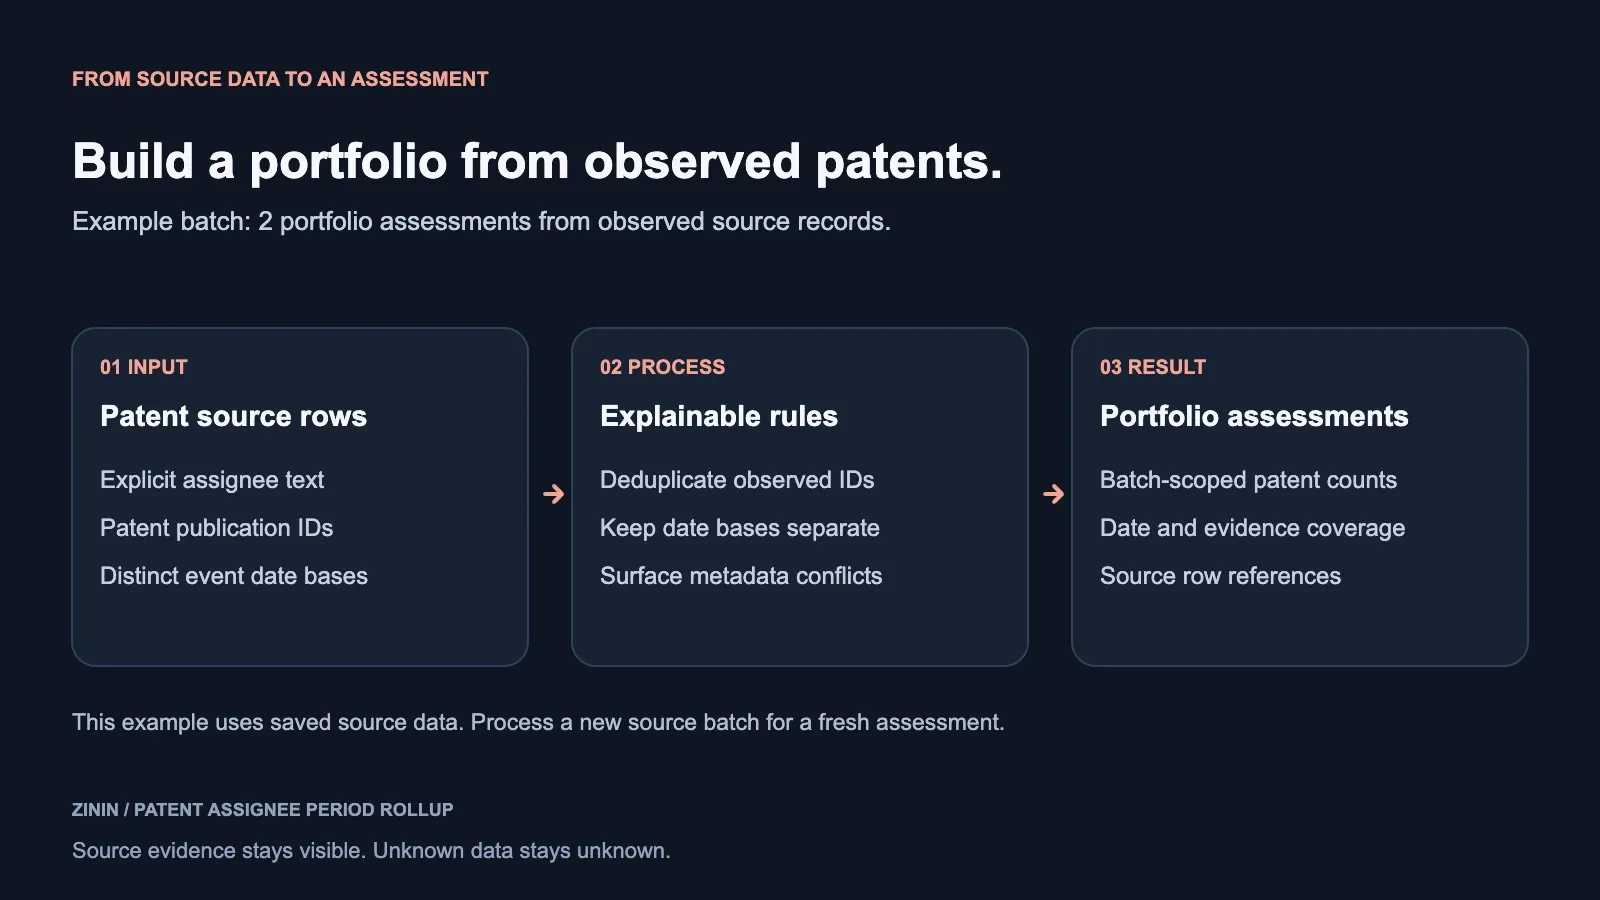
Feed this Actor a batch of patent rows from your own zinin/patent-monitor watch, a Google-Patents-shaped scraper run, or a hand-built inline list combining both, and it returns one deduplicated portfolio assessment per literal assignee name — distinct patent counts, five separate date-basis period counts with yearly buckets, co-observation disclosure, missing-metadata coverage, and exact record-conflict counts — so you can see, in minutes, which assignee's filings actually agree across your sources and which need a human to reconcile before anyone relies on the batch.
What you get
You give this Actor a dataset (or an inline list) of patent-record rows. It never scrapes, never calls a model, and never guesses — it reads exactly the rows you supply and reports, per literal assignee name, a portfolio assessment: a single deduplicated view of that assignee's patents inside the batch, with every count traceable back to the specific source row that produced it.
Concretely, for each assignee observed in your batch, you receive:
distinctPatentCount— how many unique, syntactically validpatentIdvalues this assignee's rows contained. Two rows for the same patent are one patent, not two. A row whosepatentIddoesn't match a real publication-number syntax (US, JP and other supported office prefixes) is excluded entirely and reported as a freeinvalid_patent_iddiagnostic instead — it never becomes a paid portfolio member.coObservedPatentCount— of those patents, how many were also observed under a different assignee spelling elsewhere in the same batch. This is disclosure of a fact your batch actually contains, never a claim about fractional or joint legal ownership.datePeriodCounts— five fully separate date bases:patentDate(the single date fieldzinin/patent-monitorrows carry) andfilingDate,publicationDate,grantDate,priorityDate(the four distinct legal milestones Google-Patents-shaped rows carry). Each basis reports{ count, earliest, latest, yearlyBuckets }, whereyearlyBucketsis a{ "YYYY": distinctPatentCount }map deduping a patent to at most one count per calendar year it has a known value for in that basis. These five bases are never merged into one generic "date": a row supplying onlyfilingDatenever contributes topatentDate's count.missingMetadataCounts— fortitle,url,jurisdiction,recordStatus, and each date basis, exactly how many distinct patents never carried a usable value for that field. Absence is stated explicitly; never silently treated as zero, never treated as a negative claim about the real patent.recordConflicts— a bounded list (cap 10, with an exactrecordConflictsOmittedcount) of cases where the samepatentIdunder the same assignee was observed with more than one distinct non-empty value for its title or a given date basis across duplicate rows. This is disagreement your own supplied data actually contains, not an interpretation layered on top of it.evidence— a bounded list (cap 12, with an exactevidenceOmittedcount) of sample patents backing the portfolio, each carrying its own retained source URL when the source row supplied one, and acoObservedflag.observedAtandsourceObservationWindow— the real latest (and earliest, for the window) strictly-validcheckedAt/scrapedAtcapture timestamp across contributing rows, compared by its true normalized instant (UTC-offset aware, not lexical string order). A source capture time, never a patent event date, never fabricated as "now."
What this Actor deliberately does not do, so you never mistake a convenience rollup for a legal or market conclusion:
- It does not merge differently-spelled assignee names into one corporate family.
"Example Energy Systems Inc."and"Example Energy Systems, Inc."are two separate portfolios, exactly as your source data spelled them — corporate-family resolution is a separate step you run before or after this Actor. - It does not claim market share, filing velocity, growth, or an exhaustive view of any assignee's real-world patent holdings. Every count is scoped explicitly to "what this batch contained," never to "what this assignee owns."
- It does not treat a source row's own capture timestamp (
checkedAt/scrapedAt) as a patent event date, and it never invents "now" as an observation time when no row actually carried one. - It does not call any network, AI model, or system clock from inside its transform step. Every number in the output traces back to a field on a row you supplied.
- It does not launch
zinin/patent-monitor, a Google Patents scraper, or any other upstream Actor on your behalf. It never starts new scraping work, and it never combines multiple dataset IDs automatically on a single run.
Who uses it
- IP paralegals and patent operations analysts who already run
zinin/patent-monitoror a Google Patents scraper on a watch list of assignees and need a fast, honest rollup before a status memo — without opening a spreadsheet and manually deduplicating rows by hand every week. - Competitive-intelligence and R&D strategy teams tracking a competitor's filings across quarters, who want distinct patent counts and yearly buckets per date basis rather than a raw row count that double-counts every patent scraped twice.
- M&A and diligence support staff doing a first-pass sanity check on a target company's patent batch — surfacing missing metadata and duplicate-row conflicts before they get escalated to outside patent counsel, so counsel's time goes to genuine legal questions rather than data-hygiene ones.
- Data engineers building an internal IP dashboard who need a dependable, pure post-processing step between a scraper's raw output and a BI table — one that never silently drops a disagreement between two duplicate rows and always tells you exactly how many results were capped.
- Search-term note for assignee/portfolio watch teams: if your own search vocabulary uses terms like "patent portfolio tracker", "patent assignee report", "patent filing rollup by company", "US and JP publication number validation", or the Japanese publication-number families this Actor already validates (
JPS,JPH,JPWOprefixes, e.g.JPS639877A,JPWO2014203654A1), this Actor's identity rules and date-basis separation apply directly to that batch without any extra configuration.
How to run
- Open the Apify Console and start a new run of Patent Assignee Period Rollup.
- Choose a source, in order of precedence (an explicit dataset always wins over a run reference, which always wins over the inline example — a dataset/run source never merges with inline rows):
- Source Dataset (
datasetId) — point at an existing Dataset from a priorzinin/patent-monitoror Google-Patents-style scraper run. Read with your own run's granted permissions; no elevated access is used. - Source run ID (
runId) — supply a run ID instead, if you have one but not its Dataset ID directly; its default Dataset is resolved automatically. - Integration payload (
payload.resource) — set automatically by Apify's Integrations "Actor/task run" template when you chain this Actor after an upstream scraper; carries{{resource.defaultDatasetId}}/{{resource.id}}/{{resource.actId}}so no manual mapping is needed. - Source records (inline) — paste or edit rows directly, or leave the prefilled real public sample in place for a first test run: a curated projection of an actual public
zinin/patent-monitorrun plus two actualkhadinakbar/google-patents-scraperrows.
- Source Dataset (
- Optionally set Max source rows (
maxInputRows, default 100, up to 1000) and Max results (maxResults, default 2, up to 1000). The platform's own Max total charge USD run option is a separate, independent stop: whichever limit is hit first ends delivery. - Run it. Delivered rows land in the run's default Dataset, one per assignee, each carrying
sourceRowIndexesback into your original batch so you can trace any figure to its source rows. - Read
partialand the summary'sresultsCapped/sourcePartialflags before treating a run as a complete picture of your batch — see Evidence and boundaries for exactly when those flags are set and why.
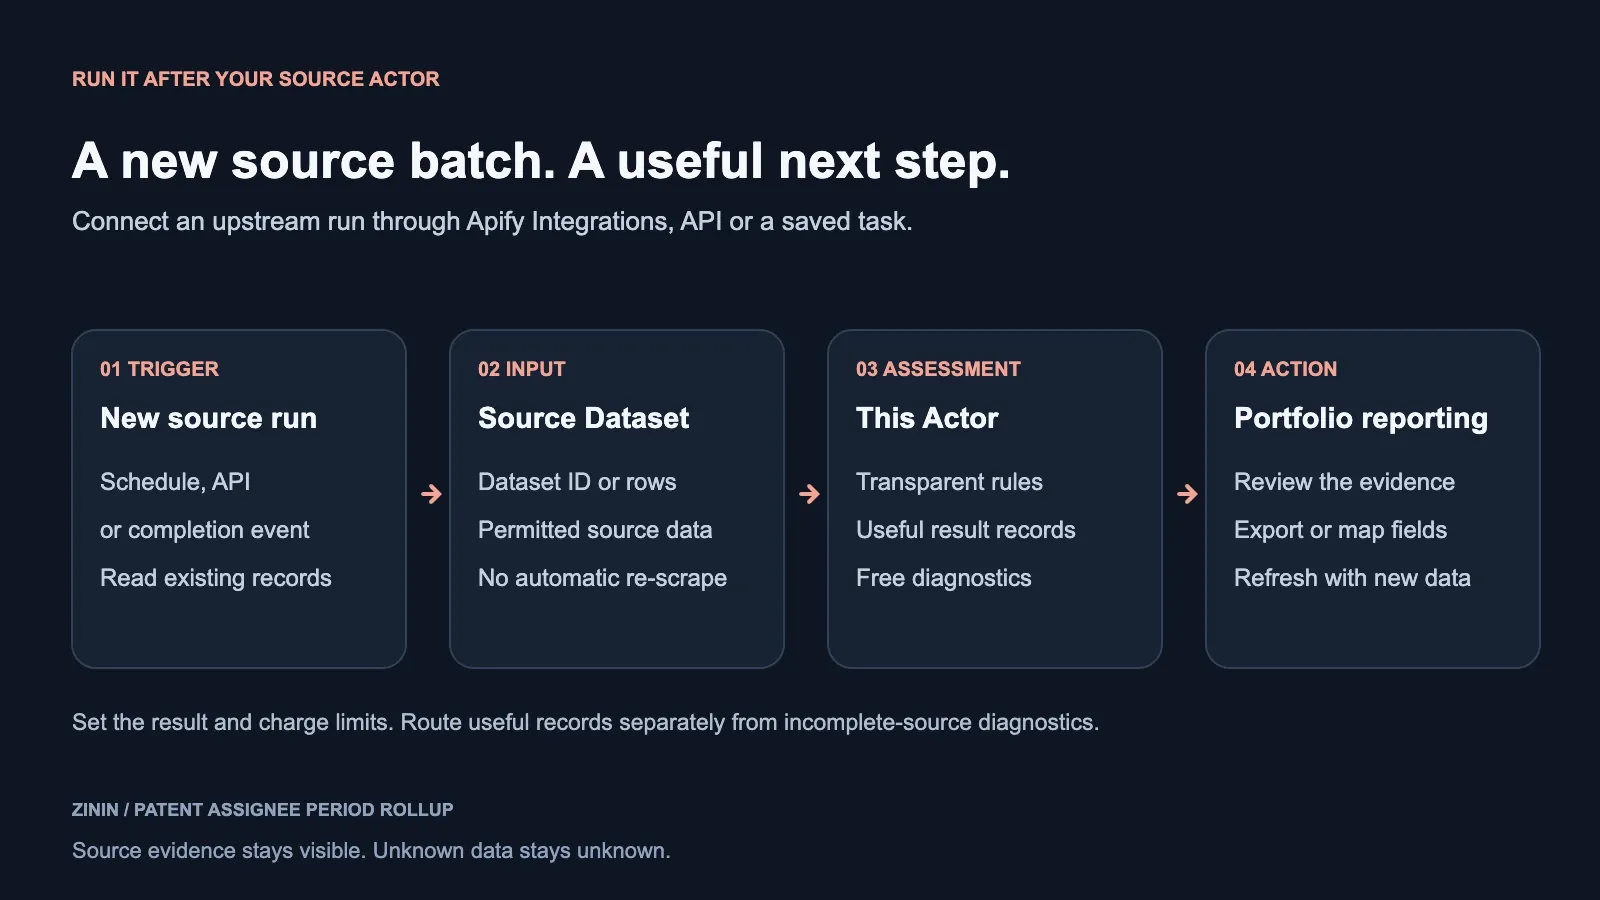
For a repeatable pipeline (e.g. a weekly assignee-watch refresh), save this configuration as an Apify Task and chain it after your zinin/patent-monitor or Google Patents scraper run via Apify's Integrations, or trigger it from your own system via the API — see Integration recipes below for both paths with the exact chaining fields.
Pricing
This Actor bills on the Apify Pay-Per-Event model under a single primary event, result-found — described to buyers under the pricing noun "portfolio assessment." There is no start fee and no per-row or per-patent charge: only a delivered, useful portfolio assessment is billed. Free diagnostics (invalid rows, missing assignee, missing/invalid patent ID, source failures, budget stops, empty-batch outcomes) never request the paid event and are never charged.
| Tier | Price per portfolio assessment |
|---|---|
| Free | $0.0350 |
| Bronze | $0.0315 |
| Silver | $0.0280 |
| Gold | $0.0245 |
| Platinum | $0.0245 |
| Diamond | $0.0245 |
Bronze, Silver and Gold apply Apify's standard 10%/20%/30% volume discounts off the Free-tier price; Platinum and Diamond are held at the Gold rate. There is no owner-run revenue claim and no guarantee of any particular run volume in this pricing table — it states only the price actually configured on this Actor's result-found event, verified against the live Actor record at publication time.
A useful portfolio assessment is a real aggregate result — a deduplicated per-assignee rollup with at least one distinct patent and populated evidence — never a raw source row passed through unprocessed. A partial: true portfolio assessment (for example, one delivered while maxInputRows cut off part of your batch) is still a useful aggregate and is still billed; only genuinely empty, invalid, or source-failure outcomes are free. See Evidence and boundaries for the exact delivery-and-charging mechanics, including why a new run of this Actor against identical input can bill again.
Input contract
This Actor's input schema is deliberately small: a source selector plus two bounds. There are no product-specific configuration fields beyond the shared source contract — the whole surface area is "which rows, how many of them, how many results."
This example is a trimmed projection of the Actor's own real prefill (the full prefill also includes a khadinakbar/google-patents-scraper row for US10000001B2 / LS Mtron Ltd, plus each row's __source provenance block and the scraper rows' full cpc/citation arrays, read but ignored by this Actor's transform — see the row-shape table below). Every patentId, assignee, and date in the prefill is a real value observed from a real upstream run, not synthetic fixture data.
| Field | Type | Notes |
|---|---|---|
items | array, optional | Inline source rows. Ignored if datasetId or a resolvable runId/payload.resource is present. Bounded to 1000 rows / 4 MiB total / 64 KiB per row. |
datasetId | string, optional | Reads an existing Dataset with your run's own granted permissions (resourcePicker, READ). Overrides inline items. For Integrations, map {{resource.defaultDatasetId}} here. |
runId | string, optional | Reads a run's default Dataset when you have a run ID but not its Dataset ID directly. No elevated access — the run's own default Dataset is resolved and read exactly as datasetId would be. |
payload | object, optional | Set automatically by Apify's Integrations "Actor/task run" template; carries resource.id / resource.defaultDatasetId / resource.actId. A raw webhook envelope alone does not grant private Dataset access — the resourcePicker's own READ grant does that. |
maxInputRows | integer, default 100, max 1000 | Hard cap on source rows read for this run, independent of maxResults. |
maxResults | integer, default 2, max 1000 | Hard cap on paid portfolio assessments delivered this run. Free diagnostics are never counted against this cap. |
Recognized row shapes
| Field | Which source carries it | Role in the rollup |
|---|---|---|
assignee | both | Identity — literal text, whitespace-normalized (trim + collapse internal runs), the sole grouping key |
patentId | both | Identity — validated against a real publication-number syntax; unrecognized forms are a free diagnostic |
title | both | Display and title-conflict detection |
url / googlePatentsUrl | both | Display — retained verbatim into evidence[].url, never re-derived |
jurisdiction / countryCode | both | Display only, not identity |
recordStatus / status | both | Display only, not identity |
patentDate | zinin/patent-monitor | Date basis 1 of 5 |
filingDate | Google-Patents-shaped | Date basis 2 of 5 |
publicationDate | Google-Patents-shaped | Date basis 3 of 5 |
grantDate | Google-Patents-shaped | Date basis 4 of 5 |
priorityDate | Google-Patents-shaped | Date basis 5 of 5 |
checkedAt / scrapedAt | either | Source capture timestamp, feeds observedAt/sourceObservationWindow, never an event date |
Any other field present on a row — cpc, citationsBackward, citationsForward, abstractSnippet, decision, confidence, freshness, and similar fields real zinin/patent-monitor or Google-Patents-shaped rows may carry — is read as part of the row but is never surfaced in the output and never used to infer anything: it is simply not part of this Actor's rollup contract.
Output examples
Every delivered row and diagnostic below is copied verbatim from an actual private cloud canary run of this Actor's value-add-candidate build (build 0.1.1), never hand-written. Field order and values match the real Dataset item exactly.
Happy path — a delivered portfolio assessment
Real run against the prefilled three-row public sample with maxResults: 2 (so the run also produced a max_results_reached diagnostic after two portfolio assessments — the assignee row below is the first of those two):
Notice missingMetadataCounts.patentDate is 0 (patent-monitor supplied it) while filingDate/publicationDate/grantDate/priorityDate are each 1 — this assignee's single patent simply never carried those Google-Patents-specific bases, and the Actor reports that absence explicitly rather than silently treating it as zero coverage. The run's summary for this exact call reported "requested": 3, "usefulResults": 3, "delivered": 2, "paid": 2, "free": 1, "resultsCapped": true, "partialOverall": true" — a real, honest example of maxResults capping a batch that had one more useful assignee than the run was configured to pay for.
Partial path — a real maxInputRows cutoff, with a genuinely delivered result
Real run against the same three-row batch with maxInputRows: 1 (so only the batch's first row was read at all) and maxResults: 2:
This row is identical to the happy-path row above in every field except partial and sourceCoverage, because the one row this narrower run actually read was the same first row. Those two changed fields say explicitly that this Actor never read your batch's two remaining real rows (the two Google-Patents-shaped patents) this run — not deleted, corrupted, or degraded, simply outside the row window you configured. The run also emitted a separate free partial_source diagnostic ("reason": "max_input_rows_reached") alongside this delivered row. If your batch legitimately has more than maxInputRows rows, raise the limit (up to 1000) rather than relying on this Actor to see rows it was never given.
Failure path — the platform's own charge limit stops delivery before any row is read
Real run with the platform's Max total charge USD run option set to $0.005 — below the configured $0.035 Free-tier price of a single portfolio assessment:
This diagnostic is free — chargedEventCounts.result-found was 0 on the real run terminal record. Critically, the Actor checks whether the run's own charge limit can cover even a single result before reading any source rows, so a misconfigured (too-low) Max total charge USD fails safely and instantly rather than partially reading your batch and then stalling mid-run.
Empty-source path — a batch with nothing usable in it
Real run with items: [] (an explicitly empty inline batch):
Also free. sourceCoverage.complete: true here means exactly what it says: the Actor read the entire (empty) batch you supplied — the emptiness is a fact about your input, not a read failure on the Actor's part.
Field dictionary
| Field | Meaning |
|---|---|
entityId | assignee:<literal assignee text> — a stable identity string for this delivered row. |
found | true for a useful result eligible for the result-found event; every free diagnostic row has found: false. |
status | assignee_portfolio_rollup for a delivered row; otherwise a diagnostic status listed under Evidence and boundaries. |
action | review_portfolio on a delivered row — a routing hint, never an automated legal or business decision. |
confidence | high, medium, or low — see Decision routing for the exact rule. |
sourceRowCount | How many source rows contributed to this portfolio (may exceed distinctPatentCount when duplicate rows repeat the same patent). |
assignee | The literal, whitespace-normalized assignee text — the grouping key, unchanged from your source spelling. |
distinctPatentCount | Unique, syntactically valid patentId values for this assignee in the batch. Never a claim of the assignee's complete real-world portfolio. |
coObservedPatentCount | Of those, how many were also observed under a different assignee spelling elsewhere in the batch. |
datePeriodCounts.{patentDate,filingDate,publicationDate,grantDate,priorityDate} | { count, earliest, latest, yearlyBuckets } per basis — five fully independent objects, never merged. earliest/latest are raw date strings, never re-derived. yearlyBuckets is { "YYYY": distinctPatentCount }. |
missingMetadataCounts | { title, url, jurisdiction, recordStatus, ...each date basis } — how many distinct patents never carried a usable value for each field. |
recordConflicts | Bounded list (cap 10) of { patentId, field, values, sourceRowIndexes } — duplicate rows disagreeing on title or a date basis. |
recordConflictCount | The exact total conflicts found, independent of the displayed list's 10-item cap. |
recordConflictsOmitted | recordConflictCount minus recordConflicts.length. 0 when nothing was omitted. |
evidence | Bounded list (cap 12) of { field: "patentId", value, title, url, coObserved, sourceRowIndex } sample patents. |
evidenceOmitted | distinctPatentCount minus evidence.length. 0 when nothing was omitted. |
observedAt | The real latest strictly-valid capture timestamp (checkedAt/scrapedAt), compared by normalized instant. A capture time, never a patent event date, never "now." null when no row carried one. |
sourceObservationWindow | { earliest, latest, validCount, totalRowCount } across every accepted row — raw capture strings, never re-derived. |
businessPartial | Product-level incompleteness: contributing source rows marked partial, capped evidence/conflicts, or capped source-row indexes. Runtime partial also includes source-reader limits. It is false in the displayed clean examples, not universally. |
sourceRowIndexes | The specific offsets into your original batch that produced this row. |
partial | true when evidence/conflicts were capped, a contributing row itself reported partial: true, or the configured row window wasn't fully read. |
sourceCoverage | { complete, reason, droppedOversized } — whether the reader established the end of the supplied source, including a bounded probe when a row limit was reached. |
product / schemaVersion | Fixed identifiers ("patent-assignee-period-rollup" / "1.0") for schema pinning. |
sourceDatasetId / sourceRunId / suppliedSourceRunId / sourceRunIdVerified | Provenance for a dataset/run-sourced batch — null on an inline-items run. |
processedAt | When this Actor processed the row — never a patent event date or source capture time. |
Diagnostics (never billed) share a smaller, honest shape: { product, schemaVersion, status, found: false, reason, sourceRowIndexes? }, with status one of invalid_row, source_row_failed, missing_assignee, missing_patent_id, invalid_patent_id, no_results, budget_stopped, partial_source, or the run-level max_results_reached summary row.
Evidence and boundaries
What "found" actually means here. A delivered portfolio assessment requires found: true with a nonempty assignee, at least one distinct valid patentId, and populated evidence — this Actor never fabricates a paid result from a batch that contained nothing usable for a given assignee.
Diagnostics carry no result event. Rejected rows produce statuses in the transform; delivery retains at most 200 diagnostic rows and reports truncation or oversized omissions in the summary. Typical statuses are: invalid_row (not an object), source_row_failed (the source itself reported found: false, failed: true, or a failure-shaped status/error), missing_assignee (no usable assignee text), missing_patent_id (no patentId at all), or invalid_patent_id (a patentId that doesn't match a supported real publication-number syntax). None of these can become a paid portfolio member.
Why maxInputRows/maxResults caps and platform charge limits interact the way they do. This Actor reads at most maxInputRows source rows and delivers at most maxResults paid portfolio assessments, independent of each other and both independent of the platform's own Max total charge USD run option — whichever bound is hit first ends delivery, and the delivered row(s) or diagnostic tell you exactly which one it was (max_input_rows_reached, max_results_reached, or budget_stopped). Before reading any source row, the Actor verifies the run's charge limit can cover at least one portfolio assessment at the confirmed live price; if it cannot, the run stops immediately with the free budget_stopped diagnostic shown above rather than reading part of your batch and then stalling.
Delivery is a dataset write, then an explicit charge — never the reverse, and never guaranteed exactly-once. Every delivered portfolio assessment is written to your run's Dataset before the corresponding result-found charge event is requested, and the two steps are not transactional. On any ambiguity about whether a write or a charge actually completed, this Actor fails closed rather than guessing — it never automatically retries a possibly-already-charged write, because a retry could double it. A run that fails partway through may still contain already-delivered, already-charged rows; that is expected behavior for a partial run, not a bug.
Re-running is new processing, not deduplication. This Actor's own-run guard only prevents an automatic resurrection of a run that already started paid work (for example, after a platform restart) — it is not a cross-run deduplication layer. Running this Actor again against the exact same input performs genuinely new processing and can bill again for the same assignees. If you need to avoid double-billing across scheduled refreshes, dedupe on your own side using assignee + observedAt, or only re-run against genuinely new upstream data.
Source resolution precedence and permissions. When both an explicit datasetId/runId and an Integrations payload.resource reference are present, they must agree — a mismatch is rejected outright. A runId (explicit or from payload.resource.id) is read with your own run's own granted permissions; no elevated access is used, and no upstream Actor is ever started. The Source Dataset field uses Apify's resourcePicker with an explicit READ-only grant — that grant, not the mere presence of a webhook payload, is what allows this Actor to read a private Dataset. A bare webhook envelope alone never grants private Dataset access on its own. Source resolution uses read-only GET requests against the fixed https://api.apify.com origin. Dataset output and billing use the Apify SDK and perform writes. Credentials belong in Authorization headers, never in URL query strings or inline source records.
Bounded everything, always. 1000 source rows / 4 MiB total input / 64 KiB per source row, per run. evidence is capped at 12 sample patents per assignee, recordConflicts at 10 — both with an exact omitted count and a partial: true flag when more exist than shown. recordConflictCount/evidenceOmitted are always an independent running total across your entire accepted batch, never approximated from the displayed list's length.
What this Actor cannot verify. It cannot confirm a real patent registry record exists behind a syntactically valid patentId — validation is against the format of real publication-number syntaxes, never a registry lookup. It cannot tell you whether two differently-spelled assignees are legally the same company, or whether a patent is valid, enforceable, or currently in force. None of these are claimed anywhere in this Actor's output.
Decision routing
confidence is set by one deterministic rule, applied per assignee, after the full batch for that assignee has been aggregated:
lowwheneverrecordConflictCount > 0for that assignee — i.e. at least one duplicate-row disagreement on a title or date-basis value was found anywhere in that assignee's patents. A conflict is a fact about your own data, and it always overrides the other two levels regardless of how much date coverage exists.highwhen there are no conflicts and at least one of the five date bases hascount > 0for that assignee — meaning at least one distinct patent carried a usable date value in some basis.mediumwhen there are no conflicts but none of the five date bases has any coverage at all — every distinct patent for this assignee is missing every date field this Actor recognizes.
Route accordingly:
confidence: "low"→ send to manual reconciliation before using any count from this assignee's portfolio in a report. ReadrecordConflicts(and request the full list via a follow-up run with a narrower batch ifrecordConflictsOmitted > 0) to find the exactpatentId/field/rows that disagree, and resolve at the source before re-trusting the aggregate.confidence: "high"→ safe to surface directly in an internal dashboard or status memo, with the usual caveat thatdistinctPatentCountdescribes the batch, not the assignee's real-world holdings.confidence: "medium"→ treat as a coverage gap, not a data-quality problem: your source rows for this assignee simply never carried usable dates. CheckmissingMetadataCountsto see which specific date basis is absent, and consider re-scraping with a source that supplies it if date coverage matters for your use case.
partial: true is an orthogonal signal from confidence — it tells you the displayed lists (evidence, conflicts) were capped, or that your configured row window wasn't fully read this run, not that the underlying assessment is untrustworthy. A high-confidence, partial: true row may be shown only with its coverage warning: omitted or unread evidence can contain further conflicts, and high confidence does not certify completeness.
Commercial playbooks
Weekly assignee-watch digest. Chain zinin/patent-monitor (or your Google Patents scraper) → this Actor, scheduled weekly via an Apify Task. Route confidence: "low" rows to a Slack/email digest tagged "needs review" and confidence: "high" rows straight into your internal filing tracker. Compare datePeriodCounts.patentDate.yearlyBuckets across successive weeks to see period coverage shift — the trend lives in your own comparison across runs, not inside this Actor.
Pre-diligence patent-batch sanity check. Before a target company's patent list goes to outside counsel for a real freedom-to-operate or portfolio-value opinion, run it through this Actor first. recordConflicts and missingMetadataCounts surface exactly the data-hygiene issues that would otherwise cost billable attorney hours to notice manually — resolve those first, then send the cleaned batch onward.
Competitive filing-cadence snapshot. Feed a competitor's known patent rows through this Actor quarterly. datePeriodCounts.filingDate/publicationDate/grantDate yearly buckets give an honest, source-scoped view of when their observed activity clustered — one input into a broader competitive-intelligence memo, never a standalone market-share claim.
Internal IP-ops data-quality gate. Insert this Actor as a validation step immediately after any patent scraper in your pipeline, before rows reach your BI warehouse. A confidence: "low" result blocks that assignee's batch from loading until a human resolves the conflict — a cheap, deterministic gate against the kind of duplicate-row disagreement that silently corrupts a downstream count table.
Integration recipes
Chained via Apify Integrations (recommended for scheduled pipelines). In the Apify Console, open your zinin/patent-monitor (or Google Patents scraper) Task, add an "Actor/task run" integration pointed at this Actor, and map the upstream run's {{resource.defaultDatasetId}} into this Actor's Source Dataset field and keep any webhook envelope consistent with that explicit reference. The integration must actually supply the reference; the Actor does not invent or automatically populate a webhook envelope. A readable run record is checked for correspondence. If that metadata is unavailable but the explicit Dataset is readable, processing may continue with sourceRunIdVerified: false; it never claims the run link was verified.
Direct API call. Start a run via POST https://api.apify.com/v2/acts/zinin~patent-assignee-period-rollup/runs?maxTotalChargeUsd=0.50 with your Authorization header, passing { "datasetId": "<upstream dataset id>", "maxInputRows": 200, "maxResults": 10 } as the JSON body. Poll GET /v2/actor-runs/<runId> for status: "SUCCEEDED", then read GET /v2/datasets/<defaultDatasetId>/items for the delivered rows.
Webhook-notified pipeline. Attach an Apify webhook to this Actor for ACTOR.RUN.SUCCEEDED, pointed at your own endpoint. The webhook payload itself never grants elevated access to the run's Dataset — treat it as a "go read the Dataset now" signal, and fetch rows via the Dataset API using your own stored token. Define the webhook with doNotRetry: true and never embed a customer credential in its configuration.
MCP / agent tool use. Pass the same datasetId/runId/items + maxInputRows/maxResults shape as any other caller. Surface confidence, partial, and recordConflicts directly to the end user rather than only the aggregate counts. They describe supplied evidence and route review; they do not certify real-world ownership or completeness.
The following webhook registration is a template, not a captured dispatch. Substitute your upstream Actor ID and configure the destination’s Dataset READ grant. A header placeholder is not a usable credential. The automatic mapping does not itself grant access.
Finalization attempts to save OUTPUT and SUMMARY; storage failures can prevent either record from being saved. After an ambiguous write or charge, raw Dataset rows may exceed confirmed summary counters. Inspect the platform event counters before deciding to rerun.
Operating guide
- Start with the real prefill. Run it once against the prefilled sample to confirm the delivered shape and confidence rule match your expectations — it costs the price of two portfolio assessments (or less, at your account's tier) and uses genuinely real, previously-observed public data.
- Set
maxInputRowsto your batch's real size, not the default. The default of 100 exists for a safe first test; a genuine assignee-watch batch may be larger. Under-setting this silently caps coverage (visible viasourceCoverage.reason: "max_input_rows_reached"andpartial: true) — it does not fail the run, so watch for that flag rather than assuming aSUCCEEDEDrun read everything. - Set
maxResultsto your real number of distinct assignees, not the default of 2. A real watch list with a dozen tracked assignees needsmaxResultsraised accordingly, or you will seemax_results_reachedand only get a partial set back. - Always set the platform's own Max total charge USD for any run touching a batch you have not sized before — a cap below one result stops before source reads, while a cap covering only part of a batch can deliver that part and then stop. Inspect paid/free and budgetStopped counters.
- Treat
recordConflictsas a to-do list, not noise. Every conflict is a real disagreement your own upstream source(s) produced — most commonly the same patent scraped twice with a title or date that changed between scrapes. Resolve at the source rather than silently trusting whichever value was observed first. - Do not rely on a single run for a moving batch. Schedule this Actor to run on a cadence rather than treating one run's output as a permanent snapshot —
observedAtandsourceObservationWindowon each row tell downstream consumers exactly how fresh that assessment was. - Keep an eye on
coObservedPatentCount. A nonzero value signals a spelling inconsistency or a genuine co-assignment worth a closer look; it will not resolve itself without a corporate-family-resolution step or a source-data fix.
FAQ
Does this Actor scrape any patent data itself?
No. It is a pure post-processing rollup over rows you already have — from your own zinin/patent-monitor, a Google Patents scraper, or a hand-built list. It never launches an upstream Actor and never fetches anything from patents.google.com or any registry directly.
Why are patentDate and filingDate/publicationDate/grantDate/priorityDate kept separate instead of one "date" field?
Because they mean different, legally distinct things, and merging them would silently misrepresent your data. zinin/patent-monitor rows only ever carry patentDate; Google-Patents-shaped rows carry the other four as genuinely separate legal milestones. Reporting five independent bases, each honestly 0-covered when a row didn't supply it, avoids fabricating a date basis a row never had.
Why did my batch's assignee names come back as two separate portfolios when they're really the same company?
Because this Actor's identity rule is deliberately literal: only whitespace trimming and internal-run collapsing are applied, never case-folding, fuzzy matching, or corporate-suffix stripping. "Acme Inc." and "ACME, Inc." are two rows in the output by design — corporate-family resolution requires business-entity knowledge this Actor deliberately does not embed.
My patentId looks valid to me, but it came back as an invalid_patent_id diagnostic instead of a result. Why?
The Actor validates against a specific, real publication-number grammar (country/office prefix, optional US RE/D/PP series or a JPS/JPH/JPWO Japanese-office prefix, digits, kind-code letter, optional trailing digits) defined by this Actor’s source contract. An ID that doesn't match this real grammar — a typo, a placeholder string, or an unsupported office format — is rejected rather than accepted as an opaque string, because accepting arbitrary text as a "patent identity" would let unrelated garbage strings masquerade as distinct patents.
What happens if I supply both a datasetId and a runId that don't actually correspond to each other?
When accessible run metadata proves the references disagree, the run returns INVALID_INPUT / run_dataset_mismatch before reading source rows. If the run metadata is unavailable but the explicit Dataset can be read, the Dataset remains the selected source and run provenance is explicitly unverified.
Can I get more than 12 sample patents or 10 conflicts per assignee in one run's output?
Not in a single delivered row — those caps keep each row's payload bounded and predictable. evidenceOmitted/recordConflictsOmitted always tell you the exact count beyond the cap; if you need further evidence, partition the source rows for that assignee into smaller batches and inspect omitted counts on each. A single-assignee filter alone does not remove per-assignee caps. Do not sum overlapping partitions without deduplicating patent identities.
Will running this Actor again on the same dataset cost me twice?
Yes, if the same assignees still qualify as useful portfolio assessments. This Actor has no cross-run deduplication, only a same-run resurrection guard. Build your own dedupe key (assignee + observedAt) on your side for a recurring schedule against overlapping data.
Is a high confidence a claim that these patents are real, valid, or currently in force?
No. confidence describes evidence coverage and internal consistency within your supplied batch only. It is never a claim about legal validity, enforceability, ownership, or any registry-verified fact.
Sources and rights
This Actor processes only patent-record rows you supply — your own zinin/patent-monitor runs, a Google-Patents-shaped scraper's output (such as khadinakbar/google-patents-scraper), or any hand-built inline list following the recognized row shapes above. It holds no scraping rights or licensing relationship of its own with any patent registry or database; you remain responsible for the terms under which your source data was originally obtained.
Related public Store Actors referenced or usable alongside this one, identified in the saved Apify Store research and public Actor metadata captured on 2026-09-23:
zinin/patent-monitor— the primary own-ecosystem upstream source for this Actor'spatentDate-basis rows.khadinakbar/google-patents-scraper— Google Patents Scraper, the primary external source for this Actor'sfilingDate/publicationDate/grantDate/priorityDate-basis rows.
Public examples in this Actor's prefill and in this README are curated, provenance-tagged projections of actual public source runs, never synthetic fixtures — every value traces back to a real upstream Actor, run, and Dataset recorded in the row's own __source block. The saved public examples omit dates of birth, home addresses, nationality, and personal contact details. Fields supplied in your own records remain your responsibility, consistent with the business-record-only scope of the rows it processes.
zinin/company-registry-enricher— separate corporate context for an analyst reviewing an assignee name; registry rows are not patent input and do not establish that similarly named assignees are the same legal entity.zinin/funding-round-tracker— separate filing context for company research; funding records are not patent input and neither imply patent ownership nor validate portfolio value.


