
PII Masker — Redact CPF, CNPJ, Emails, Phones, Names (LGPD)
Pricing
from $0.35 / 1,000 record processeds
PII Masker — Redact CPF, CNPJ, Emails, Phones, Names (LGPD)
Find and mask personal data in texts, JSON or any Apify dataset: CPF, CNPJ (incl. alphanumeric), e-mails, phones, cards, IBAN, IPs and names. Redact, mask, partial or hash. Check-digit validated. LGPD/GDPR ready.
Pricing
from $0.35 / 1,000 record processeds
Rating
0.0
(0)
Developer

Leandro Zanatta
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
14 days ago
Last modified
Categories
Share
PII Masker — Redact CPF, CNPJ, E-mails, Phones & Names (LGPD / GDPR)
Find and hide personal data in texts, JSON records or any Apify dataset in one call. Detects Brazilian documents (CPF, CNPJ including the new alphanumeric format, PIS, RG, CEP, license plates) and international data (e-mails, phone numbers, credit cards, IBAN, IP addresses), plus person names with a small language model. Choose how to hide them: redact, mask, partial or hash (consistent pseudonyms).
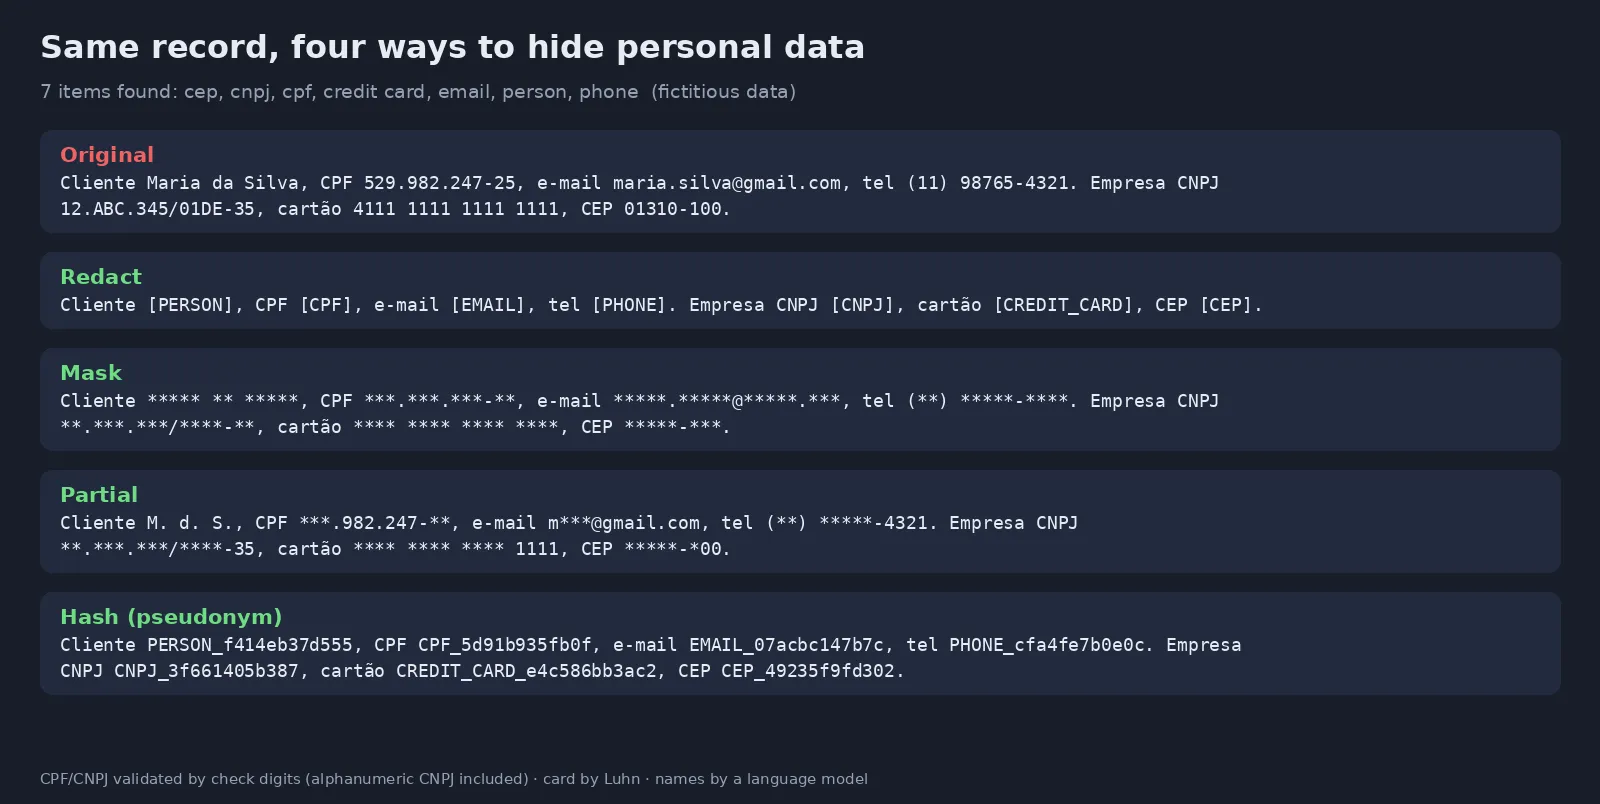
Real output of this Actor on fictitious data.
Why use it
- ✅ Fewer false alarms: CPF, CNPJ and PIS are validated by their check digits, cards by the Luhn algorithm and IBANs by mod-97. Order numbers, prices, dates, barcodes and protocol numbers are left alone.
- 🇧🇷 Built for Brazil (LGPD): CPF, CNPJ (numeric and the alphanumeric CNPJ in use since July 2026), PIS/PASEP/NIS, RG, CEP and Mercosur plates, in all their usual formats.
- 🧩 Keeps your data usable: JSON structure stays the same; only the sensitive values change. Hash turns each value into the same token every time, so you can still count, group and join records.
- 🔗 Plugs into any scraper: give it a dataset ID and it cleans the whole output of another Apify run, ready to share or load into BI and AI tools.
- 🤖 Safer AI: strip personal data before sending tickets, chats or documents to an LLM, a vector database or a third-party API.
- 🔒 Runs inside the Actor: no external AI or API is called; nothing is logged.
Who uses it
| Sector | Typical use |
|---|---|
| Companies under LGPD / GDPR | Anonymize exports before sharing with partners, vendors or analytics teams |
| Customer support & CX | Clean tickets, chats and call transcripts before analysis or AI training |
| Data & AI teams | Remove PII from datasets before LLM fine-tuning, RAG or vector search |
| Developers & QA | Turn production data into safe test data, keeping formats and joins |
| Scraping & lead workflows | Mask personal fields in scraped data before storage or resale of aggregated insights |
| Legal, health & finance | Prepare documents and records for audits, research and data-subject requests |
What it detects
| Type | Examples | Validation |
|---|---|---|
| CPF | 529.982.247-25, 52998224725 | Check digits; unformatted numbers only with "CPF" or a matching field name nearby |
| CNPJ | 11.222.333/0001-81, 12.ABC.345/01DE-35 | Check digits, numeric and alphanumeric |
| PIS / PASEP / NIS | 120.12345.67-2 | Check digit |
| RG | RG: 12.345.678-9 | Needs an "RG / identidade" label (no national check digit) |
maria@empresa.com.br | Format | |
| Phone | (11) 98765-4321, +55 21 99876-5432, 0800 123 4567, +1 415 555 2671 | Format; not part of longer codes |
| Credit card | 4111 1111 1111 1111, 3782 822463 10005 | Luhn + card formats; barcodes and order numbers ignored |
| IBAN | GB82 WEST 1234 5698 7654 32 | mod-97 |
| IP address | 192.168.0.12, IPv6 | Valid ranges; "version 10.2.3.4" ignored |
| CEP | 01310-100 | Format with hyphen |
| License plate (BR) | ABC1D23, ABC-1234 | Old and Mercosur formats |
| Person name | Maria da Silva, John Smith | Language model (Portuguese and English) |
Measured on 500 synthetic texts mixing real-format documents with order numbers, prices, dates, barcodes and protocol codes: 100% of CPF, CNPJ, card, phone, e-mail, CEP, IP and plate values found, 0 false positives. Person names: 96% found in 200 simple Portuguese and English sentences, with no city, street or company names flagged. Real texts are messier than test data; review a sample for critical uses.
Masking methods
| Method | CPF 529.982.247-25 becomes | Best for |
|---|---|---|
| Redact (default) | CPF [CPF] | Sharing, AI prompts, logs |
| Mask | CPF ***.***.***-** | Keeping the layout of documents and screens |
| Partial | CPF ***.982.247-** | Customer service screens (the LGPD-style CPF display), e-mail m***@gmail.com, card **** 1111 |
| Hash | CPF CPF_5d91b935fb0f | Analytics and joins: the same value gives the same token (with the same secret) |
For hash, set a Hash secret and reuse it in every run to get the same tokens across runs. Without a secret, a random one is used, so tokens only match within the run. Hashing with a secret is pseudonymization: under the LGPD and GDPR, whoever holds the secret can still link records, so keep it safe.
Input
| Field | Type | Default | Description |
|---|---|---|---|
Texts (texts) | array | — | Free texts; each is one record |
JSON records (records) | array | — | Objects of any shape; structure is kept |
Apify dataset ID (datasetId) | string | — | Clean every item of an existing dataset (e.g. a scraper's output) |
Masking method (method) | string | redact | redact, mask, partial or hash |
Data types (piiTypes) | array | all documents | Which types to look for |
Detect person names (detectNames) | boolean | true | Use the language model for names |
Language for names (namesLanguage) | string | auto | auto, pt or en |
Only these fields (fields) | array | all | Dot paths such as contact.email |
Hash secret (hashSecret) | string | random | Secret for consistent hashing (stored encrypted) |
Return positions (includeEntities) | boolean | false | Add type, field and character positions of each finding (never the original value) |
Add _pii summary (addSummary) | boolean | true | Count of findings per record |
Max records (maxRecords) | integer | 0 | Stop after N records (0 = all) |
Example: clean the output of a scraper run, keeping joins possible:
Output
One dataset row per text or record, in the same order. JSON records keep their structure:
Texts come back as { "index": 0, "text": "Cliente [PERSON], CPF [CPF], ...", "_pii": {...} }. A run summary (records processed and findings per type) is saved as SUMMARY in the key-value store. Original values are never written to the output.
Pricing
Pay per record processed (a text or a JSON record of up to 5,000 characters; longer ones count once per started 5,000 characters), plus a tiny per-run start fee. No subscription. Apify plan discounts apply automatically (see the Pricing tab).
| Example | Records billed |
|---|---|
| 1,000 support tickets | 1,000 |
| A scraper dataset with 20,000 items | 20,000 |
| One 12,000-character document | 3 |
Use Max records or the run's maximum cost setting to cap spending.
Use it from code or an AI agent
Python: clean texts before sending them to an LLM
JavaScript: mask a scraper's output
HTTP
No-code and agents: chain it after any Actor with an integration or webhook, use it in Make, Zapier or n8n, or call it from an AI agent through the Apify MCP server as a privacy step.
FAQ
Does it keep the original values anywhere? No. Only masked values are written. With includeEntities you get positions and types, never the values.
Is masked data anonymous under the LGPD / GDPR? Redact and mask remove the values; whether the remaining text is anonymous depends on what else it contains (e.g. a rare job title plus a city). Partial and hash are pseudonymization, still personal data under the law. Review your use case with your DPO.
Why was a number not detected as CPF? Unformatted 11-digit numbers pass the CPF check digit by chance about 1 time in 10, so they are only treated as CPF when "CPF" (or a field name like cpf_cliente) is nearby. Formatted CPFs (529.982.247-25) are always detected.
Which languages are supported for names? Portuguese and English models. Documents, e-mails, phones and cards work in any language.
Can it process PDFs or images? Not directly; extract the text first. For faces and plates in images and videos, see the anonymizer below.
Models and licenses: spaCy pt_core_news_sm (CC BY-SA 4.0) and en_core_web_sm (MIT) for names; everything else is rule-based.
Related Actors
- Image & Video Anonymizer — blur faces and license plates in photos and videos
- Audio & Video to Text (Whisper) — transcribe calls, then mask the transcripts here
- Face Compare — face verification and embeddings
- Video Frame Extractor for AI — turn videos into clean image datasets
Support
Missing a document type or format? Open an issue in the Issues tab with a (fictitious) example.
Need a different tool? Request it
Missing a feature, an input or output format, or a whole different tool for your workflow? Open an issue in the Issues tab and describe what you need:
- what goes in (files, URLs, data) and what should come out,
- roughly how much you process (per day or month),
- one example, if you can share it.
Requests with a real use case get built, either as a new option in this Actor or as a new Actor in this collection, and you get notified in the issue when it's live. Every request is read.


