
Stack Overflow & Stack Exchange Q&A Scraper, No Login
Pricing
from $1.89 / 1,000 questions
Stack Overflow & Stack Exchange Q&A Scraper, No Login
Scrape Stack Overflow and 170+ Stack Exchange sites by tag, search or question URL. No login. Official API. Questions with answers, votes, tags, authors and a CC BY-SA credit line.
Pricing
from $1.89 / 1,000 questions
Rating
0.0
(0)
Developer

Cliqto Media
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
10 days ago
Last modified
Categories
Security
Limited permissionsShare
Stack Overflow & Stack Exchange Q&A Scraper exports questions with their answers from Stack Overflow and the other Stack Exchange sites (Super User, Server Fault, Ask Ubuntu, Mathematics and 170+ more). You pick a site and a tag, a search query or a list of question links, and get one table row per question with the title, body, tags, votes, author and the answers inside the same row.
Use it to follow questions about your product or library, to build a Q&A dataset for search or an LLM, or to save a fixed list of threads. The smallest run is one tag, for example apify, and 10 questions. No login or API key is needed: the Actor reads the official Stack Exchange API, and every row has a ready CC BY-SA attribution line.
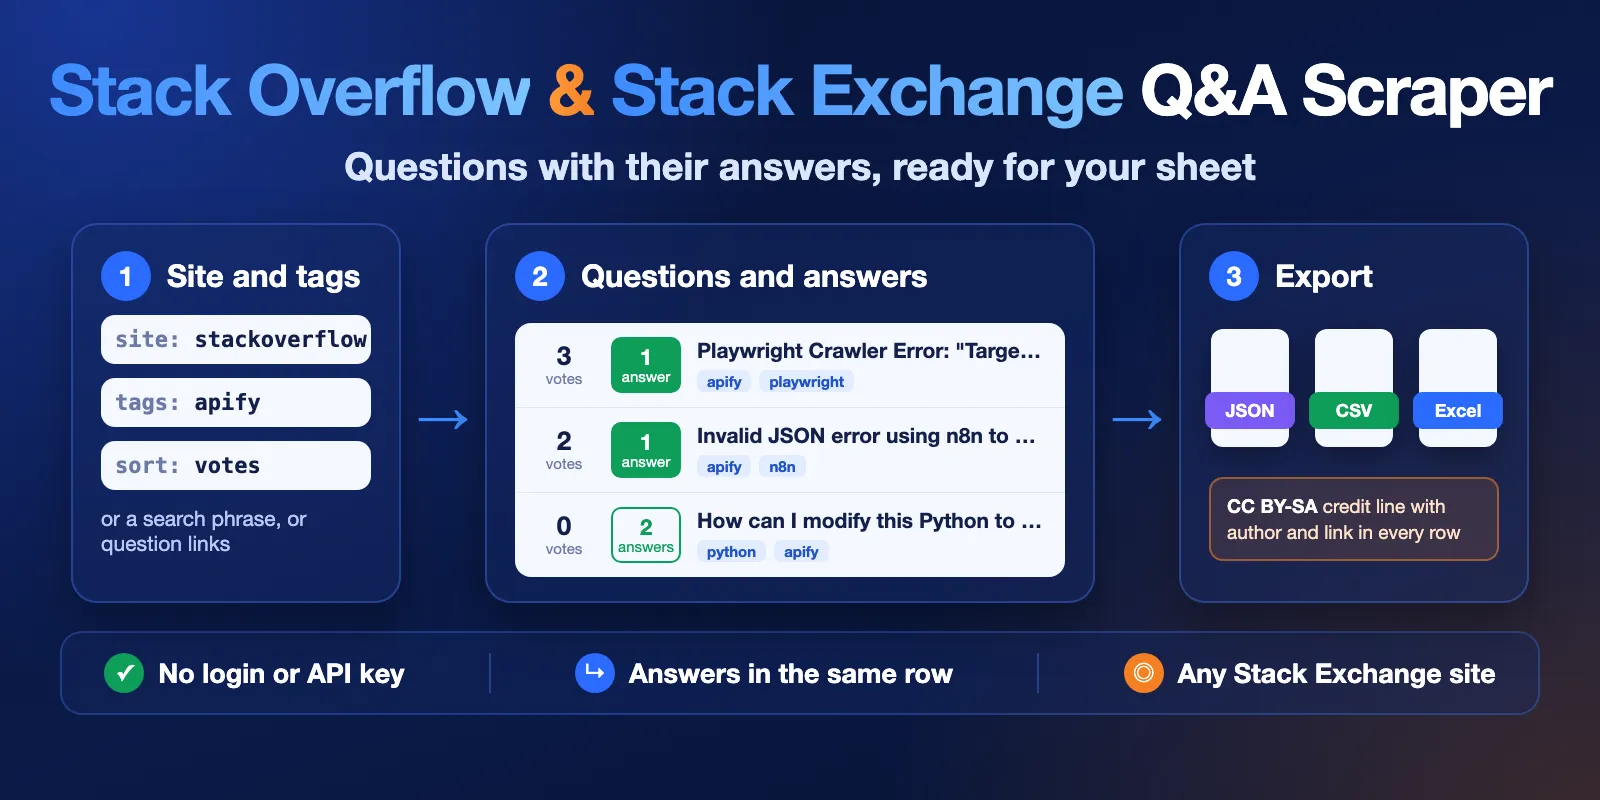
Table of contents
- What it does
- How it works
- Quick start
- Use cases
- Input
- Output
- Pricing
- Limits
- API, export and AI agents
- Troubleshooting
- FAQ
- Related Actors
- Support
What it does
The Actor reads questions from one Stack Exchange site and saves each question as one dataset row with its answers inside. It has three modes:
mode | What you give | What it returns |
|---|---|---|
tag | site and up to 5 tags | Questions that carry all the tags, in your sort order |
search | site, a query and optional tags | Questions that match the words in the title or body |
question | questions: IDs or question URLs | Exactly these questions; a URL sets its own site |
With includeAnswers on (the default), the answers are inside the row: the accepted answer first, then by score. You choose the body format: Markdown as written, HTML as shown on the site, or plain text. You can also limit the creation date with fromDate and toDate.
Good fit
- Watch new questions about your product tag on Stack Overflow.
- Build a question-and-answer dataset in Markdown for search, RAG or an LLM.
- Save a list of known threads with all answers and votes.
- Find the most-voted questions on a topic on any Stack Exchange site.
How it works
- The Actor asks the official Stack Exchange API for the questions of your tag list, search or question links on the site you chose.
- For each page of questions it reads the answers, the content licence and the authors, sorts the answers (accepted first, then by votes) and converts the bodies to the format you picked.
- It saves one row per question in the dataset, free
not_foundanderrorrows for links that do not work, and aRUN_SUMMARYrecord with counts and the remaining daily API quota.
Quick start
-
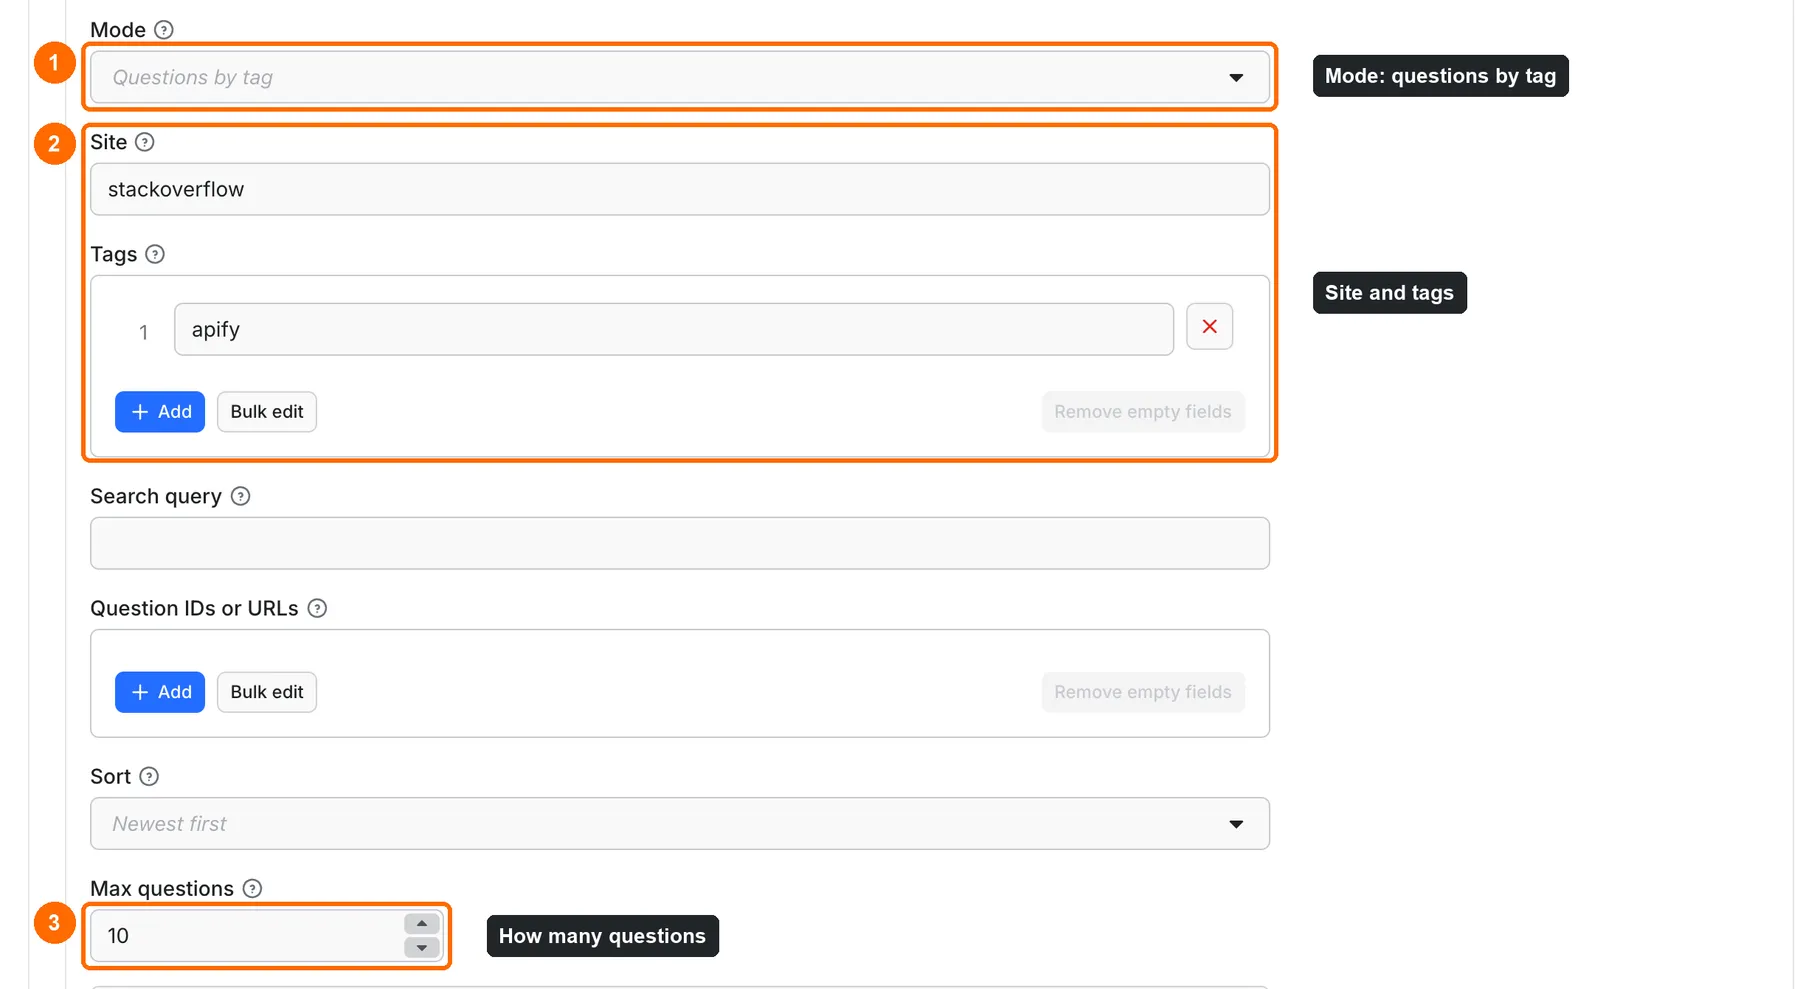
Open the Input tab. Mode stays at the default Questions by tag (box 1).
-
Keep Site at the prefilled
stackoverflowand Tags at the prefilledapify, or type your own site and tag (box 2). -
Keep Max questions at the prefilled
10or set your own number (box 3; the runtime default is50). -
Click Start at the bottom of the page.
-
Open the Questions view in the Output tab and check
title,score,answerCountandlink(box 5).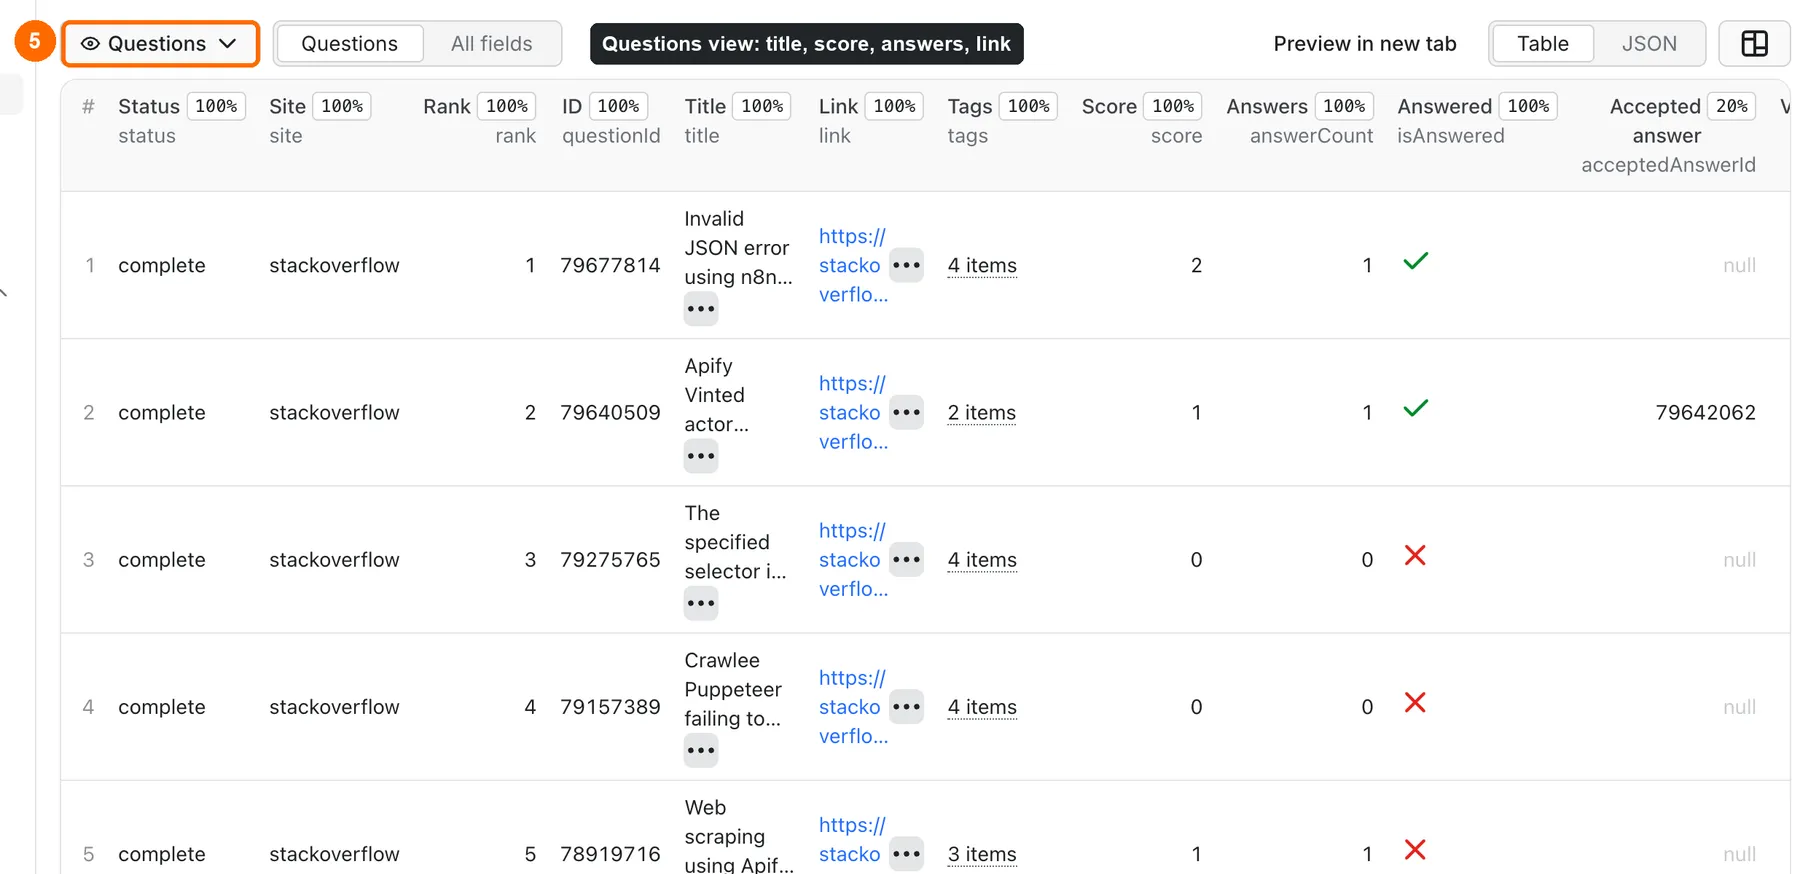
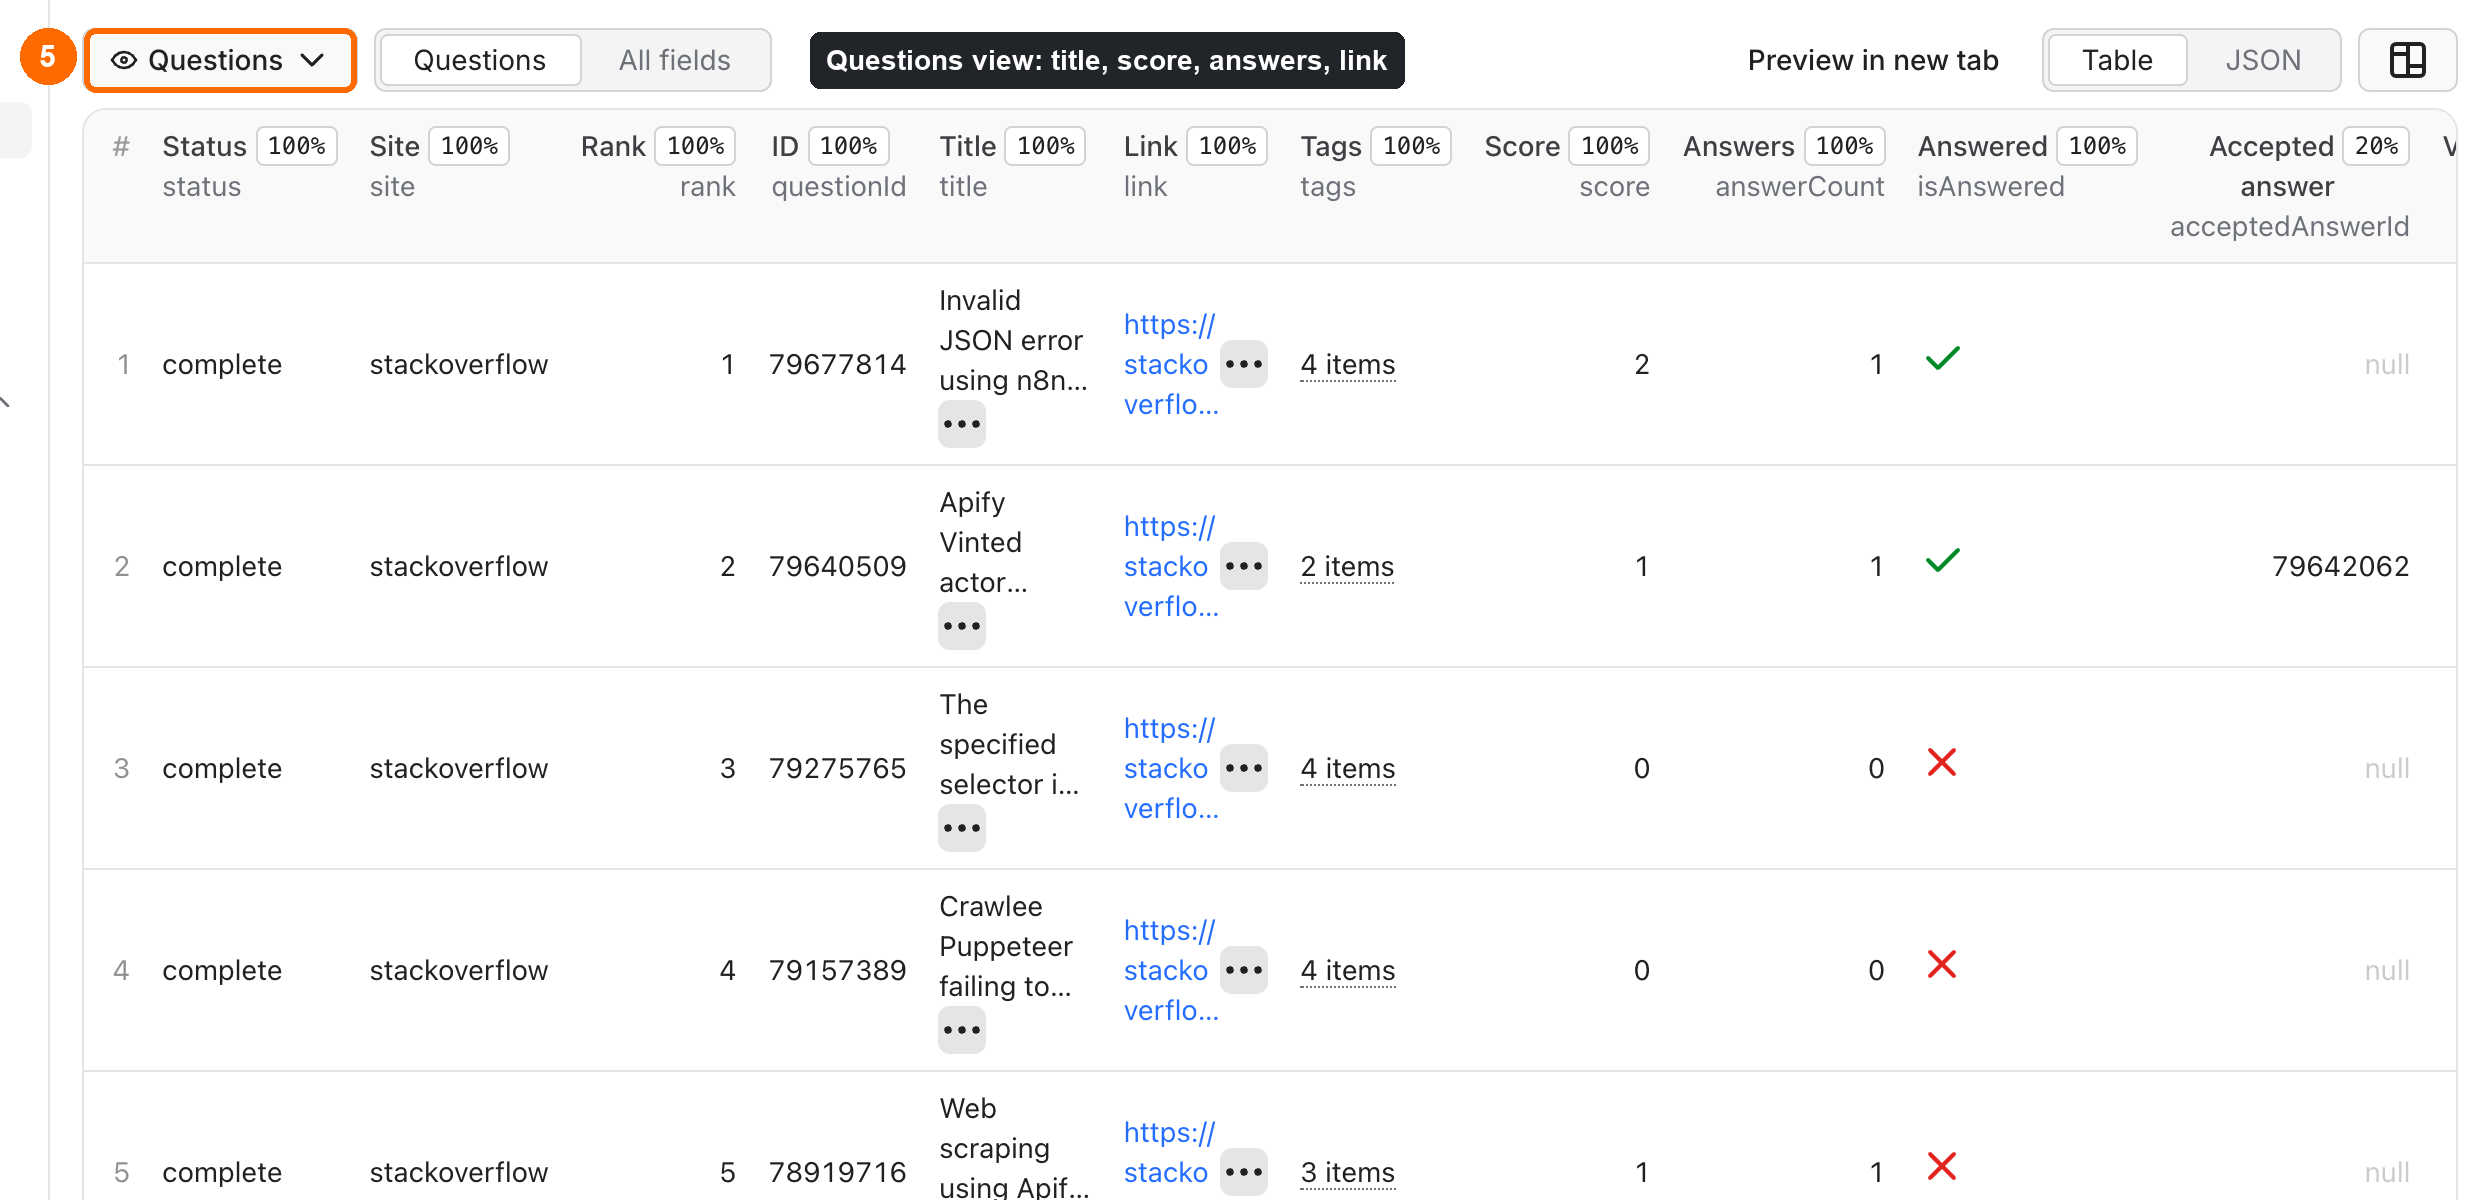
Expected result: the 10 newest questions with the apify tag and their answers, in a few seconds.
Use cases
| Buyer job | Input | Output | Key fields | Next step |
|---|---|---|---|---|
| Follow questions about your product | tags: ["your-tag"], sort: newest, scheduled | question rows | title, link, createdAt, isAnswered | Send unanswered ones to your support channel |
| Build an LLM or RAG dataset | tags, sort: votes, bodyFormat: markdown | rows with answers | body, answers[].body, answers[].isAccepted, attribution | Load into a vector store, keep the credit line |
| Research a topic | mode: search, query, fromDate | question rows | score, viewCount, tags | Count questions per month or per tag |
| Save known threads | mode: question, questions | one row per thread | answers, acceptedAnswerId, lastActivityAt | Archive or compare over time |
Input
You need a site and at least one of: tags (tag mode), query or tags (search mode), questions (question mode). A wrong input stops the run with INVALID_INPUT before any request.
| Field | Plain name | Type | Default | Allowed values | What it changes | Recommendation |
|---|---|---|---|---|---|---|
mode | Mode | enum | tag | tag, search, question | Which list the Actor reads | tag to follow a topic, question for known threads |
site | Site | string | stackoverflow (prefill too) | API site name or domain: superuser, serverfault, askubuntu, math, math.stackexchange.com … | The Stack Exchange site | Use the short name from the site URL |
tags | Tags | array of strings | none (prefill ["apify"]) | up to 5 tags | Questions must carry all the tags. Empty in tag mode = all questions of the site | One or two tags give the clearest list |
query | Search query | string | none | up to 500 characters | Words to find in titles and bodies (search mode only) | Add sort: relevance |
questions | Question IDs or URLs | array of strings | none | up to 1,000 IDs like 11227809 or question URLs | Exact questions to read (question mode only). Duplicates are read once | Paste links from your browser |
sort | Sort | enum | newest | newest, active, votes, hot (tag mode), relevance (search mode) | Order of the list | votes for the best-known questions |
maxQuestions | Max questions | integer | 50 (prefill 10) | 1–1,000 | The run stops after this many question rows | Start small, then raise |
includeAnswers | Include answers | boolean | true | true, false | Answers inside each row | Turn off for a list of titles only |
maxAnswersPerQuestion | Max answers per question | integer | 30 | 1–500 | Keep only the best answers | answersComplete shows if all answers fit |
bodyFormat | Body format | enum | markdown | markdown, html, text | Format of question and answer bodies | markdown for LLMs, text for spreadsheets |
fromDate, toDate | Created from / until | date | none | 2025-01-01 (UTC; toDate includes the whole day) | Only questions created in this window | Use for a monthly report |
apiKey | Stack Exchange API key | secret string | none | free key from stackapps.com | Higher daily quota | Not needed for normal runs |
Interacting settings
| When | Field A | Field B | Effect |
|---|---|---|---|
| Search | query | tags | Both must match: the words and all the tags |
| Order | sort: hot | mode: tag | hot works only in tag mode; relevance only in search mode |
| Question links | questions with a URL | site | The URL's own site wins; bare IDs use site |
| Answers | includeAnswers: false | maxAnswersPerQuestion | No answers, so maxAnswersPerQuestion is ignored and answers is null |
| Dates | fromDate, toDate | mode: question | Dates work in tag and search modes only |
Input examples
Newest questions about a product tag (the prefill)
Expected: 10 question rows, newest first, each with its answers. The output example below comes from this input.
Best-voted answers on Server Fault for a search
Expected: up to 100 question rows, most votes first, with plain-text bodies and answers.
A fixed list of threads
Expected: one row per question that exists, each with up to 5 answers. A missing question gives a free not_found row.
Coming from another Stack Exchange Actor
Input names here are different. This table helps to move an existing input:
| Common input in other Actors | This Actor |
|---|---|
tagged: "a;b" | tags: ["a", "b"] |
searchQuery | mode: "search", query |
questionIds | mode: "question", questions |
fetchAnswers | includeAnswers (on by default, no extra price) |
maxResults | maxQuestions |
sort: activity / creation | sort: active / newest |
Output fields are camelCase (questionId, answerCount) with ISO dates, not raw API snake_case. The asker is one author object.
Output
Output example
A real row from the prefill run (body and the answer body are shortened here):
null means the API gave no value (no accepted answer, no bounty, never edited). 0 is a real zero. commentCount can be null in tag and search lists and filled in question mode: the Actor copies what the API endpoint returns.
Output fields
Question rows (status: complete or partial)
| Field | Meaning | Type | Can be null? | Example |
|---|---|---|---|---|
site | Site the row came from | string | no | "stackoverflow" |
questionId | Question ID, stable key | integer | no | 77823456 |
title, link | Title and public question link | string | no | |
tags | Question tags | array | no | ["node.js", "apify"] |
score, upVotes, downVotes | Votes | integer | yes | 0, 1, 1 |
viewCount, answerCount | Views and number of answers | integer | yes | 213, 1 |
isAnswered, acceptedAnswerId | Has an upvoted or accepted answer; ID of the accepted one | boolean, integer | yes | true, null |
commentCount, bountyAmount | Comments on the question; open bounty | integer | yes | null |
isClosed, closedReason, closedAt | Closed questions | boolean, string | yes | false |
createdAt, lastActivityAt, lastEditedAt | Dates (ISO, UTC) | string | yes | "2024-01-16T04:20:59.000Z" |
author | userId, displayName, reputation, userType, profileUrl | object | yes (deleted users) | |
bodyFormat, body | Body format and question body | string | body yes | "markdown" |
answers | Answers: answerId, link, score, isAccepted, author, body, license, dates | array | null when includeAnswers is off | |
answersIncluded, answersComplete | How many answers are in the row; false if maxAnswersPerQuestion cut some | integer, boolean | yes | 1, true |
license, licenseUrl | Content licence of the question | string | yes | "CC BY-SA 4.0" |
attribution | Ready credit line: title, author, link, licence | string | yes | |
rank | Position in the tag or search list | integer | yes (question mode) | 8 |
status, statusReason, errorCode | Row status and why | string | statusReason, errorCode yes | "complete" |
input, inputs | What you entered for this row (question mode) | string, array | yes | "11227809" |
sourceUrl, fetchedAt | API request and fetch time | string | no |
partial means the row has no licence from the API, or the API returned fewer answers than expected. It is still a useful row and is charged.
Issue rows (status: not_found or error)
Question mode only. These rows are free.
not_found: the IDs do not exist, are deleted or are not question IDs. Missing IDs from one batch share one row, with the list ininputs.error: a bad item (for example an answer link or a non-Stack Exchange URL), or a source error for that batch. Items with the same reason share one row, with the list ininputs.
When a row is about one item, input and questionId are filled; when it is about several, they are null and inputs lists them.
Run report
The key-value store record RUN_SUMMARY has the run status, reason, counts (rows, questions, answers, complete, partial, not found, errors, charged questions), request counts and the remaining daily API quota. It never contains your API key.
| Run status | Meaning | Run result |
|---|---|---|
COMPLETE | All requested questions were read | SUCCEEDED |
CAPPED | Stopped early with saved rows: your maximum charge (CHARGE_LIMIT), the daily API quota (QUOTA_LIMIT), the time limit (DEADLINE) or the API page limit (PAGE_LIMIT) | SUCCEEDED, saved rows are kept |
NO_RESULTS | No questions match the filters | SUCCEEDED, empty dataset |
NOT_FOUND | No question from the list exists | SUCCEEDED, free not_found rows |
PARTIAL | Some rows are partial (PARTIAL_ROWS), or the source failed after some rows (SOURCE_ERROR) | SOURCE_ERROR marks the run FAILED; saved rows are kept |
ERROR | The source failed or the run stopped before any question was saved | FAILED |
INVALID_INPUT | The input cannot work, for example an unknown site, or no item in questions is a valid question | FAILED |
CANCELLED | You aborted the run | saved rows are kept |
Licence and attribution
Stack Exchange content is licensed by its authors under CC BY-SA (2.5, 3.0 or 4.0, by post date). Each row has its license and licenseUrl, and attribution gives a ready credit line with the title, author and link. When you reuse the content, show that line and keep the same licence. The Stack Exchange API terms also ask you to name Stack Exchange as the source. The Stack Exchange Acceptable Use Policy limits some uses, for example training AI models without their consent; check that it fits your plan.
Data comes from the Stack Exchange API. See also the Stack Exchange API terms of use, the Acceptable Use Policy and the CC BY-SA 4.0 licence. This Actor is not affiliated with or endorsed by Stack Exchange, Inc.
Pricing
Pay per event. Apify platform usage is included.
| Event | When | Price (USD) |
|---|---|---|
| Actor start | once per run; Apify counts the start per GB of run memory, so it is one start at the default 256 MB and the 512 MB maximum | 0.002 |
| Question | per saved question row (complete or partial), answers included | 0.0027 Free · 0.00243 Bronze · 0.00216 Silver · 0.00189 Gold and above |
not_found and error rows are free. A run with no results pays only the start.
| Example run | Free | Bronze | Silver | Gold+ |
|---|---|---|---|---|
| 1 question | $0.0047 | $0.0044 | $0.0042 | $0.0039 |
| 10 questions (the prefill) | $0.029 | $0.026 | $0.024 | $0.021 |
| 100 questions | $0.272 | $0.245 | $0.218 | $0.191 |
| 1,000 questions with answers | $2.702 | $2.432 | $2.162 | $1.892 |
| Search with no matches | $0.002 | $0.002 | $0.002 | $0.002 |
Set Maximum cost per run in the run options to cap a run. The Actor checks the limit before each row. It stops before a charge would go above it, keeps what it already saved and ends as CAPPED with reason CHARGE_LIMIT.
Limits
- Up to 1,000 questions per run. Measured runs of 1,000 questions with answers, all COMPLETE inside the 600-second default timeout: 16 seconds for Super User
windows-10in HTML, 217 seconds for the most-voted Stack Overflowjavascriptquestions in Markdown (about 20 answers per question, 40 MB of text). - Without an API key, the Stack Exchange API gives about 300 requests per day per IP address, and Apify runs share IP addresses. One request reads up to 100 questions with answers, so normal runs use a few requests.
RUN_SUMMARYshows the remaining quota. - If the daily quota runs out, the run stops as
CAPPEDwith reasonQUOTA_LIMIT, keeps saved rows and suggests anapiKey. If nothing was saved yet, the run isERROR. - The API asks clients to wait between some requests. The Actor follows this, so big runs take minutes, not seconds.
- The Actor stops reading 30 seconds before the run timeout, and after 870 seconds at most, so it can save the results (
CAPPED,DEADLINE). With a shorter timeout, for example 300 seconds, a run of 1,000 answer-heavy questions can stop early with the rows read so far. - No comments, user profiles, badges or chat. Only questions and their answers.
- No private or deleted content. Deleted questions come back as
not_foundrows. - Answer links (
/a/<id>) are not looked up. Use the question link instead. - The data is live: votes, views and answers can change between runs.
API, export and AI agents
- Export: the dataset downloads as JSON, CSV, Excel, XML or HTML. The Questions view shows a flat table with the main question fields.
- API: start a run with
POST https://api.apify.com/v2/acts/cliqtomedia~stack-exchange-scraper/runsand the input JSON; read rows from the run's default dataset. - Scheduling, webhooks, Make, Zapier, n8n: use the standard Apify integrations. The next system can use
site+questionIdas a stable key.
Use with AI agents (MCP)
- MCP server with only this Actor:
https://mcp.apify.com?tools=cliqtomedia/stack-exchange-scraper - Smallest useful input:
{"site": "stackoverflow", "tags": ["apify"], "maxQuestions": 10} - Key output fields:
title(question title),link(public URL),score(votes),answers[].bodywithanswers[].isAccepted(answer text and accepted flag),attribution(credit line to show with the content). - The prefill run takes a few seconds and costs $0.029 on the Free plan (start $0.002 + 10 questions). 1,000 questions with answers took 16 to 217 seconds in our tests, inside the 600-second default timeout. Keep
maxQuestionssmall for quick answers.
Troubleshooting
The run failed with Unknown Stack Exchange site
Symptom: the run is FAILED with INVALID_INPUT. Likely reason: the site value is not a site name. Check: open the site in a browser; the name is the first part of the address (superuser.com → superuser, math.stackexchange.com → math). Action: fix site or paste the full domain.
The dataset is empty
Symptom: the run SUCCEEDED with NO_RESULTS. Likely reason: no question has all the tags, or the dates or query are too narrow. Check: open the tag page on the site. Action: remove a tag or widen the dates.
I got a not_found row
Likely reason: the question was deleted, or the ID is an answer ID. Check: open the link from inputs in a browser. Action: use the question link. These rows are free.
The run ended with QUOTA_LIMIT
The shared daily API quota of this IP address ran out. Saved rows are kept. Run again later, or add a free Stack Exchange API key in apiKey.
FAQ
Do I need a Stack Overflow account or API key?
No. The Actor reads public data from the official Stack Exchange API. No login and no cookies. The apiKey field is optional: a free Stack Apps key only raises the daily quota and gives no account access.
Are answers charged separately?
No. Answers are part of the question row. One question row is one charge, with up to 500 answers inside.
Which sites work?
Any public Stack Exchange site: Stack Overflow, Super User, Server Fault, Ask Ubuntu, Mathematics, MathOverflow, Stack Overflow in Russian and others. Use the site name or domain in site.
Are the numbers live?
Yes. Each run reads the API at that moment; fetchedAt shows when. Votes, views and answers change over time.
Is personal data included?
Only public profile data shown on the site: the author's user ID, display name, reputation and profile link. No email, location or other profile details.
Related Actors
- Hacker News Scraper: Stories, Comments & Parent IDs — stories and comment threads from another big developer community.
- Reddit Scraper: Posts, Comments & Subreddits (No login) — posts and comments from subreddits about the same topic.
- Quora Answers Scraper: Upvotes, Views & Authors, No Login — questions and answers from Quora, with upvotes and authors.
- GitHub Releases Scraper & Monitor: Notes & Assets — release notes of the library your questions are about.
Support
For a bug, question or feature request, open an issue on the Actor's Issues tab. Add the run ID and your input. Never post API keys or other secrets.


