
Reddit Brand Mention Monitor
Pricing
from $3.00 / 1,000 brand mentions
Reddit Brand Mention Monitor
Monitor Reddit for mentions of your brand, products, competitors and tracked keywords. New posts and comments with relevance, sentiment, complaint / praise / comparison / switching signals and only-new scheduled monitoring. No Reddit login or API key.
Pricing
from $3.00 / 1,000 brand mentions
Rating
0.0
(0)
Developer
Delowar Munna
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
5 days ago
Last modified
Categories
Share
Track new Reddit posts and comments mentioning your brand, products and competitors — with relevance, sentiment and intent signals.
Give it your brand names, their aliases, your competitors and any keywords you care about. It searches Reddit (all of it, or the subreddits you choose), reads the posts and the comments under them, keeps only the ones that genuinely name what you track, and returns one clean row per mention:
- which brand, alias, competitor or keyword matched, and why (a 0–100 relevance score with a point-by-point breakdown)
- sentiment (POSITIVE / NEUTRAL / NEGATIVE / MIXED, −1…+1)
- what kind of mention it is: complaint, praise, bug report, support issue, feature request, comparison, alternative request, switching, purchase intent, recommendation, question …
- buying-intent and switching flags, and the competitors named alongside you
- author, subreddit, text, link, publish time, Reddit score and comment count
- for comments: the post they reply to
Schedule it hourly or daily with only-new mode and you get each mention once, and pay for it once.
No Reddit login, no API key, no cookies. No AI cost: classification is rule-based and explainable.
What can I monitor?
| Input | What it's for | Example |
|---|---|---|
| Brands | Your brands and products | Notion, HubSpot, Canva |
| Aliases | Other spellings, attributed to the brand | { "OpenAI": ["Open AI", "ChatGPT", "chat gpt"] } |
| Competitors | Competitor brands — monitored too, and used to detect comparisons and switching | Obsidian, Coda |
| Keywords | Campaigns, slogans, features, launches, founders | Notion AI, #ShotOniPhone |
| Subreddits | Optional — restrict to these communities | productivity, r/SaaS, https://www.reddit.com/r/Notion/ |
Every term is matched literally, as a whole word or phrase, case-insensitive, in post titles, post bodies and comments. "CRM" matches "CRMs"; "Monday.com" and "C++" work as written.
Can I use aliases?
Yes. A match on ChatGPT comes back with trackedTerm: "OpenAI", canonicalBrand: "OpenAI" and matchedAlias: "ChatGPT". Aliases are never merged across brands unless you map them. An alias that contains its brand ("notion app" under "Notion") is not searched separately, because the brand search already finds it, but it is still matched and reported.
Can I monitor competitors?
Yes. Each competitor is searched and its mentions returned (termType: "COMPETITOR"). A post or comment that names your brand and a competitor is flagged COMPARISON, and phrases like "switched from X to Y", "alternative to X" or "X vs Y" set the switching, alternative and comparison signals. Turn Search competitors off to use competitors only for classifying mentions of your own brands; that halves the searches.
Do you scan posts and comments?
Both, by default. Every post that names a tracked term has its first comments read (top comments first, up to Max comments per post), and every comment that names a term is a mention row too. Complaints, recommendations and "we switched away from it last month" are very often in the replies.
A comment must name a term itself. A reply in a Notion thread that never says "Notion" is not counted: in testing, that rule kept chatter like "why do so many people need a system?" out of the results.
Can I monitor all of Reddit? Can I limit it to subreddits?
Leave Subreddits empty to search all of Reddit, or list communities to search each of them. A subreddit named after your brand (r/Notion) raises relevance, and so does any subreddit you selected.
Only-new monitoring
What does only-new mode do?
With Only new mentions on, the Actor remembers every mention it delivered under your Monitor key, in a named key-value store on your account (reddit-brand-monitor-<key>). Later runs with the same key return, and charge for, only mentions it has not delivered before. Mentions it has seen are counted in the run summary as alreadySeenMentions and are free. An edited post keeps its ID, so an edit is never delivered twice.
Use the same monitor key on every scheduled run. Without one, a key is derived from your terms and subreddits, so changing them starts a fresh memory. With a key set and only-new mode off, everything is delivered and rows still say whether they are new (isNew, firstSeenAt).
What happens on the first monitoring run?
You choose, with First run:
RETURN_CURRENT(default): the first run returns the current mentions in your time window, and remembers them.BASELINE_ONLY: the first run remembers the current mentions without returning or charging any. From the second run on, you get only mentions that appeared after it. Use this when you want a clean feed of genuinely new mentions from day one.
Can I schedule hourly or daily?
Yes, that is what it is built for. Use Posted within = HOUR or DAY, Search sort = NEW, only-new mode on and a fixed monitor key, then add a schedule in Apify Console. Each run stops collecting shortly before its timeout and delivers what it has found, so a long run is never wasted.
Relevance, sentiment and signals
What does the relevance score mean?
0–100, built from named factors that are all listed in relevanceBreakdown:
| Factor | Points |
|---|---|
| Brand, alias, competitor or keyword named | 40 |
| Named in the post title | +20 |
| Named in a comment whose post names a tracked term too | +10 |
| Named more than once | +10 |
| Product words nearby ("app", "pricing", "support", "switched", "bug" …) | +15 |
| Brand and competitor named together | +10 |
| Subreddit named after the term · or a subreddit you selected | +15 · +5 |
| A Capitalised one-word brand seen only in lower case with nothing product-like nearby ("an apple") | −20 |
| Bot, link dump or copy-paste promotion | −60 |
| Free search result whose body could not be read (see Limitations) | 15 |
Minimum relevance (default 30) drops everything below it. For ambiguous brand names (Apple, Monday, Linear, Square) raise it and add Exclude words ("apple pie", "linear algebra").
Common-word brands are protected by case. When a one-word brand like Linear or Apple appears only in another case ("linear algebra", "FORECAST.LINEAR"), the mention is dropped unless something backs it up: the subreddit is named after the brand, another tracked term is named alongside it, or it is a comment on a post that writes the brand as "Linear". Product words nearby ("using", "model") are not enough on their own. These drops are counted as ambiguous-common-word in the run summary.
Is sentiment included?
Yes: sentiment and sentimentScore (−1…+1). It is read where your brand is named, not across the whole text, so "Notion is great for docs. Obsidian is a mess." is positive for Notion. A post whose title names the brand is read whole, but the title counts double and body sentences that don't name the brand count half, so praise for the tool someone is moving to doesn't make leaving yours positive. The title also leads the category: "Ditching Notion due to database lag" is about leaving Notion, whatever the rest of the post covers. Negation ("not great", "wouldn't recommend") and intensifiers are handled, and in a question positive words are ignored ("Is Notion any good?" is neutral). It is inferred by rules and will sometimes be wrong; treat it as a signal.
Are buying and switching signals included?
Yes. signals can hold BUYING_INTENT, SWITCHING_INTENT, ALTERNATIVE_REQUEST, COMPARISON_INTENT, SUPPORT_INTENT, RECOMMENDATION_INTENT, CANCEL_OR_CHURN_INTENT and FEATURE_REQUEST, and buyingIntent / switchingIntent are booleans. Switching and buying count only when the writer is doing it ("we switched from Notion", "thinking of leaving Notion", "should I upgrade?"). "You should switch from Notion" is advice, not churn. A quoted example of what other people say is ignored.
primaryCategory is the most specific category that fired, in this order: BUG_REPORT, SUPPORT_ISSUE, COMPLAINT, SWITCHING_INTENT, ALTERNATIVE_REQUEST, PURCHASE_INTENT, COMPARISON, FEATURE_REQUEST, RECOMMENDATION, PRAISE, PRODUCT_FEEDBACK, QUESTION, CAMPAIGN_MENTION, otherwise GENERAL_MENTION. The others are in secondaryCategories, and matchedPhrases shows the text that triggered them.
Each of these outputs can be switched off (Sentiment, Mention category, Intent signals, Buying-intent flag); a switched-off field is null, so every row keeps the same columns.
Is AI required?
No. Every classification is rule-based, runs inside the Actor and costs nothing extra. Rules are predictable and explainable: you can always see the phrase behind a label.
How are duplicate mentions handled?
One row per post or comment. A post found by three searches, or naming both your brand and a competitor, is one row with every term in matchedTerms, canonicalBrands, matchedAliases and matchedCompetitors, and is charged once. duplicatesMerged in the run summary counts them.
Input examples
One brand across Reddit, past week:
Brand with aliases, past 24 hours, stricter relevance:
Competitor monitoring in chosen subreddits:
Daily only-new monitor (schedule this):
Start a monitor with a baseline (first run returns nothing):
When you paste JSON into the Console, state every on/off option you care about. The Console can store an option you leave out as
falseeven when its default is on.
Output
One row per mention. The dataset has three views, each a different cut of the same rows, and every row carries every field. The records below are real, from a run of the first input example (Notion, all of Reddit, past week) on 2026-10-16. Usernames are anonymised and long text is trimmed.
Mentions: what was said, where, by whom
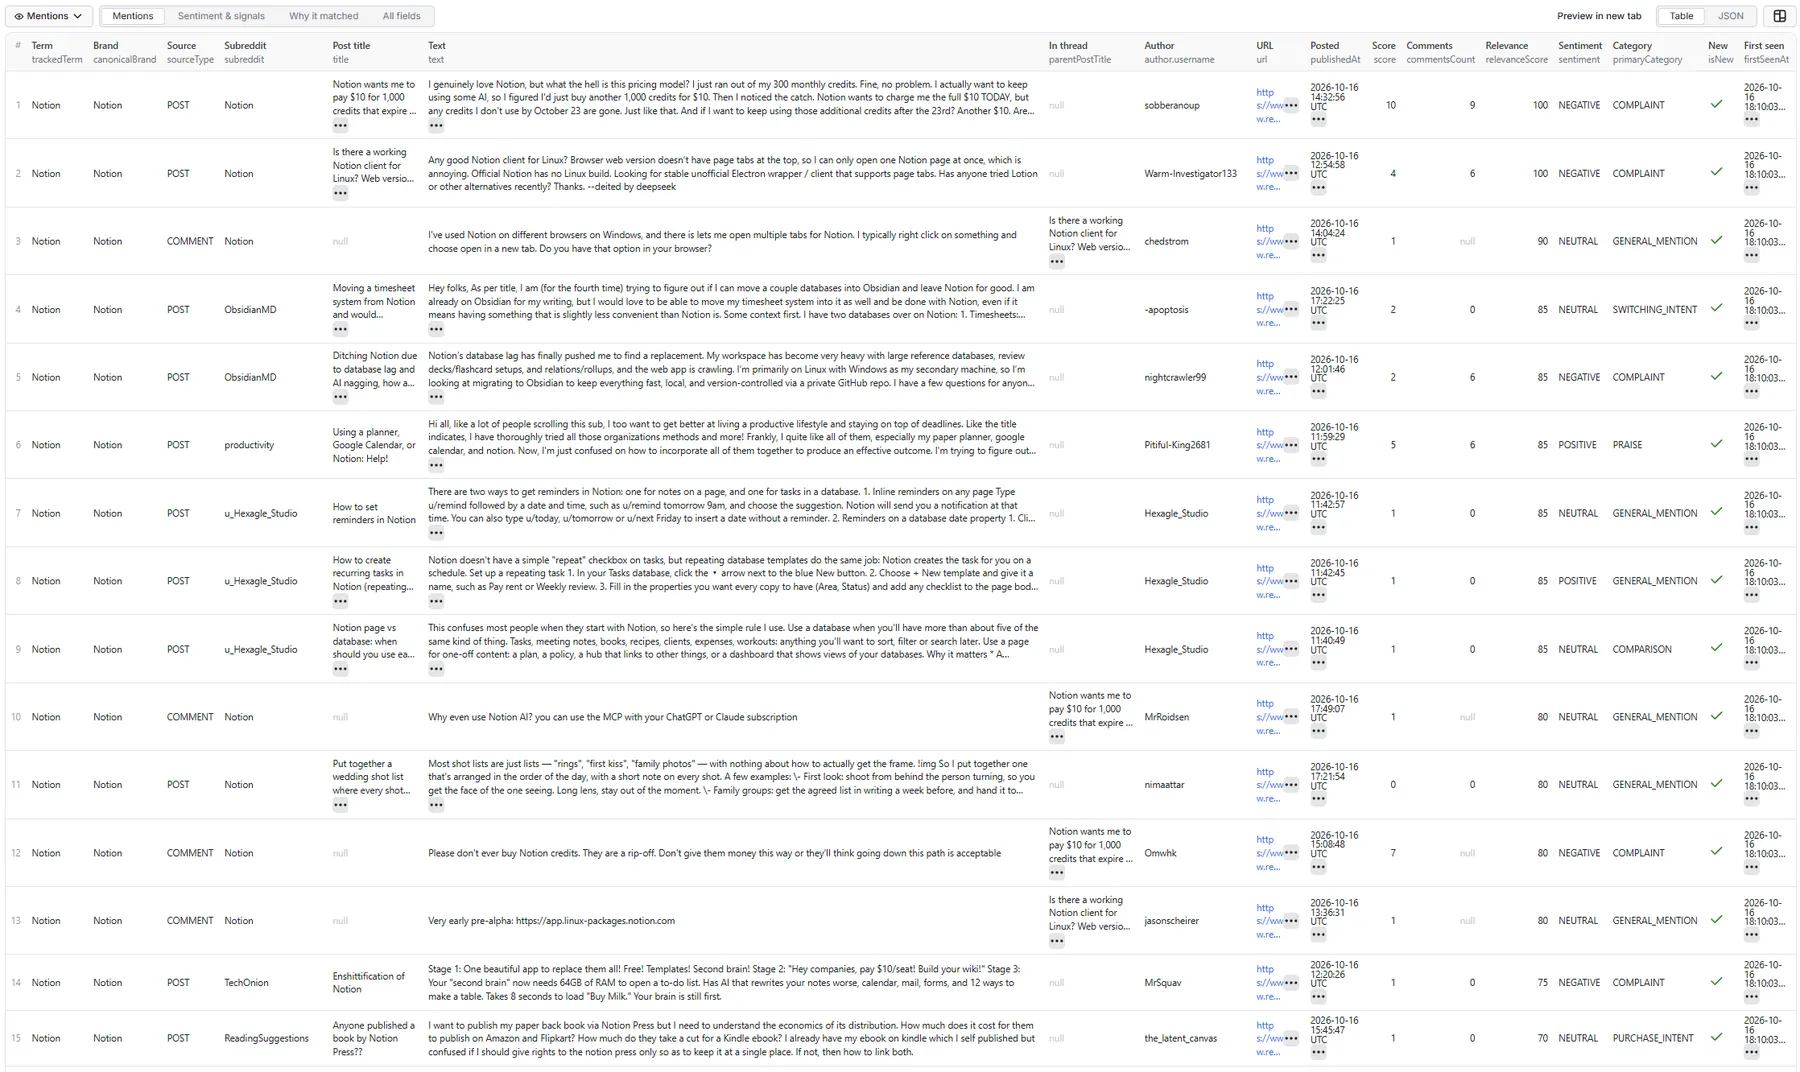
One row from that table, as JSON:
commentsCount is for posts; a comment row carries its post's title, ID and link instead.
Sentiment & signals: complaints, switching, buying intent
The body praises the tool the writer is moving to ("fast, local"). It doesn't make leaving Notion positive, because body sentences that don't name your brand count for less than the title and the sentences that do. Had Obsidian been a competitor in the input, it would appear in matchedCompetitors and the row would also be a COMPARISON.
Why it matched: the evidence behind every row
A reply to that post, "Rollups on notion are a broken relational database system. That's why it lags…":
The comment writes "notion" in lower case, which could be the ordinary word, so it loses 20 points. It is kept because the post it replies to names Notion, which corroborates it and adds 10. On its own, the same sentence would be dropped as ambiguous-common-word. relevanceBreakdown always adds up to relevanceScore (relevanceSignals lists the positive factors).
Every row also has: rowType, matchedAliases, matchedKeywords, canonicalBrands, postId, commentId, parentPostId, monitorKey, capturedSequence. A field that doesn't apply is null rather than missing, so CSV and Excel exports keep one shape.
Run summary
Each run writes two records to its key-value store:
RUN_SUMMARY: tracked terms, search operations, posts and comments scanned, qualifying / new / already-seen mentions, positive / negative / complaint / comparison / switching / buying-intent counts, duplicates merged, every drop reason, andobservedMentionVelocity: mentions in the last hour, 24 hours and 7 days, plus per-term counts. Velocity counts what this run found, which is bounded by Max posts per term and Posted within. It is not total platform volume.SOURCE_SUMMARY: the outcome of every search:SUCCESS,NO_RESULTS,INVALID_TERM,INVALID_SUBREDDIT,SUBREDDIT_NOT_FOUND,RATE_LIMITED,BLOCKED,PARTIAL_RESULT,TEMPORARY_REDDIT_ERROR. One failed term or subreddit never fails the run.
How does pricing work?
Pay per event: you are charged once per unique qualifying mention delivered to your dataset. You are never charged for searches, for posts and comments that were scanned but didn't qualify, for mentions below your minimum relevance or caught by your filters, for duplicates, for mentions your monitor has already delivered, for a BASELINE_ONLY first run, for retries, or for failed searches. A run that finds nothing costs you nothing in events.
See the Pricing tab for the current rate. This README deliberately doesn't quote figures, because they can change.
If you set a maximum charge per run, the Actor stops there and delivers the most relevant mentions first.
Can I use it through the API or MCP?
Yes, like any Apify Actor: run it with the Apify API, the JavaScript or Python client, or from AI agents through the Apify MCP server. Read results from the run's default dataset, and RUN_SUMMARY from its key-value store.
Limitations
- Relevance is literal, not semantic. A mention must contain the term. A post about your product that never names it is not found, and an unrelated use of a common word can slip through. That is what Exclude words and Minimum relevance are for.
- Search depth is bounded. Reddit's search returns roughly 250 results per query, sort and time window. For busy brands use short windows (
DAY,HOUR) on a schedule rather than one huge search. - Comments are read from the top of each thread. Logged-out Reddit serves a thread's first page of comments (plus a few expansions), so very long threads are sampled, not read in full.
- Occasionally a post's body can't be read. If the search route that returns full post bodies is unavailable, posts come from Reddit's own search results, which carry the title only. Reddit's search also matches ordinary words in the hidden body ("a notion of…"), so such a post scores only 15, below the default minimum relevance. It qualifies only in a subreddit named after the term, and it has
matchType: "SEARCH_MATCH"andtextAvailable: false. Its comments are read only when you selected subreddits or it is in a subreddit named after the term. Each comment must still name the term itself. - Sentiment and categories are inferred by rules and can be wrong, especially for sarcasm. Every label shows the phrases behind it.
🚦 Proxy policy
Use Apify Datacenter proxy (the default) or no proxy. Both work reliably for Reddit search and comment pages at this Actor's conservative pacing.
Apify Residential proxy is not supported. The Actor fails at startup if apifyProxyGroups includes RESIDENTIAL. Reason: in pay-per-event Actors, residential bandwidth is billed to the developer, not the run user, and Reddit comment pages are large, so a single bandwidth-heavy run could cost more than it earns.
If you genuinely need residential routing, supply your own residential provider in the proxy editor's Custom proxy URLs field. That traffic goes through your provider, not Apify, and is unaffected:
Responsible use
- This is an unofficial tool, not affiliated with or endorsed by Reddit.
- It reads public posts and comments only. No login, no private data, no email discovery.
- Sentiment and intent are inferred and may be imperfect. Do not make decisions about individuals from them.
- Follow each subreddit's rules if you respond to a mention. Never use the output for spam, harassment, vote manipulation or automated replies; this Actor does none of those, and you shouldn't build them on top of it.
- You are responsible for processing the data lawfully (GDPR / CCPA and similar) in whatever you do downstream.
Related Coregent Actors
- Reddit Leads / Purchase Intent Finder: turn high-intent mentions into scored leads, one row per person.
- Reddit Posts Search Scraper: full Reddit search results, every field.
- Reddit Comments Scraper: complete comment trees for any thread.
- Reddit User Scraper: profile details for the authors you find.


