
Greenhouse Jobs Scraper: All Jobs & New-Job Alerts
Pricing
from $0.75 / 1,000 jobs
Greenhouse Jobs Scraper: All Jobs & New-Job Alerts
Scrape every open job from any company on Greenhouse (boards.greenhouse.io) via the official public Job Board API. Departments, offices, locations, full descriptions. Paste a board token, URL or company website. Monitoring mode returns only new jobs.
Pricing
from $0.75 / 1,000 jobs
Rating
0.0
(0)
Developer
Red Fox Scout
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Share
Get every open job from any company hiring on Greenhouse (boards.greenhouse.io, job-boards.greenhouse.io), live, in one clean table. Paste company websites like discord.com, or board tokens like airbnb, and the Actor finds each Greenhouse board. Switch on monitoring mode to get only the jobs that are new since your last run. Thousands of companies use Greenhouse, including Airbnb, Stripe, Figma, Discord and Databricks.
Each job also gets rule-based fields read from the posting: salary range, years of experience, visa sponsorship, remote or hybrid, the tools and skills it names, and the application form questions, and any contact email or recruiter name the posting shows. Nothing is generated by AI, and a field is null when the posting does not say.
Price: $1.00 per 1,000 jobs. Companies that fail, aren't on Greenhouse, or have no matching jobs cost nothing. Apify's free plan ($5 monthly credit) covers about 5,000 jobs a month.
Questions it answers
- What jobs is this Greenhouse company hiring for right now, and what does it pay?
- Which of these companies opened new roles this week?
- Which Greenhouse jobs mention visa sponsorship, or ask for fewer than 3 years of experience?
- How do I get an alert when a company on Greenhouse posts a new job?
Who uses this
- 📋 Job boards and aggregators: fresh jobs straight from the source.
- 🤝 Recruiters: watch target companies and get alerted when they open roles.
- 💼 Sales teams: hiring is a buying signal. A company hiring 5 data engineers needs data tools.
- 📈 Investors and analysts: track headcount growth, pay bands and hiring mix by department across a portfolio.
- 🧭 Job seekers: monitor dream companies for new openings.
Why this Actor
- 🌐 Paste websites, not board tokens. Enter
discord.comand the Actor finds its Greenhouse board from the careers page, or from a board named after the company. - 🔔 New jobs only. Monitoring mode remembers every job it has returned for your company list, so scheduled runs feed alerts or a database without duplicates.
- ✅ Official Greenhouse Job Board API. Greenhouse publishes it for public use. No login, no proxies, no breakage from page redesigns.
- ⚡ Live data. Jobs are fetched at run time, never stale.
- 📧 Contacts the posting shows. Email addresses and a named recruiter, as written in the job description. Nothing is looked up.
- 🔗 Need Lever, Ashby, Workable, SmartRecruiters, Recruitee, Personio or Breezy too? Use ATS Jobs Scraper: same schema, 8 ATS. For Ashby boards, see Ashby Jobs Scraper.
How to use the Greenhouse Jobs Scraper
- Click Try for free (a free Apify account is enough).
- Add companies, one per line: a company website, a board token (
airbnb), or a board URL. - Optional: add keywords, locations, remote-only, a posting-date limit, or pay and description filters.
- Click Start. Hundreds of jobs per company come back in a few seconds.
- Download the jobs as JSON, CSV or Excel, or schedule the run with monitoring mode on to get only new jobs each day.
Input
| Field | Default | What it does |
|---|---|---|
companies | required | Company websites, Greenhouse board tokens or board URLs. One per line. |
keywords | empty | Keep jobs whose title/department/team contains any of these. |
excludeKeywords | empty | Drop jobs whose title/department/team contains any of these (plain substring match, so intern also matches "international"). |
searchInDescription | false | Also match keywords against the full description. |
excludeDescriptionKeywords | empty | Drop jobs whose full description contains any of these whole words or phrases, e.g. security clearance. Unlike excludeKeywords, intern does not match international. |
locations | empty | Keep jobs whose location contains any of these (London, Germany, Remote). |
remoteOnly | false | Only remote jobs. |
postedWithinDays | 0 | Only jobs posted in the last N days. |
hasSalary | false | Keep only jobs that publish a pay figure, in the posting text. |
minSalary | 0 | Keep jobs whose top published pay, converted to a yearly amount, reaches this number. Hourly is x 2,080, weekly x 52, monthly x 12, daily x 260. 0 = off. Jobs with no pay or no stated pay period are dropped when set. |
salaryCurrency | empty | Keep only jobs whose pay is in this currency, e.g. USD. Set it with minSalary: amounts are compared as published, with no currency conversion. |
includeDescription | true | Include full descriptions. Turn off for smaller results. The description-based fields, descriptionEmails and hiringContact, need it. |
includeQuestions | false | Add applicationQuestions (label, required, type and answer options) from the application form. One extra request per returned job. |
onlyNewJobs | false | Monitoring mode: return only jobs not returned before. |
monitorName | auto | Name for monitoring memory, to share it between schedules. |
maxJobsPerCompany | 0 | Limit per company (0 = all). |
guessSlugs | true | If no Greenhouse link is found on a website, try a board named after the domain. |
maxConcurrency | 5 | Companies processed in parallel. |
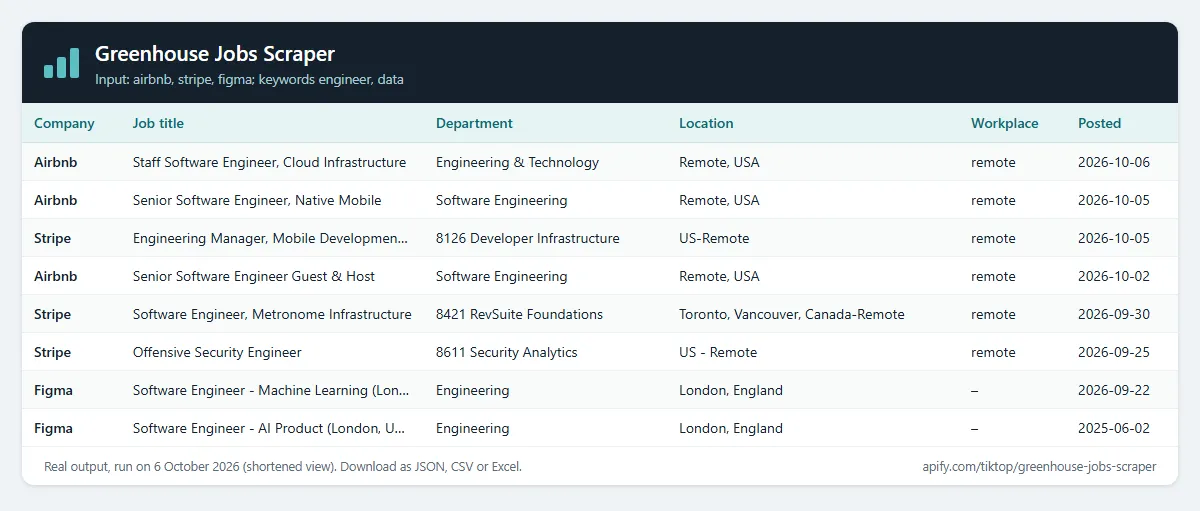
Example (the input behind the table above):
Output
One row per job. A real row from a run on airbnb (descriptions shortened):
With includeQuestions on, each row also has applicationQuestions: for this job, 18 questions, starting with {"label": "First Name", "required": true, "type": "input_text", "options": []}.
workplaceType and isRemote come from the location text and the posting, so they are null when the posting says nothing. team, country, employmentType, seniority and salary are part of the shared schema with our other job scrapers, but Greenhouse's public API doesn't provide them, so they are null here. The pay fields are read from the posting's own pay range, such as "Annual Pay Range £46,000—£54,000 GBP".
detectedVia tells you how the board was found: input (you gave it), a careers page URL (found on the company website), or slug-guess (matched by company name; double-check these).
A per-company report (jobs found, jobs returned, errors) is saved in the run's key-value store as RUN_SUMMARY.
Derived fields (rule-based, no AI)
Each value comes from wording in the posting, or it is null. Check the description when a figure matters to a decision.
- Pay (
salaryMin,salaryMax,salaryCurrency,salaryPeriod): the first pay range in the posting. Figures are in the period the posting uses; they are not converted. A figure of 10,000 or more, or akfigure, with no period is read as yearly. A smaller figure with no period staysnull, because it could be monthly. experienceLevel: intern, entry, mid, senior, lead or executive, from the title.yearsOfExperience: the minimum years the description asks for ("5+ years of experience" gives 5, "3-5 years" gives 3).visaSponsorship:truewhen the description says visa sponsorship is offered,falsewhen it says it is not,nullwhen silent.workArrangement: remote, hybrid or onsite, from the posting.keySkills: up to 25 tools and skills from a curated list of about 300 (Python, SQL, Salesforce, AWS, Figma...), in order of mention.educationRequirement: the highest degree the description mentions: phd, masters, bachelors, associate or high school.descriptionEmailsandhiringContact: the contact details the posting shows. See Contacts written in the posting.
Example tasks
Ready-made inputs you can open, change and run:
- New Greenhouse jobs at a list of companies since last run
- Data science and ML jobs at Airbnb, Stripe and Databricks
- Remote engineering jobs at Greenhouse companies
- Which Greenhouse companies are hiring salespeople
- Tech jobs in London from Greenhouse boards
What you get per job
- Title, department, all office locations, remote flag when the location says so
- First published date, last updated date
- Job link and apply link
- Full description as HTML and plain text
- Contact email addresses and a named recruiter from the description (
descriptionEmails,hiringContact) - Pay range read from the posting (when the company states one), experience level, years of experience, visa sponsorship, work arrangement, key skills and education
- With
includeQuestions, the application form questions and answer options
Contacts written in the posting
Some postings name a recruiter or give an address for applications. The Actor returns what the description says, read by fixed rules in English, German and French:
descriptionEmails: every email address in the description, including mailto links, lowercased and de-duplicated (up to 20). Role mailboxes such ascareers@oraccommodations@are kept, because the posting shows them. Image file names such aslogo@2x.pngand sample addresses such asname@example.comare dropped.hiringContact:{ "name", "email" }for a person the description names after a label: "Contact Jane Doe", "Recruiter: Jane Doe", "Hiring manager: Jane Doe", "Ansprechpartnerin: Anna Schmidt", "Contactez Claire Dubois".emailis the address that belongs to that person (it carries their surname or first name, or sits right next to the name), otherwisenull. A role mailbox is never assigned to a person, and a phrase such as "Contact Center Operations" is not read as a name.
Nothing is looked up on LinkedIn, the web or company directories, and no address is guessed. A contact that appears only in an image or a PDF is not found.
Needs descriptions. Both fields come from the description, so keep includeDescription on (it is on by default). With it off, both are null, unless a description or pay filter already read the descriptions. Greenhouse sends each job's description in the same request, so the fields cost nothing extra.
Real rows from local runs, shortened. Cloudflare, with keywords: ["architect", "engineer"]:
Databricks, with keywords: ["architect"]:
Paste company websites, get only the new jobs
Put company websites in companies (one per line), turn on Only new jobs (monitoring mode) and schedule the run.
How the Greenhouse board is found for a website:
- The homepage is read for a link to a Greenhouse board, or an embedded board.
- If there is none, up to four careers-looking links on the same site (for example
/careers,/jobs, "Join us") are read the same way. - If still nothing, a Greenhouse board named after the company's domain is tried (
discord.comtriesdiscord). Turn this off withguessSlugs. - Every board found is confirmed with Greenhouse's API before it is used.
The detectedVia field shows which step found each board. Check slug-guess rows, because a name match is a guess. A website that does not link its Greenhouse board, or that is not on Greenhouse, is reported in RUN_SUMMARY and costs nothing. Give its board token (airbnb) or board URL to be sure.
Monitoring mode
Turn on onlyNewJobs and schedule the Actor (e.g. daily). The first run returns all matching jobs. Later runs return only jobs that weren't returned before. Connect a webhook, Slack, email, Google Sheets or Zapier integration to get alerts. The memory is tied to your company list; set monitorName to keep it when you edit the list.
Jobs that a filter removes are not remembered, so they are returned on a later run if the filter changes to let them through. Jobs cut off by maxJobsPerCompany are also not remembered, and come back in a later run.
What this Actor does not do
- It does not log in, use cookies or accounts, or solve CAPTCHAs. It reads only the public job-board data Greenhouse publishes.
- It does not read other ATS. Use ATS Jobs Scraper for those.
- It does not look people up or guess addresses. A recruiter's name or email appears only when the posting itself shows it, and it never returns LinkedIn profiles or contact details from other sources. Demographic survey questions are left out of
applicationQuestions.
How much does it cost?
Pay per event:
- Job result: $0.001 per job returned ($1.00 per 1,000).
- Actor start: $0.00005 per GB of memory (default 1 GB = $0.00005 per run).
- Companies that fail, use another ATS, or have no matching jobs cost nothing.
- Filters are applied before charging. You only pay for jobs you get.
| What you run | Cost |
|---|---|
| Airbnb's 163 open jobs (test run, 2026-10-08) | about $0.16 |
| 20 companies, about 2,000 jobs | about $2 |
| Daily monitoring that finds 30 new jobs a day | about $0.90 a month |
Apify's free plan includes $5 of credit every month, enough for about 5,000 jobs. Paid Apify plans get Store discounts of up to 25%. Set a maximum cost per run in the run options; the Actor stops cleanly when it's reached.
FAQ
Is this legal? It reads job postings through Greenhouse's public Job Board API, the feed companies use to syndicate their jobs. Job postings are company information. The Actor returns only the contact details the posting itself shows, and it looks nobody up.
Are the contact fields complete? No. They are read from the text of the posting with fixed rules. An address written in an unusual way, such as jane [at] acme [dot] com, or a contact that appears only in an image, is not found.
How do I find a company's board token? It's the part after boards.greenhouse.io/ (or job-boards.greenhouse.io/) on their careers page. Or just enter the company website.
Are EU-hosted boards (job-boards.eu.greenhouse.io) supported? Not yet; Greenhouse has no public API host for them.
Can I search all Greenhouse companies at once? Not with this Actor; it fetches live jobs from the companies you list. To search thousands of Greenhouse, Lever and Ashby companies at once, use Startup Jobs Search.
Are the pay and experience fields accurate? They are read from the posting's wording with fixed rules, so they show what the company wrote. Check the description for anything that matters to a decision.
How fast is it? Hundreds of jobs per company in a few seconds.
Related Actors
- ATS Jobs Scraper: the same, for 8 ATS including Lever, Ashby and Workable.
- Ashby Jobs Scraper: Ashby boards, with salary ranges.
- Startup Jobs Search: search 260,000+ jobs from 8,000+ companies at once.
- Company Signals MCP: hiring data for Claude, ChatGPT and Cursor.


