Facebook URL to ID Scraper
Pricing
from $1.99 / 1,000 results
Facebook URL to ID Scraper
Facebook URL to ID Scraper — Convert Facebook profile, page, group, and video URLs into their corresponding Facebook IDs. Useful for data extraction, automation, lead generation, audience research, and building Facebook scraping workflows.
Pricing
from $1.99 / 1,000 results
Rating
0.0
(0)
Developer

Social Data API
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
0
Monthly active users
7 hours ago
Last modified
Categories
Share
Facebook URL to ID Scraper — Page, Group and Post IDs with Metadata
Facebook URL to ID Scraper turns public Facebook page, group and post links into their Facebook IDs. Each row also carries the link type, canonical URL, Open Graph title, description and image, plus the group name and member count or the post ID and owner page ID. Every response is structured JSON — ready to pass directly to an LLM, index into a vector store, or feed a CRM enrichment pipeline. No Facebook account or cookies needed. Paste one link to test, then resolve your whole list in one run.
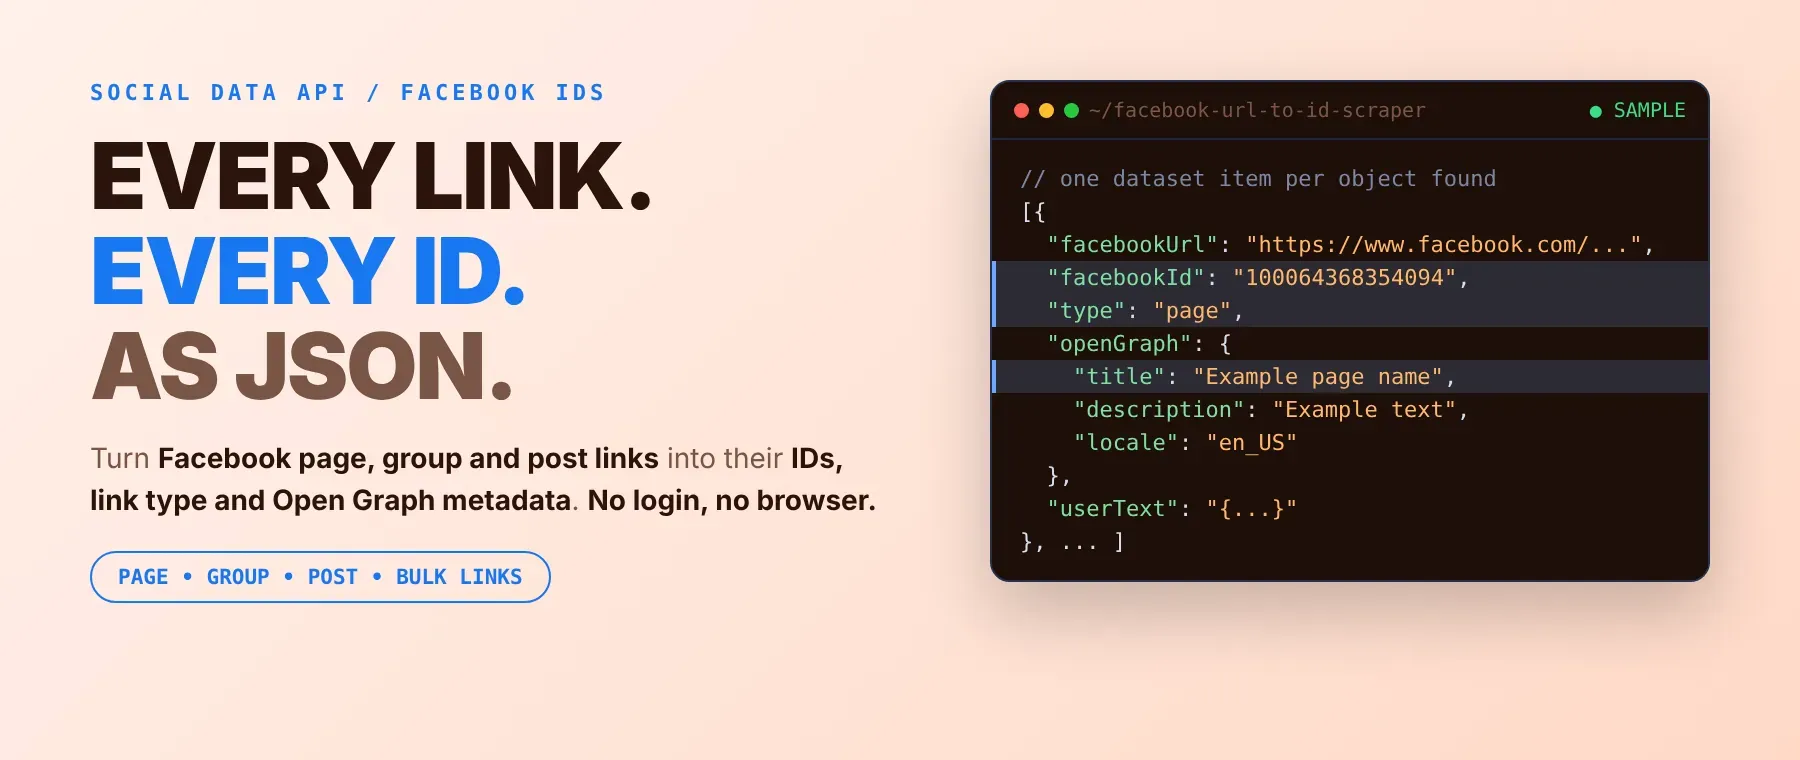
What data can I extract with Facebook URL to ID Scraper?
Using this Facebook ID API, you will be able to extract the following Facebook link data:
| 🆔 Facebook ID | 📂 Link type (page, group or post) | 🔗 Canonical Facebook URL | 🌐 Resolved URL |
|---|---|---|---|
| 📣 Open Graph title and description | 🖼️ Preview image | 🌍 Locale | 📱 App-link IDs (Android and iOS) |
| 👤 Page or profile object (pages) | 📢 Ad Library page ID (when shown) | 👥 Group name and ID | 🔢 Group member count text |
| 🚪 Group join state | 🧾 Post ID | 🏠 Owner page ID of a post | 🧩 Post story details |
| 🧭 Source URL that was fetched | 📄 Text copies of every object for tables and CSV |
How to use Facebook URL to ID Scraper
Marketers, ad engineers and data teams use this Facebook ID finder to turn a list of Facebook links into IDs and public metadata in one run.
Copy to your AI assistant:
Facebook URL to ID Scraper MCP Server: use these Actors from ChatGPT, Claude or Cursor
Point your AI assistant at Apify's MCP server and it can read Facebook links on its own: the server starts with this Actor already loaded as a tool, so your agent runs it and reads the rows. No glue code, no scraping logic in your prompts.
Step by step
- Create a free Apify account.
- Open Facebook URL to ID Scraper in the Apify Store.
- Enter the Facebook page, group or post links, or page usernames, one per line.
- Click Start (or send your API request).
- Download or stream your results in JSON, CSV or Excel.
How to scale Facebook URL to ID Scraper to bulk
Put every link and username into the same list, one per line: one run works through them in order, with a one-second pause between links, and writes all rows into one dataset. That makes it a bulk Facebook ID converter for spreadsheets of mixed links. For a recurring job, save the input as an Apify task and run it on a schedule, or start several runs through the Apify API with different lists. Each saved row is one row_result charge event; a page link usually saves about five rows.
✨ Features
Facebook URL to ID Scraper fetches clean, structured Facebook IDs and link metadata from Facebook ⚡. It's ideal for ad-account setup, CRM enrichment, de-duplicating link lists and mapping vanity links to IDs that survive username changes.
It extracts, per link:
- Facebook ID – the numeric page or profile ID (a Facebook profile ID lookup for public profiles), the group ID, or Facebook's story ID for posts
- Link type – page, group or post, detected from the link
- Open Graph data – title, description, preview image, locale and app-link IDs
- Group details – group name, member count text and join state
- Post details – the numeric post ID and the ID of the page that owns the post
- Ad Library page ID – when Facebook shows one for the page
⚡ No browser and no login: each link is one page fetch through a residential IP, retried on a fresh IP when Facebook blocks it.
Use cases 💡
- Ads engineer — find Facebook page ID values for every brand link before building audiences.
- Community manager — use it as a Facebook group ID finder and log member count text.
- Data engineer — swap vanity links for Facebook IDs so joins survive username changes.
- Social analyst — use it as a Facebook post ID extractor next to each owner page ID.
- AI agent builder — feed page titles and descriptions to an agent as company context.
Building an AI agent? Connect Facebook URL to ID Scraper over MCP and let it call the actor on its own.
Why choose this actor?
- Four kinds of input in one list. A recorded test run resolved 4 links (a page, a profile, a post and a group) into 12 rows in 11 seconds.
- The ID plus the context around it. A recorded page row came back with the page ID 100064368354094, the title "Nintendo of America" and a description showing 5,644,661 followers; a recorded group row carried the group ID 270834543757117 and "901.2K members".
- 3 link types, 20 output fields. Pages, groups and posts are detected automatically, and every row keeps the raw Facebook objects next to plain-text copies for tables.
⬇️ Input
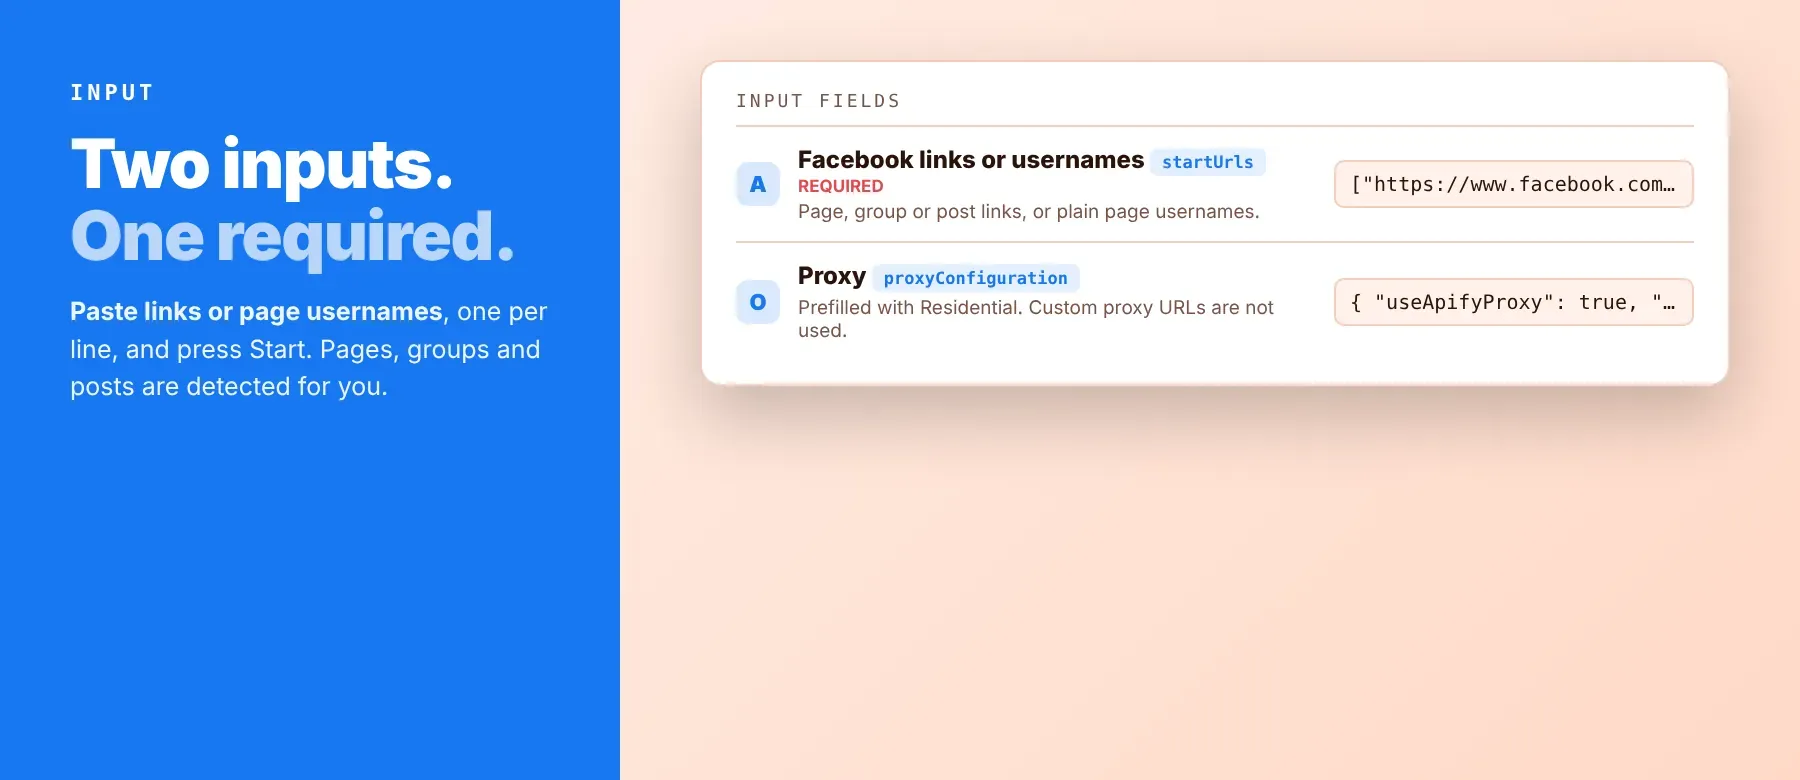
The actor accepts a list of Facebook links or page usernames, one per line, so you can get Facebook ID from URL lists in one run. startUrls is the only required field.
| Parameter | Required | Type | Description | Example value |
|---|---|---|---|---|
startUrls | Yes | array of strings | Facebook page, group or post links, page usernames or @usernames. Text that is not a link becomes https://www.facebook.com/<text> (spaces become hyphens); there is no keyword search. Empty lines are skipped. No default. | ["https://www.facebook.com/NintendoAmerica"] |
proxyConfiguration | No | object | Apify Proxy settings. Every request goes through Apify Residential proxy; groups (and a country) you pick are used when Apify Proxy is on with groups set. Custom proxy URLs are not used. Prefilled with Residential. | {"useApifyProxy": true, "apifyProxyGroups": ["RESIDENTIAL"]} |
Accepted link formats:
- Pages and profiles:
https://www.facebook.com/NintendoAmerica,NintendoAmerica,@NintendoAmerica - Groups:
https://www.facebook.com/groups/python - Posts:
https://www.facebook.com/zuck/posts/10117999199162391(links with/posts/,/permalink/or/photoare read as posts)
Free plan limits
Users on the Apify free plan can fetch up to 20 rows per run (all links together) and 200 rows per month. When the limit is reached, the run finishes successfully with a status message explaining the limit. Upgrade to any paid Apify plan to remove these limits.
Example input
⬆️ Output
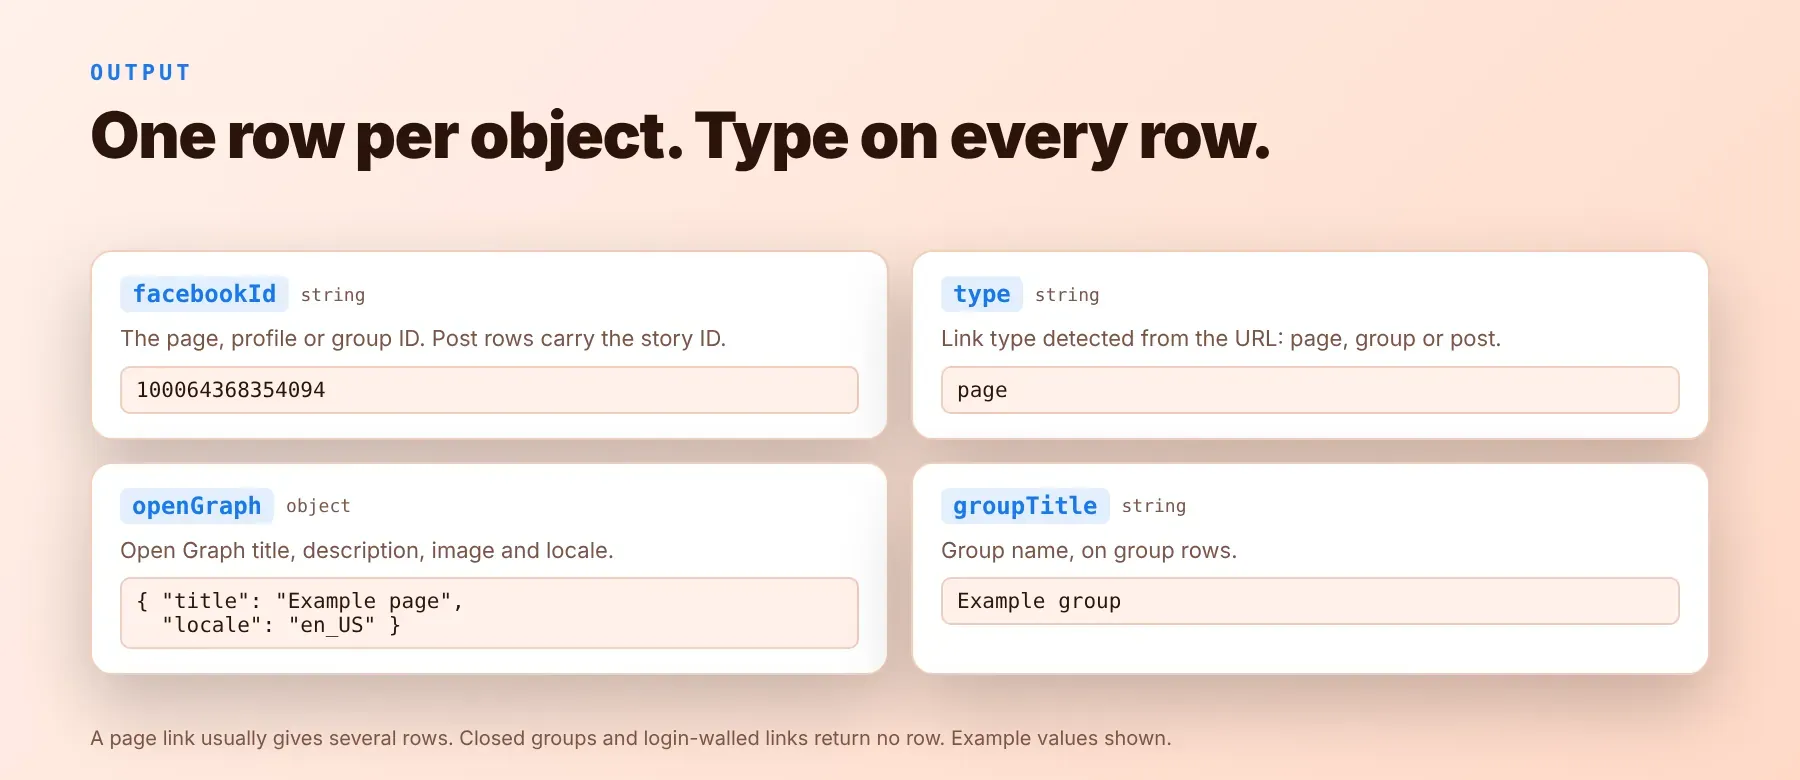
Every row is one typed JSON item with the same top-level fields on every run, plus the raw Facebook objects that fit its link type (page, group or post). Export formats: JSON (default), CSV, Excel.
Example output
Real rows from a test run: a page row and a group row. Long text fields and nested objects are shortened here (…).
Post rows add the numeric post ID, the owner page ID, the full story details and the source URL that was fetched; their Facebook ID is Facebook's encoded story ID.
How does it work?
This Facebook ID scraper works like a logged-out visitor, so you never need a Facebook account. Every request goes through a rotating residential IP from Apify Proxy, and your link is loaded with plain HTTP requests, without a browser. The actor then reads the public information Facebook shows for that link, including the page, group or post IDs. When Facebook answers with a block or a login wall, the link is retried up to three times, each time on a fresh residential IP. It returns only what any visitor sees without logging in; closed groups and login-walled links return nothing. Every row uses the same field names, and the raw Facebook objects are kept next to their plain-text copies, so you can parse as much or as little as you need.
How do you integrate Facebook URL to ID Scraper into your stack?
It works with what you already use: the Apify REST API from any language, MCP for AI agents, and no-code tools.
MCP integration for AI agents
This registers Apify's MCP server in your client with this Actor already loaded as a tool; your agent calls it directly, passing the same JSON input you would use in the Console. Sign in with your Apify account when the client asks. Compatible clients include Claude Code, Cursor and Windsurf.
No-code tools (n8n, Make, LangChain)
n8n: add the Apify node, choose "Run an Actor", pick this Actor and pass the same JSON input; the next node receives the dataset rows with each Facebook ID.
Make: use the Apify app's "Run an Actor" module, then "Get Dataset Items" to map the Facebook ID, link type and Open Graph title into Google Sheets or a CRM.
LangChain: the langchain-apify package's ApifyActorsTool runs an Apify Actor by its ID (socialdataapi/facebook-url-to-id-scraper); the agent then gets the rows back as tool output.
Is it legal to scrape Facebook data?
Collecting publicly available Facebook data, such as page, group and post IDs shown to logged-out visitors, is generally lawful in many jurisdictions. This actor returns only publicly available data: what any user sees without logging in. Some rows can include names of public pages or of people who posted publicly. Under GDPR, scraping public data is generally permissible, but storing and using it must comply with local data-protection law. Consult legal counsel if your use case involves bulk storage of personal data.
Frequently asked questions
What fields does Facebook URL to ID Scraper return?
It returns the Facebook ID, the link type, the canonical URL, the Open Graph title and description, and for groups and posts the group details or the post ID. See the data fields section for the full list.
Does Facebook URL to ID Scraper require a Facebook account or login?
No. Only public data that Facebook shows to logged-out visitors is extracted. No credentials or cookies are needed.
How fast does Facebook URL to ID Scraper run?
A recorded test run resolved 4 links into 12 rows in 11 seconds. Every link is fetched live from Facebook, not from a cache; a link that Facebook blocks takes longer because it is retried on a fresh IP.
What happens if a link is private or doesn't exist?
A closed group or a link behind Facebook's login wall returns no row, and the run log shows a warning for it. A page that does not exist returns one row with the Facebook ID set to null, so check for a null ID in your code. A link that cannot be fetched at all also returns no row.
Can I scrape multiple Facebook links at once?
Yes. Put as many links and usernames as you need into the list, one per line; the run works through them in order and saves all rows into one dataset.
Does Facebook URL to ID Scraper work with Claude, ChatGPT, and other AI agent tools?
Yes — Facebook URL to ID Scraper is available as an MCP tool through Apify's MCP server. Register it in Claude Code, Cursor or Windsurf with claude mcp add --transport http apify "https://mcp.apify.com?tools=socialdataapi/facebook-url-to-id-scraper", and the agent gets this Actor as a ready-to-call tool. Any agent that can call an HTTP endpoint can use the Apify REST API directly.
Does Facebook URL to ID Scraper return data in a format LLMs can use directly?
Yes. Every row is JSON with consistent field names, and each nested object also comes as a plain-text copy. No HTML parsing, no selectors: pass it straight to an LLM, index it into a vector store, or feed it to an agent tool.
What happens when Facebook changes its layout or updates its anti-bot system?
The actor is maintained. When Facebook changes, the actor is updated, and your calls keep returning the same field names with no changes on your end.
Can I use Facebook URL to ID Scraper without managing proxies or browser infrastructure?
Yes. Residential proxy rotation and retries on a fresh IP run on the actor's side, and it uses plain HTTP, so there is no browser to run. You send one request and get JSON back.
Which Facebook link fields work best for AI training data and RAG indexing?
For RAG, use the Open Graph title and description and the group name as text, keyed by the Facebook ID. For structured data, the Facebook ID, link type, post ID and owner page ID are the most consistent fields across rows. Values come as strings, numbers, booleans and nested objects exactly as Facebook provides them.
Your feedback
Found a bug or missing a field? Let us know on the Issues tab of this Actor's page in Apify Console. Include the links you ran, so the problem can be reproduced quickly; every report is read and fixes are shipped in new versions.