
Reddit API Scraper
Pricing
from $0.95 / 1,000 results
Reddit API Scraper
Reddit API Scraper searches Reddit by keyword or subreddit and returns post title, subreddit, author, score, upvote ratio, comment count and flair, with sort options. No Reddit account or API key needed. Export as JSON, CSV or Excel, or use the API.
Pricing
from $0.95 / 1,000 results
Rating
0.0
(0)
Developer

Social Data API
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Share
Reddit API Scraper — Titles, Scores and Comments
Reddit API Scraper is a reddit scraper that searches Reddit by keyword and returns structured post data — title, subreddit, author, score, upvote ratio, and comment count. Search all of Reddit or narrow to specific subreddits, then sort by new, hot, top, relevance, or comments. Every response is structured JSON, ready to pass to an LLM, index into a vector store, or feed a brand-monitoring pipeline. No Reddit account, API key, or OAuth setup is needed — only public post data is read. Start with one keyword and scale from there.
What data can I extract with Reddit API Scraper?
Using this Reddit post search API, you will be able to extract the following Reddit data:
| 🔎 Keyword matched | 🆔 Post ID | 📝 Title | 💬 Self text (if text post) |
|---|---|---|---|
| 📘 Subreddit | 👤 Author username | ⭐ Score (net upvotes) | 💬 Comment count |
| 📊 Upvote ratio | 🔁 Crosspost count | 🏆 Award count | 📅 Created date (epoch + ISO) |
| 🚩 NSFW flag | 🎞️ Is-video flag | 📄 Is-self-post flag | 🖼️ Is-gallery flag |
| 🔗 Permalink | 🌐 Full URL | 🏷️ Post flair | 🏷️ Author flair |
| 🆔 Subreddit ID | 🔒 Subreddit type | 🔢 Post fullname (prefixed ID) | 🆔 Author ID |
How to use Reddit API Scraper
Anyone who needs to scrape Reddit posts by keyword — a brand manager, a market researcher, or a RAG pipeline builder — gets one typed JSON row per matching post, grouped by keyword, from a single run.
Copy to your AI assistant:
Reddit API Scraper MCP Server: use these Actors from ChatGPT, Claude or Cursor
Add the Apify MCP server and your AI assistant can find and call this Actor on its own — no glue code, no scraping logic in your prompts.
Step by step
- Create a free Apify account.
- Open Reddit API Scraper in the Apify Store.
- Enter your search keyword(s) and, optionally, the subreddits to scope the search to.
- Click Start.
- Download or stream your results in JSON, CSV or Excel.
How to scale Reddit API Scraper to bulk
Used as a bulk reddit post scraper, searchKeywords and subredditNames both accept multiple values with bulk-edit support (one entry per line), so a single run already searches every keyword — optionally scoped to every listed subreddit — without repeated runs. Raise resultsLimitPerKeyword (up to 1000) to pull more posts per keyword in the same run.
✨ Features
Reddit API Scraper is a reddit data extractor that fetches clean, structured posts matching your keywords ⚡ with no HTML parsing required. It's ideal for brand and keyword monitoring, building a RAG corpus from real discussion text, tracking engagement trends over time, and scouting mentions inside specific communities.
It extracts, per post:
- Title and self text – the post's own headline and body text for text posts
- Engagement metrics – score, upvote ratio, comment count, crosspost count, and awards
- Subreddit and author – which community the post is in and who posted it
- Flair and flags – post and author flair, plus NSFW/video/gallery/original-content flags
- Timestamps – post creation time as both a raw Unix timestamp and an ISO 8601 string
⚡ Posts are written to the dataset the moment each one is found for its keyword, not buffered until a keyword or the run finishes, and every request runs through a fresh residential proxy session.
Use cases 💡
Whether you need a reddit keyword monitoring tool for ongoing brand tracking or a one-off research pull, here's who gets value from each field:
- Brand manager — run it as a reddit brand mention scraper, tracking mentions by subreddit, score, and comment count to spot which communities drive engagement.
- Market researcher — build a time-ordered corpus of discussion text for a topic using self text and creation date.
- RAG/AI engineer — feed title and self text into a retrieval index, citing the permalink.
- Data analyst — chart engagement trends for a keyword over time using score and upvote ratio.
- Community manager — scope a search to specific subreddits and track recurring authors.
Building an AI agent? Connect Reddit API Scraper over MCP and let it call the actor on its own.
Why choose this actor?
- Streams every match as it's found. Each post is pushed to the dataset the moment it's fetched for its keyword — not buffered until a keyword or the run finishes — and pages are deduplicated by post ID as they're walked.
- 36 documented fields per post. Every row carries title, self text, engagement metrics, flair, timestamps, and both an author and subreddit identity, with no HTML to strip out.
- 5 sort orders and subreddit scoping, one Actor. Search all of Reddit or scope to specific subreddits, sorted by new, hot, top, relevance, or comments, with results from other orders merged in automatically when one order alone can't reach your requested limit.
⬇️ Input
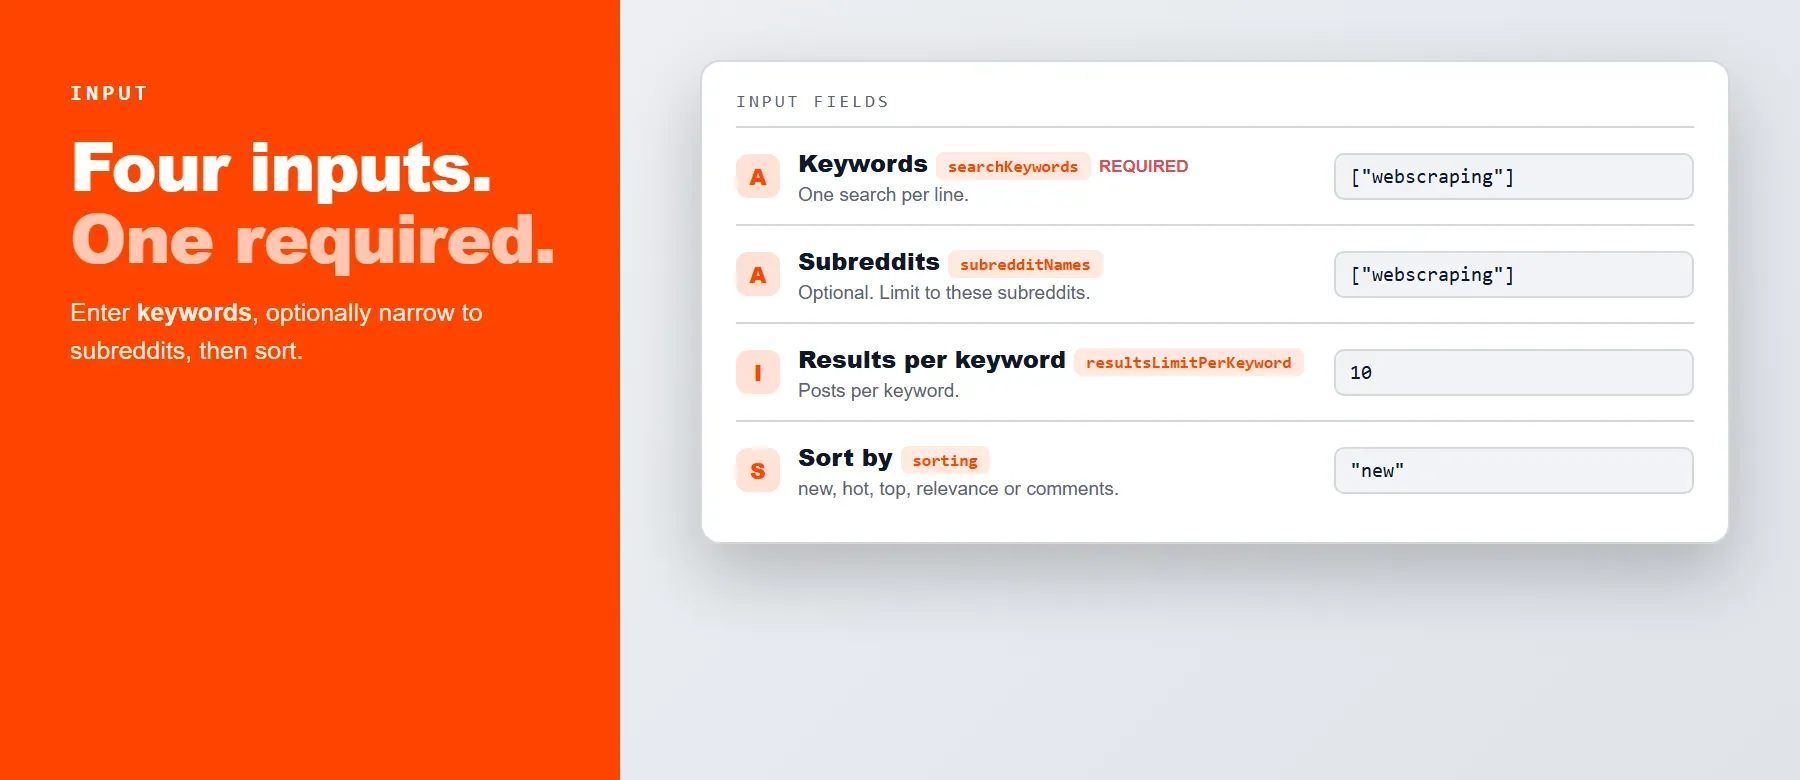
The Actor accepts one or more search keywords in searchKeywords — the only required field.
| Parameter | Required | Type | Description | Example value |
|---|---|---|---|---|
searchKeywords | Yes | array | Words or phrases to search on Reddit. Bulk-edit supported, one keyword per line. | ["webscraping", "python"] |
subredditNames | No | array | Restrict the search to specific subreddits. Leave empty to search all of Reddit. | ["webscraping"] |
resultsLimitPerKeyword | No | integer (default 10, minimum 1, maximum 1000) | Maximum number of posts to fetch per keyword. Higher values take longer. | 50 |
sorting | No | string enum (default "new") | Post order: new, hot, top, relevance, or comments. | "new" |
Free plan limits
Free plan: up to 20 posts per run (all keywords together) and 200 per month; paid plans have no limit.
Example input
⬆️ Output
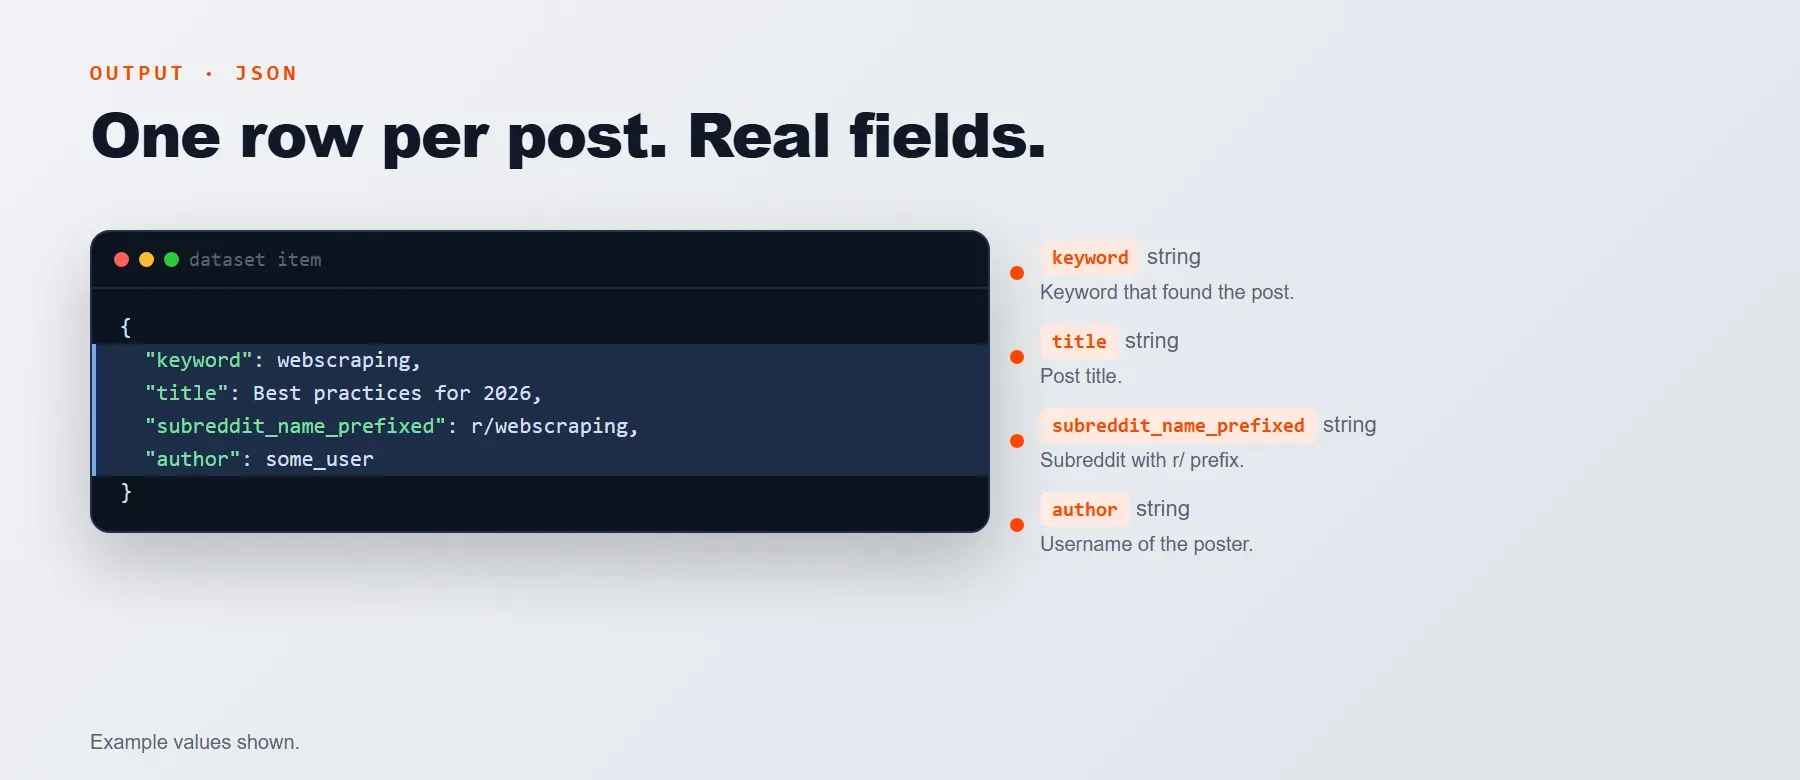
Every matching post is one typed, normalized JSON item with the same 36-key field set on every run, written to the dataset the moment it's found. Export Reddit posts to CSV, JSON, Excel, or any other format the Apify dataset export supports.
Example output
How does it work?
The Actor runs Reddit's own post search over plain HTTP rather than rendering reddit.com in a browser, so there is no headless browser in the request path. Your keyword, and optionally each subreddit, is searched in the order you picked, following pages until your configured limit is reached and deduplicating by post ID along the way. Every request goes through a fresh residential proxy session, and a refused or timed-out page is retried before being given up on. Only publicly accessible post data is returned, and the output schema stays stable regardless of changes to Reddit's own site or ranking algorithms.
How do you integrate Reddit API Scraper into your stack?
Reddit API Scraper works with what you already use: a REST API callable from any language, MCP for AI agents, and no-code automation tools.
No-code tools (n8n, Make, LangChain)
In n8n, use the Apify node's "Run an Actor" action, or the HTTP Request node pointed at the Actor's run-sync endpoint with your Apify token. In Make, use the Apify app's "Run an Actor" module followed by "Get Dataset Items" to route new matching posts into Slack, a spreadsheet, or a CRM. In LangChain, install langchain-apify and call ApifyActorsTool() once the Actor is in your account to let an agent run it directly.
MCP integration for AI agents
Add the Apify MCP server and your agent can search for, add, and call this Actor on its own:
This registers the Apify MCP server as a tool your agent can call directly. Compatible with Claude Code, Cursor, and Windsurf.
Is it legal to scrape Reddit posts?
Scraping publicly visible Reddit content is generally lawful — data a website makes available without requiring a login falls outside the scope of anti-hacking laws like the U.S. Computer Fraud and Abuse Act (hiQ Labs, Inc. v. LinkedIn Corp., 9th Cir., 2019). Reddit API Scraper returns only publicly visible data — whatever content and metadata anyone can see on Reddit without signing in. Because each post record includes an author's Reddit username, it can still count as personal data under GDPR or CCPA if that username is linked or linkable to an identifiable person. Consult legal counsel if your use case involves bulk storage of personal data.
Frequently asked questions
What fields does Reddit API Scraper return?
The top fields are title, subreddit, author, score, and comment count, alongside 31 more covering flair, timestamps, and post flags — see the data fields section for the full list.
Does Reddit API Scraper require a Reddit account or login?
No. This reddit API scraper no login tool needs no Reddit credentials, API key, or app registration to set up — only an Apify account to run it.
What happens if a search returns zero results?
The Actor logs the keyword as returning 0 posts and moves on to the next one; no error is thrown and the run continues.
Can I scrape multiple Reddit keywords or subreddits at once?
Yes. As a reddit subreddit search scraper, searchKeywords and subredditNames both accept multiple values with bulk-edit support, and every keyword is searched against every listed subreddit — or all of Reddit if none are given — in the same run.
Does Reddit API Scraper work with Claude, ChatGPT, and other AI agent tools?
Yes — it's reachable through the Apify MCP server, which lets an AI assistant find and call it directly. Any agent that can call an HTTP endpoint can also use the REST API directly.
Does Reddit API Scraper return data in a format LLMs can use directly?
Yes. Typed, normalized JSON with consistent field names, no HTML parsing and no selectors. Pass title and self text straight to an LLM, index them into a vector store, or feed them to an agent tool with no transformation step.
What happens when Reddit changes its layout or anti-bot system?
The maintaining team updates the Actor when Reddit changes its site or defenses — your calls keep returning the same JSON schema with no changes on your end.
Can I use Reddit API Scraper without managing proxies or browser infrastructure?
Yes. There's no browser to configure — requests go out over plain HTTP — and a residential proxy session is applied automatically to every request.
Which Reddit post fields work best for AI training data and RAG indexing?
For RAG, index title and self text as your text content and keep the permalink as the citation link. For training data, post ID, created date, score, and comment count return as consistently typed primitives across every record.


