
SimilarWeb Scraper - Website Traffic, Rank & Competitors
Pricing
from $2.80 / 1,000 website profiles
SimilarWeb Scraper - Website Traffic, Rank & Competitors
Scrape SimilarWeb traffic data for any website: global, country and category rank, monthly visits with trend, bounce rate, pages per visit, the full traffic-source split, top countries, organic keywords, AI-assistant traffic and competitors. Monitor mode re-checks domains and returns only changes.
What does SimilarWeb Scraper do?
SimilarWeb Scraper turns a list of domains into structured SimilarWeb website traffic, rank and competitor data: one row per website with its global, country and category rank, monthly visits and trend, engagement, the full traffic-source split, top countries and keywords and the AI-assistant traffic share, plus up to 20 ranked competitors per site as an add-on. Built for SEO teams, growth marketers, sales and lead-scoring teams, investors and researchers who need website traffic data in bulk without a paid SimilarWeb seat.
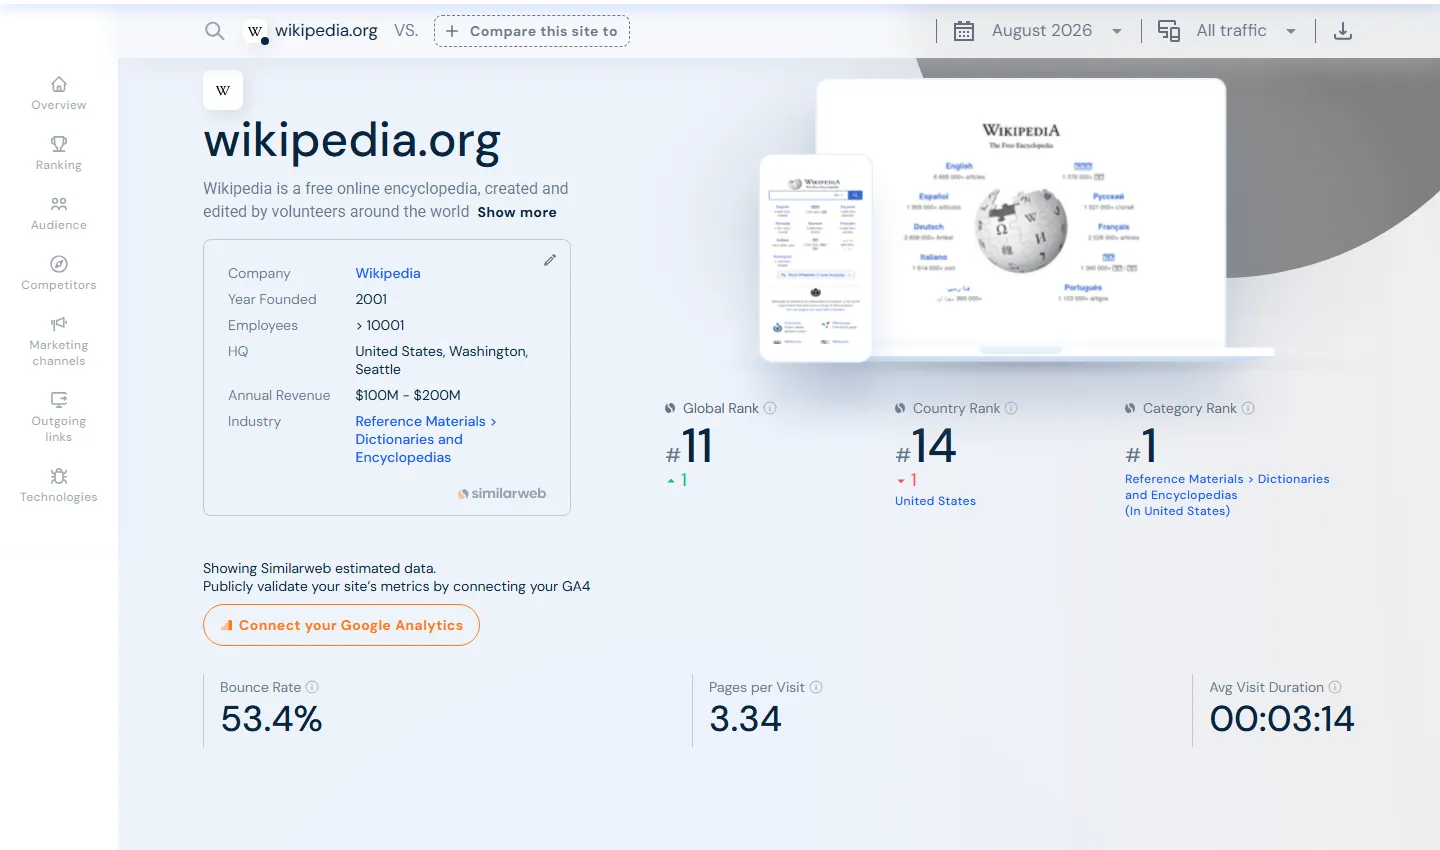
- Every number on the overview page: rank, visits, bounce rate, pages per visit, visit duration, channel mix, top countries and keywords
- Bulk by design: paste thousands of domains, bare or as full URLs; one run returns one clean row per site
- AI-assistant traffic, broken out: the share of visits from ChatGPT, Gemini, Perplexity, Claude and Copilot, with month-by-month history and the actual AI-search prompts — the field most scrapers miss
- Competitors on demand: up to 20 ranked similar sites per domain with category, estimated visits and a similarity score
- No login, no cookies, no SimilarWeb API key: you pass domains and nothing else
- Pay only for delivered sites: no start fee, and domains SimilarWeb has no data for cost nothing
- Monitor mode: re-check the same domains on a schedule and get only the ones whose numbers moved
- Export and automate: JSON, CSV, Excel, XML; schedules, webhooks, Make, Zapier, n8n, Google Sheets, Slack, the API and MCP
What website traffic, rank and competitor data can you get from SimilarWeb?
| 🏆 Global rank (`globalRank`) | 🌍 Country rank (`countryRank`) | 🏷️ Category rank (`categoryRank`) |
| 📈 Monthly visits (`totalVisits`) | 📊 3-month trend (`monthlyVisitsTrendPct`) | ↩️ Bounce rate (`bounceRate`) |
| 📄 Pages per visit (`pagesPerVisit`) | ⏱️ Visit duration (`avgVisitDuration`) | 🧭 Traffic sources (`trafficSources`) |
| 🔗 Direct / referral share | 🔎 Search share (organic + paid) | 📣 Social & display share |
| 🤖 AI-assistant share (`aiShare`) | 💬 Per-assistant split (`aiShareChatgpt`…) | ❓ AI-search prompts (`aiTopPrompts`) |
| 🌐 Top countries (`topCountries`) | 🔑 Top keywords + CPC (`topKeywords`) | 🥊 Competitors (`competitors`) |
On a 21-site test run every row had its rank, visits, engagement, traffic-source split, top countries and keywords (100% fill), 21 of 21 had the AI-assistant share, and with includeCompetitors on, competitors returned 20 similar sites per site.
How to scrape SimilarWeb with SimilarWeb Scraper
- Create a free Apify account — $5 of monthly credit, no card needed.
- Open SimilarWeb Scraper and click Try for free.
- Paste your domains into Websites (bare domains or full URLs both work) and set Max sites to deliver.
- Click Start. Rows stream into the dataset as each site is fetched.
- Open the Storage tab and Export as JSON, CSV or Excel — or let a schedule run it for you.
⬇️ Input
| Parameter | Type | Description |
|---|---|---|
| 🔍 What to scrape | ||
domains | List | Required. Domains or URLs, one per line: wikipedia.org, https://www.bbc.com/news, apify.com. The registrable domain is extracted and duplicates merged. |
| ✂️ Refine results | ||
minMonthlyVisits | Integer | Keep only sites with at least this many visits last month. Default 0 (no minimum). |
maxGlobalRank | Integer | Keep only sites at or above this global rank. Default 0 (no limit). |
countries | List | Two-letter codes (US, GB). Keep only sites whose largest audience country is in the list. |
categoryFilter | List | Keep only sites whose category contains one of these words (news, finance). |
| ➕ Extra data | ||
includeCompetitors | Boolean | Add up to 20 ranked similar sites per domain — charged as competitors only for sites that return at least one. Default false. |
includeUnavailable | Boolean | Write a row for domains with no data or invalid inputs, so a bulk list is complete. Default false. |
| 🔁 Monitoring | ||
monitorMode | Boolean | Deliver a domain only if it is new or its rank/visits/bounce/AI-share changed. Pair with a daily schedule. |
monitorStoreName | String | Name of the key-value store that holds the per-domain memory. |
| 📦 Output | ||
maxResults | Integer | Stop after this many delivered sites (your cost cap). Default 0 = every domain. |
compact | Boolean | Core fields only, sized for AI agents and MCP. |
| ⚙️ Advanced | ||
proxyConfiguration | Object | Residential proxy (the default); SimilarWeb rate-limits a single IP, so the scraper uses a fresh session per domain. |
maxConcurrency | Integer | Domains fetched in parallel. Default 8. |
Input JSON
Paste domains any way you have them
The Websites field accepts bare domains, www. addresses and full URLs — wikipedia.org, https://www.bbc.com/news and BBC.COM all resolve to the same site. A subdomain such as en.wikipedia.org is looked up as its own property.
Filter SimilarWeb sites by visits, rank, country and category
minMonthlyVisits, maxGlobalRank, countries and categoryFilter are applied after the data is fetched. Use them to keep only the sites that matter — say every domain over a million visits whose top audience is in the US.
⬆️ Output
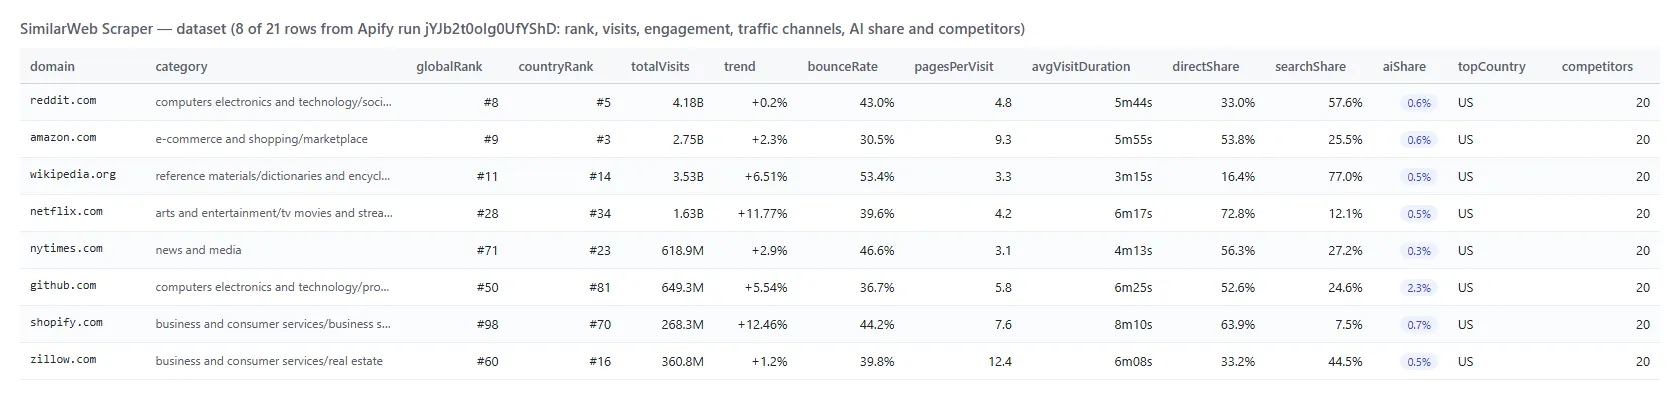
Every website becomes one dataset item. Here is the table view of a run for a mix of domains:
And the same row as JSON (trimmed):
Fields
| Field | Type | What it is | Fill on test run |
|---|---|---|---|
globalRank | number | Global traffic rank (1 = most visited) | 100% |
totalVisits | number | Estimated visits last month | 100% |
monthlyVisitsTrendPct | number | Percent change across 3 months | 100% |
bounceRate / pagesPerVisit / avgVisitDuration | number | Engagement metrics | 100% |
trafficSources | object | 10-channel share split, 0–1 | 100% |
aiShare / aiShareChatgpt… | number | AI-assistant traffic share | 100% (AI columns on sites with AI traffic) |
topKeywords | array | Organic keywords with volume and CPC | 100% |
competitors | array | Up to 20 ranked similar sites | 20 per site with includeCompetitors |
How can I use SimilarWeb traffic data?
- 🎯 SEO & content teams — benchmark a market: pull rank, visits, bounce and the keyword list for every competitor in one run.
- 📊 Growth marketers — read each site's channel mix to see who leans on search, social, referral or paid, and where the gaps are.
- 🤖 GEO / AI-search teams — track the
aiShareand per-assistant split to see which sites ChatGPT, Gemini and Perplexity send traffic to. - 💼 Sales & lead scoring — enrich a list of prospect domains with traffic size and trend to prioritise the accounts worth a call.
- 📈 Investors & analysts — verify a company's traffic claims and watch month-over-month trend direction across a portfolio.
- 🔁 Anyone on a schedule — run it weekly in monitor mode and get only the domains whose rank or visits moved.
How much does it cost to scrape SimilarWeb?
SimilarWeb Scraper is pay-per-result: $0.0028 per website ($2.80 per 1,000 domains), no start fee. Competitors are an optional add-on at $0.0009 per site that receives them.
| Sites | Cost | With competitors |
|---|---|---|
| 10 | $0.028 | $0.037 |
| 100 | $0.28 | $0.37 |
| 1,000 | $2.80 | $3.70 |
| 10,000 | $28.00 | $37.00 |
There is nothing else to pay: Apify platform usage (compute, proxy) is included in these prices. A 21-site run with competitors took about one minute on 256 MB.
Integrations, API, scheduling & MCP
- Schedules: run SimilarWeb Scraper daily or weekly from the Schedules tab; combine with monitor mode to collect only changed sites.
- Webhooks: fire a URL when a run finishes — push rows to your CRM, a sheet or Slack.
- No-code: Make, Zapier, n8n, Google Sheets, Airtable and Slack via Apify integrations.
- API: call it from Node.js or Python with
apify-client— code on the API tab and the Apify API reference. - MCP / AI agents: connect Claude, Cursor or any MCP client through the MCP tab and ask for website traffic in plain language; turn on
compactto keep the payload small.
More SimilarWeb and web-data scrapers
| 📍 Google Maps Reviews Scraper | 🎬 TikTok Video Scraper | 👤 Instagram Scraper |
| 💼 Indeed Jobs Scraper | 📣 Facebook Search Posts Scraper | 🧭 All our scrapers |
SimilarWeb data limits & empty runs
- One row per domain: SimilarWeb publishes one traffic profile per site; there is no per-run ceiling because each domain is its own lookup.
- Estimates, dated: the numbers are SimilarWeb's monthly estimate;
snapshotDatesays which month, andisDataFromGoogleAnalyticsis true only when the site owner connected GA. - No data: small or brand-new sites that SimilarWeb has no measurement for come back as
status: no_datawith every metric null (never a fake zero). - Competitors: some sites have no similar-sites data; those rows carry an empty
competitorsarray. - Proxy: SimilarWeb rate-limits a single IP, so Residential proxy is on by default with a fresh session per domain. An empty dataset means the inputs were not valid domains or every site was filtered out — the run log says which.
FAQ
How many websites can SimilarWeb Scraper collect in one run?
As many as you paste. One run handles thousands of domains; use maxResults as a cost cap and maxConcurrency to control speed.
Can I run SimilarWeb Scraper on a schedule to track traffic over time?
Yes. Save your domains as a task, open Schedules, pick the cadence, and turn on monitorMode so each run returns only the sites whose rank or visits changed.
Does SimilarWeb Scraper return AI-assistant traffic?
Yes — it is a headline field. Every site with AI referral data carries aiShare (the GenAI share of visits), per-assistant columns (aiShareChatgpt, aiShareGemini, aiSharePerplexity, aiShareClaude, aiShareCopilot), the month-by-month history, and example AI-search prompts.
Can I get competitors and similar sites with SimilarWeb Scraper?
Yes. Turn on includeCompetitors and each site gets up to 20 ranked similar sites with category, estimated visits and a similarity score. It is charged only for sites that return competitors.
Can I integrate SimilarWeb Scraper with other apps?
Yes — Make, Zapier, n8n, Google Sheets and Slack via Apify integrations, or use webhooks to trigger an action when a run finishes.
Can I use SimilarWeb Scraper with the Apify API?
Yes. Start runs and fetch datasets with apify-client for Node.js or Python; the API tab has ready-to-paste code.
Can I use SimilarWeb Scraper through an MCP server?
Yes. Open the MCP tab, connect your MCP client, and ask for website traffic in plain language. Turn on compact for a smaller payload.
Do I need a SimilarWeb account, cookies or an API key?
No. SimilarWeb Scraper reads only SimilarWeb's publicly available data; you pass domains and nothing else.
Why did my SimilarWeb Scraper run return no results?
Either the inputs were not valid domains, or every site was removed by your filters, or the sites are too small for SimilarWeb to have data. Turn on includeUnavailable to see a row for each, and check the run log.
How accurate is the SimilarWeb Scraper traffic data?
It is SimilarWeb's own published estimate — the same figure their public page shows — so expect it to differ from a site owner's internal analytics. Sites with a connected GA integration are flagged with isDataFromGoogleAnalytics: true.
Your feedback
We keep improving SimilarWeb Scraper. Found a bug or missing a field? Open an issue on the Issues tab and we will take a look.


