
Website to Markdown: Sitemap Crawler for RAG + llms.txt
Pricing
from $0.20 / 1,000 pages
Website to Markdown: Sitemap Crawler for RAG + llms.txt
Website to Markdown crawler for RAG and LLMs: sitemap to Markdown, token chunks, llms.txt, incremental sync of only new or changed pages. No browser, no login. Export data, run via API, schedule and monitor runs, or integrate with other tools.
Pricing
from $0.20 / 1,000 pages
Rating
0.0
(0)
Developer

Mohamed Bahaa
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
13 days ago
Last modified
Categories
Security
Limited permissionsShare
What does Website to Markdown Crawler do?
Website to Markdown, website content crawler and sitemap to Markdown for RAG. Returns only new or changed pages on re-runs, lists removed URLs, and includes token chunks and llms.txt at no extra charge.
| What you can extract | Features & integrations |
|---|---|
| 📝 Clean Markdown: main content without nav, footers or banners | Sitemap discovery: robots.txt, sitemap indexes, .xml.gz |
| 🏷️ Title & description: plus front matter, optional | URL filters: include and exclude patterns, lastmod after |
| 🧭 Headings: the page outline | Incremental sync: only new or changed pages, plus removed URLs |
| 🔢 Word & token counts: size every page before you embed it | LLM-ready output: Markdown and chunks for RAG |
| 🧩 RAG chunks: heading-aware chunks with token estimates | Scheduling: run it hourly, daily or weekly with Apify schedules |
| 🔄 Change status & diff: new, changed, unchanged, with the changed lines | Export anywhere: JSON, CSV, Excel, XML or HTML from the dataset |
| 🗺️ Sitemap URLs: with lastmod, or as a plain URL list | API & SDKs: Apify REST API plus JavaScript and Python clients |
| 📄 llms.txt files: llms.txt and llms-full.txt for the site | AI agents (MCP): call it from Claude or other agents via Apify's MCP server |
Try it free in 1 click: open this ready-made example and press Start. Apify's free plan includes $5 of usage every month, no credit card needed. The Input example below returned 11 records and costs about $0.002 at list price.
- Website to Markdown and sitemap to Markdown: give it a domain like
https://docs.example.comand it finds the sitemap on its own (robots.txtSitemap:lines,/sitemap.xml,/sitemap_index.xml,/sitemap-index.xml,/wp-sitemap.xml,/sitemap.xml.gz, nested indexes, plain-text sitemaps). - Website content crawler for RAG: strips navigation, footers, cookie banners and scripts and returns the main content as clean Markdown with title, description, headings, word count and token estimate.
- RAG chunking: heading-aware token chunks (or character chunks) with overlap, stored inside each page record.
- llms.txt generator: writes
llms.txtandllms-full.txtfor the site to the key-value store. - Incremental sync / website change detection: on re-runs returns only new or changed pages, shows the changed lines (
changeDiff) and lists removed URLs. - Sitemap scraper / URL extractor:
sitemapOnlylists every URL withlastmod,changefreqandpriority, without fetching pages. - No sitemap? It crawls same-site links from the start URL instead (2 clicks deep by default).
- Filters: include/exclude URL patterns (glob like
**/docs/**or/regex/),lastmodafter a date or "30 days", newest first, section scoping (https://example.com/blogkeeps only/blogpages). - Any language: tested on Japanese and German sites; Chinese, Japanese and Korean text is counted per character for word counts.
- A lighter alternative to browser-based website crawlers for sites that publish a sitemap: plain HTTP at 256 MB, no browser, no proxy, no login, with incremental sync built in. It does not render JavaScript.
What makes it different
- Incremental sync that also tells you what was removed. With
incrementalon, unchanged pages are not fetched or charged, new and changed pages come back withchangeStatus, and aCHANGESrecord lists new, changed, unchanged and removed URLs, so you can delete stale vectors too. Test: once all 36 htmx.org posts were saved, the next run returned 0 pages (36 unchanged). - It shows what changed, not just that something changed. Each changed page carries
changeDiff: up to 10 removed and added lines of Markdown. In one look you can tell a real edit from a widget or a date that flips on every build, then strip that block and stop paying for it. The other Markdown/RAG crawlers we checked in the Apify Store (Oct 2026) flag a page as changed but don't show the lines. - RAG chunks and llms.txt in the same run, at no extra charge. Heading-aware chunks with token estimates sit inside each page record, and
llms.txt/llms-full.txtare written to the key-value store. - Flat $0.20 per 1,000 pages. Plain HTTP at 256 MB, no browser and no proxy costs on top.
What data does Website to Markdown Crawler extract?
🔗 url / canonicalUrl: page URL and its rel=canonical | 🏷️ title / description: page title and meta description | 📝 markdown: main content as Markdown (YAML front matter on by default) |
🧭 headings: the page outline (level + text) | 🔢 wordCount / charCount / tokenEstimate: page size | 🧩 chunks / chunkCount: RAG chunks with heading path and token estimate |
#️⃣ contentHash: SHA-256 of the Markdown | 🔄 changeStatus / changeDiff: new or changed, and the changed lines (incremental mode) | 📅 lastmod / httpLastModified: sitemap lastmod and the HTTP Last-Modified header |
🌐 language: page language | 🗺️ source / crawlDepth / sitemapUrl: found in a sitemap or by link crawl | 🔗 linksCount / internalLinks / externalLinks: link counts |
📄 frontMatter: title, url, canonical_url, lastmod, language, word_count, thin_content, scraped_at | ⚠️ type / thinContent: page, thin_page, url or error | 🕒 statusCode / scrapedAt: HTTP status and time of scrape |
How to use Website to Markdown Crawler in 5 steps
- Create a free Apify account.
- Open Website to Markdown Crawler.
- Add your input: one or more website or sitemap URLs, Max pages, and a chunk size if you want RAG chunks.
- Click Start.
- Download the results as JSON, CSV or Excel (or use the API), and grab
llms.txt/llms-full.txtfrom the key-value store.
Want a ready-made setup? Open the example Task Turn docs into Markdown chunks for a RAG chatbot or Detect new and changed pages on a website.
Input
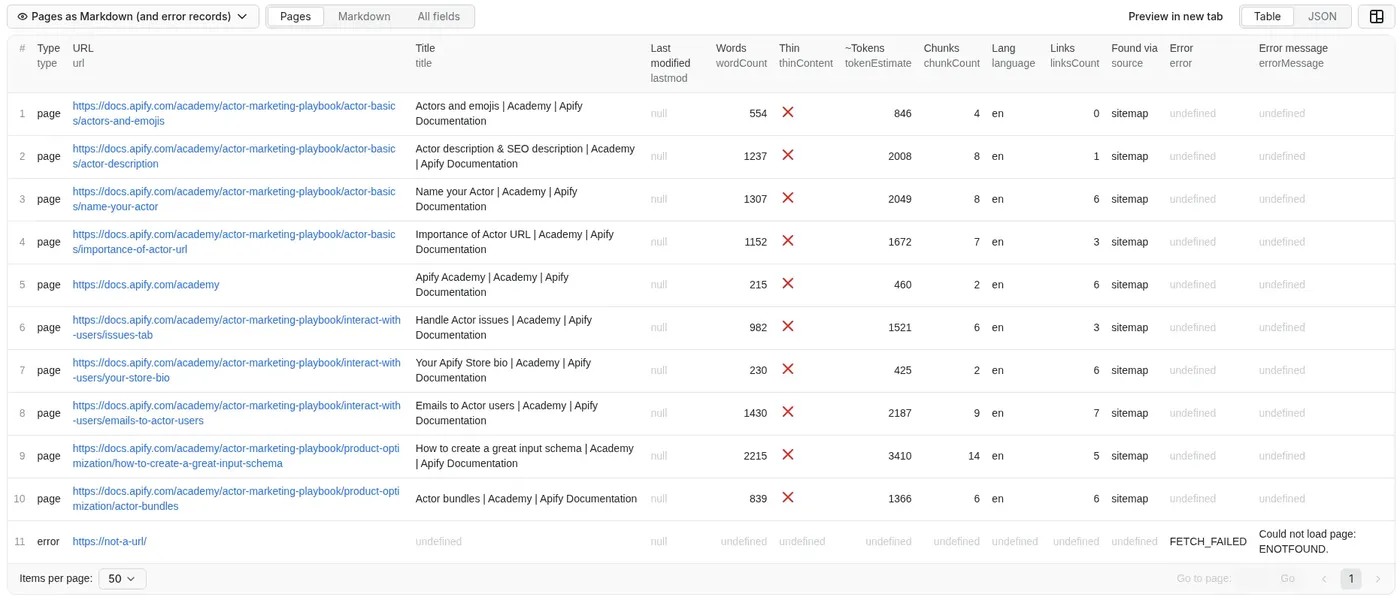
This exact input was run on the Apify cloud (256 MB, Oct 19 2026). The second entry is deliberately broken, to show what an error record looks like:
It returned 10 pages from the Apify Academy sitemap, each with chunks, plus one error record for not-a-url.
More tested inputs (paste into the Input tab in JSON view and click Start):
1. Turn a docs site into Markdown chunks for a RAG chatbot
2. Keep a vector store in sync: only new and changed pages
Run it on a schedule with the same input. The first run saves a baseline; later runs skip pages whose sitemap lastmod hasn't changed (not fetched, not charged), drop pages whose content hash is the same, and list removed URLs in the CHANGES record.
In our test the first run returned 36 pages (changeStatus: "new"); the second run returned 0 pages and reported 36 unchanged.
3. A site with no sitemap
The site has no sitemap, so the Actor crawls same-site links from the start URL (2 clicks deep by default). Each page says "source": "linkCrawl" and its crawlDepth. /index.html is skipped as a duplicate of /.
lastmodAfter keeps only sitemap URLs with a <lastmod> on or after the date, so sites whose sitemap has no <lastmod> return nothing with it set; use Incremental mode for those. Only want the URL list? Set "sitemapOnly": true.
Output
One record per page. A real record from the run above (Markdown, headings and chunk text shortened):
Sitemap-only records: { "type": "url", "url", "lastmod", "changefreq", "priority", "sitemapUrl", "site" }.
Key-value store: llms.txt, llms-full.txt, RUN_SUMMARY (sitemaps found, how each site was discovered, URL counts, duplicates skipped, errors, robots.txt skips) and, in incremental mode, CHANGES (shape shown with one edited and one removed post):
You can download the dataset as JSON, CSV, Excel, XML or HTML.
Front matter and thin-page flags
Each page's markdown starts with a YAML front matter block (turn off with Add YAML front matter):
Use lastmod to re-pull only changed pages and canonical_url to skip duplicate paths. Pages with less main content than Thin page threshold (default 50 words) come back as type: "thin_page" with thinContent: true and are left out of llms.txt, so they don't end up in your embeddings as noise. Turn off Save thin pages to skip them entirely, and you won't be charged for them.
Incremental mode, link crawl and duplicates
- Incremental mode (
incremental: true): the Actor remembers each page's sitemaplastmodand content hash in the named key-value storesitemap-to-markdown-state(one record per set of start URLs; set Incremental state name to keep separate histories). On the next run, pages with the samelastmodare skipped without being fetched, and fetched pages with the same hash are left out of the dataset (turn on Also output unchanged pages to keep them). You're charged only for pages in the dataset. TheCHANGESrecord in the run's key-value store listsnew,changed,unchangedandremovedURLs, so you can upsert and delete vectors. Removed pages are detected when the whole sitemap was read (set Max pages to 0 or above the site's size, and leave Changed after empty). In this mode Max pages counts pages that need fetching, so unchanged pages don't use it up, andllms.txtcovers only the pages returned in that run. ForchangeDiff, the last Markdown of each page is kept as a small gzipped record in the same store (one per page, capped at 300,000 characters, deleted when the page is removed from the sitemap), so the main state stays small even for sites with thousands of URLs. - Link crawl (
linkCrawl):fallback(default) crawls same-site links from the start URL when there is no sitemap, or the sitemap has nothing under your start URL;alwaysadds linked pages to the sitemap's pages;neverturns it off. Depth is set by Max link-crawl depth (default 2). Links stay on the same site and under the start path, and follow your include/exclude patterns and robots.txt. Changed after only filters sitemap URLs, since crawled pages have nolastmod. - Duplicates (
skipDuplicates, on by default): a page whose Markdown is identical to one already saved in the run, or that shares a canonical URL with a saved page and has near-identical length, is skipped and not charged. - Blocked sites: a 401/403/429 or a Cloudflare challenge comes back as a
BLOCKEDerror record. This Actor uses plain HTTP without proxies or a browser, so it can't get past bot walls.
Tuning incremental sync (stop false "changed" pages)
Some sites put things inside the main content that change on pages nobody edited: a "popular this week" box, related posts under a custom class, a "last updated" date, a view counter. Each one changes contentHash, so the page comes back as changed and is charged again. To find and remove them:
- Run the same input twice with Incremental mode on (and a fixed Incremental state name).
- In the second run, open the pages marked
changedand readchangeDiff. Ifremovedandaddedhold only a date, a widget heading or a list of other posts, that's noise. - Find that block's CSS selector in the page (browser dev tools) and add it to Remove selectors (
removeSelectors). Or set Content selector to the element that holds only the article. - Re-run. The first run with the new selector re-saves the affected pages once (their
changeDiffshows onlyremovedlines, the block you stripped). From then on they come backunchangedunless the real content changes.
Real example from our test (htmx.org essays, Oct 19 2026; to simulate a page whose in-content date changed, we edited the stored copy of one essay): the run marked it changed with
The date sits in a <time> tag inside <main>, so we added "removeSelectors": ["main > time"]. The next run returned the page once with "removed": ["May 29, 2020"], "added": [], and the run after that fetched it again and returned 0 pages (56 unchanged). Cloud runs: xBC9W6TwQIm2zpThH, 0o7nv9siorXvobMgs, GTXjvSCHIJlsZPib5.
Note: pages whose sitemap <lastmod> didn't change are skipped without being fetched, so this noise only shows up on sites whose sitemap has no <lastmod> or bumps it on every deploy.
How can I use the data?
- RAG pipelines and vector databases: feed docs, help centers, blogs and knowledge bases into Pinecone, Weaviate, Qdrant, pgvector, Chroma or LlamaIndex/LangChain loaders.
- Keep a vector store in sync: upsert pages by
url, re-embed onlychangedpages, and delete theremovedURLs from theCHANGESrecord. - AI agents and MCP clients: give an agent a website's full content as Markdown in one call.
- Custom GPTs, Claude Projects and NotebookLM: download
llms-full.txtand upload one file. - llms.txt generation: publish an
llms.txtindex for your own site. - Content audits and SEO: list every URL in a sitemap with
lastmod(sitemap-only mode), word counts, headings and thin pages. - Competitor and docs monitoring: schedule it with Incremental mode and read
changeDiffto see what changed on a site.
Holiday sales: watch competitor product pages (Black Friday, Cyber Monday)
This isn't a dedicated price tracker, but it can watch a store's product pages between runs. On a server-rendered store, prices land in the page Markdown: a test run on a Shopify store's /products section (Oct 20 2026) returned lines like $14.99 and $19.99 for each product.
Schedule it daily (or every few hours) through Black Friday (Nov 27 2026) and Cyber Monday. The first run saves a baseline; later runs return only new or changed product pages, and changeDiff shows the removed and added lines, so a price change appears as the old and new price line. New products and removed products show up in the CHANGES record. Send the results to Google Sheets, Slack or email with Apify integrations.
Limits: pages whose sitemap lastmod didn't change are skipped without being fetched, so a store that doesn't update lastmod when a price changes won't be re-checked. Prices loaded by JavaScript don't appear (no browser). It reads text, not structured price fields, so you match the price lines yourself.
How it compares
Generic website crawlers follow links and can render JavaScript, which is slower and often pricier; Website Content Crawler, for example, is billed by compute and lists about $0.20 per 1,000 pages with raw HTTP and $0.50–$5 with a browser. This Actor reads the sitemap the site already publishes, so it gets exactly the pages the owner wants indexed, at a flat $0.20 per 1,000 pages, and adds what a RAG sync needs out of the box: per-page changeStatus with a line diff of what changed (changeDiff) and a removed-URL list between runs, contentHash, token chunks, YAML front matter and llms.txt. If you need JavaScript rendering, proxies, logins or file downloads (PDF, DOCX), use a browser-based crawler instead.
Tips
- Docs sites (Docusaurus, MkDocs, GitBook, ReadTheDocs, Mintlify, Nextra): pass the docs root, e.g.
https://docs.example.com. - WordPress:
/wp-sitemap.xmland Yoast/RankMath indexes are found automatically; exclude**/tag/**and**/author/**. - Weekly refresh: schedule the Actor with Incremental mode on, upsert pages by
url, and delete theremovedURLs from theCHANGESrecord. - Messy pages: set Main content CSS selector (e.g.
article) or add Extra CSS selectors to remove. - JavaScript-only sites (content rendered client-side with no server HTML) return little text; this Actor does not run a browser. Those pages come back as
thin_page, so you can spot them (tested on excalidraw.com and app.diagrams.net).
More Actors from the same developer
| Actor | What it does |
|---|---|
| Telegram Channel Scraper | Public Telegram channel posts with a keyword monitor and only-new mode |
| Substack Scraper | Substack newsletters to clean Markdown, plus podcast transcripts |
| Greenhouse & Workday Jobs Scraper | Jobs from 8 career-site platforms with visa sponsorship and clearance flags |
| App Store & Google Play Reviews Scraper | Reviews from both stores in one run, only new reviews on schedules |
| Government Bids & RFP Scraper | Open bids and RFPs from 500+ US city and county portals on OpenGov |
| State Bids Scraper | Open bids from COMMBUYS, BidBuy, NJSTART, OregonBuys and NevadaEPro |
| PERM Green Card Sponsors | Companies that sponsor green cards, from official DOL PERM data |
Error items
When something fails, the Actor pushes an error record to the dataset (on by default, Save error records / saveErrorRecords). Every error record has type: "error", url, error (the code), errorMessage and scrapedAt; page-level errors add statusCode, and some add lastmod or contentType. Real record from the run above (timestamp shortened):
error | When |
|---|---|
INVALID_URL | A start URL can't be parsed as a URL (inputs without https:// get it added first) |
NO_SITEMAP_FOUND | No sitemap found at robots.txt or the common locations; the message lists what was checked |
BLOCKED | The site answered 401/403/429 or a bot challenge (e.g. Cloudflare), for the sitemap or a page |
FETCH_FAILED | The page couldn't be loaded (HTTP error, timeout, DNS), was too large, or an unexpected error occurred |
NOT_HTML | The URL isn't an HTML page; contentType says what it was |
EXTRACTION_FAILED | The HTML couldn't be parsed |
Error records count as dataset items and are charged like pages. Turn off Save error records and errors are only written to the log and counted in RUN_SUMMARY (errors, blocked). These are skipped without a dataset record by design: pages disallowed by robots.txt (counted as robotsBlocked in RUN_SUMMARY), duplicates, unchanged pages in incremental mode (unless Also output unchanged pages), and thin pages when Save thin pages is off. When your run's max charge is reached, the Actor stops cleanly and sets stoppedBySpendingLimit: true in RUN_SUMMARY.
FAQ
How much does it cost?
Pay per event, no subscription. See the Pricing tab.
| Event | Price |
|---|---|
| Actor start | $0.00005 |
| Each dataset record (page, URL in sitemap-only mode, or error record) | $0.0002 |
1,000 pages of Markdown = $0.20. Chunks are stored inside the page record, so chunking costs nothing extra, and the llms.txt files are free. Platform usage is included. In incremental mode, unchanged pages aren't in the dataset, so a re-run of a site where nothing changed costs only the start fee. Skipped duplicates aren't charged either.
Can I connect it to Make, Zapier, Google Sheets or Slack?
Yes. Use Apify's integrations for Make, Zapier, n8n, Google Sheets and Slack, or a webhook that fires when a run finishes. Schedule it in Apify to run hourly, daily or weekly.
How do I run it from the API?
Use the Apify REST API or the official clients. Node.js (apify-client):
Python (apify-client):
Can I use it with AI agents (MCP)?
Run it from the Apify API, the Apify MCP server, LangChain's ApifyWrapper, LlamaIndex, Make, Zapier or n8n. Read results from the default dataset (markdown and chunks fields) or fetch llms-full.txt from the key-value store. With the Apify MCP server, Claude and other MCP clients can call chimey_forearm/sitemap-to-markdown as a tool.
Is it legal to scrape websites to Markdown?
The Actor only fetches publicly available pages listed in a site's sitemap or linked from its pages, and respects robots.txt Disallow and Crawl-delay by default (Respect robots.txt). Pages behind logins or paywalls are not accessed. Pages can contain personal data, which is protected by GDPR in the EU and similar laws elsewhere; only collect it with a legitimate reason, and make sure your use of the content complies with the website's terms and copyright law. If unsure, ask a lawyer.
Found a bug or need a feature?
Open an issue in the Issues tab with the URL and what you expected. I usually reply within a day.
If it saved you time, a quick review on the Store helps a solo developer keep improving it. Bugs or ideas? Open an Issue.


