

Broken Link Checker: 404s, redirects and bad URLs
Pricing
$0.80 / 1,000 checked links
Broken Link Checker: 404s, redirects and bad URLs
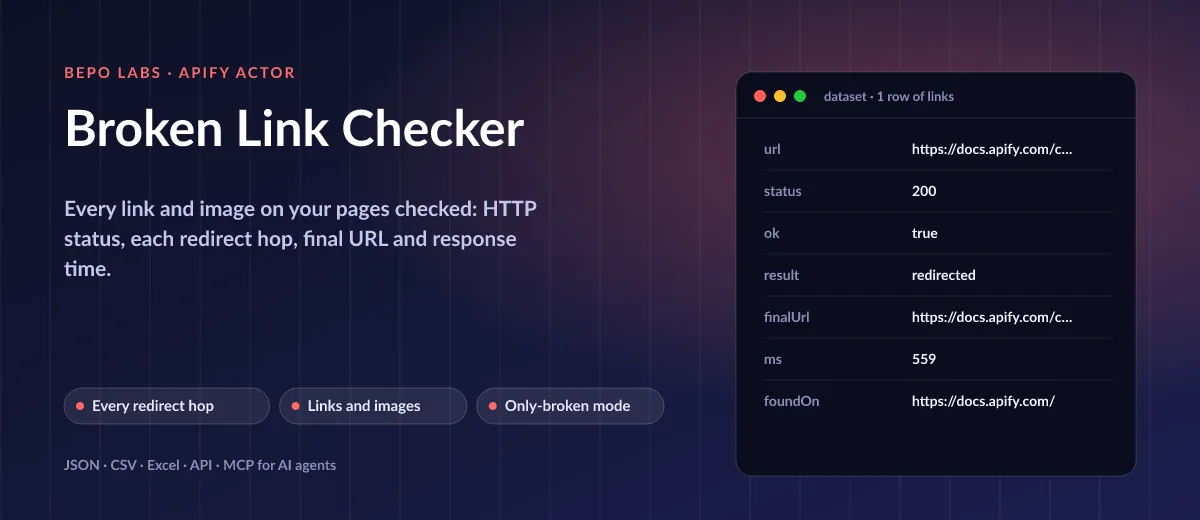
Give it your key sites or a list of addresses. Each hyperlink and image gets one row: answer code, every hop of its redirects trail, final destination, response time and where it was found.
Pricing
$0.80 / 1,000 checked links
Rating
0.0
(0)
Developer

BEPO Labs
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Security
Limited permissionsShare
🔗 What is Broken Link Checker?
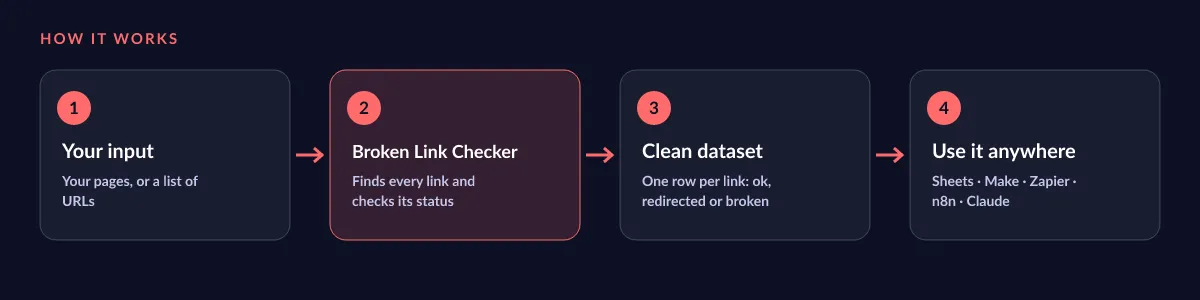
Spot every broken link, 404 and chain of redirects before customers do. Point it at the documents you care about, or drop in a plain spreadsheet column, and each target is requested once, then labelled ok, redirected or broken. Switch on onlyBroken to keep and pay for failures only.
- SEO audits: find 404s and redirect chains that waste crawl budget and link equity
- Website QA before a launch: check every link on your key pages after a redesign or a migration
- Redirect mapping: verify that old addresses land on the right new destination, one jump at a time
- Content maintenance: schedule a weekly run over blog posts and docs and fix what broke
- Outbound link monitoring: make sure partner, affiliate and reference links still work
✨ Why use this Actor?
- ✅ Every redirect hop: each 301, 302, 307 or 308 is listed with its URL and status, up to
maxRedirectshops (default 10) - ✅ Links and images: anchors and
<img src>pictures are both covered, with the visible text and the page they were found on - ✅ Pages or plain URL lists: read documents and test what they point to, or give up to 500 addresses directly
- ✅ Failures on request: with
onlyBroken, only dead targets are stored and charged - ✅ Light on servers: a HEAD request first (GET when a server refuses it), eight at a time, retries with backoff on network errors, 429 and 5xx
- ✅ Polite: robots.txt is honoured for every host; disallowed targets are marked as skipped, not hammered
📦 What data can you get with Broken Link Checker?
| 🔗 Checked URL | ✅ Result: ok, redirected, broken | 🔢 HTTP status code |
| ↪️ Redirect chain, hop by hop | 🎯 Final URL | ⏱️ Response time (ms) |
| 📄 Page the link was found on | 📝 Link text | 🖼️ Tag: link or image |
| 🏠 Internal-only filter | 🤖 robots.txt skips marked | 📊 Run summary: broken and redirected counts |
🚀 How to use Broken Link Checker
Broken Link Checker works in a few clicks, no coding needed:
- Create a free Apify account (the free plan includes 5 USD of monthly credit).
- Open Broken Link Checker and click Try for free.
- Paste your documents (or plain addresses with "Check links on the pages" off) and choose whether to keep only failures.
- Click Start and wait for the run to finish (most runs take seconds).
- Download your data as JSON, CSV, Excel, XML or HTML, or send it straight to Google Sheets, Make, Zapier or your AI agent.
⬇️ Input
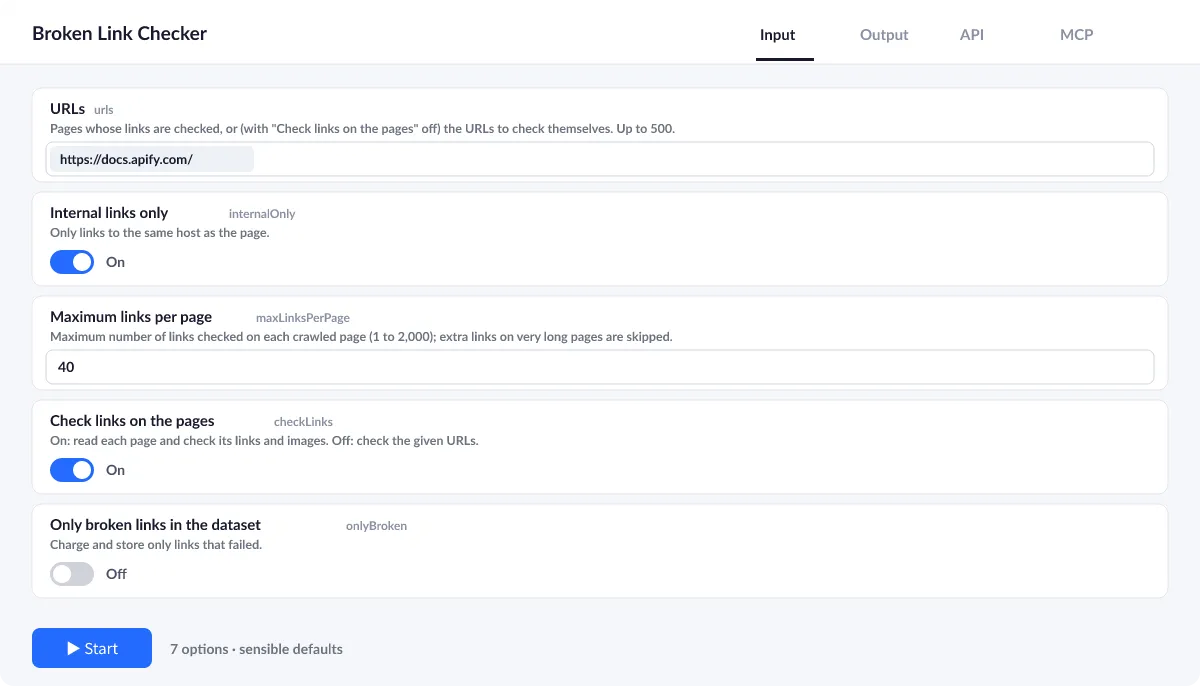
Add the pages to check, up to 500 per run. Everything else has sensible defaults.
Check the links on pages, or the URLs themselves
With checkLinks on (default), each entry is opened and everything it points to gets a verdict. With checkLinks off, the entries themselves are examined, which suits sitemaps, redirect maps and spreadsheet columns.
Internal links only
Switch on internalOnly to follow only targets on the same host, for example to audit your own navigation and skip outbound ones.
Limits
maxLinksPerPage caps how many each document may yield (default 200, up to 2,000). The Actor handles what you give; it does not crawl the whole site, so add every one you want covered.
| Field | Type | What it does | Default |
|---|---|---|---|
URLs (urls) | array | Pages whose links are checked, or (with "Check links on the pages" off) the URLs to check themselves. | ["https://www.iana.org/help/example-doma |
Check links on the pages (checkLinks) | boolean | On: read each page and check its links and images. | true |
Internal links only (internalOnly) | boolean | Only links to the same host as the page. | false |
Only broken links in the dataset (onlyBroken) | boolean | Charge and store only links that failed. | false |
Maximum links per page (maxLinksPerPage) | integer | Maximum number of links checked on each crawled page (1 to 2,000); extra links on very long pages are skipped. | 200 |
Maximum redirects (maxRedirects) | integer | Hops followed before a link counts as broken. | 10 |
Maximum retries (maxRetries) | integer | Retries per request with exponential backoff on network errors, 429 and 5xx. | 2 |
Input example
⬆️ Output
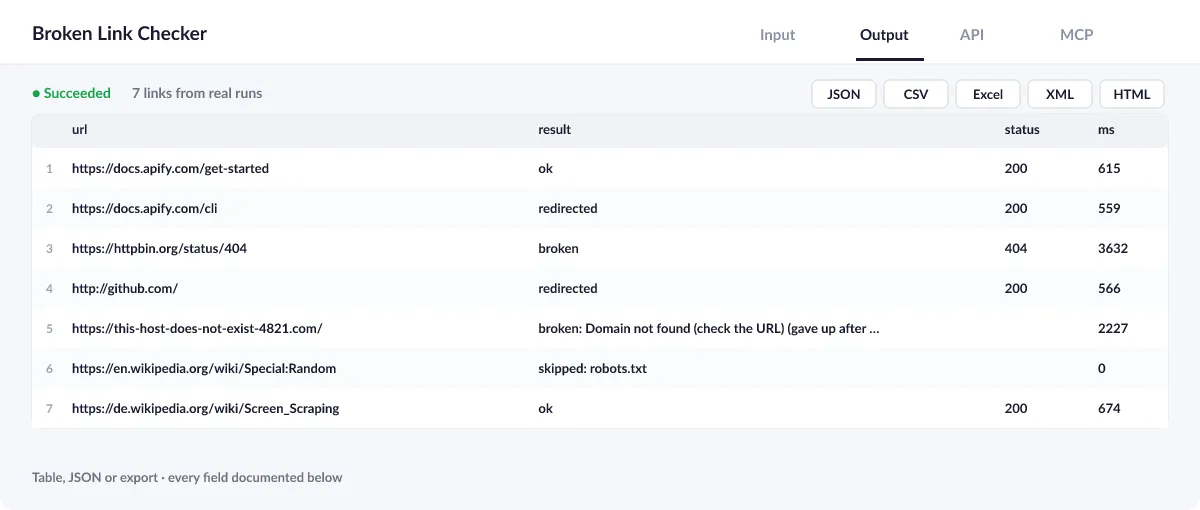
Each target becomes one row with its result: ok, redirected (it works, but through one or more redirects), broken (status 400 or higher, too many redirects, or no answer at all) or skipped: robots.txt. The run summary in the key-value store (OUTPUT) counts broken and redirected rows and lists every document with the number found or the reason it could not be read.
Output example
One row of the dataset (a redirected link on docs.apify.com, from a real run):
A broken link
From the same kind of run, with checkLinks off:
⚠️ Result values
result | Meaning |
|---|---|
ok | Answered with a status below 400, no redirect |
redirected | Works, but only after one or more redirects (see redirects) |
broken | Answered with a status from 400 to 499, for example 404 or 410 |
broken: too many redirects | More than maxRedirects hops |
broken: <reason> | No answer after the retries: unknown domain, timeout, refused connection, rate limit (429) or server error (5xx); the reason is in the text |
skipped: robots.txt | The host's robots.txt disallows the URL; not requested |
A page you list that cannot be read (for example HTTP 404 or blocked by robots.txt) is not charged and does not stop the run: it appears in the run summary with the reason.
View the results as a table or JSON in the Output tab and download them as JSON, CSV, Excel, XML, HTML or RSS, all fields or only those you pick.
💰 How much does Broken Link Checker cost?
Broken Link Checker is priced per event: 0.8 USD per 1,000 links (0.0008 USD per link), with no monthly rental. With onlyBroken on, you pay for failures only. Unreadable inputs cost nothing.
| You get | You pay |
|---|---|
| 100 links | 0.08 USD |
| 1,000 links | 0.8 USD |
| 10,000 links | 8 USD |
| 100,000 links | 80 USD |
💡 Apify's free plan gives you 5 USD of credit every month, enough for about 6,250 links at no cost. Set a spending limit per run and the Actor stops there.
⚖️ Broken Link Checker vs. the alternatives
| Broken Link Checker | Free online link checkers | SEO suite subscriptions | |
|---|---|---|---|
| Every redirect hop with its status | ✅ | often final status only | ✅ |
| Plain URL lists (sitemaps, redirect maps) | ✅ up to 500 per run | ❌ one site at a time | ✅ |
| JSON, CSV, Excel and API | ✅ | ❌ | ✅ on paid plans |
| Pay per link, no monthly plan | ✅ 0.8 USD per 1,000 | free with limits | monthly plan |
| Schedules, webhooks and MCP for AI agents | ✅ | ❌ | varies |
🔌 Integrations, API and MCP
Connect Broken Link Checker to your AI agent (MCP)
Give Claude, ChatGPT, Cursor or any MCP client direct access to Broken Link Checker through the Apify MCP server. Add this URL to its settings:
For Claude Desktop, add it under mcpServers in claude_desktop_config.json:
Then ask: "Check every link on https://example.com/pricing and tell me which ones are broken or redirect."
Run it from your code
Python (pip install apify-client):
JavaScript (npm install apify-client):
No-code integrations
Send results to Google Sheets, Slack, Airtable, HubSpot, Make, Zapier, n8n and more from the Integrations tab, start runs on a schedule, or trigger your own endpoint with a webhook when a run finishes. The Apify API gives you full control over runs and datasets.
❓ FAQ
Does it crawl my whole website?
No. It examines what your listed entries point to (up to 500, with up to 2,000 targets each). To cover a whole site, pass the addresses from its sitemap, or give that file itself with checkLinks off.
What counts as a broken link?
A status of 400 or higher, more redirects than maxRedirects, or no answer at all (unknown domain, timeout, connection refused). Redirects that end in a working page are marked redirected, not broken.
Why are some links marked skipped?
Their host's robots.txt disallows them, so the Actor does not request them. These rows are still in the dataset so you can see what was not checked.
Are images checked too?
Yes. <img src> addresses are examined like anchors and marked with tag: img. Targets using mailto:, tel:, javascript: and in-document jumps are left out.
How do I get only the broken links?
Switch on onlyBroken. Only failed links are stored and charged; the run summary still counts everything.
Is it legal to use Broken Link Checker?
Yes. Asking whether an address works means one request each, the same as a visitor clicking it, and the Actor honours robots.txt for every host with an honest user agent (BEPOLabsLinkChecker). It does not log in or collect personal data. Use it on sites you own or have a legitimate reason to examine, and keep runs on third-party hosts reasonable.
What if something is missing or does not work?
Open an issue on the Issues tab; we read each one and reply. Feature requests are welcome too.
💬 Your feedback
Tell us what Broken Link Checker should add on the Issues tab or leave a review; your notes decide what we work on next.
🔗 Related Actors
| Actor | What it does |
|---|---|
| 🩺 SEO Audit | Any page to a 0 to 100 SEO score and grade, with the fixes that matter most first: on-page, links and Core Web Vitals. |
| 🗺️ Sitemap URL Extractor | Every URL of a website from its sitemaps, in one deduplicated list with lastmod, changefreq and priority. |
| ⚡ Bulk PageSpeed Insights | Lighthouse scores, lab metrics and real-user Core Web Vitals for any list of URLs, on mobile, desktop or both. |
| 📸 Website Screenshot | Full-page PNG, JPEG or PDF of any URL, on desktop, tablet and phone, with cookie banners closed. |
| 📝 Website to Markdown | Any web page or docs site to clean Markdown for LLMs, RAG and AI agents, with headings, links and ready-made chunks. |
| 🌐 Domain RDAP and DNS | Domains to registrar, creation and expiry dates, age, status, nameservers, DNSSEC and DNS records from official RDAP, in bulk. |
| 📈 Google Trends Scraper | Interest over time for up to five keywords on one 0 to 100 scale, any country or worldwide, plus top and rising related queries. |
| 🧩 Tech Stack Detector | Any list of domains to the technologies behind each site: CMS, shop, framework, analytics, CDN and hosting. |


