
DOI Metadata & Bibliography Enrichment
Pricing
from $1.50 / 1,000 doi metadata records
DOI Metadata & Bibliography Enrichment
Turn a list of DOIs into clean citation metadata from the official Crossref, DataCite and JaLC APIs: title, authors with ORCID, journal or book, exact dates, pages, ISSN/ISBN, license, citation counts, and an honest not-found status.
Pricing
from $1.50 / 1,000 doi metadata records
Rating
0.0
(0)
Developer
Cliqto Media
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
5 days ago
Last modified
Categories
Share
Paste a list of DOIs and get one clean citation record per DOI. This bulk DOI metadata lookup checks each DOI at doi.org, reads the metadata from the official Crossref, DataCite or JaLC API, and returns title, authors, journal or book, exact dates, volume, pages, ISSN/ISBN, license and citation counts.
Use it to fill a reference list, check a bibliography or enrich a spreadsheet of papers and datasets. The smallest run is one DOI, and three DOIs finish in about 2 seconds.
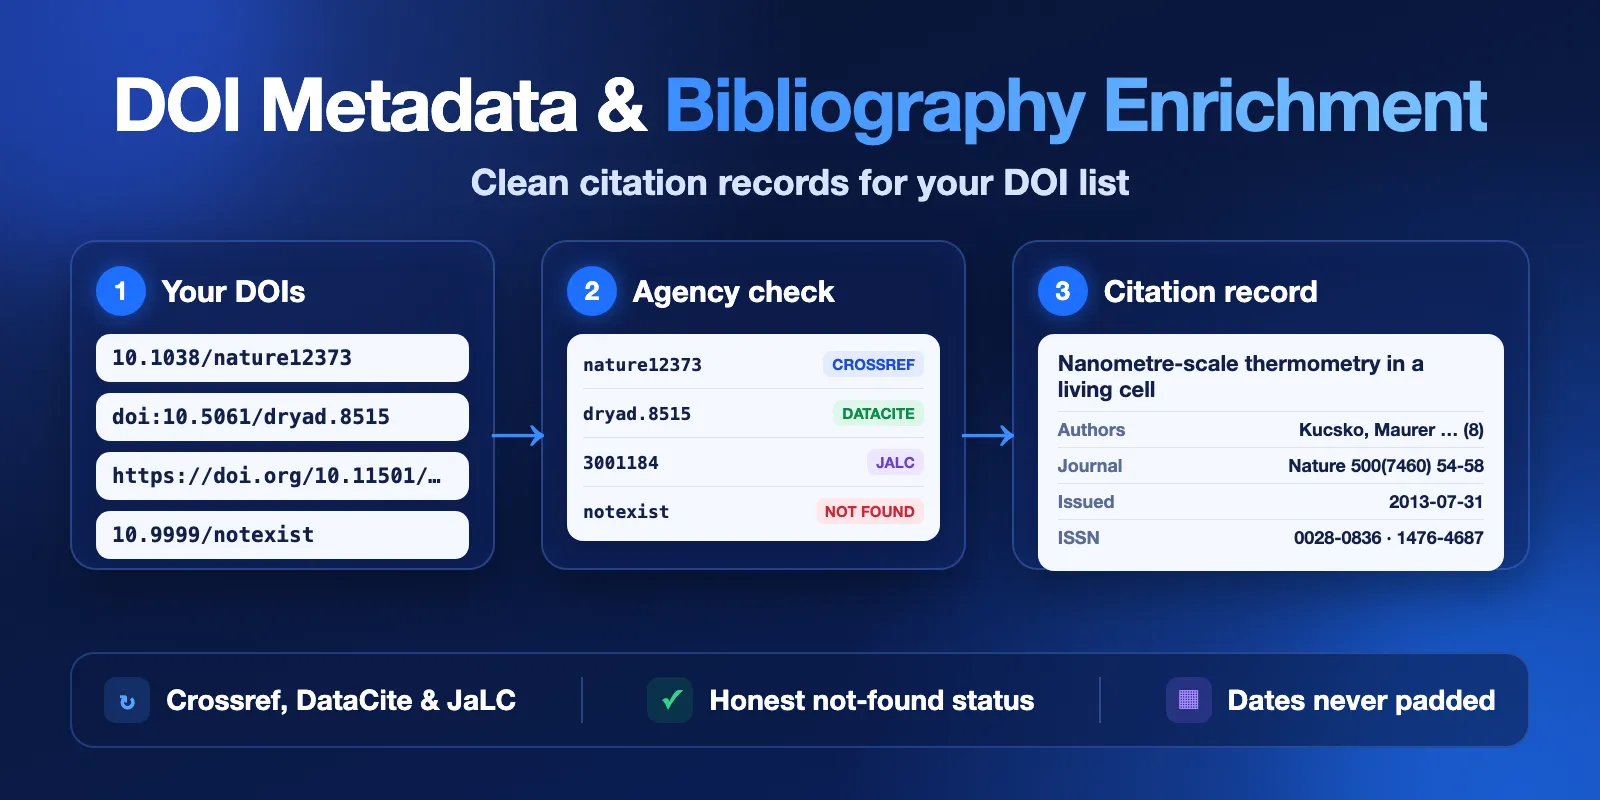
Table of contents
- What it does
- Quick start
- Use cases
- Input
- Output
- Pricing and limits
- API, export and integrations
- Troubleshooting
- FAQ
- Data sources and licence
- Support
What it does
A DOI (Digital Object Identifier) is a permanent ID for a paper, book chapter, dataset or other work, for example 10.1038/nature12373. Each DOI is registered with one registration agency. This Actor:
- Cleans your input. It accepts
10.…,doi:10.…,https://doi.org/10.…anddx.doi.orglinks, in any letter case. - Asks doi.org which agency registered each DOI.
- Reads the record from that agency: Crossref (most journals and books), DataCite (datasets, software, repositories) or JaLC (Japan).
- Writes one Dataset row for each input value, in your input order, with a clear
status.
Good fit
- Turn a list of DOIs into a table of titles, authors, journals, years and pages.
- Check a reference list: find DOIs that are not registered or have a typo.
- Add ISSN, ISBN, publisher, license and citation counts to a list of papers.
- Mix journal articles and research datasets in one run (Crossref and DataCite).
Not a fit / limits
- No search by title or author. You need the DOI.
- No PDFs, full text or abstracts. The Actor reads only bibliographic metadata.
- No Open Access links (for example from Unpaywall).
- DOIs from other agencies (for example mEDRA) are only identified. The row has
status: unsupported_agencyand the agency name, but no title or authors. - No BibTeX or RIS file. You get structured fields that you can export as JSON, CSV or Excel.
- Up to 500 DOIs per run.
Quick start
- Open the Input tab.
- Keep the three example DOIs in DOIs (
dois) or paste your own, one per line. - Leave Contact email empty, or add your own email for large runs.
- Click Start.
- Open the Output tab, view Citations. Check
statusandtitlein the first row.
Expected result: one row per DOI. With the example input you get three complete rows: a Nature article (Crossref), a Dryad dataset (DataCite) and a book chapter (Crossref).
Use cases
| Buyer job | Input path | Output entity | Key fields | Next integration |
|---|---|---|---|---|
| Build a reference table | dois | One citation record per DOI | title, authors, containerTitle, issuedDate, pages | Export CSV/Excel, or read the Dataset by API |
| Clean a bibliography | dois | Status per DOI | status, statusReason, errorCode, doi | Filter rows where status is not complete |
| Enrich a paper list | dois | Identifiers and counts | issn, isbn, publisher, licenses, citedByCount | Join on doi (always lower case) |
| Catalogue research data | dois | DataCite dataset record | resourceTypeGeneral, publisher, publicationYear, language | Export or API |
Input
Input fields
| Field | Plain name | Type | Required | Default / prefill | Allowed values | Effect | Example | Recommendation |
|---|---|---|---|---|---|---|---|---|
dois | DOIs | array of strings (one per line in the form) | yes | Prefill: 3 example DOIs. No runtime default. | 1–500 values, each up to 1,000 characters | Each value becomes one output row | 10.1038/nature12373 | Paste DOIs in any common form. Split lists longer than 500 into several runs. |
contactEmail | Contact email for Crossref and DataCite | string | no | empty | A plain email address, up to 254 characters | Sent only in the request User-Agent (mailto) to Crossref, DataCite and doi.org. Crossref uses it to put requests in its "polite" pool. | name@example.org | Add it for runs of hundreds of DOIs. It is never logged or saved in the output. |
How dois is read:
- Accepted forms:
10.1038/nature12373,doi:10.1038/nature12373,https://doi.org/10.1038/nature12373,http://dx.doi.org/…and percent-encoded links. Spaces around a value are removed. Empty lines are skipped. - Letter case does not matter: DOIs are case-insensitive, and the output
doiis always lower case. - A repeated DOI (also in another form or case) gets its own row with the same data, but it is charged only once.
- A value that is not a DOI gets a free row with
status: invalid. - An empty list or more than 500 values is rejected before the run starts.
Input examples
Mixed list of papers and data
Expected behavior: doi.org returns Crossref for the first and third DOI and DataCite for the second. One batch request goes to each API.
Expected output: three complete rows with title, authors, containerTitle, issuedDate and agency.
Limit or cost note: 3 found DOIs = 3 doi-metadata events plus the run start.
Reference list check with problems
Expected output: row 1 is complete; row 2 is not_found with errorCode: DOI_NOT_REGISTERED; row 3 is invalid (free); row 4 is a duplicate of row 1 (complete, free).
Output
Each input value gives exactly one row in the default Dataset, in input order. The Citations view shows the main columns; the Identifiers view shows IDs and links. A run summary is saved as RUN_SUMMARY in the default Key-value store.
Status values
status | Meaning | Charged as |
|---|---|---|
complete | The DOI is registered and the record has a title. | doi-metadata |
partial | The DOI is registered, but the record has no title (NO_TITLE, for example a journal issue or a figure) or the agency API has no record for it yet (RECORD_NOT_INDEXED). Read statusReason. | doi-metadata for NO_TITLE; doi-check for RECORD_NOT_INDEXED |
not_found | doi.org says the DOI is not registered (DOI_NOT_REGISTERED). | doi-check |
unsupported_agency | The DOI is registered with another agency. agency names it (UNSUPPORTED_AGENCY). | doi-check |
invalid | The value is not a DOI (INVALID_DOI). | free |
error | A source failed after retries, or the run reached its time limit. Existence is unknown; the row never says "not found" in this case. | free |
Output fields
| Field | Meaning | Type | Can be empty? | Example / enum | Source / notes |
|---|---|---|---|---|---|
input | Your input value exactly as given | string | no | https://doi.org/10.1038/NATURE12373 | Input |
doi | DOI in lower case | string | null for invalid | 10.1038/nature12373 | Cleaned input |
doiUrl | Resolvable link | string | null for invalid | https://doi.org/10.1038/nature12373 | Built from doi |
status | Result type | string | no | see Status values | Actor |
statusReason | Plain-English reason for any status other than complete | string | null for complete | doi.org reports that this DOI does not exist … | Actor |
agency | Registration agency | string | null for invalid, not_found, error | Crossref, DataCite, JaLC, mEDRA | doi.org |
type | Work type as the agency names it | string | yes | journal-article, book-chapter, dataset | Agency |
resourceTypeGeneral | DataCite general type | string | null outside DataCite | Dataset, Software, Text | DataCite |
title | Title, markup removed, entities decoded | string | null for partial and non-found rows | Nanometre-scale thermometry in a living cell | Agency |
subtitle | Subtitle | string | yes | Agency | |
authors | Authors in record order: given, family, name, orcid, affiliations | array | empty when the record has none | [{"given":"G.","family":"Kucsko",…}] | Agency. orcid only when the source lists it. affiliations is copied as the source has it and can include contact details. |
editors | Editors, same shape | array | often empty | Agency | |
containerTitle | Journal, book or proceedings that contains the work | string | yes | Nature, ggplot2 | Agency. For a book chapter: the book. |
containerTitles | All container titles as the agency lists them | array | yes | ["Use R!","ggplot2"] | Agency |
seriesTitle | Book series | string | yes | Use R! | Crossref |
publisher | Publisher | string | yes | Springer Science and Business Media LLC | Agency |
issuedDate | Publication date at the source precision | string | yes | 2013-07-31, 2013-08, 2016 | Agency. Never padded to a full date. |
publishedOnlineDate | Online date | string | yes | 2013-07-31 | Crossref |
publishedPrintDate | Print date | string | yes | 2013-08 | Crossref |
publicationYear | Year | integer | yes | 2013 | Agency |
volume | Volume | string | yes | 500 | Agency |
issue | Issue | string | yes | 7460 | Agency |
pages | Page range | string | yes | 54-58 | Agency |
articleNumber | Article number (journals without pages) | string | yes | e06495 | Crossref |
issn | ISSNs: value, type (print/electronic/null) | array | yes | [{"value":"0028-0836","type":"print"}] | Agency |
isbn | ISBNs, same shape | array | yes | [{"value":"9783319242750","type":null}] | Agency |
licenses | License statements: url, name, contentVersion, startDate | array | yes | [{"url":"http://www.springer.com/tdm",…}] | Crossref license / DataCite rightsList |
referencesCount | References deposited with the record | integer | yes | 30 | Crossref |
citedByCount | Citations known to the agency | integer | yes | 1845 | Crossref is-referenced-by-count / DataCite citationCount. Other indexes count differently. |
language | Language code | string | null for Crossref | en, ja | DataCite, JaLC |
landingUrl | Publisher landing page | string | yes | https://www.nature.com/articles/nature12373 | Agency |
sourceUpdatedAt | When the agency last indexed or updated the record | string | yes | 2026-10-11T02:44:13Z | Agency |
authorsCount | Number of authors | integer | no (0 when none) | 8 | Actor |
provider | API the row came from | string | yes | Crossref REST API | Actor |
sourceUrl | API request the metadata was read from | string | yes | https://api.crossref.org/works?filter=doi:… | Actor |
fetchedAt | When the row was made (ISO 8601) | string | no | 2026-10-11T09:31:37.688Z | Actor |
errorCode | Machine code | string | null for complete | INVALID_DOI, DOI_NOT_REGISTERED, UNSUPPORTED_AGENCY, RECORD_NOT_INDEXED, NO_TITLE, SOURCE_UNAVAILABLE, RATE_LIMITED, DEADLINE_REACHED | Actor |
null means the agency record does not have this value. The Actor never invents a value, for example a day or month that the source does not give.
Output entities and surfaces
| Situation | Where | Result shape | User action |
|---|---|---|---|
| Normal item | Dataset, view Citations | complete row with metadata | Export or use the fields |
| DOI not registered | Dataset | not_found row, metadata fields null | Check the DOI for a typo |
| Partial result | Dataset | partial row with statusReason | Read statusReason; try again later for RECORD_NOT_INDEXED |
| Technical failure | Dataset + RUN_SUMMARY | error row with SOURCE_UNAVAILABLE, RATE_LIMITED or DEADLINE_REACHED | Run these DOIs again later; error rows are free |
| Run overview | Key-value store RUN_SUMMARY | counts by status and agency, HTTP stats, warnings, sources | Check status and counts |
Output example
This example is trimmed: it shows one row from the first input example, with one of eight authors and some fields left out. Counts such as citedByCount change over time.
Field names compared with other DOI tools
If you move from another DOI tool, these names may help:
| Common name elsewhere | Field here |
|---|---|
journal | containerTitle |
publishedDate | issuedDate |
publishedYear | publicationYear |
page | pages |
citationCount | citedByCount |
url | doiUrl (DOI link) or landingUrl (publisher page) |
authors as one string | authors[].name |
Pricing and limits
Pricing unit
This Actor uses pay-per-event pricing. You pay for each DOI result and once for each run start. Platform usage is included.
| Event | When it is charged | Free plan | Bronze | Silver | Gold |
|---|---|---|---|---|---|
doi-metadata | A complete row, or a partial row with metadata (NO_TITLE) | $0.0018 | $0.0017 | $0.0016 | $0.0015 |
doi-check | A not_found, unsupported_agency or RECORD_NOT_INDEXED row | $0.0005 | $0.0005 | $0.0005 | $0.0005 |
| Actor start | Once per run (memory is 256 MB, so always one event) | $0.001 | $0.001 | $0.001 | $0.001 |
Free: invalid rows, error rows and repeated DOIs. A run where no value is a DOI fails with a clear message and charges only the start.
Cost examples (Free plan prices)
| Scenario | Input scope | Expected events | Base charge | Total |
|---|---|---|---|---|
| Example input | 3 DOIs, all found | 3 × doi-metadata | $0.001 start | $0.0064 |
| Small list | 100 DOIs, all found | 100 × doi-metadata | $0.001 start | $0.181 |
| Reference check | 100 DOIs: 90 found, 5 not registered, 5 invalid | 90 × doi-metadata, 5 × doi-check | $0.001 start | $0.1655 |
| Full run | 500 DOIs, all found | 500 × doi-metadata | $0.001 start | $0.901 |
Spending limit
If you set a maximum cost per run, the Actor stops before it goes over the limit. Rows already saved stay in the Dataset; DOIs after the limit get no row, and RUN_SUMMARY.status is CAPPED.
Limits
- Up to 500 DOIs per run. In tests, 500 DOIs finished in about 24 seconds and 100 DOIs in about 6 seconds.
- The Actor reads sources for up to 240 seconds. DOIs not processed in time get a free
errorrow withDEADLINE_REACHED. - It sends batch requests (up to 50 DOIs each) and retries temporary failures. It respects source rate limits.
API, export and integrations
- API: start the Actor with the Apify API and read the Dataset items. The
doifield is lower case, so you can join on it. - Export: download the Dataset as JSON, CSV, Excel, XML or RSS from the Output tab.
- Scheduling: you can run it on an Apify schedule, for example to refresh citation counts.
Use with AI agents (MCP)
AI agents can call this Actor through the Apify MCP server: add https://mcp.apify.com?tools=cliqtomedia/doi-bibliography-enrichment to your MCP client (Claude, Cursor, VS Code and others). The MCP server needs your Apify account (OAuth sign-in or an Apify API token); the DOI sources need no key. The agent builds the input from the input schema. The smallest useful input:
Key output fields for an agent: status (complete, not_found, …), title, authors, containerTitle, issuedDate, agency, errorCode. A call with 10 DOIs usually finishes in a few seconds and costs about $0.019. Up to 500 DOIs fit in one run. Treat error rows as "unknown", not as "does not exist".
Troubleshooting
| Symptom | Check | Action |
|---|---|---|
not_found for a DOI you trust | input, doi | Look for a typo or extra characters. doi.org itself says the DOI is not registered. |
invalid row | input, statusReason | After cleaning, the value is not in the form 10.<prefix>/<suffix>. Fix the value. |
partial with RECORD_NOT_INDEXED | statusReason | The DOI is registered, but the agency API does not have the record yet. Try again later. |
partial with NO_TITLE | type | Records such as journal issues or figures often have no title. This is source data. |
unsupported_agency | agency | The DOI belongs to another agency. This Actor does not read its metadata. |
error rows | errorCode, RUN_SUMMARY.warnings | A source was down or slow. Run only these DOIs again later; they were not charged. |
| Run rejected at start | Input | dois is empty or has more than 500 values. |
FAQ
Do I need an API key?
No. Crossref, DataCite, JaLC and doi.org are open. You only need your Apify account.
Why is a date only a year or a month?
The Actor keeps the precision of the source. If the record says 2016, you get 2016, not 2016-01-01.
Why is citedByCount different from Google Scholar?
It is the count known to the registration agency (Crossref or DataCite). Other indexes count different sources.
How fresh is the data?
Each run reads the sources live. Each row has fetchedAt (our read time) and sourceUpdatedAt (when the agency last updated the record).
Can I get abstracts or PDFs?
No. The Actor returns bibliographic metadata only.
Data sources and licence
- doi.org — registration agency of each DOI.
- Crossref REST API — bibliographic metadata. Abstracts are not exported.
- DataCite REST API — metadata under CC0.
- JaLC — Japanese records, read through doi.org content negotiation.
This Actor is independent and not endorsed by Crossref, DataCite, JaLC or the DOI Foundation.
Support
Use the Issues tab of this Actor. Add the run ID, the DOI and the status or errorCode you saw. Do not send API tokens or private data.


