
Teamtailor Job Watch
Pricing
from $18.00 / 1,000 company feed checkeds
Teamtailor Job Watch
Read public Teamtailor job feeds by company slug. Filter titles and locations, export job rows, and keep only IDs your monitor has not emitted before.
Pricing
from $18.00 / 1,000 company feed checkeds
Rating
0.0
(0)
Developer
Cliqto Media
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
8 days ago
Last modified
Categories
Share
Get public Teamtailor jobs from the company feeds you choose. Filter the rows and keep only job IDs that your monitor has not saved before.
Start with {"companies":["polestar"],"maxJobsPerCompany":10}. Open the Dataset for job rows and RUN_SUMMARY for empty, partial or failed results. Check the price shown before Start; no fixed selling rate is set by this guide.
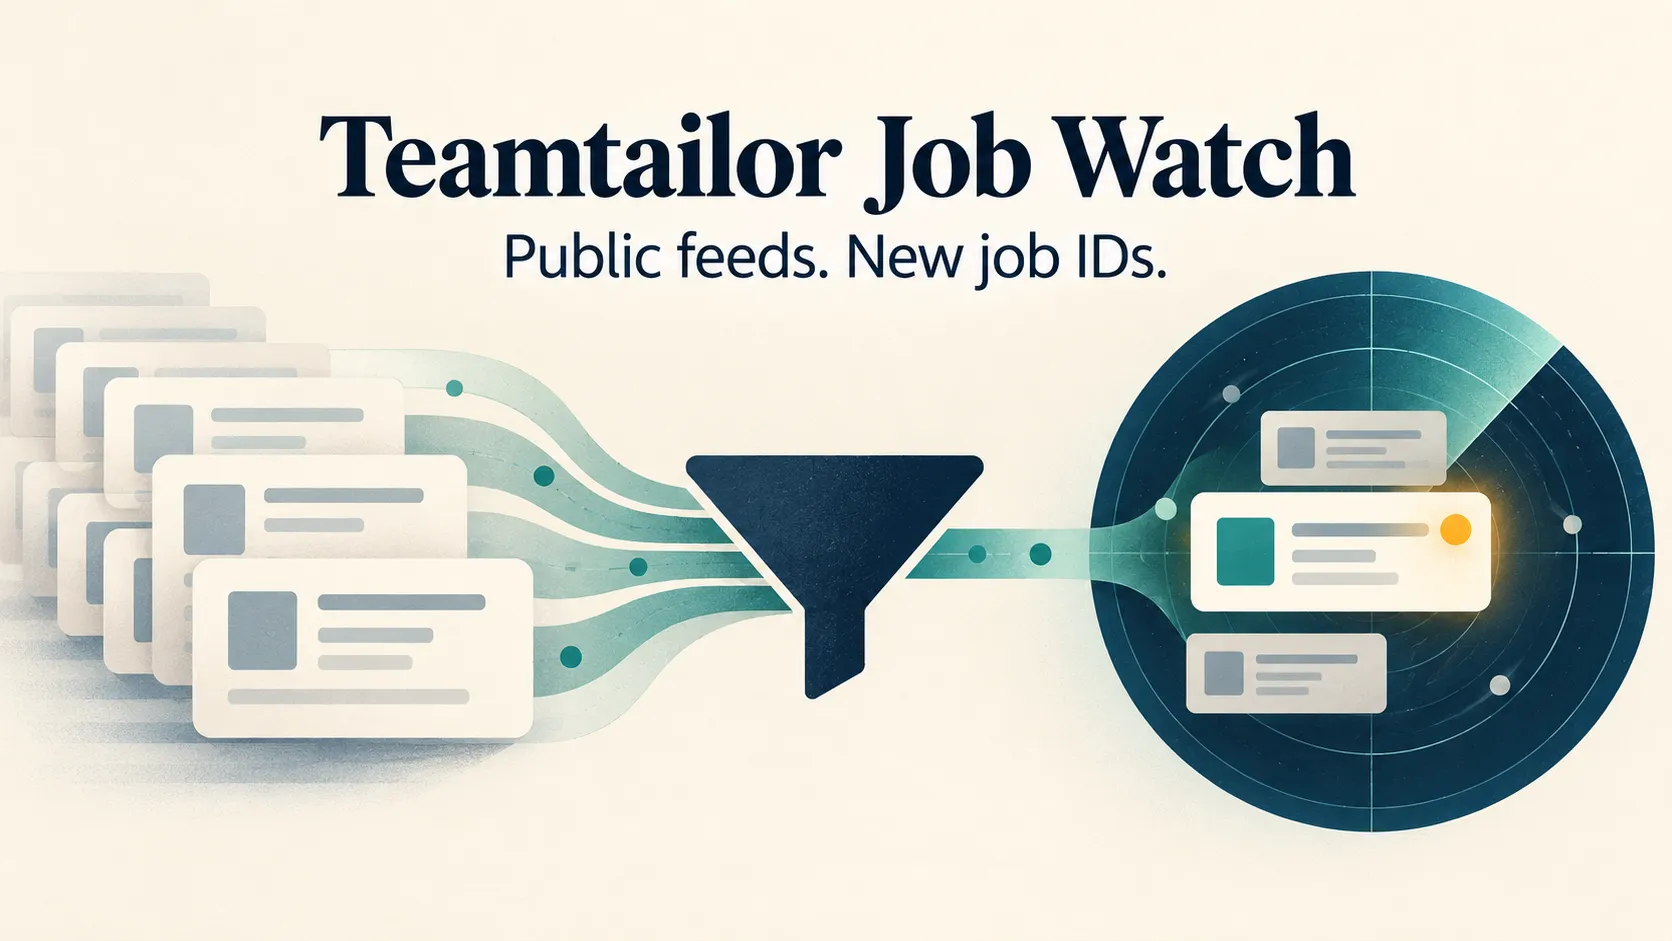
Table of contents
- What this Actor does
- What data you can get
- Quick start
- Input reference
- Input examples
- Output example
- Output field reference
- Pricing and cost examples
- Use cases
- Scheduling and monitoring
- API, MCP and integrations
- Limits and partial results
- Troubleshooting
- FAQ
- Related Actors
- Support
What this Actor does
Add one to five public Teamtailor company slugs. A slug is the name before .teamtailor.com, such as polestar. The Actor reads each company's /jobs.json and /jobs.rss. It joins JSON items to RSS items by feed ID and saves one row for each matching posting ID.
Use a snapshot to get matching jobs in feed order. Use a monitor to get the newest matching IDs that have not been saved in that monitor. The first monitor run also returns current matches. Caps and filters leave unreturned jobs eligible for a later run.
This is an independent tool. It is not affiliated with, endorsed by or sponsored by Teamtailor. It reads public employer job feeds. It does not use a Teamtailor account key, read candidate profiles or submit applications. Teamtailor describes the public fields in its RSS feed guide.
What data you can get
Each job row has 20 keys. You can get the job ID, title, public description text, addresses, publication time and job link. Department and remote status come from RSS. Missing optional values stay null.
location is the first JSON address, with city, region and country when present. allLocations contains the unique addresses. RSS location names are used if JSON has no usable address. Location filters can match either source. country comes from the first JSON address; it stays null when that address has no two-letter country code.
The Dataset holds jobs. The default Key-value store holds INPUT, OUTPUT and RUN_SUMMARY. Monitoring adds a separate named store with saved job IDs. An empty Dataset is not enough to tell you why there are no rows: read the summary.
Quick start
- Open this Actor's Input tab.
- Switch to JSON input and paste the input below. No company is supplied by default.
- Leave descriptions on. Set the output cap to 10 for your first check.
- Click Start. Your Apify account must have access to the Actor.
- Open the run's Dataset. Check
company,jobId,title,locationandurl. - Open the run's Key-value store and check
RUN_SUMMARY.outcome. Usecompanies[].errorCodesif the result is partial or empty.
This input returned ten real rows in the saved example below. Live feeds can change. A cap of 10 limits saved matches, not the number of source items fetched.
To download results, open the Dataset and select Export, then JSON, CSV or Excel (XLSX) and Download. Leave the field selector empty to include all keys, or select your fields explicitly. Keep hidden metadata fields when you need _type or _scrapedAt. The default table view shows only nine columns; it is not the full field contract.
JSON keeps arrays and null values. CSV and XLSX expand arrays into columns such as allLocations/0; null cells can look blank. The saved ten-row Dataset was checked in all three formats. Use JSON if you need exact JSON types. See Dataset export options.
Input reference
All inputs are in one JSON object. companies is required. Omitted optional fields use the defaults below. A fresh Input form offers polestar, a two-job cap and snapshot mode (onlyNewSinceLastRun=false). You can run this sample without editing it; live job counts can change. API calls still require companies; there is no hidden fallback. Null is not an accepted input value. Unknown keys are rejected.
| Key / form label | Type / required | Default / prefill | Allowed values | Effect and recommendation |
|---|---|---|---|---|
companies / Teamtailor company slugs | string[] / yes | None / ["polestar"] | 1–5 unique slugs; 1–63 letters, digits or hyphens; start with a letter or digit | Add known public boards, such as ["polestar"]. Values are trimmed and lowercased. Duplicate normalized slugs are rejected. URLs, custom domains and regional hosts are not accepted. |
includeDescription / Include job descriptions | boolean / no | true / none | true, false | Use true for readable descriptions. False sets descriptionText to null; both feeds are still fetched. |
maxJobsPerCompany / Job limit per company | integer / no | 55 / 2 | 1–55 | Limit matching output for each company. Start with 10. A snapshot takes feed order; a monitor takes newest unseen matches. A low cap does not make the feed request smaller. |
titleKeywords / Words in job titles | string[] / no | [] / none | At most 20 values; each trimmed value 1–100 characters | Match any word or phrase as a case-insensitive title substring, such as ["engineer","intern"]. Empty means all titles. |
locations / Locations to match | string[] / no | [] / none | At most 20 values; each trimmed value 1–100 characters | Match any value in JSON addresses or RSS names. Try ["Sweden"] or ["Göteborg"]. Empty means all locations. |
remoteOnly / Only explicit remote jobs | boolean / no | false / none | true, false | True accepts only explicit RSS fully, remote, fully_remote, remote_first or remote_work. Hybrid, none and missing status do not match. Text mentioning remote work is not enough. |
postedAfter / Earliest publication date | string / no | Omitted / none | YYYY-MM-DD, or ISO date-time with seconds and Z or an explicit UTC offset; optional 1–3 fractional digits | Inclusive publication-date filter. Example 2026-01-01 or 2026-01-01T00:00:00Z. A date-only value uses UTC. Omit it for all dates. Invalid dates and local times without a zone are rejected. |
onlyNewSinceLastRun / Only IDs not saved before | boolean / no | false / false | true, false | False gives a snapshot. True emits and saves unseen matching IDs. First run emits current matches too. Use sequential runs, not overlapping runs. |
monitorNamespace / Separate monitor name | string / no | "default" / none | 1–64 letters, digits, underscores or hyphens; first character a letter or digit | Use a name such as my-sweden-watch. Keep it and the filters unchanged to continue a monitor. A new name starts a fresh baseline without deleting old state. |
How settings work together
| Settings | Effective behavior | What to do |
|---|---|---|
| Title values and location values | OR within each list; AND between the two lists | A job must match a title value and a location value when both lists are nonempty. |
| Filters and output cap | Filters run before the cap | Unmatched and unreturned IDs are not marked seen. |
| Monitor plus cap | Newest unseen matching jobs first | Repeat capped runs until the matching page is drained; later repeats can return zero. |
| Same monitor, new cap or description choice | The same saved-ID scope is used | Changing these does not reset the baseline. |
| New title/location/remote/date filters | A different state scope is used | Treat this as a separate baseline; filter order, case and repeated filter values are normalized for state identity. |
| Snapshot mode and namespace | No monitoring store is read or updated | Set onlyNewSinceLastRun true when you want persistent IDs. |
Empty title/location lists disable those filters. Empty strings in those lists are rejected. The Actor does not search for every Teamtailor company.
Input examples
Minimal snapshot
This uses the runtime cap of 55, descriptions on and no filters or monitoring. It returns available matching jobs from the first page. It is the smallest valid input, not a promise of 55 source jobs.
Small snapshot used for the output example
This gives job rows in feed order. Check jobId, title, location, descriptionText and url. A source snapshot used with this input returned ten rows.
Separate Sweden monitor
This is a valid setup example. It starts a separate monitor for Sweden matches posted on or after that date. The first run emits up to two matches; later runs emit up to two unseen matches. It is not a claim that this exact namespace has already been run. Adding titleKeywords:["engineer"] narrows results further. Turning remoteOnly on excludes hybrid jobs and can make the Dataset empty.
Output example
This is one real row from the ten-row snapshot. All 20 keys are shown. Only descriptionText is shortened to a direct excerpt for this page; the actual Dataset contains the full text. The collection time is a sample time, not a freshness guarantee.
The posting date can be much older than collection time. The Actor does not change publication dates to make jobs look new. A job is new to a monitor when its ID has not been emitted by that monitor, even if its posting date is old.
Output field reference
Job rows: all 20 Dataset fields
| Field | Type / empty behavior | Meaning and source / sample |
|---|---|---|
_type | string | Always job. This is a job row, not an error row. |
_schemaVersion | string | Output contract version, currently 1.0. |
_source | string | Always teamtailor. |
company | string | Normalized input slug, such as polestar. |
jobId | string | JobPosting identifier when supplied, then numeric ID in the validated job URL, then feed ID. Keep as text; sample 3528756. |
title | string | Feed title with repeated whitespace collapsed; sample Internship | Retail Network. An item without a usable ID or title is skipped and reported. |
department | string or null | Direct RSS department; sample Global Sales. Missing RSS value stays null. |
team | null | No separate team value is extracted. It is not inferred from department. |
location | string or null | First unique JSON address; RSS-name fallback only when JSON addresses are unavailable. Sample Cologne, Central Europe, DE. |
allLocations | string[] | Unique addresses or fallback RSS names, in source order. No location gives [], not null. |
workplaceType | null | No separate workplace-type classification is created. |
commitment | null | No separate contract or employment-type value is extracted. |
country | string or null | Two-letter code from the first JSON address, uppercased; sample DE. A missing first code stays null even if a later address has one. |
url | string or null | Validated HTTPS job URL on the selected slug's .teamtailor.com host. Unsafe, redirected/custom-host or unsuitable values stay null. |
applyUrl | string or null | Currently the same validated public job URL as url; not a separate direct application endpoint. |
postedAt | string or null | Feed date_published, converted to UTC ISO time; sample 2024-01-17T14:42:18.000Z. Missing or invalid date stays null. |
remoteStatus | string or null | Direct RSS label, such as none, hybrid or fully. It is not a guessed boolean. |
updatedAt | null | No changed-job timestamp is extracted. |
descriptionText | string or null | Readable text from content_text, then content_html, then summary. Markup is removed. Missing text or descriptions off gives null. |
_scrapedAt | string | UTC collection time for this row; different from publication time. |
Null means the output has no supported value, not that a job failed. Do not treat null as an empty string. A consumer that requires an always-null department needs to handle the RSS addition; this Actor does not promise that stricter contract.
Default Key-value store: OUTPUT and RUN_SUMMARY
INPUT holds the submitted settings with any defaults supplied by the platform. OUTPUT is a small result manifest. RUN_SUMMARY explains how the run ended. These records are separate from Dataset job rows.
| OUTPUT field | Type | Meaning |
|---|---|---|
schemaVersion | string | Manifest contract version 1.0. |
status | string | succeeded, partial, not_found, failed or cancelled. |
generatedAt | string | Summary finish time in UTC. |
companyCount | number | Number of companies requested. |
datasetItemCount | number | Number of rows acknowledged by Dataset writes. |
companies | object[] | Per-company outcomes; all fields are listed below. |
monitorState | object, optional | Present only in monitor mode; reference fields are below. |
| RUN_SUMMARY field | Type | Meaning |
|---|---|---|
schemaVersion | string | Summary contract version 1.0. |
outcome | string | Same semantic outcomes as OUTPUT status. |
startedAt, finishedAt | string | UTC run-processing start and finish times. |
durationMs | number | Elapsed product-processing milliseconds. |
firstRowLatencyMs | number or null | Time until the first successful Dataset write; null when no row was written. |
companiesRequested, companiesCompleted | number | Requested companies and companies that reached a non-cancelled result. |
datasetRowsWritten | number | Acknowledged Dataset rows. Compare with Dataset count and OUTPUT count. |
httpRequests, retries | number | Request attempts, including retries, and retry attempts. Two feed requests per healthy company are normal. |
responseBytes | number | Bytes from successfully read feed bodies. Error bodies are excluded. |
residentMemoryBytesAtFinish | number | Process memory observation at finish; not platform peak memory. |
apifyComputeUnits, estimatedCostUsd | null | These are not calculated in the product summary. Check platform billing separately. |
cancellation | string | none, requested, run_timeout, platform_abort or platform_migration. |
companies | object[] | Per-company counters and errors. |
fatalErrorCode | string, optional | Present on a fatal failure; may be invalid_input, actor_runtime_error, output_storage_error or summary_storage_error. |
monitorState | object, optional | Present for monitoring; points to persistent state. |
companies[] field | Type | Meaning |
|---|---|---|
company | string | Company slug. |
status | string | ok, partial, not_found, error or cancelled. |
feedItemCount | number | Number of JSON items read, including rejected items. |
validJobCount | number | Number of valid unique posting IDs. |
duplicateJobCount | number | Valid duplicate posting IDs discarded. |
emittedJobCount | number | Rows saved for this company after filters, seen-ID checks and cap. |
rssMatchedCount | number | Unique valid jobs joined to RSS. |
newJobBaselineCreated | boolean | True when this monitor/company had no previous state record. |
errorCodes | string[] | Source, state or write errors; empty for a normal result. |
Named monitoring state
OUTPUT and RUN_SUMMARY use the same monitorState reference:
| Reference field | Type | Meaning |
|---|---|---|
storeId | string | Apify ID of the named Key-value store. |
storeName | string | teamtailor-monitor-v2- plus a scope hash. |
namespace | string | Your monitorNamespace value. |
schemaVersion | string | State format 2; separate from job contract 1.0. |
Each company uses a SEEN-<UPPERCASE-SLUG> record, such as SEEN-POLESTAR.
| State record field | Type | Meaning |
|---|---|---|
schemaVersion | string | State format 2. |
savedAt | string | UTC time of the last state write. |
jobIds | string[] | IDs already saved to the Dataset by this monitor; up to 50,000 per company. |
Only acknowledged rows enter the saved-ID set. State is isolated by Actor/account identity, namespace and title/location/remote/date filters; companies have separate record keys. Cap and description choice do not form part of that identity. Old v1 IDs are not imported into v2. No snapshot files, content diffs, changed/removed lists or history of every source job are produced.
Pricing and cost examples
Check the pricing model and charge unit shown on the Actor page before Start. For the pay-per-event configuration described here, a useful company feed check costs USD0.018 and each saved job row costs USD0.00045. A complete successful check with zero matches or no unseen IDs is still a feed check. This guide does not apply a pricing setting; the live Actor page governs your charges. Read the price and charge unit shown on the Actor page before Start. Use the run details for actual platform usage. Export and storage operations can also use platform resources.
| Example | Scope / output | Cost and stop choices |
|---|---|---|
| Small snapshot | One slug, cap 10; the saved example has 10 rows | Check the current price. Set a timeout and the supported maximum charge limit before running. |
| Small new board | One slug, cap 3; a checked source gave 3 rows | Fewer saved rows do not guarantee a proportionally cheaper run: the feeds are still fetched. |
| Capped monitor | One slug, cap 2; checked repeats gave 2 then 2 distinct rows | Each repeat reads the feeds. Zero new rows can still use platform resources and incur the successful feed-check fee in pay-per-event mode. |
| Larger allowed input | Up to 5 slugs and cap 55 per slug | This is an input ceiling, not an observed price for 275 live rows. Do not estimate that bill from a ten-row example. |
Descriptions off reduces output size, not feed fetching. Do not assume error or empty runs are free. See Apify pricing models and run charges.
Use cases
| Buyer job | Input choice | Useful fields | Next step |
|---|---|---|---|
| Review an employer's current openings | Snapshot, one known slug | title, location, descriptionText, url | Export JSON or read the public job page. |
| Track new matching job IDs | Monitor, stable namespace and filters | company, jobId, postedAt, _scrapedAt | Add returned rows to your own database; deduplicate by company and ID. |
| Watch a location or role | locations and/or titleKeywords | allLocations, title, remoteStatus | Review the filtered rows and source links. |
| Check why a board is incomplete | Keep the run summary | Company status, errors, counts | Fix input or source access before relying on the result. |
Scheduling and monitoring
- Save a valid monitor input as an Apify Task if you want to reuse it.
- Keep the same
monitorNamespaceand filters for that monitor. - Open Apify Schedules and choose that task or Actor with the saved input.
- Choose the timezone and times you need. Allow enough time between runs to avoid overlap.
- Check the first scheduled run's Dataset, OUTPUT and RUN_SUMMARY.
These are setup instructions; the Actor does not create schedules. See Actor and task schedules.
The first run emits current matching IDs and creates state. A checked capped monitor emitted two matches, then two different matches; its state grew from two to four IDs. Repeat until unseen matches are drained. Use a new namespace to reset logically; the old named store stays in your account. There is no reset switch or automatic deletion.
Keep monitoring runs sequential. Dataset writes and state writes are not one atomic transaction. If a state write fails, rows can reappear next time. An ID that changes its text or later disappears is not returned as a changed or removed job. Very old emitted IDs can fill the 50,000-ID state ceiling; choose a new namespace when you need a fresh baseline. An interrupted run is not automatically resumed as a content-history scan.
API, MCP and integrations
The API starts a run and returns a run ID and storage IDs. Poll that run until it reaches a terminal status, then read its Dataset. Use the build number your account can access; a tag is mutable. This example uses the exact private Actor ID. Set APIFY_BUILD to the immutable build number confirmed for your candidate; the saved output example comes from earlier build 0.3.1. Access must be granted to your account.
Set APIFY_TOKEN and the verified immutable APIFY_BUILD in your environment outside the script. Do not put a real token in this README, a URL or shared input.
Starting a run can cost money. This is a copyable example, not a run started by the guide. The maximum charge parameter is an Apify run option, not an Actor input field. Check the returned status and billing; do not retry an uncertain POST blindly. See the Run Actor API.
From the returned run, use defaultDatasetId with GET /v2/datasets/{datasetId}/items?format=json&clean=false. Use defaultKeyValueStoreId to read OUTPUT and RUN_SUMMARY. CSV and XLSX use the same items endpoint with format=csv or format=xlsx. Keep authorization in a header. Some Dataset access is possible by ID; do not share private run/storage IDs or exports with people who should not see them.
You can use the HTTP API from your own automation. Treat company + jobId as the job key, and check the summary before importing rows. This Actor does not provide its own MCP server or endpoint. No MCP service is installed by this guide. An agent must have a working, authorized API or platform connector before it can start runs; an MCP connection alone does not make this private Actor accessible.
Limits and partial results
- Use 1–5 unique public slugs on the global
.teamtailor.comhost. URLs, custom domains,.na.teamtailor.comand.au.teamtailor.comare outside the input contract. - The output cap is 1–55 per company. Only the first JSON page is fetched. If it contains
next_url, results remain usable but the company is partial withjson_feed_paginated; the Actor does not follow that URL. - Historical checks on build 0.3.1 emitted 10 snapshot rows and parsed a 55-job board for a three-row cap. Build 0.4.2 was checked with four small Cloud runs that emitted 2, 1, 1 and 1 rows. Ten-row comparisons and larger capacity evidence were reused from earlier checks. These are not proof of 275 live output rows or complete coverage of every employer.
- Each request has a 12-second timeout, at most one retry and a 5 MB response limit. Redirects are blocked. The Actor has a five-minute processing deadline; a shorter platform timeout or charge limit can stop it earlier.
- RSS may be absent, smaller than JSON or invalid. JSON jobs stay usable, but RSS fields can be null and the company is partial. An RSS-only location name or a remote filter can then exclude matches.
- The Actor does not infer salary, separate team, employment type, changed timestamps or remote status from prose.
team,workplaceType,commitmentandupdatedAtremain null.
| Situation | Dataset / summary | Meaning |
|---|---|---|
| Existing feed, no items or no matches | Empty Dataset; company ok, run succeeded | Valid empty result. Check filters or drained monitor state. |
| JSON feed returns 404 | No rows for that company; not_found, feed_not_found | That public feed was not found. Not a timeout or valid empty board. |
| RSS unavailable or unmatched | Available JSON rows; partial, RSS error or rss_unmatched_items | Some enrichment is unavailable. |
| One company fails, another succeeds | Good rows retained; run can be partial | Read each company entry; do not discard valid rows from other boards. |
| Invalid input or technical failure | Failed summary when it can be saved; possibly no rows | Check the fatal error and platform logs. Do not label it a valid empty board. |
| Cancellation or storage failure | Previously written rows may remain | Inspect summary and platform status before using the run as complete. |
Use public feeds with care. Public job data can change or disappear. Source availability and permissions are the employer's responsibility; you are responsible for your use and retention of the exports. No candidate data or private recruitment account access is part of this tool.
Troubleshooting
| Symptom | Likely reason / error codes | Check and safe action |
|---|---|---|
| Input rejected | invalid_input; URL, duplicate slug, unsupported field, null or invalid date | Use the nine documented keys and a known bare slug. Check cap and date format. |
| No rows, normal outcome | Empty feed, filters or saved IDs | Check validJobCount, filters and emittedJobCount. For a fresh baseline use a new namespace. |
| Board not found | feed_not_found | Confirm the global public slug. A branded URL is not a substitute. |
| Feed cannot be read | timeout, network_error, rate_limited, http_5xx, http_4xx | Check the source later. Transient errors get at most one retry; do not create overlapping monitors. |
| Feed blocked or too large | redirect_blocked, response_too_large | Use a supported slug. The Actor will not follow an arbitrary host or raise the limit for this run. |
| Bad feed data | invalid_json_feed, invalid_json_feed_shape, invalid_job_items, rss_source_error | Read the source and summary; do not turn a parsing error into an empty-board claim. |
| Missing enrichment | RSS-prefixed request errors, rss_unmatched_items or rss_cancelled | JSON rows can still be useful. Check null values before filtering or importing. |
| Feed advertises more pages | json_feed_paginated | Treat the page as partial. Full pagination is not provided. |
| State cannot be read or saved | state_read_error, state_write_error | Check the referenced named store and access. Avoid overlap; state-write failure can cause repeats. |
| State is full | state_capacity_exceeded | The 50,000-ID ceiling stopped new emission. Choose a new namespace for a separate baseline. |
| Billing limit or problem | charge_limit_reached, billing_operation_error, billing_configuration_error, billing_duplicate_result | Read run billing and logs. The Actor checks the combined feed/row budget before writing. Unknown prices or synthetic extra fees stop work. It does not replay a nonempty run Dataset or retry an uncertain charge. Dataset delivery and event charging are not atomic; a billing failure can leave acknowledged rows. |
| Dataset/terminal records fail | dataset_write_error, output_storage_error, summary_storage_error, actor_runtime_error | Inspect platform logs. A missing record is not a successful empty result. |
FAQ
Why can a monitor check cost money when no new jobs are returned?
A healthy check still reads the feeds and compares current IDs with saved IDs. In pay-per-event mode, the feed-check event covers this useful check. A duplicate or already-seen job is not charged as a new job row. Errors and partial checks with zero rows have no useful billable event; they can still use platform resources.
Do I need a Teamtailor API key?
No. The Actor reads public career feeds. You still need an Apify account with access and available usage for a Cloud run.
Does the first monitor run return zero jobs?
No. It returns current matching jobs up to the cap and saves only those IDs. Later runs return unseen matches. A low cap can give several nonempty repeats before zero.
Can I pass a custom career URL or find all Teamtailor employers?
No. Add known global Teamtailor slugs. The Actor does not discover all employers or resolve custom domains.
Why does an old job appear as new?
New means not previously emitted by that monitor. postedAt is the source publication date; _scrapedAt is collection time. Add postedAfter if you need a publication-date boundary.
Does hybrid count as remote?
No. remoteOnly requires an explicit accepted RSS value. Missing remote status and prose about flexible work are not enough.
Can I get changed, removed or every historical job?
No. State stores emitted IDs, not content snapshots or deletion events. Feed pagination, retention and employer changes can limit what you see.
Will a low cap or descriptions off cut the run cost by the same ratio?
No such cost reduction is promised. The feeds are still read. Check the shown price and the run's real usage; storage and exports can add resource use.
Related Actors
- Ashby Jobs Scraper — use the same owner's separate tool for public Ashby career boards.
- Lever Job Scraper — use the same owner's separate tool for public Lever boards.
These are separate products with their own inputs and prices. Their coverage does not expand this Actor's Teamtailor input contract.
Support
Open the Actor's Issues tab in Apify Console for a bug, question or feature request. Include the run ID, input mode, Dataset row count and relevant summary status/error code. Send only information you are allowed to share. Never include an API token, cookie, candidate record or private billing payload.
The examples and artwork explain the public job-feed workflow. They do not imply Teamtailor endorsement, a full job-history service or a source availability guarantee.


