
Reddit Keyword Monitor
Pricing
from $1.00 / 1,000 keyword matches
Reddit Keyword Monitor
Monitor Reddit for keywords, phrases and topics across all Reddit or selected subreddits. Track posts and comments, deduplicate matches, filter noise, and return only new results on scheduled runs. Export clean JSON, CSV or Excel. No Reddit login or API key.
Pricing
from $1.00 / 1,000 keyword matches
Rating
0.0
(0)
Developer
Delowar Munna
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
a day ago
Last modified
Categories
Share
Monitor Reddit for keywords, phrases and topics across all of Reddit or the subreddits you choose. Track posts and comments, get one row per match with every keyword it matched, filter out noise and bots, and — on a schedule — receive only the new matches on every run. No Reddit login, API key or AI. Export clean JSON, CSV or Excel.
Configure keywords → schedule the Actor → receive only new matches.
What it does
- Searches all of Reddit or selected subreddits for your keywords and exact phrases, within a time window (past hour to all time) or since a date.
- Checks posts and comments, including comments that mention your keyword under any post. A row is delivered only when your keyword actually appears in that post or comment — Reddit's search finds candidates, the Actor confirms the match.
- Returns one row per post or comment, with
matchedKeywordslisting every keyword it matched. Found by three keywords or three searches? Still one row, one charge. - Noise filters: require words (any or all), exclude words, excluded authors, bot filtering.
- Subreddit-only monitoring: no keywords, just the newest posts (and comments) of a community.
- Only-new monitoring with a monitor key, and a baseline-only first run for professional setups: the first run records what exists today, later runs deliver only what is new.
- Run summary: posts and comments scanned, unique matches, new matches delivered, already-seen suppressed, duplicates merged, authors filtered.
Quick start
Monitor two keywords across Reddit:
Restrict to subreddits:
Filter the noise out of an ambiguous keyword:
Scheduled monitoring — run it daily and get only what is new:
Start a monitor from a clean baseline (the first run returns nothing and is not charged):
FAQ
What can I monitor?
Any keyword, phrase or topic: product and company names, technologies, regulations, launches, feature requests, error messages, events. Up to 100 keywords per run, across all of Reddit or a list of subreddits.
Do I need a Reddit login or API key?
No. The Actor reads public Reddit content only. No login, no API key, no cookies.
Can I search all of Reddit?
Yes — leave subreddits empty. Each keyword is one search across Reddit.
Can I restrict to subreddits?
Yes. webscraping, r/webscraping and https://www.reddit.com/r/webscraping/ all work. Each
keyword is then searched in each listed subreddit.
Are comments supported?
Yes. With sourceTypes COMMENTS or BOTH, every keyword is also searched among Reddit's
comments (across all of Reddit or in your subreddits), so a comment that mentions your keyword is
found under any post, not only under posts that mention it. Each comment is matched on its own
full text and carries its parent post's title and URL in parentPost.
In subreddit-only monitoring (no keywords) there is nothing to search comments for, so the top
comments of each new post's thread are read instead (up to maxCommentsPerPost, replies included).
Can I monitor subreddit feeds without keywords?
Yes. Leave keywords empty and list subreddits: every new post in the time window (and, with
BOTH or COMMENTS, its comments) is delivered. Your require/exclude words and author filters still
apply.
How do exact phrases work?
Put a phrase in quotes: "customer service" matches those words in that order. Without quotes,
pricing issue matches when both words appear, in any order — the way Reddit's own search reads it.
A single word matches as a whole word with an optional plural (CRM matches "CRMs", not "CRMify").
The keyword is reported in matchedKeywords exactly as you typed it, quotes included.
How does only-new monitoring work?
Turn on onlyNew and give a monitorKey (for example coding-ai-tools). The Actor remembers every
post and comment it delivers under that key — its first-seen time, last-seen time and matched
keywords — and skips them on later runs. Runs with the same key share the memory; different keys
are independent. If you leave monitorKey empty, one is derived from your keywords and subreddits.
A match that was cut by maxResults or your spending limit is not remembered, so the next run can
still deliver it. An item already delivered is not delivered again even if it later matches another
keyword.
Once a run of a monitor has read all its searches and delivered everything it found, the next run
with the same settings stops each newest-first search at the first page of matches it already
delivered, so scheduled runs only read what is new. Change the keywords, subreddits, filters or time
window, or let a run be cut by maxResults or your spending limit, and the next run reads its whole
window again.
What is baseline-only mode?
With onlyNew on and baselineMode BASELINE_ONLY, the first run of a monitor records every
current match and delivers none (and is not charged). From the second run on you receive only what
appeared after you started monitoring:
How are duplicate keyword matches handled?
One post or comment is one row, whatever found it. If a post matches openai, chatgpt and
ai tools, you get one row with "matchedKeywords": ["openai", "chatgpt", "ai tools"] and one
charge. The same goes for a post found by a global search, a subreddit search and a feed.
Can I require or exclude words?
Yes. requireWords keeps an item only if it also contains one of them (requireMode ANY) or all
of them (ALL). excludeWords drops any item containing one of them.
Can I exclude bots or specific authors?
Yes. skipBots (on by default) drops AutoModerator and other well-known bot accounts, and text that
says it was posted automatically. It is deliberately conservative: a username is not treated as a bot
just because it contains "bot". excludeAuthors drops any usernames you list.
Why may scores, comment counts or text be null?
Different public Reddit sources expose different fields. When a value is not available it is null
— never a made-up zero. A hidden score is null. When a post's body cannot be read, text is
null, textAvailable is false, and the match was confirmed by Reddit's search rather than in the
body (matchBasis: "reddit-search"); require/exclude words are then checked against the title.
Are search results exhaustive?
No. Reddit's search returns at most roughly 250 results per keyword, sort and time window, and only public, non-deleted content. This Actor is built for repeated scheduled monitoring, not for exhaustive historical coverage. To go deeper, narrow the time window or add subreddits.
How often should I schedule it?
Use an Apify schedule:
| Cadence | Good for | Suggested settings |
|---|---|---|
| Hourly | Fast-moving alerts | maxAgeHours: 2, onlyNew: true |
| Daily | Normal monitoring | maxAgeHours: 24 or timeRange: DAY, onlyNew: true |
| Weekly | Research | timeRange: WEEK, onlyNew: true |
A small overlap between the window and the schedule is fine — only-new monitoring removes repeats.
How does pricing work?
Pay per result: you are charged once per unique post or comment delivered. Search requests,
retries, non-matches, duplicates, filtered items, items already delivered to your monitor, a
baseline-only first run, results beyond maxResults and failed searches are never charged. Results
are delivered newest first, so a spending limit keeps the freshest matches. See the Pricing tab
for the current rate — this README deliberately does not quote figures.
Can I use the API / MCP?
Yes. Run it like any Apify Actor through the API, the JavaScript/Python clients, integrations (Make, Zapier, n8n, webhooks for alerts) or Apify's MCP server, and read the dataset views below.
Input reference
| Field | Default | Description |
|---|---|---|
keywords | ["web scraping"] | Up to 100. "quoted" = exact phrase. Empty + subreddits = subreddit-only monitoring |
subreddits | [] | Names, r/name or URLs. Empty = all of Reddit |
sourceTypes | BOTH | POSTS, COMMENTS, BOTH |
sort | NEW | NEW, RELEVANCE, TOP, COMMENTS, HOT |
timeRange | WEEK | HOUR, DAY, WEEK, MONTH, YEAR, ALL |
postedAfter | — | ISO date or date-time, e.g. 2026-10-14T00:00:00Z. Wins over maxAgeHours and timeRange |
maxAgeHours | — | e.g. 6, 24, 72. Wins over timeRange |
maxResults | 100 | 1–10,000 delivered unique results per run, newest first |
maxCommentsPerPost | 50 | 1–100 comments read per thread in subreddit-only monitoring |
onlyNew | false | Skip what earlier runs of the same monitor delivered |
monitorKey | — | Name of the monitor's memory. Alone (without onlyNew) it marks rows isNew without skipping |
baselineMode | RETURN_CURRENT | BASELINE_ONLY: first run records, delivers nothing |
requireWords / requireMode | [] / ANY | Also require these words (ANY / ALL) |
excludeWords | [] | Drop items containing these |
excludeAuthors | [] | Usernames to ignore |
skipBots | true | Drop well-known bots |
maxConcurrency | 3 | 1–5 searches/threads at once |
proxyConfiguration | Apify Datacenter | See the proxy policy below |
An empty run (no keywords and no subreddits), an unparseable postedAfter, a non-positive limit or
an unknown option value stops the run with a clear message. One invalid keyword or subreddit does not:
it is skipped and reported in SOURCE_SUMMARY.
Output
Every tab below shows every row: Apify dataset views choose columns, not rows, so the Post columns
tab also lists comments (with an empty title) and the Comment columns tab also lists posts. Filter on
sourceType (POST / COMMENT) in your export or integration to split them.
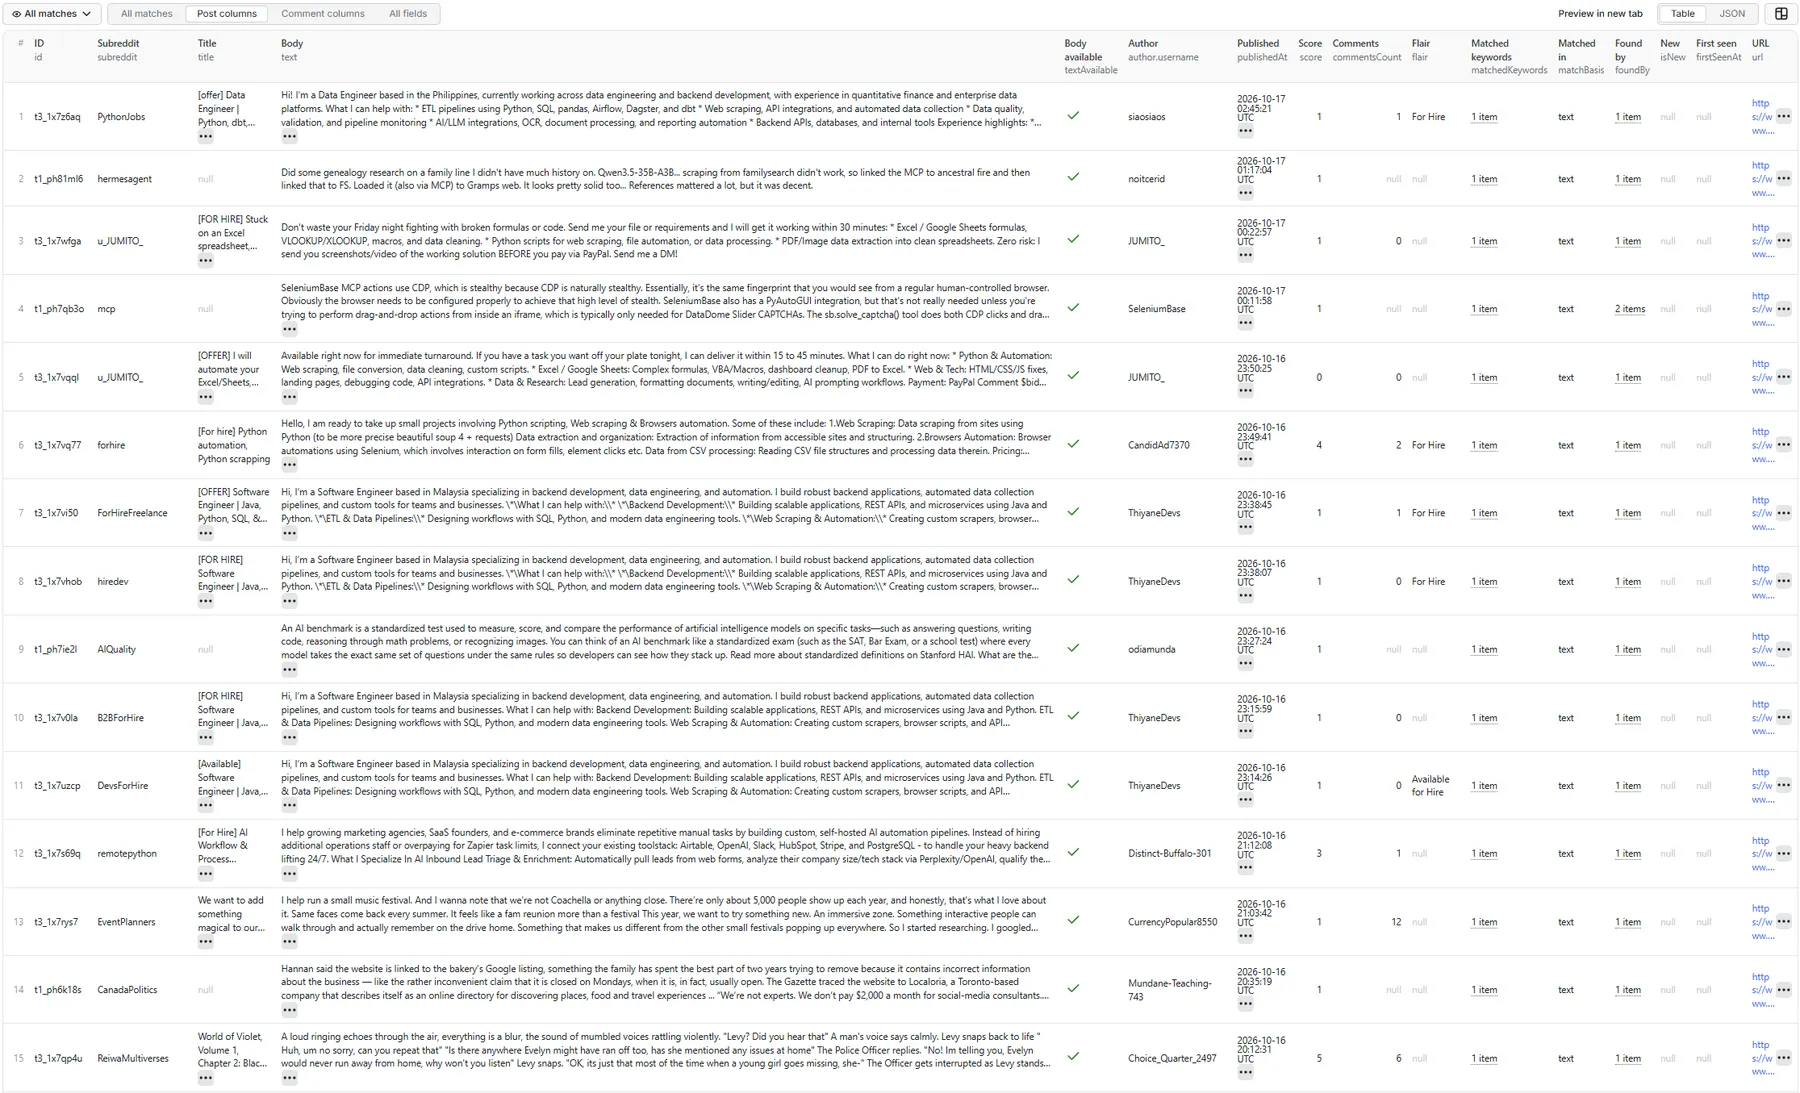
All matches tab
Posts and comments together, newest first. A post from a one-off run (no monitor, so isNew and
firstSeenAt are null):
Post columns tab
The same post with the post columns — its body was read and the keyword confirmed in it
(matchBasis: "text"):
Comment columns tab
A comment from a scheduled monitor run, found by comment search under a post that does not name
the keyword. Comment search does not say whether a top-level comment's parent is the post, so
parentId is null here:
All fields
Every field of a row — here a reply (parentId is the comment it answers):
Usernames in these samples are anonymised.
| Field | Meaning |
|---|---|
sourceType | POST or COMMENT |
id | Reddit fullname (t3_… post, t1_… comment) — the dedupe key together with sourceType |
parentId | For a comment: the comment it replies to (t1_…) or the post (t3_…); null when Reddit's comment search does not say |
text, textAvailable | Body text; textAvailable: false when the post body could not be read |
matchedKeywords | Every keyword the item matched, as you typed it |
matchBasis | text (found in the item's text), reddit-search (title-only post, matched by Reddit's search), subreddit-feed (no keywords) |
foundBy | Which searches found it (comments: … = comment search) |
isNew, firstSeenAt | Monitoring state; null when no monitor is used |
parentPost | For a comment: the post's ID, title, URL and author (author is null when the comment came from comment search alone) |
Dataset views and run records
| View / record | What it shows |
|---|---|
| All matches | Every match, newest first, with the columns common to posts and comments |
| Post columns | Every match, with the post columns (body, flair, comment count, match basis, found by) |
| Comment columns | Every match, with the comment columns (parent post, parent ID, poster flag) |
RUN_SUMMARY | Keywords, subreddits, search operations, posts and comments scanned, unique matches, new matches delivered, already-seen suppressed, duplicates merged, authors and bots filtered, drops by reason |
SOURCE_SUMMARY | Each search's status: SUCCESS, NO_RESULTS, INVALID_KEYWORD, INVALID_SUBREDDIT, SUBREDDIT_NOT_FOUND, RATE_LIMITED, BLOCKED, PARTIAL_RESULT, TEMPORARY_REDDIT_ERROR, PROVIDER_ERROR |
One failed keyword or subreddit search never fails the run; it is reported there.
Limitations
- Search depth is bounded. Reddit's search returns roughly 250 results per query, sort and time window. Repeated scheduling is the intended monitoring model.
- Comment search depth is bounded too, like post search, and only comments Reddit's search indexes are found. In subreddit-only monitoring, thread reading is capped per thread (the comments Reddit ranks first are read). Scheduling with only-new monitoring is how a monitor stays complete over time.
- Comment search does not say whether a top-level comment's parent is the post, or whether its
author wrote the post:
parentIdandisSubmitterare thennull, andparentPost.authorisnullunless the post was also found (a reply's parent comment is given). Comments read from a thread in subreddit-only monitoring carry all three. - Matching is literal, not topical: a post that mentions your keyword in passing matches; a post about your topic that never uses the keyword does not. Use several keywords and require/exclude words to tune it.
- Deleted, removed and private content is unavailable, and public content may later be edited or deleted.
- Long runs stop early to deliver. Shortly before the run's timeout, collecting stops and the matches found so far are delivered (the status message says so). Results are delivered at the end of a run, so aborting a run part-way can leave it with none.
🚦 Proxy policy
Use Apify Datacenter proxy (the default) or no proxy — both work for Reddit search and comment pages at this Actor's conservative request rate.
Apify Residential proxy is not supported. The Actor fails at startup if apifyProxyGroups
includes RESIDENTIAL. Reason: on pay-per-result Actors residential bandwidth is billed to the
developer, not the run, and Reddit comment pages are large, while Reddit serves the same pages to
datacenter addresses.
If you genuinely need residential routing, supply your own provider through the proxy editor's Custom proxy URLs field — that traffic goes through your provider, not Apify:
Responsible use
This is an unofficial tool and is not affiliated with Reddit. It processes public posts and comments only.
- Search coverage is bounded by Reddit's own search behaviour.
- Follow each subreddit's rules and Reddit's terms. Public content may later be deleted or edited.
- You are responsible for lawful downstream processing of the data.
The Actor never reads private messages, never asks for account credentials, never votes, replies or sends messages, and never infers sensitive attributes about people.
Related Actors
- Reddit Posts & Search Scraper — every post for a search or subreddit, with full post fields
- Reddit Comments Scraper — whole comment threads with parent, depth and path
Changelog
- 1.0 — first release: keywords and exact phrases across Reddit or subreddits, subreddit-only
monitoring, posts and comments, local keyword validation with matched-keyword attribution,
require/exclude words, excluded authors, bot filtering,
postedAfter/maxAgeHours, only-new monitoring with a monitor key, baseline-only first run.


