
Workday Jobs Scraper: Salary, Remote & Level Filters $1/1k
Pricing
Pay per event
Workday Jobs Scraper: Salary, Remote & Level Filters $1/1k
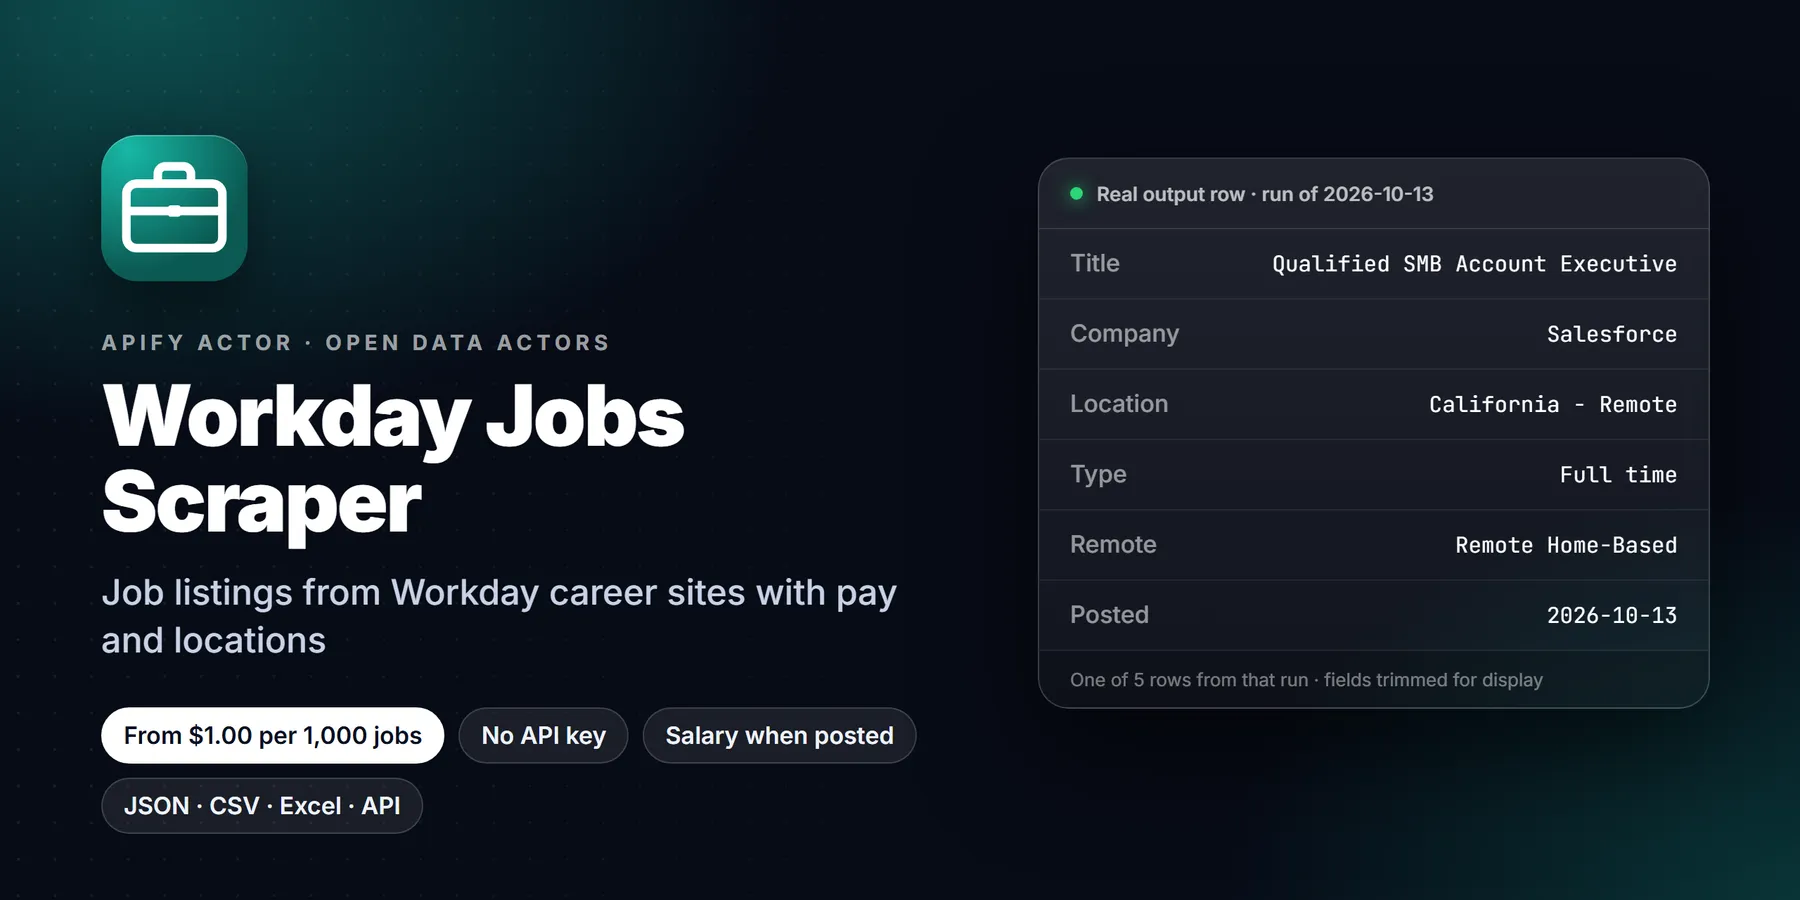
Scrape Workday career sites (myworkdayjobs.com) or 165+ big employers by name. Filter by keyword, location, date, remote/hybrid, salary, title and description. Rows add salary range, employment type, level, cities and logo. Only-new mode. $1 per 1,000 jobs.
Pricing
Pay per event
Rating
0.0
(0)
Developer
Detroit Web Agent - Open Data
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
12 hours ago
Last modified
Categories
Share
Workday Jobs Scraper: any myworkdayjobs.com career site, 165+ companies built in
| Price per 1,000 jobs | Free plan | Starter | Scale | Business |
|---|---|---|---|---|
| This Actor | $1.00 | $1.00 | $1.00 | $1.00 |
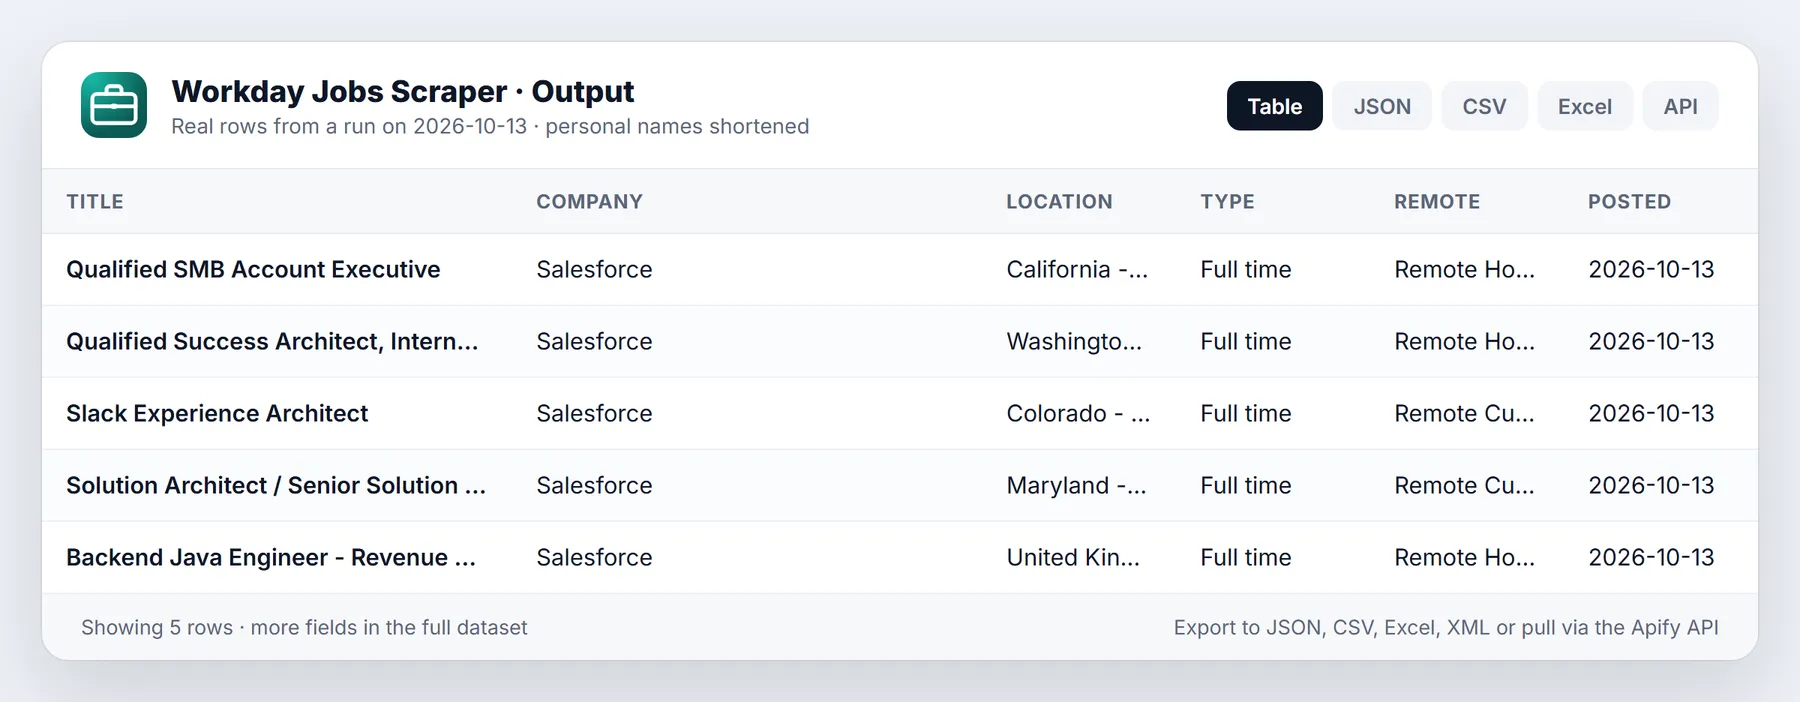
- In short: Workday Jobs Scraper (Apify actor
transparent_meteorite/workday-jobs-scraper) scrapes job postings from any Workday career site (myworkdayjobs.com), or from 165+ verified large employers by name. - Who it is for: job boards and aggregators, recruiters, HR-tech and labor-market analysts, sales teams tracking enterprise hiring.
- Input: company names, company domains or Workday career-site URLs; search text; location include/exclude; title exclusion; description search; posted within days or posted-after date; remote/hybrid/on-site; salary-stated only; include description; max items per company; only-new mode.
- Output: job title, company, location(s) plus derived cities/regions/countries, work arrangement, employment type, experience level, posted date, job ID, URL, salary min/max/currency/period (and annualized), employer logo and URL, optional full description.
- Price: $0.001 per job listed, $0.002 per job with full description, $0.00005 per run start. Pay per result, no subscription; Apify's free plan credit covers a first test.
- Limits: Workday returns at most 2,000 jobs per search, so very large employers need keyword or location splits.
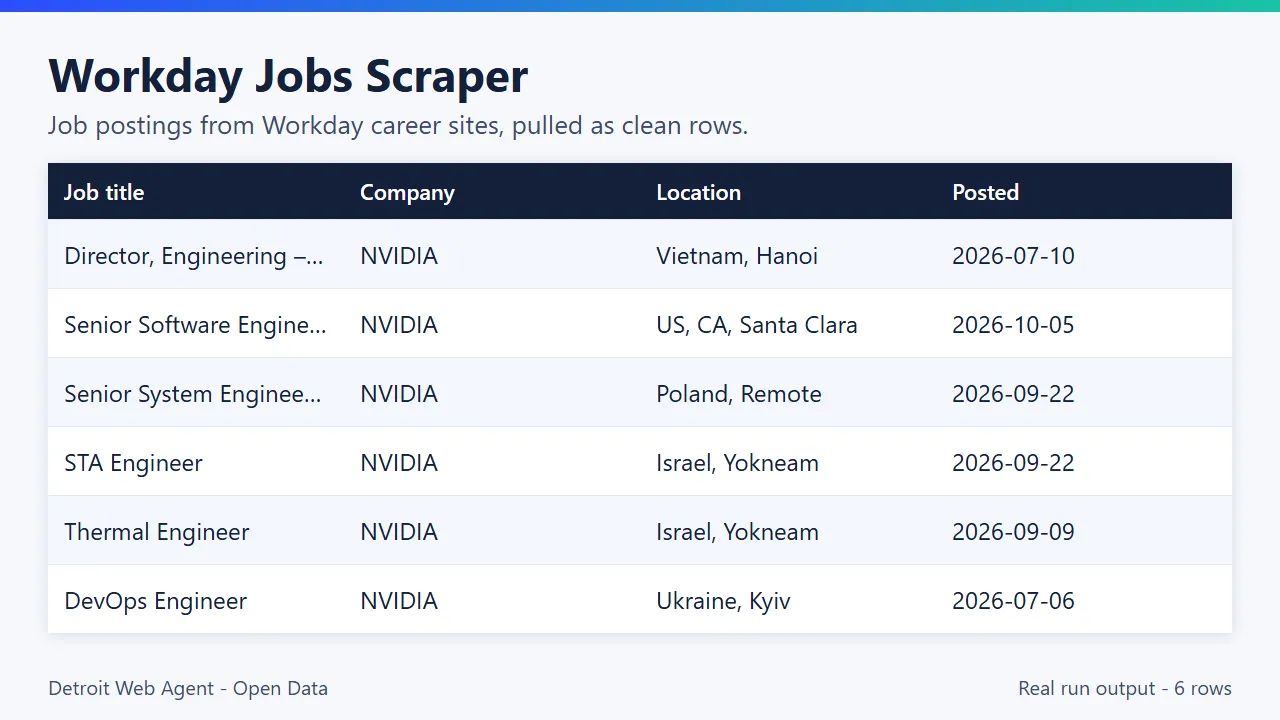
Key facts
- Actor name: Workday Jobs Scraper
- Actor ID:
transparent_meteorite/workday-jobs-scraper - Store page: https://apify.com/transparent_meteorite/workday-jobs-scraper
- Data source: employers' own public Workday career sites
- Pricing model: pay per event (
apify-actor-start$0.00005,job-listed$0.001,job-with-description$0.002) - Output formats: JSON, CSV, Excel, XML, HTML table, RSS (Apify dataset)
- Access: Apify Console, REST API, JavaScript/Python clients, schedules, webhooks, Apify MCP server
- Login or third-party API key needed: no, only an Apify account
- Also known as: Workday jobs scraper, myworkdayjobs scraper, Workday careers API, Workday job postings API
- Maintainer: transparent_meteorite (independent developer)
- Last updated: 2026-10-13
Scrape job postings from any public Workday career site, or pick from a built-in, live-verified directory of 167 large employers (NVIDIA, Salesforce, Boeing, Pfizer, Target, Home Depot, Bank of America, Cisco, Intel and more). Search by keyword, filter by location and posted date, pull full descriptions and stated salary ranges, and run on a schedule to get only new jobs. $1 per 1,000 jobs.
Run in 30 seconds
- Open the prefilled run (free Apify account; it creates a saved task with a working input).
- Press Start. The input is small on purpose, so the first run is quick and costs a few cents at most.
- Open the Output tab, switch to Table view, download as CSV, Excel or JSON.
Prefilled input:
Ready-made presets by use case (each opens as a saved task you can edit):
Why choose this over alternatives
- Any Workday career site (myworkdayjobs.com) by URL, or 165+ verified employers by name.
- Keyword, location and posted-date filters, full descriptions, salary ranges, remote/hybrid.
- Only-new-jobs delta mode for daily schedules.
- $1 per 1,000 listed jobs, $2 per 1,000 with full descriptions.
| Check | This actor |
|---|---|
| Automated tests on the current build | 64 passed, 0 failed |
| Employers in the bundled directory | 165+ verified |
Measured 2026-10-09 (source: this actor's own test suite and runs).
What does Workday Jobs Scraper do?
Thousands of large employers host their careers page on Workday (*.myworkdayjobs.com). Each of those sites exposes the same public job-search data that your browser loads when you visit it. This Actor reads that public data directly and returns clean, structured rows:
- Any Workday career site: paste a URL such as
https://nvidia.wd5.myworkdayjobs.com/NVIDIAExternalCareerSite(or any job link from it). The tenant, data center (wd1,wd5,wd12...) and site name are parsed for you.myworkdaysite.comURLs work too. - Or just type company names: 167 big employers are bundled with their verified Workday URLs, so
["Pfizer", "Target"]is enough. UseALLto sweep the whole directory. - Keyword search through Workday's own search engine (
searchText). - Location filter (
Texas,London,Remote...), checked against every location of multi-location jobs. - Posted within N days or posted on/after a date, turning Workday's "Posted 3 Days Ago" into a real ISO date.
- More filters: exclude title words (
titleExclusion), exclude locations, require words in the description (descriptionSearch), keep only Remote / Hybrid / On-site (workArrangement), keep only jobs that state a salary (hasSalary), or pick employers by website domain (domainFilter, e.g.boeing.com). - Derived fields on every row:
employmentType(Full-time, Part-time, Contract, Temporary, Internship),experienceLevel(Internship, Entry, Mid, Senior, Lead/Manager, Principal, Director, Executive),workArrangement,cities/regions/countries, annualized salary and the employer's career-site logo. - Full job details on demand: description text (and HTML), exact posting date, all locations, country, time type, remote/hybrid/on-site, hiring legal entity, and salary range when the posting states one (parsed into min, max, currency, period).
- Only-new mode (delta): remembers which jobs you already received and returns just the new ones. Seen jobs are never charged.
Why use it?
- One Actor for every Workday employer: no per-company scraper, no browser, no login.
- Low per-job price: $0.001 per listed job, $0.002 with full description. No monthly rental.
- Fast: the default input (2 companies, 20 jobs each) finishes in about 5 seconds.
- Built for monitoring: schedule it daily with
onlyNewJobsand you get a clean feed of new postings for alerts, job boards, recruiting or labor-market research. - Polite and reliable: one request at a time per career site with pauses, automatic retries on HTTP 429 and 5xx with back-off.
- Clean dates: every row has
postedOnasYYYY-MM-DD, exact when details are fetched and clearly flagged (postedOnIsEstimate) when derived from "Posted N Days Ago".
How to use it
- Click Try for free (or open the Actor in Apify Console).
- Enter company names in Companies and/or paste Workday career site URLs in Workday career site URLs.
- Optionally add Search keywords, a Location filter and Posted within (days).
- Switch on Include full job description if you need descriptions and salaries.
- Click Start, then download the results as JSON, CSV, Excel, or read them via API.
- For alerts: turn on Only new jobs, save the task and add a schedule (e.g. every morning).
Input example
| Field | What it does |
|---|---|
companies | Names from the built-in directory (case-insensitive). ALL = every company. |
careerSiteUrls | Any public Workday career site or job URL. |
searchText | Keywords for Workday's search. Empty = all open roles, newest first. |
locations | Keep jobs whose location contains any of these words. |
postedWithinDays | Keep jobs posted in the last N days. |
postedAfter | Keep jobs posted on or after a date (YYYY-MM-DD). The stricter of the two date filters wins. |
titleExclusion | Drop jobs whose title contains any of these words (e.g. intern, director). |
locationSearch | Alias of locations; the two lists are merged. |
locationExclusion | Drop jobs whose location contains any of these words. Fetches job details (slower, same price). |
descriptionSearch | Keep jobs whose description contains any of these words or phrases. Fetches job details (slower, same price). |
workArrangement | Remote, Hybrid and/or On-site. Fetches job details (slower, same price). |
hasSalary | Keep only jobs whose posting states a pay range. Fetches job details (slower, same price). |
domainFilter | Employer website domains (e.g. nvidia.com) matched to the built-in directory; unmatched domains are listed in the log. |
includeDescription | Fetch the job detail (description, exact date, salary, all locations). |
includeDescriptionHtml | Also return the original description HTML. |
maxItemsPerCompany | Cap saved jobs per career site (default 100, max 2,000). |
onlyNewJobs / deltaStoreName | Delta mode and the named store that remembers seen jobs. |
maxConcurrency | Career sites scraped in parallel (default 4). |
Output fields
| Field | Meaning |
|---|---|
company, title, url, jobReqId, jobId | Employer, job title, job link, requisition number, stable ID. |
location, locations, locationsText, country | Primary location, every location (multi-location jobs), Workday's label, country. |
cities, regions, countries | Best-effort split of the location strings into city / state-province / country lists. |
workArrangement | Remote, Hybrid or On-site. From Workday's remote type, title and location; with job details also from the description (inferred On-site when nothing says otherwise). null when only the list was read and nothing is stated. |
remoteType, timeType | Workday's raw remote and time-type labels. |
employmentType | Derived: Full-time, Part-time, Contract, Temporary or Internship. |
experienceLevel | Derived from the title: Internship, Entry, Mid, Senior, Lead/Manager, Principal, Director, Executive (null when the title gives no signal). |
postedOn, postedOnIsEstimate, postedOnText, postedDaysAgo | Posted date (exact with details, otherwise derived from "Posted N Days Ago"). |
salaryText, salaryMin, salaryMax, salaryCurrency, salaryPeriod | Pay range as stated in the posting, parsed. |
salaryAnnualMin, salaryAnnualMax | The same range converted to a yearly figure (hour x 2,080, week x 52, month x 12). |
organizationLogoUrl, organizationUrl, hiringEntity | Employer career-site logo, employer URL when Workday publishes one, legal hiring entity. |
description, descriptionHtml | Only with the description switches on. |
careerSiteUrl, workdayTenant, workdaySite, scrapedAt, isNew | Source site, tenant, site name, scrape time, new-job flag in delta mode. |
Derived fields are best-effort text rules, not employer-supplied data. Salary and arrangement are filled most reliably when the job details are fetched.
Sample output
Real rows from a platform run of the default input (NVIDIA + Salesforce, engineer):
| Company | Title | Location | Posted | Req ID |
|---|---|---|---|---|
| Salesforce | Corporate Development M&A Senior Analyst | California - San Francisco | 2026-10-08 | JR363033 |
| Salesforce | Summer 2027 Intern - Tableau Research | 2 Locations | 2026-10-08 | JR363252 |
| Salesforce | Account Executive - Data Foundations, Public Sector | Australia - South Australia - Remote | 2026-10-08 | JR354774 |
| Salesforce | Software Engineer AMTS (Junior) - Keynote Demo | Mexico - Mexico City | 2026-10-08 | JR362623 |
| NVIDIA | STA Engineer | 2 Locations | 2026-09-23 | JR2016441 |
One full item with includeDescription: true (description shortened):
When a posting states pay (for example a Target analyst role: "$98,000.00 - $176,000.00"), you get salaryMin: 98000, salaryMax: 176000, salaryCurrency: "USD", salaryPeriod: "year".
Pricing
Pay per event, no subscription:
| Event | Price |
|---|---|
| Actor start | $0.00005 per run |
| Job listed (descriptions off) | $0.001 per job ($1 per 1,000) |
| Job with description (descriptions on) | $0.002 per job ($2 per 1,000), replaces Job listed |
Worked example: a daily alert over 20 companies, 50 new jobs per day with descriptions = 50 x $0.002 = $0.10 per day, about $3 per month. Listing 5,000 jobs without descriptions costs $5. Filtered-out jobs, already-seen jobs (only-new mode) and failed rows are never charged. Set a maximum charge per run in Console to cap spend; the Actor stops cleanly when it is reached.
Apify's free plan includes $5 of monthly platform credit, which covers about 4,000 job listings with this actor (at $0.001 per result, plus small platform usage). Paid Apify plans get the same data with no monthly cap; scheduled daily runs stay cheap because each run only returns new records.
Use cases
- Job boards: jobs from any myworkdayjobs.com site in one schema.
- Recruiters: watch large employers and get only new jobs each day (
onlyNewJobs). - Labor-market analysis: openings by keyword and location across employers.
- Sales signals: enterprise hiring for the teams you sell to.
Use from AI agents (MCP, ChatGPT, Claude, Perplexity)
Workday Jobs Scraper works as a tool for AI assistants through the official Apify MCP server. Add this server URL to any MCP client (Claude Desktop, Claude Code, Cursor, ChatGPT connectors, VS Code):
Claude Desktop / Cursor config:
Then ask in plain language, for example: "How do I scrape jobs from a myworkdayjobs.com site?"
Call it directly over HTTP (runs the actor and returns the dataset items in one request):
Python:
The same actor works in n8n, Make, Zapier, LangChain, LlamaIndex and CrewAI through their Apify integrations.
Questions people ask
How do I scrape jobs from a myworkdayjobs.com site? Paste the career-site URL into careerSiteUrls (or a company name from the built-in list) and run.
Is there a Workday jobs API? Workday has no public jobs API for third parties; this actor gives you one through the Apify API.
Can I get only new jobs each day? Yes, set onlyNewJobs true and schedule it.
Use it from code
Small real input: it returns only a couple of rows, so a test run costs very little (see Pricing). Set the APIFY_TOKEN environment variable to your token from Apify Console > Settings > API & Integrations.
Python (pip install apify-client)
JavaScript / Node.js (npm install apify-client)
curl (runs the actor and returns the dataset items in one call)
Send results to Google Sheets, Zapier, Make or n8n
- Google Sheets: every run's dataset has a CSV export link:
https://api.apify.com/v2/datasets/<DATASET_ID>/items?format=csv&clean=true(the dataset ID is on the run's Storage tab). In Sheets,=IMPORTDATA("<that link>")loads it. Anyone with the link can read that dataset, so share it carefully. To export to Google Drive automatically, use the Google Drive integration on the actor's Integrations tab. - Zapier: in the Apify app, use the trigger Finished Actor run (or Run Actor as an action) with
transparent_meteorite/workday-jobs-scraper, then Fetch dataset items and pass the rows to Google Sheets, a CRM or Slack. - Make: the Apify app has Watch Actor Runs, Run an Actor and Get Dataset Items modules; connect them to any Make app.
- n8n: install the Apify node (
@apify/n8n-nodes-apify) and use Run an Actor and get dataset, or the On new Apify event trigger. - Schedule and webhooks: create a Task with your input, add a Schedule in Apify Console, and add a webhook if you want a call when a run finishes.
See the Apify integrations docs for setup steps.
Integrations
API (cURL)
Python
JavaScript
No-code: Make, Zapier and n8n via the Apify integrations; Google Sheets, Slack and email via webhooks on run success. Schedules: add a daily schedule to a saved task with onlyNewJobs: true for a new-jobs feed.
New to Apify? Create a free account and run this Actor in under a minute. Some links are affiliate links.
Related actors
More tools from the same publisher that fit this workflow:
- LinkedIn Public Jobs Scraper: public LinkedIn job listings with salary and level
- Greenhouse & Lever Jobs Scraper: open roles from Greenhouse, Lever and other career sites
- Company Enrichment by Domain: enrich a domain with socials, emails and tech stack
- Website Email Extractor: pull emails, phones and socials from each business website
- Website Tech Stack Detector: detect the CMS, frameworks and hosting behind any site
- Local Business Leads: find local businesses with no website from OpenStreetMap, a cheap complement to Maps data
Use from AI agents: every actor here is callable through the Apify MCP server (mcp.apify.com) and our open-data-actors MCP endpoint.
FAQ
Is it legal to scrape Workday career sites? The Actor reads only public job postings that each employer publishes for anyone to see, through the same public endpoints the careers page uses. No login, no captcha bypass, no personal data. You are responsible for how you use the data; check your local rules and the site terms for your use case.
My company is not in the directory. Can I still scrape it? Yes. Open its careers page, copy the myworkdayjobs.com URL and put it in careerSiteUrls. Any Workday career site works.
How do I find a company's Workday URL? Click "Careers" / "Search jobs" on the company website; if the address contains myworkdayjobs.com, that is it. Unknown company names are listed in the run log.
Why is a run limited to 2,000 jobs per site? Workday itself does not page beyond 2,000 results per search. Use keywords, locations or several searches to cover very large employers.
How accurate is postedOn? With descriptions on, it is the exact posting start date from Workday. Without, it is computed from "Posted N Days Ago" (flagged with postedOnIsEstimate: true); "30+ Days Ago" is a lower bound (postedDaysAgo: 30).
Do I always get a salary? Only when the employer states a pay range in the posting (common for US roles in states with pay transparency laws). It needs includeDescription: true.
How does only-new mode work? Job IDs you received are stored in a named key-value store (deltaStoreName). The next run skips them and does not charge for them. Use a different store name per watch list.
Does it use proxies? No. Requests are light, sequential per site, with pauses and back-off on rate limits.
More questions
How do I scrape jobs from a myworkdayjobs.com site?
Paste the career site URL into careerSiteUrls, or pick employers by name in companies.
Which companies are built in? 165+ verified large employers; any other Workday career site works through its URL.
Is there a limit per search?
Workday returns at most 2,000 jobs per search, so split very large employers by searchText or locations.
Can I get the full job description?
Yes, with includeDescription (priced separately, see Pricing).
Is the posted date exact?
Workday shows relative dates like "30+ days ago", so some dates are estimates; those rows are flagged with postedOnIsEstimate.
How this compares
Workday career sites are public, but each one needs its tenant and site name. This actor handles that and returns one schema, with an only-new mode. Large job-data vendors may cover more ATS and keep history; this actor reads live Workday sites.
Limits
- Public Workday career sites only; internal or login-only sites are not reachable.
- Max 2,000 jobs per site per search (Workday's own cap); max 2,000 saved per company per run.
- Location filtering is text-based on Workday's location labels. Filters that need the job description or arrangement fetch each job's detail page, so those runs are slower (price is unchanged).
- Run with no input: the Actor scrapes a small built-in example (NVIDIA, "engineer", 5 jobs) instead of failing.
- Salary is parsed only from text the employer wrote; formats vary.
- The bundled directory was verified live on 2026-10-07; employers occasionally move career sites. If one fails, the run log says so and the other sites continue.
Reliability
Last 30 days, measured from Apify run records (all runs, including our own daily health checks): 32 of 32 finished runs succeeded (100.0%), median run time 6.5 s (90th percentile 8.0 s). Aborted runs (0) are not counted.
Updated 2026-10-11 automatically every week from the run history. Report any failure on the Issues tab with the run URL.
More resources
- Guide & examples: mamoo85.github.io/open-data-actors/workday-jobs-scraper.html
- Sample output and example input on GitHub (masked sample CSV): github.com/Mamoo85/apify-actor-samples/workday-jobs-scraper
- Video walkthrough: Watch the 1-minute demo on YouTube
Changelog
- 2026-10-07: Launched: any Workday career site plus a built-in employer directory.
- 2026-10-09: Multi-location jobs now list their locations; employer count updated to 165+; Output tab table view.
- 2026-10-09: Input sections, status messages, examples.
- 2026-10-09: Branding: maintained by Detroit Web Agent - Open Data.
- 2026-10-13: Added a Run in 30 seconds section with a one-click prefilled run link, saved use-case presets and Store title and search description reworded around how buyers search.
- 2026-10-13: v0.2: 8 new filters (description, title and location exclusion, posted-after, remote/hybrid/on-site, has-salary, domain), derived employment type / experience level / cities / regions / countries / annualized salary / logo, empty-input run now returns a working example.
Support
Found a company that does not work, or want a field added? Open an issue on the Actor's Issues tab and include the career site URL. Fixes for broken sites are usually same-day.
Works well with
Other actors from Detroit Web Agent - Open Data that pair with this one:
- Career Site Jobs API (Greenhouse, Lever, Ashby and more): covers Greenhouse, Lever, Ashby and other ATS that Workday does not.
- WARN Layoff Notices: layoff notices for the same employers.
- Company News Monitor: news alongside hiring activity.
- LinkedIn Public Jobs: public LinkedIn job posts next to company career-site roles.
What the free plan gets you
Free plan: about 5,000 job listings from your $5 monthly Apify credit (at $0.001 each, today's price); default settings return about 5 rows. Listings with full descriptions are $0.002 each. Need more? Upgrade your Apify plan or set a higher result limit in the input.
Need more than the data?
This actor is built by Detroit Web Agent, a small Detroit studio that builds websites, lead pages and simple data tools for small businesses. If you want these results turned into a working website, a landing page or a CRM import, or you need a field this actor does not cover yet, open an issue on the Issues tab or visit detroitwebagent.com.
Built and maintained by Detroit Web Agent - Open Data (Detroit, Michigan). Questions, bugs or a field you need: open an issue on this Actor's Issues tab and we will reply there.


