
Career Page Scraper — Company Jobs by Domain, 9 ATS Boards
Pricing
from $0.80 / 1,000 jobs
Career Page Scraper — Company Jobs by Domain, 9 ATS Boards
Career page jobs: paste a company domain and get every live opening from its Greenhouse, Lever, Ashby, Workday or other ATS board — nine platforms, one box, no board tokens needed. From $0.80 per 1,000 jobs. Never pay for a domain we couldn't resolve.
Pricing
from $0.80 / 1,000 jobs
Rating
0.0
(0)
Developer
Steadyfetch Team
Maintained by CommunityActor stats
0
Bookmarked
3
Total users
2
Monthly active users
2 hours ago
Last modified
Categories
Share
A career page scraper that takes a domain, not a board token — from $0.80 per 1,000 jobs. Paste a company domain and we find its Greenhouse, Lever, Ashby or Workday board and return every live opening from that company's own career page. Thirteen ATS platforms, one box.
Never pay for a domain we couldn't resolve.
Using an AI agent? Pin this actor in Apify's MCP server with one link: https://mcp.apify.com?tools=steadyfetch/company-jobs-by-domain
- Actor id:
steadyfetch/company-jobs-by-domain - Input:
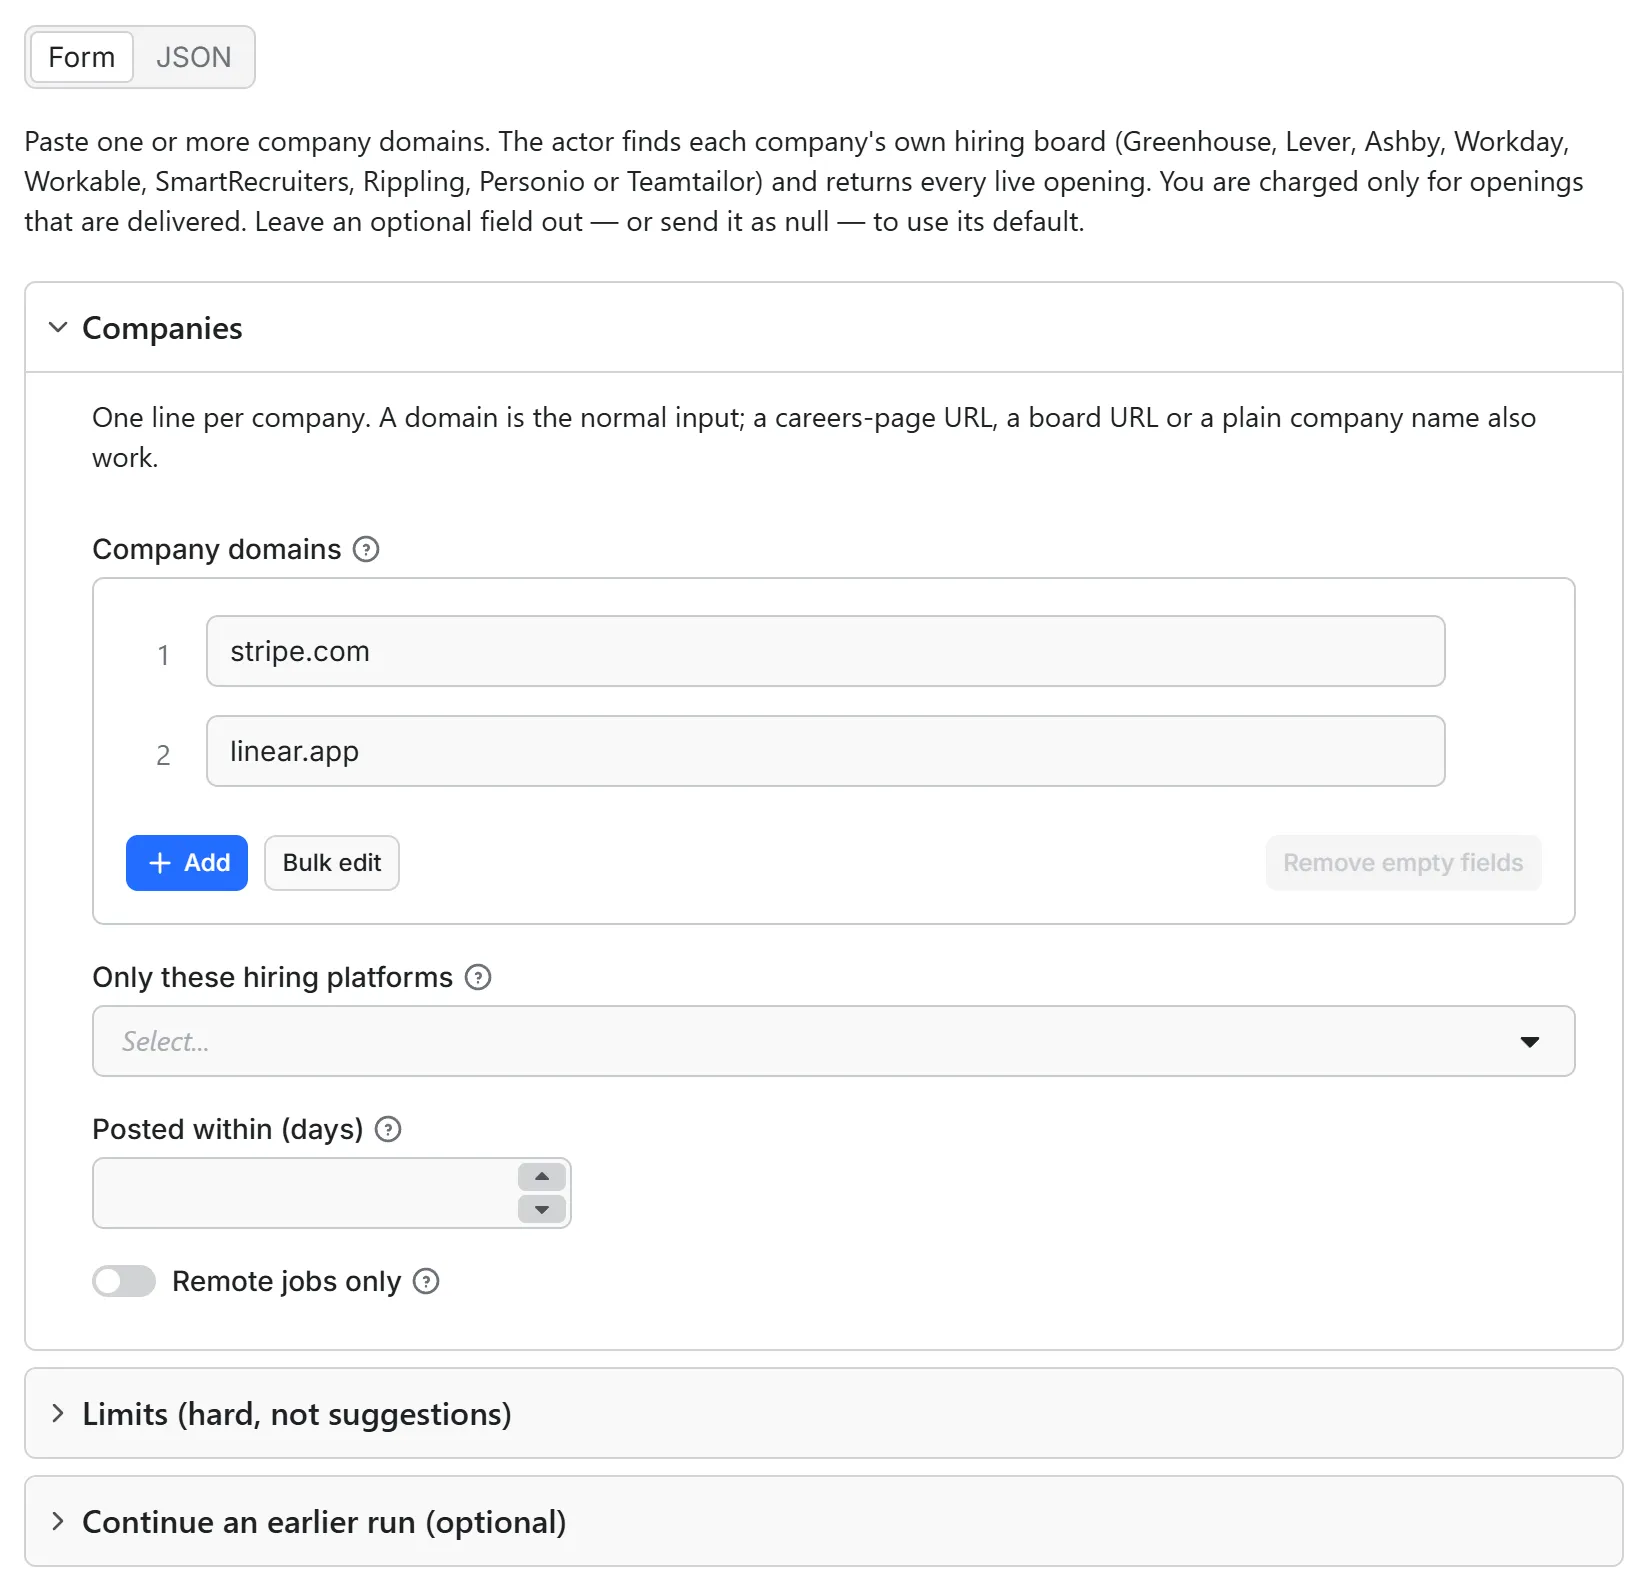
{ "domains": ["stripe.com"] }— the one field you have to set. - Cap the bill: set
maxTotalChargeUsdon the run (a run option, not Actor input), e.g.0.50— the run stops when it reaches it.
From $0.80 per 1,000 jobs — all-inclusive pay per event, nothing charged for starting a run, charged only on delivery.
Running the same domains again? An opening already delivered to your account is never charged a second time — see Never pay for the same opening twice (a run started with a scoped API token needs key-value store permission for that check to work).
Just want to see it work? Run it with no input at all ({} from the API or an AI agent) and
you get a real 5-opening sample — vercel.com's own hiring board — charged like any run, at most
$0.02 on the Apify free plan and less on paid plans. Set only the filters — a posted-within window, remote-only, a row cap — and no companies,
and that same sample runs under them, charged like any run; a limit larger than the sample's own
is capped at it. In the console, Start with the example domains already in the form and you get
those companies for real, up to your row caps.
Every row carries charged and missReason, so you can reconcile the invoice from the
dataset itself without opening the console. Only rows with charged: true were billed.
Output — a real row
Five live openings from a real run, in the Apify console's dataset table — the company's own board, the department, the posted date and both the job and apply links, one row per opening:
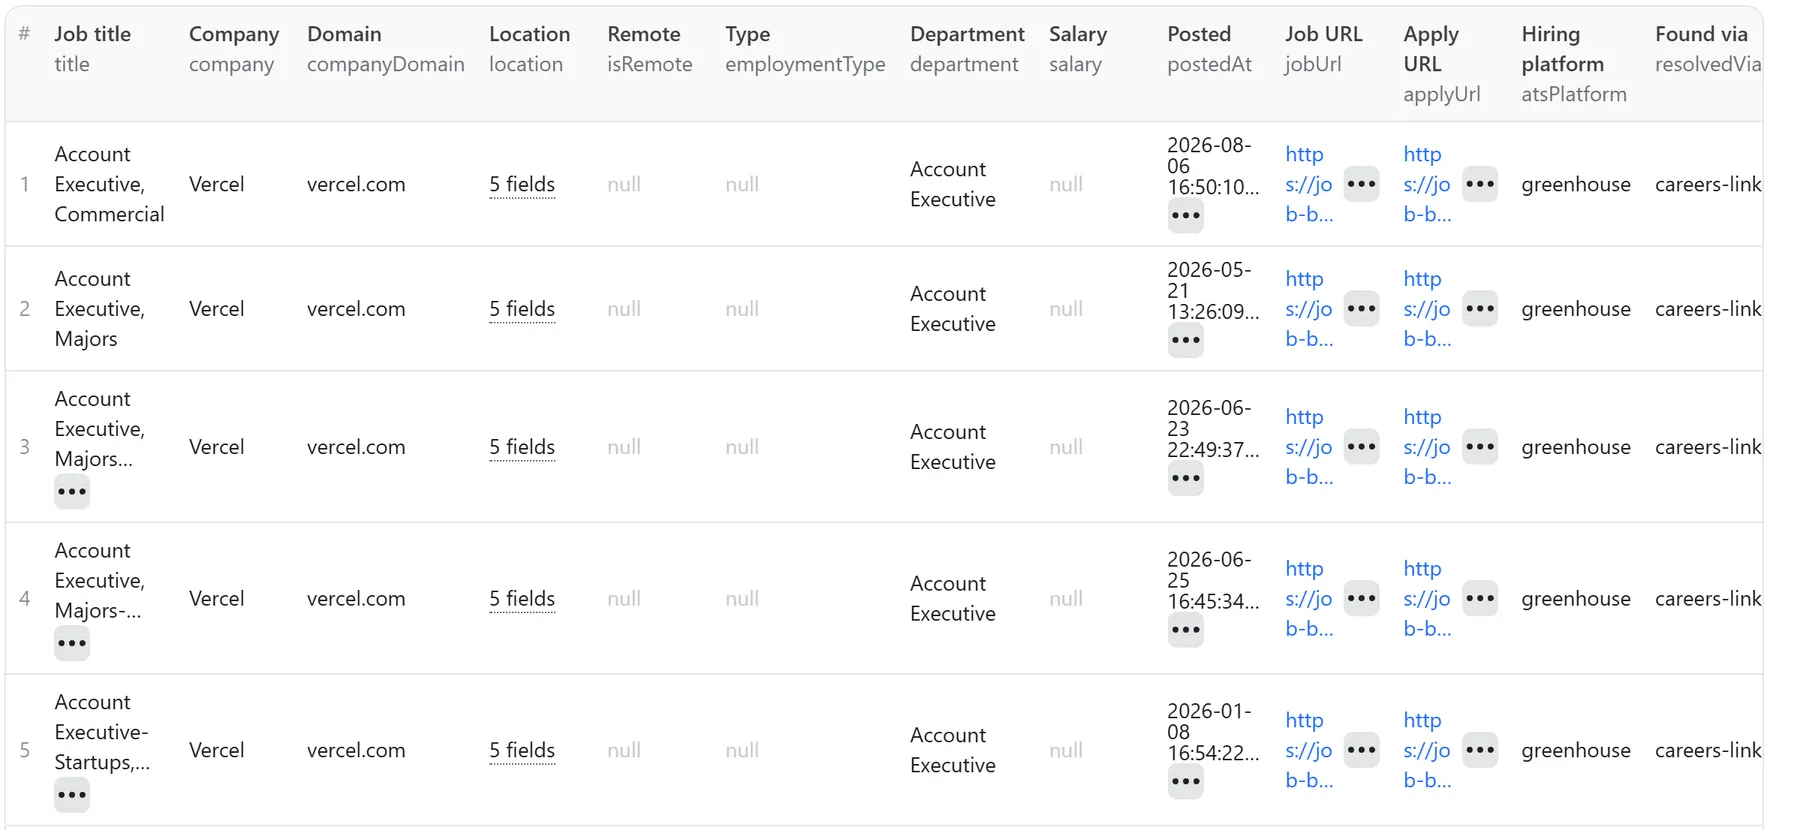
And one delivered row in full:
Plus one company row per domain — domain, companyName, atsPlatform, boardUrl,
openRoleCount, sharedRoleCount (openings already delivered — and charged once — under
another company in the same run), totalOpenRoles, resolved, resolvedVia — and one summary row
with delivered, stoppedBy, resumeCursor, datasetId (paste it into resumeFromDatasetId to
continue this run later), carriedOver and chargedEvents.
See a whole run's output before you spend anything:
real dataset from a verified run
— six live openings from vercel.com and linear.app, their two company rows, and the run
summary, exactly as this actor returned them.
| field | notes |
|---|---|
title · company · companyDomain | company is filled when the board publishes it |
location{raw,city,region,postcode,country} · isRemote | as the board states it — country is an ISO-2 or null, never a state or a postcode |
employmentType · department | |
salary{min,max,currency,period,isEstimate} | null unless the company published a range |
postedAt · updatedAt · scrapedAt | ISO 8601; null when the board only gives relative text |
descriptionText · descriptionHtml | full description where the board's API includes it |
jobUrl · applyUrl | the company's own posting, not a re-hosted copy |
atsPlatform · atsBoardToken · resolvedVia | how we found the board |
charged · missReason · dedupeKey | the reconciliation trio |
Agent / API paste-block
Hiring platforms
Greenhouse · Lever · Ashby · Workday · Workable · SmartRecruiters · Rippling · Personio · Teamtailor · Breezy · BambooHR · ADP WorkforceNow · Phenom People. Each is read from that platform's own public job-board feed, so the data is whatever the company published, unchanged.
On the last two the company's own careers site is the board — there is no separate board address to find — so they are reached from the company's careers page rather than guessed from the domain, as SmartRecruiters, Workday and BambooHR already are.
How a domain becomes a board (resolvedVia tells you which one happened):
resolvedVia | what it means |
|---|---|
board-url | you pasted the board URL — no lookup needed |
careers-link | the company's own careers page links its board |
token-pattern | the domain name matched a board token and that board returned live openings |
name-probe | same, from a company name instead of a domain |
A board found by guessing the token only counts when real openings come back. An empty board reached by guesswork is not a match, so it is never charged.
What you are never charged for
| situation | missReason | run status |
|---|---|---|
| No hiring board found for the domain | UNRESOLVED_DOMAIN | SUCCEEDED — the row lists every platform checked |
| The board rate-limited or dropped us | THROTTLED | SUCCEEDED — re-runnable, and the row says so |
| The board answered with an access challenge | CHALLENGED | SUCCEEDED — re-runnable |
| The board was unavailable this run | SOURCE_UNAVAILABLE | SUCCEEDED — re-runnable |
| The board answered and listed nothing | CLEAN_EMPTY | SUCCEEDED |
| A domain, URL or name we could not read | USER_INPUT | SUCCEEDED — the row names the fix |
| A hiring platform name we do not recognise in "Only these hiring platforms" | USER_INPUT | SUCCEEDED — the row names it; the run stops rather than bill you for every platform |
| The note on a run where you set filters but no companies, so the sample ran under them | SAMPLE_SETTINGS_KEPT | SUCCEEDED — the row names which settings were yours |
| An opening your account already has from an earlier run | — | skipped, never charged twice (the check needs key-value store permission) |
Your own maxItems / maxRunSeconds / cost cap | STOPPED_AT_LIMIT | SUCCEEDED — summary row with resumeCursor and the datasetId to continue from |
The one exception: COMPANY_NO_OPENINGS charges the company-checked event and no
job rows. Confirming a company is not hiring is a real answer, and it is the answer
that costs you the least.
We never guess. A rate limit is reported as a rate limit, not as "this company has no board" — a temporary problem is never dressed up as a permanent verdict.
This actor may fail when a hiring platform changes things. The two you are most likely
to see are UNRESOLVED_DOMAIN (we checked every platform and found no board) and
THROTTLED (a board rate-limited us). Both ship as a row with charged: false, the
run still SUCCEEDS, and the row says whether re-running can help.
Never pay for the same opening twice
Every run remembers the openings it delivered for your account, in a key-value store called
company-jobs-watch-account in your own Apify account. Run the same domains again and what you
already have is skipped before it takes a row slot: no row, no charge, and no bite out of your
row cap. The status line says how many (18 already in your account, skipped, not charged) and
OUTPUT.skippedSeen holds the number; each company's own row says how many of its openings you
already had.
The memory is a key-value store in your own Apify account, so a run started with a scoped API token in restricted-access mode needs key-value store Read, Write and Create permission (or Actor runs set to Full access) under Settings → API & Integrations; without it the run says so on its status line and on an uncharged row at the top of your dataset, and cannot skip what you already have (Write is what lets the run remember what it delivered; without it every run pays again).
The company answer is different on purpose: "this board has N live openings today" is a fresh fact about that company right now, so it is delivered and charged on every run — that is what you are asking for when you re-run a domain.
Want one complete dataset per run instead of only what changed? Turn on Include openings you
already have (includeSeen: true) and those rows come back anyway — marked repeat: true with
firstSeenAt and firstSeenRunId naming the run that first delivered them, charged: false.
- The store lives in your account, one record (
SEEN). Open it in Storage → Key-value stores to see everything the actor has delivered you, or delete the record to start over. This actor runs with limited permissions and touches nothing else in your account. A run started with an API token whose permissions are limited to this Actor's scope can only open it if that token has key-value store Read, Write and Create — the store is created on your first run, so Create matters too. - Entries older than 90 days count as new again, so an opening you collected last quarter is collected (and charged) again if it is still live.
- Only delivered rows are remembered. An unresolved domain, a throttled board or a board that listed nothing leaves nothing behind, so the next run tries it again.
- If the store cannot be read on some run, the run still runs: it delivers and charges as usual and the status line says the repeat check was unavailable, so you know a repeat may have been charged that once.
Filters you can set, and what they cost you
Only these hiring platforms is a hard filter on where we look. The console's dropdown and
Apify's own input check refuse a name we do not know before a run starts; if one ever reaches the
actor another way, the run ships one uncharged row naming it and stops — it is never quietly
ignored, because that would read as "check all of them" and bill you for exactly the boards you
asked to leave out. A single name works as well as a list ("greenhouse" or ["greenhouse"]),
and capitalisation does not matter.
keywords, location, remoteOnly and postedWithinDays narrow what is delivered,
and an opening they leave out is never charged.
keywords matches the job title — any one of the words is enough. location matches
the place the board published, and it takes one place, not a list ("New York, NY" is
one location with a comma in it). Both match whole words and the start of a word, never
a bare substring: "engineer" keeps "Engineering Manager", "new york" keeps "New York, NY",
and "ny" keeps "NY" but not "Sunnyvale" — a substring match would keep the wrong openings
and you would pay for them. Accents fold, so "Munchen" finds "München". Ask for more than
25 keywords and the run continues at 25 with one uncharged row saying so.
All four lean on what each board actually publishes: Greenhouse and Workday publish no
remote flag at all, a few boards publish no posting date, and a few publish no location. An
opening we cannot check against your filter is left out too — and the company's own row
says how many and which field the board did not publish, so a filter can never read as
"this company has no openings". A board emptied by your filters keeps missReason: null
for exactly that reason.
Limits are hard limits
maxItems, maxItemsPerCompany and maxRunSeconds stop the run exactly where you set
them. Ask for more than this actor can do and the run still starts. One run delivers
up to 100,000 jobs, up to 5,000 of them from any one company, inside 30 to 3,600 seconds,
and reads posting dates up to 30 days back. A larger (or smaller) number is not an error:
the run continues at the nearest limit and writes one extra uncharged row saying what you
asked for and what bound it — you are never left with no run at all. The run still finishes successfully, the summary row names which limit bound,
and resumeCursor lists the companies that were not reached. A time limit ends the
collecting, never the delivering: a board already fetched when the clock runs out is
still delivered in full, so a run never pays for openings it does not hand you. To collect the rest without paying again for what you already have, re-run the same input
with a higher cap and resumeFromDatasetId set to that run's dataset ID (it is on the
summary row as datasetId): every opening already in that dataset is skipped — never
fetched, never charged — and the new summary's carriedOver says how many. A dataset ID
that cannot be read stops the run before it fetches anything, uncharged.
And they hold across a restart. If the platform moves your run to another server mid-way — or you resurrect it yourself — the run reads back what it already delivered and picks up from there: no duplicate rows, no second charge for an opening you already have, and your row cap still means what it says. Resurrecting a run that already finished costs nothing and returns the same dataset.
FAQ
The company isn't on any ATS — what now?
The company row lists every platform that was checked. If you know the board URL, paste it
directly (https://jobs.lever.co/acme) and we skip the lookup entirely.
Can I search jobs across boards instead of by company? Not with this actor — it answers "is this company hiring, and for what". A job board URL (LinkedIn, Indeed, Glassdoor) is rejected with a guidance row rather than treated as an employer.
How do I chain this after a company-list scraper?
Feed the domains array from any actor that outputs company domains. Same-company
duplicates across input shapes are delivered once and charged once — the later
company's row reports them in sharedRoleCount instead of claiming them again.
Why is company sometimes empty?
Several board APIs do not publish the employer name in their listing payload. We leave the
field null rather than invent one; companyDomain and the company row always identify it.
Does {} cost anything?
Yes — like any run, and at most $0.02 on the Apify free plan (less on paid plans). With no
input at all it reads one real hiring board
(vercel.com's) and returns up to 5 openings, and you pay for the openings it delivers. If that
board cannot be reached at that moment you get one uncharged company row saying so, never an
empty result.
Run it from an AI agent (MCP)
Works out of the box from any MCP client (Claude, Cursor, …) via Apify's MCP server — ask for "every open role on stripe.com's careers page" and point it at this actor.
The one-link pin is at the top of this page.
Steadyfetch jobs suite
One actor per source, one job each, the same row shape — so a pipeline built on one source takes the next without a rewrite. All-inclusive pay per event, nothing charged for starting a run, charged only on delivery. Google Jobs adds one search fee of $0.004 per search that returns listings; a search that returns nothing pays nothing.
| Source | Actor |
|---|---|
| Indeed | Indeed Jobs Scraper — Indeed API Alternative, Salary, Vacancies |
| A company's own career site (paste a domain) | this actor |
| Glassdoor, with the employer rating | Glassdoor Jobs Scraper — Glassdoor API Alternative + Ratings |
| Several boards at once, de-duplicated | Multi Job Board Scraper — Career Pages, Listings Aggregator |
| Google Jobs, with the full panel and apply links | Google Jobs Scraper — Google for Jobs Listings, Apply Links |
The rest of the steadyfetch shelf — same contract everywhere: all-inclusive pay per event, nothing charged for starting a run, charged only on delivery (three actors add a small delivery-conditional fee: keyword volume's fresh lookup, profile posts' profile lookup, Google Jobs' search fee — each README states it).
| Family | Actors |
|---|---|
| Ad creative intelligence | Facebook · Google Ads video · TikTok · LinkedIn · Google Ads text & OCR |
| Trends & keywords | Google Trends · Trends Now · Breakout keywords · Autocomplete keywords · Keyword volume & CPC · Social trends |
| YouTube transcripts | YouTube videos · YouTube channels |
| Reel transcripts · Profile posts | |
| Jobs | Indeed · Career sites by domain · Glassdoor · Multi-board · Google Jobs |
| Amazon | Products · Search · Bestsellers · Sellers |
| Any media file | Speech to Text · any link or file |
Feedback & support
Found an issue? Open it on the Issues tab — we usually reply within a couple of hours, always within a day. Feature requests welcome.
If it earned its keep, a rating helps other buyers find it, and saving the actor keeps it one click away.


