
Facebook Ad Library Scraper | Exact Limits, $0.70/1K
Pricing
from $0.60 / 1,000 ad results
Facebook Ad Library Scraper | Exact Limits, $0.70/1K
Scrape the Facebook Ad Library at $0.70 per 1,000 ads, vs $5.80 for Apify's own Facebook Ads Scraper, with exact limits: ask for 100 ads, pay for at most 100. Search by plain keyword, page ID or URL: ad text, creatives, dates, platforms, new-ads-only mode, optional EU reach and payer data. No login.
Pricing
from $0.60 / 1,000 ad results
Rating
0.0
(0)
Developer
Aurelix
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
15 minutes ago
Last modified
Categories
Share
What is Facebook Ad Library Scraper?
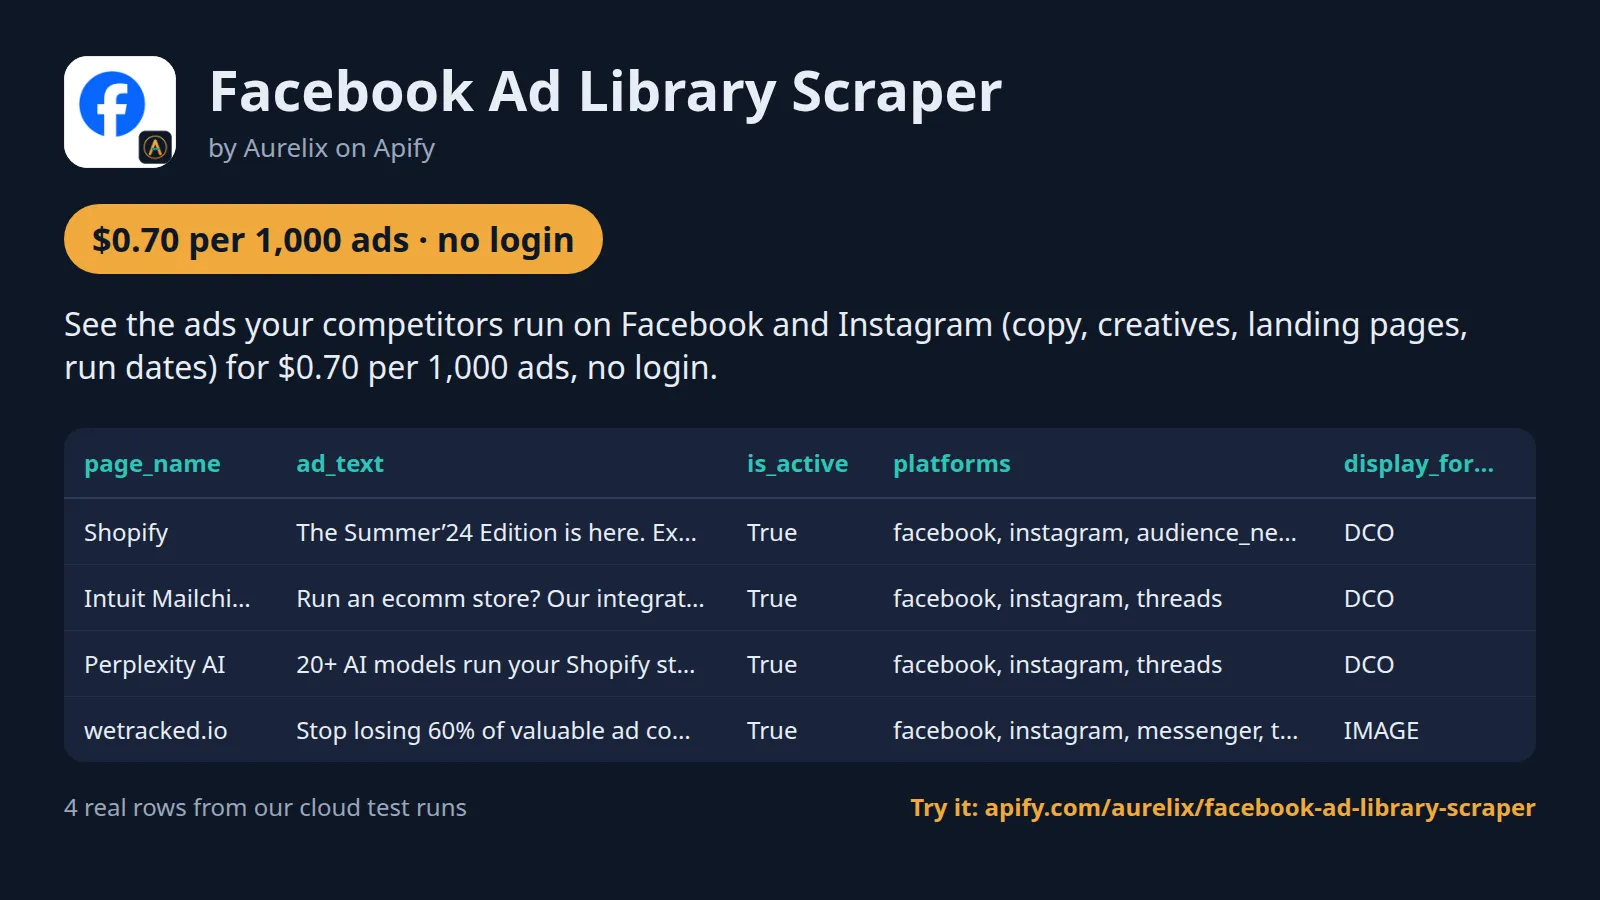
See the ads your competitors run on Facebook and Instagram (copy, creatives, landing pages, run dates) for $0.70 per 1,000 ads, no login.
For marketers, agencies and founders tracking rivals. Search by keyword, page ID or a pasted Ad Library URL; political, issue and personal-page ads are dropped before charging. Your first run with the example input costs about $0.024 (30 ads in our test run).
| Search by | Keyword, Facebook page ID or Ad Library URL |
| Filters | Country, active/inactive status, media type, exact max ads per query |
| Output | 33 fields per ad, 41 with EU transparency; JSON, CSV, Excel, API |
| Automate | Schedules, Slack or webhook digest, Zapier, Make, n8n, Google Sheets, MCP for AI agents |
| Price | $0.70 per 1,000 ads ($0.60 per 1,000 ads on paid Apify plans) |
| Login needed | No |
Why Facebook Ad Library Scraper users pick this one
- About 8x cheaper than Apify's own. $0.70 per 1,000 ads against $5.80 for Apify's Facebook Ads Scraper.
- Exact limits. Ask for 100 ads, get and pay for at most 100.
- New-ads alerts. Only ads you haven't seen, with an optional Slack or webhook digest.
- Optional EU transparency data. EU reach, age and gender breakdown, payer and beneficiary: $0.20 per 1,000 extra.
Get started in 3 steps
- Put search terms (e.g. 'meal kit'), Facebook page ids or Ad Library URLs into Queries.
- Optionally pick a country, active/inactive status, media type and the exact number of ads per query; turn on 'Only new ads since last run' for a feed.
- Click Start, then download JSON, CSV or Excel, or schedule it and send results to Google Sheets, Zapier, Make or n8n.
▶ Try it with the example input
The form opens with an example input already filled in: that run costs about $0.024 on the free plan.
How much does it cost to scrape Facebook Ad Library?
Pay per event: you pay only for what the run returns, plus a small start fee. Bronze, Silver, Gold and higher Apify plans pay less per result.
| Ads | Free plan | Paid plans (Bronze, Silver, Gold) |
|---|---|---|
| 100 | $0.073 | $0.063 |
| 1,000 | $0.70 | $0.60 |
| 10,000 | $7.00 | $6.00 |
Totals include the $0.003 start fee per run, rounded to the cent. Apify's free plan includes $5 of credit a month, enough for about 7,100 ads.
Proxy cost (datacenter first, residential when Meta rate-limits) is included. Paid Apify plans pay $0.60 per 1,000 ads. EU transparency data is optional and costs $0.20 per 1,000 ads that get it; ads without EU data are not charged for it. Excluded political and personal-page ads and duplicates are never charged.
Billing events
| Event | Free plan | Paid plans (Bronze, Silver, Gold) |
|---|---|---|
ad-result | $0.70 per 1,000 ads | $0.60 per 1,000 ads |
eu-details | $0.20 per 1,000 ads with EU data | $0.20 per 1,000 ads with EU data |
apify-actor-start | $0.003 per run | $0.003 per run |
Facebook Ad Library Scraper vs alternatives
| This Actor | apify/facebook-ads-scraper | curious_coder/facebook-ads-library-scraper | |
|---|---|---|---|
| Price per 1,000 ads, free plan | $0.70 | $5.80 | $0.75 |
| Price per 1,000 ads, paid plans | $0.60 | $5.00 | $0.75 |
| Start fee per run | $0.003 at 256 MB | None | $0.00005 at 512 MB |
| Platform usage billed on top | No | No | No |
| Exact cap on ads (pay for at most N) | ✓ | not stated | ✗ (may exceed by up to 30) |
| Plain keywords as input | ✓ | ✗ (URLs) | ✗ (URLs) |
| EU reach, age/gender/country breakdown, payer | ✓ (optional, +$0.20 per 1,000) | ✓ (optional) | EU reach (optional) |
| Only new ads since last run | ✓ | ✗ (date filter) | ✗ (date period) |
| Slack or webhook digest after each run | ✓ | ✗ | ✗ |
Prices checked regularly on each Actor's Store page.
Benchmarks: how we compare
| Test | What we ran | Result |
|---|---|---|
| Keyword searches | 5 searches of 150 ads each (US, US, GB, all countries, CA) | 750 of 750 ads; 5 of 5 searches complete; 6 Meta rate limits, all recovered |
| Field fill rate | 620 ads from 2 runs (US and all countries) | ad text 95%, landing page 96%, image or video link 100% |
| Political and personal-page filter | 10 runs, 1,779 ads seen | 179 dropped (about 10%), 1,600 kept; dropped ads not charged |
| New-ads mode | Same search run twice with 'Only new ads since last run', 40 ads each | 0 of 40 ads repeated in the second run |
| Speed, keyword | 2 queries, 150 ads | 49 s |
| Speed, page id | 1 advertiser page, 60 ads | 31 s |
| Speed under rate limits | 2 queries, 400 ads | about 6 minutes, most of it waiting out Meta rate limits |
| Timeout safety | Run timeout cut to 90 s | Ended SUCCEEDED with 213 ads and a PARTIAL status message |
| EU transparency | shoes (FR), 40 ads; running shoes (DE), 150 ads | 37 of 40 and 150 of 150 ads got EU data; 9 s and 48 s |
| EU transparency, cloud | shopify (FR), 30 ads | 30 of 30 ads got EU data |
| Charges | Runs in GB, CA and FR on the current build | Ads charged equal ads returned on every run |
| First run | Prefilled input, 30 ads | 30 ads for $0.024 |
Measured on Apify at 256 MB memory, except the first EU row (two local, logged-out test runs). Samples are small (1 to 5 searches per test), so times are examples, not guarantees: they depend mostly on how often Meta rate-limits the run. Fill rates and exclusion counts come from the build of that time.
What data you get
Facebook Ad Library Scraper turns ads in the public Meta Ad Library into clean rows: advertiser page, ad text, headline, landing page, button, image and video links, carousel cards, start and stop dates, platforms and active status. Search by keyword, Facebook page ID or an Ad Library URL copied from your browser, and filter by country, active status and media type. Turn on 'Add EU transparency data' to also get EU reach, the reach breakdown by country, age and gender, the targeting and the payer and beneficiary for ads delivered in the EU. Political and issue ads and ads from personal pages are dropped before you pay, and the per-query limit is exact.
- Advertiser page name, id, link, categories and like count
- Ad id and public Ad Library link
- Ad text, headline, link description, display link, button text and type, landing page URL
- Image and video creative links, carousel/dynamic cards
- Start and stop dates in ISO 8601 UTC, active flag
- Platforms (Facebook, Instagram, Messenger, Audience Network, Threads)
- Spend range and impressions where Meta publishes them
- Number of near-identical versions Meta groups with the ad
- Optional EU transparency: EU reach, reach by country/age/gender, targeted locations/gender/ages, payer and beneficiary
| page_name | ad_text | is_active | start_date | platforms | display_format | link_url |
|---|---|---|---|---|---|---|
| Shopify | The Summer’24 Edition is here. Explore 150+ new product u... | True | 2024-06-24T07:00:00Z | ["facebook", "instagram", "audience_network", "messenger"] | DCO | http://shopify.com/editions/summer2024?utm_source=meta&ut... |
| Intuit Mailchimp | Run an ecomm store? Our integrations help automate emails... | True | 2026-08-18T07:00:00Z | ["facebook", "instagram", "threads"] | DCO | https://mailchimp.com/landers/omnichannel-marketing-platf... |
| Perplexity AI | 20+ AI models run your Shopify store. Every e-commerce co... | True | 2026-09-18T07:00:00Z | ["facebook", "instagram", "threads"] | DCO | https://perplexity.sng.link/A6awk/lplb?_smtype=3&_android... |
| wetracked.io | Stop losing 60% of valuable ad conversion data due to poo... | True | 2026-09-08T07:00:00Z | ["facebook", "instagram", "messenger", "threads"] | IMAGE | https://www.wetracked.io/reviews/ |
One full ad record, exactly as a real run returned it (long text and lists shortened here). From a real run:
Use cases
- Marketers and agencies studying competitors' ad copy and creatives
- E-commerce brands tracking which products rivals advertise, with the new-ads feed
- Copywriters collecting ad examples by keyword and country
- Sales teams finding businesses that are actively advertising
Use-case recipes
Weekly new-ads alert on a market
For brands and agencies watching what rivals launch. Put the market's keywords in queries, set the country, turn on 'Only new ads since last run' and schedule the task weekly. Each run returns only ads it has not returned before; add a Slack or webhook URL to get the top 10 with links. Sort the rows by start_date and open ad_library_url to see each creative.
Ad copy swipe file for a niche
For copywriters and media buyers collecting examples. Search a niche keyword, pick a country and a media type, and keep the limit small. Use ad_text, title and cta_text for the copy, video_urls or image_urls for the creative, and variants_count to spot ads the advertiser runs in many versions.
EU reach and audience check
For marketers sizing competitor campaigns in Europe. Pick an EU country and turn on 'Add EU transparency data'. Compare eu_total_reach across ads, read eu_reach_breakdown for the country, age and gender split, and eu_target_age_min/max and eu_target_locations for the targeting. eu_payer_beneficiary shows which business paid.
Find businesses that are advertising now
For agencies and B2B sales teams looking for companies with an ad budget. Search a trade keyword with active ads only. Group rows by page_id, count ads per page and use page_url and the domain of link_url to research the business. Personal pages are already dropped, so the list is businesses.
Input
| Field | Type | What it does | Default |
|---|---|---|---|
queries (Search terms, page ids or Ad Library URLs) | array | Each entry is one of: a keyword (e.g. 'shopify', 'meal kit'); a Facebook page id (e.g. '20409006880' or 'page:20409006880') to... | |
maxResultsPerQuery (Max ads per query) | integer | Exact upper limit of ads returned for each query (after political/individual ads are excluded). | 100 |
proxyConfiguration (Proxy) | object | Proxy used to reach the Ad Library. | {"useApifyProxy": true} |
country (Country) | string | Two-letter ISO code of the country where the ads ran, e.g. 'US', 'CA', 'GB', or 'ALL' for every country. | "ALL" |
activeStatus (Ad status) | string | 'active' = ads running now; 'inactive' = stopped ads; 'all' = both. | "active" |
mediaType (Media type) | string | Keep only ads with this creative type. | "all" |
All 11 fields, with examples: see the Input tab.
Switching from apify/facebook-ads-scraper
Already running apify/facebook-ads-scraper? Map its input fields to this Actor's like this:
apify/facebook-ads-scraper input | This Actor's input | Notes |
|---|---|---|
startUrls (Ad Library search URL) | queries | Paste the same URL. Its search term or page id, country, status, media type and search type are used; other URL filters are ignored. |
startUrls (Facebook page URL) | queries with the page id | A facebook.com/brand link is not read as a page. Use the number after view_all_page_id, e.g. 20409006880 or page:20409006880. |
startUrls (keyword inside a URL) | queries | Plain keywords work too, e.g. meal kit. No URL needed. |
resultsLimit | maxResultsPerQuery | Exact cap per query, counted after exclusions and duplicates. Default 100, maximum 10,000; it is never left unlimited. |
activeStatus | activeStatus | Same choices: active, inactive, or both (all). Default active. |
isDetailsPerAd | includeEuTransparency | EU reach, reach by country/age/gender, targeting, payer and beneficiary. No Instagram follower or page About data. |
onlyAdsNewerThan / onlyAdsOlderThan | no equivalent | Use incremental for a feed of ads not seen before, or filter on start_date after the run. |
sorting | no equivalent | Ads come in the Ad Library's own order. |
includeAboutPage | no equivalent | Page name, id, link, categories and like count are on every row. |
onlyTotal | no equivalent | The run returns ads, not counts. |
enrichWithEcommerceData | no equivalent | Each row has link_url, the ad's landing page, to enrich yourself. |
- Price: $0.70 per 1,000 ads on the free plan ($0.60 on paid plans) against $5.80 ($5.00); this Actor adds a $0.003 start fee per run, and EU data is +$0.20 per 1,000 ads that get it.
- Output is one flat row per ad version: ad_id, page_name, ad_text, title, link_url, image_urls, video_urls, cards, start_date, platforms and so on. EU data sits in top-level eu_ fields, not in a nested object.
- Expect fewer rows than the same search on the Ad Library website: political and issue ads and ads from personal pages are dropped before charging.
- Each ad id is returned once per run, even when several queries match it, and a query entered twice runs once.
Use with AI agents (Apify MCP server, Claude, ChatGPT, n8n AI agent)
Facebook Ad Library Scraper is a ready-made tool for AI agents. Through the Apify MCP server an agent reads this Actor's input schema, fills in the input from your request, starts the run and reads the ads back. You pay the same per-result price as a run started by hand, from your own Apify account.
Example prompts
- "Show me 50 active Facebook and Instagram ads for meal kits running in the US, with the ad text, landing page and start date, as a table."
- "Get the active ads of the Facebook page with ID 20409006880 and summarise which offers and calls to action they use most."
- "Find 30 skincare ads delivered in France with their EU reach and age and gender breakdown, and tell me which age group each ad reached most."
Claude (claude.ai and Claude Desktop)
Open Settings > Connectors, choose Add custom connector, paste https://mcp.apify.com/?tools=aurelix/facebook-ad-library-scraper and sign in to Apify when asked. Then ask Claude one of the prompts above.
Claude Code, Cursor, VS Code and other MCP clients
Clients configured with JSON take the same URL:
A client without Apify sign-in sends the header Authorization: Bearer <YOUR_APIFY_TOKEN>; to run the server locally instead, use npx -y @apify/actors-mcp-server --actors aurelix/facebook-ad-library-scraper with APIFY_TOKEN set.
ChatGPT
Where your ChatGPT plan offers custom connectors (developer mode), add https://mcp.apify.com/?tools=aurelix/facebook-ad-library-scraper as a connector, sign in to Apify, and ask for the data in plain words.
n8n AI agent
Give an AI Agent node an MCP Client Tool with the endpoint https://mcp.apify.com/?tools=aurelix/facebook-ad-library-scraper and a Bearer credential holding your Apify token. The agent can then call Facebook Ad Library Scraper whenever a workflow step needs ads; for a fixed, non-agent workflow use Apify's n8n node with Run Actor instead.
Use it from AI agents (MCP), the API or no-code
Copy this to your AI assistant
MCP server URL for this Actor: https://mcp.apify.com/?tools=aurelix/facebook-ad-library-scraper (setup for each client in the section above).
API
Start a run and read the dataset with Apify's REST API or the Python and JavaScript clients:
No-code: schedule it in 3 clicks
Send the results to Google Sheets, Zapier, Make, n8n, Slack or any webhook URL.
- Fill in the input, then click Save as a new task.
- In the task, click Schedule and pick daily or weekly (Apify Schedules).
- Turn on Only new ads since last run so each run returns only what is new, and paste a Slack or webhook URL into Slack webhook URL / Webhook URL to get a digest of the new items (count plus the top 10) after every run.
Prefer n8n or Make? Ask in the Issues tab and we will share a ready-made workflow for it.
FAQ
Can I scrape Facebook Ad Library without login?
No. The Actor reads the public Ad Library pages that anyone can open without logging in. It never logs in and uses no account.
Is there a Facebook Ad Library API?
You can use this Actor as one. Start it with Apify's REST API or the Python and JavaScript clients and read the results as JSON (see the code above), or call it from an AI agent through MCP.
How much does it cost to scrape Facebook Ad Library?
About $0.70 for 1,000 ads on Apify's free plan and $0.60 on paid plans, start fee included. The free $5 monthly credit covers about 7,100 ads.
Can I export Facebook Ad Library data to Excel or Google Sheets?
Yes. Download the results as Excel, CSV, JSON, XML or HTML from the run's Storage tab, or send them to Google Sheets with Apify's Google Sheets integration or the API.
Is it legal to scrape Facebook Ad Library?
It reads only public data any logged-out visitor can see: the Meta Ad Library. It goes at a polite pace, never logs in and never solves CAPTCHAs. It returns ad fields for business advertisers (page, ad text, media links, dates, platforms, status); political ads and personal pages are excluded. To have a record removed, open an issue on this Actor's Issues tab; if Meta formally asks us to stop, this Actor will stop. You are responsible for using the data lawfully, incl. anti-spam and privacy laws; this is not legal advice.
How are political and personal advertisers excluded?
An ad is dropped if Meta labels it political or issue, carries a 'Paid for by' disclaimer, comes from a page whose category is a person (Public figure, Politician, Profile, Digital creator, Entrepreneur, Coach and similar) or has no category at all, or from a page named like a person (a common first name plus surname, e.g. 'Dr. Jane Smith'). Dropped ads are counted in the log and never charged.
Why are spend and impressions empty?
Meta publishes spend and impressions only for political/issue ads and some EU-delivered ads. Political ads are excluded, so these fields are usually empty. For EU reach and audience data, turn on 'Add EU transparency data'.
What EU transparency data do I get?
Turn on 'Add EU transparency data'. For ads delivered in the EU (Meta's 'See ad details' panel), each row gets eu_total_reach, eu_reach_breakdown (country, age range, male, female, unknown), eu_target_locations, eu_target_gender, eu_target_age_min/max and eu_payer_beneficiary. Other ads get empty EU fields and are not charged the $0.20 per 1,000.
Does the limit really hold?
Yes. 'Max ads per query' is an exact cap applied after exclusions and duplicates are removed, and Apify's spending limit is respected too.
What happens if a search finds no ads?
The run still succeeds with 0 ads and a status message such as '0 ads; 1/1 queries complete'. You pay only the start fee, since ads are charged one by one as they are saved. If every query fails (blocked, or no results page) and nothing was saved, the run ends FAILED and names the queries.
Which parts of a pasted Ad Library URL are used?
The search term (q) or the page id (view_all_page_id), plus country, active_status, media_type and search_type, so an exact-phrase search stays exact. These override the Country, Ad status and Media type fields for that URL. Other filters in the URL, such as language, platform or date range, are ignored. A URL with neither a search term nor a page id is skipped with a warning in the log.
How do I get every ad of one advertiser?
Put the advertiser's page id into queries, as digits (e.g. 20409006880) or as page:20409006880, or paste the Ad Library URL of their page view, which contains view_all_page_id. A normal facebook.com/brand link is not recognised as a page and is searched as a keyword. Set Ad status to 'Active and inactive' to include stopped ads.
How does 'Only new ads since last run' work?
The Actor remembers the ad ids it returned, in a store named after your queries, country, status and media type (or after 'Incremental state name' if you set one). Ads returned before are skipped, not charged and not counted against 'Max ads per query'. An ad not seen again for 60 days is forgotten. Changing the queries or filters starts a new feed unless you keep the same state name.
Are duplicates removed?
Yes. Within a run each ad id is returned once, even when several queries match it, and a query entered twice runs once. Meta groups near-identical versions of an ad; each version is its own row, with variants_count and collation_id telling you which belong together.
How long does a run take?
The Actor pauses 1.5 s between result pages of about 30 ads. In our tests 150 ads over two queries took 49 s and 60 ads from one page took 31 s, while 400 ads took about 6 minutes because Meta rate-limited the run. EU transparency data adds about 0.2 s per ad.
Which countries can I search?
Any two-letter country code the Ad Library accepts, e.g. US, GB, CA or FR, or ALL for every country. Each row's search_country records the filter used. reached_countries is filled only where Meta publishes it, and EU transparency data exists only for ads delivered in the EU.
Lawful use
- Business ads only: political, issue and personal-page ads are dropped before charging.
Limits (stated honestly)
- Data comes from the public Ad Library web pages, not Meta's official API (which needs a personally verified developer account). A Meta layout change can break it until fixed; the daily health run catches that within 24 hours.
- Meta rate-limits datacenter addresses quickly, so the Actor starts on datacenter proxy and switches to residential proxy (included in the price) after the first rate limit.
- The personal-page filter is a heuristic on Meta's page categories and page names. A person with an unusual name who files their page under a business category can slip through; a business with no category, or one named exactly like a person (e.g. 'Sarah Jane'), is dropped.
- Meta groups near-identical ad versions; each version is returned as its own row with 'variants_count'.
- Reached-countries, spend and impressions are only filled where Meta publishes them (mostly EU and political ads).
- Meta rate-limits the Ad Library from time to time. The Actor waits and retries with up to 8 fresh sessions (new IP addresses), backing off up to a minute between tries. If Meta still refuses, that query stops early: the status message names it as PARTIAL ('stopped at N ads (Meta rate limit)') and does not count it as complete; the run still succeeds and you pay only for the ads returned. A query that stops on another error after saving ads is also named as PARTIAL.
- A run that would outlast its timeout stops by itself shortly before it, keeps and charges only the ads already saved, and ends SUCCEEDED with a PARTIAL status message. With the default 1-hour timeout that is several thousand ads; raise the timeout for bigger pulls.
- EU transparency data exists only for ads Meta shows it for (delivered in the EU); it adds about 0.2 s per ad to the run.
Related Aurelix tools
Public Aurelix Actors, grouped by the data they collect. All are pay-per-result and need no login.
Jobs and hiring data
- Greenhouse Jobs Scraper: Live jobs from a company's Greenhouse, Lever, Ashby or SmartRecruiters board, with salary and Canadian province tags.
- LinkedIn Jobs Scraper: Public LinkedIn job postings by keyword and country: title, company, location, seniority, job type, salary text, description.
E-commerce and product data
- AliExpress Scraper: AliExpress search results by keyword: price, discount, rating, units sold, ship-from country and sponsored flag.
- Amazon Best Sellers Scraper: Amazon Best Sellers and New Releases top 100 on 10 marketplaces: rank, ASIN, price, rating, rank change.
Leads and company data
- Google Maps Business Scraper: Local business lists from Google Maps: phones, websites, ratings, hours, coordinates; optional website emails and socials.
- Recently Funded Companies: US companies that just filed an SEC Form D: amount raised, industry, state, executives, confirmed website.
Canada and government data
- Canada Building Permits Scraper: Building permits and development applications from 7 Canadian cities: address, type, status, dates, value, contractor company.
AI, content and SEO
- Google Trends Scraper: Google Trends interest over time, by region and rising queries for any number of keywords, plus trending searches.
- Website to Markdown Crawler: Crawls a site and returns one row of clean main-content Markdown per page, with title, headings and links.
Recent changes
- 0.2: Fixed: a query stopped by Meta rate limits is now named as PARTIAL in the status message instead of counted as complete.
- 0.1: Optional Slack and webhook digest after each run; the prefilled first run is capped at 30 ads.
The full history is on the Changelog tab.
Tested daily
An automated health check runs this Actor every day on a fixed input and checks that at least 15 ads come back with ad_id, page_name, start_date, ad_library_url, source_url, scraped_at filled in; a failed check alerts the maintainer straight away.
Your feedback
Missing a field, found a bug or need another filter? Open an issue on the Issues tab; we aim to answer within a day. If this Actor saved you time, a short review helps other people find it.


