
PDF to Markdown OCR & Table Extraction | API, $0.30/1K
Pricing
from $0.25 / 1,000 page results
PDF to Markdown OCR & Table Extraction | API, $0.30/1K
Extract PDF to Markdown, priced per page: $0.30 per 1,000 pages ($0.003 for a 10-page PDF), cheaper than the most-used per-PDF extractors up to 11 pages, and the only one of them with DOCX, tables as JSON rows and RAG chunks. OCR for scans at $8 per 1,000 pages, about half the leading rate.
Pricing
from $0.25 / 1,000 page results
Rating
0.0
(0)
Developer
Aurelix
Maintained by CommunityActor stats
0
Bookmarked
1
Total users
0
Monthly active users
29 minutes ago
Last modified
Categories
Share
What is PDF to Markdown OCR & Table Extraction?
Convert PDF and DOCX links into clean Markdown, tables as JSON rows and RAG-ready chunks for $0.30 per 1,000 pages, no login, with OCR for scans.
For RAG pipelines and document workflows. Priced per page, so a 10-page PDF costs $0.003; scanned pages are read with OCR automatically at $8 per 1,000 OCR pages. Your first run with the example input costs about $0.005 (15 pages in our test run).
| Input | PDF or DOCX links (up to 50 MB each) |
| Per page | Markdown, tables as JSON rows, text chunks, word count, OCR flag |
| OCR | Tesseract for scanned pages: English, French, Spanish, German |
| Output | 13 fields per page; JSON, CSV, Excel, API |
| Automate | Schedules, webhooks, Zapier, Make, n8n, Google Sheets, MCP for AI agents |
| Price | $0.30 per 1,000 pages ($0.25 per 1,000 pages on paid Apify plans) |
| Login needed | No |
Why PDF to Markdown OCR & Table Extraction users pick this one
- Priced per page. $0.003 for a 10-page PDF, no per-file fee.
- Tables twice. As Markdown in the text and as JSON rows.
- Chunks for vector databases. Page-level chunks with overlap.
- OCR only when needed. Scanned pages are read with OCR; text pages never are.
- Failures are free. Failed downloads, non-documents and empty pages are never charged.
Get started in 3 steps
- Paste one or more PDF or DOCX links, e.g. https://arxiv.org/pdf/1706.03762.
- Optionally limit the pages per document, choose the OCR language for scans and set the chunk size.
- Click Start, then download JSON, CSV or Excel, or send the pages to your vector database, LangChain, LlamaIndex, Zapier, Make or n8n through the API.
▶ Try it with the example input
The form opens with an example input already filled in: that run costs about $0.005 on the free plan.
How much does it cost to convert PDF to Markdown?
Pay per event: you pay only for what the run returns, plus a small start fee. Bronze, Silver, Gold and higher Apify plans pay less per result.
| Pages | Free plan | Paid plans (Bronze, Silver, Gold) |
|---|---|---|
| 100 | $0.031 | $0.026 |
| 1,000 | $0.30 | $0.25 |
| 10,000 | $3.00 | $2.50 |
Totals include the $0.001 start fee per run, rounded to the cent (amounts under $0.10 to four decimals). Apify's free plan includes $5 of credit a month, enough for about 16,000 pages.
OCR pages are charged as ocr-page-result instead of page-result, never both. Not charged: URLs that fail to download, are blocked by robots.txt or are not a PDF or DOCX, and pages with no text even after OCR.
Billing events
| Event | Free plan | Paid plans (Bronze, Silver, Gold) |
|---|---|---|
page-result | $0.30 per 1,000 pages | $0.25 per 1,000 pages |
ocr-page-result | $8.00 per 1,000 OCR pages | $5.60 per 1,000 OCR pages |
apify-actor-start | $0.001 per run | $0.001 per run |
PDF to Markdown OCR & Table Extraction vs alternatives
| This Actor | memo23/pdf-text-extractor | automation-lab/pdf-text-extractor | |
|---|---|---|---|
| Price per 1,000, free plan | $0.30 per 1,000 pages | $5 per 1,000 PDFs | $3.45 per 1,000 PDFs |
| Price per 1,000, paid plans | $0.25 per 1,000 pages | $5 per 1,000 PDFs | $3.00 per 1,000 PDFs |
| Start fee per run | $0.001 | $0.005 | $0.005 |
| Platform usage billed on top | No | No ($7 per 1,000 proxy MB if used) | No |
| A 10-page PDF, free plan | $0.003 | $0.005 | $0.00345 |
| OCR for scanned pages | ✓ $8 per 1,000 pages, automatic | ✓ $15 per 1,000 pages, opt-in | ✗ |
| Markdown output | ✓ per page | ✓ | ✗ |
| Tables as JSON rows | ✓ | not stated | not stated |
| RAG chunks | ✓ | not stated | ✗ |
| DOCX (Word) files | ✓ | ✗ | ✗ |
| Uploaded files or base64 | ✗ (URLs) | ✓ | ✗ |
Prices checked regularly on each Actor's Store page.
Benchmarks: how we compare
| Test | Input | Result | Run time |
|---|---|---|---|
| First run (prefilled input) | the arXiv paper 1706.03762, Max pages per document 15 | 15 pages for $0.005 in total | not recorded |
| Mixed batch | an arXiv paper, a 39-page statistics release, a scanned book with a text layer, a DOCX, plus an HTML page and a 404 link | 63 pages; the HTML page and the 404 refused and not charged | 16 s |
| Text accuracy | 114 pages from 4 PDFs, compared page by page with an independent text extraction | 98.2% of words found on average, 99.5% precision; 104 of 114 pages at 99% or more | not timed |
| Hardest pages | the arXiv paper's last 3 pages (figures with rotated labels) | 35% to 49% of words found, because rotated text is skipped | not timed |
| OCR | 2 image-only scanned PDFs | 2 OCR pages, 732 and 728 words | 7.7 s |
| Blank scans | a PDF of 40 blank scanned pages | 0 pages charged; the document stopped after 5 blank pages in a row | 0.46 s per blank page |
| Nothing to convert | a 404 link and an HTML page | 0 pages, only the start fee charged | 1.8 s |
Cloud runs at the default 1,024 MB with no proxy, except the accuracy rows and the blank-scan row, which were local test runs of the same code. Accuracy compares each page's Markdown words with pdftotext's text of the same page (114 pages). The first-run cost includes the $0.001 start fee.
What data you get
PDF to Markdown OCR & Table Extraction downloads the PDF or Word (DOCX) files you link and returns one row per page: the page as Markdown (headings from font sizes, paragraphs, bullet lists, numeric table rows kept one per line, ruled tables as Markdown tables), every table also as JSON rows, the page split into AI-ready chunks for embeddings, the word count and the document title. Pages without a text layer, such as scans, are read with the open-source Tesseract OCR engine in English, French, Spanish or German.
- url, file_name, file_type (pdf or docx), title, page, pages_total
- markdown: the page as Markdown
- tables: [{index, rows}] with each table as rows of cells
- chunks: the page split for embeddings; word_count
- ocr: true when the page was read by OCR; source_url and scraped_at
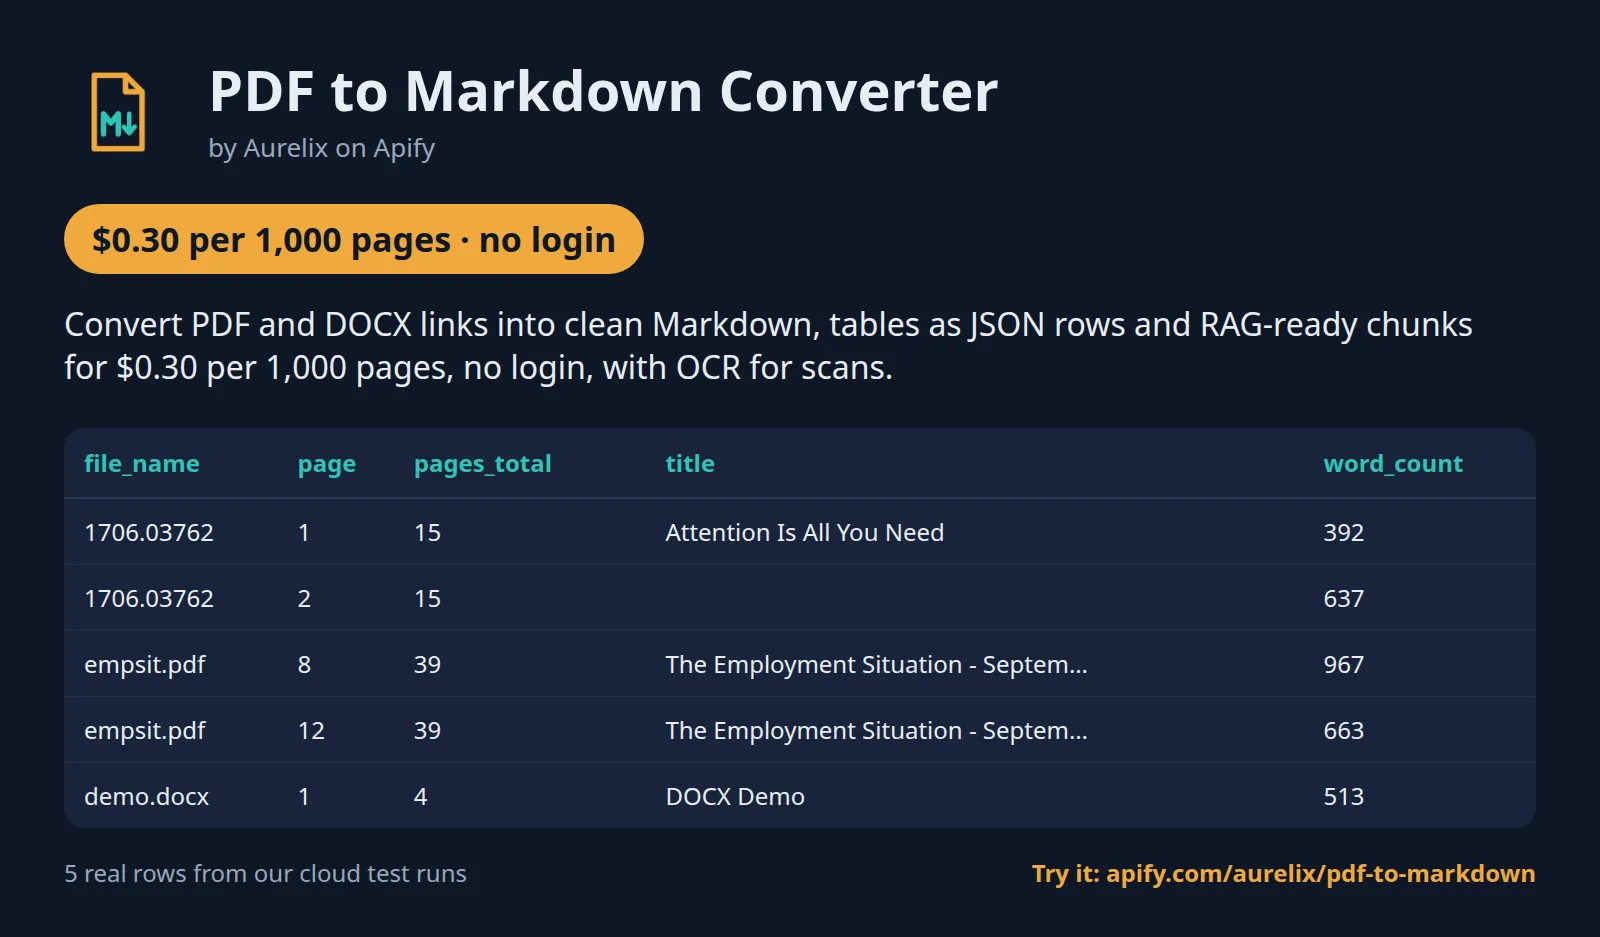
| file_name | page | pages_total | title | word_count | ocr | markdown |
|---|---|---|---|---|---|---|
| 1706.03762 | 1 | 15 | Attention Is All You Need | 392 | False | Provided proper attribution is provided, Google hereby gr... |
| 1706.03762 | 2 | 15 | 637 | False | 1 Introduction Recurrent neural networks, long short-ter... | |
| empsit.pdf | 8 | 39 | The Employment Situation - September 2026 | 967 | False | | Technical Note | | | |---|---|---| | This ne... |
| empsit.pdf | 12 | 39 | The Employment Situation - September 2026 | 663 | False | ### HOUSEHOLD DATA ### Table A-2. Employment status of t... |
| demo.docx | 1 | 4 | DOCX Demo | 513 | False | # Demonstration of DOCX support in calibre This document... |
| skew.pdf | 1 | 1 | 732 | True | The LinnSequencer 32 Track MID I Sequence Recorder The... |
One full page record, exactly as a real run returned it (long text and lists shortened here). From a real run:
Use cases
- AI developers loading reports, manuals and papers into a RAG pipeline
- Analysts pulling tables out of statistical releases and annual reports
- Teams digitising scanned letters and forms with OCR
- AI agents that need a document's text and tables through MCP
Use-case recipes
Load research papers into a RAG index
For AI developers. Put the paper links in urls and set chunkSize to what your embedding model handles well. Embed each entry of chunks, and store url, title and page with it so every answer can cite the exact page.
Pull tables out of a statistics release
For analysts. Link the PDF and limit the pages to the table section. Each entry in tables has an index and rows, ready to write to a spreadsheet or a database. Tables laid out with spaces only stay as one row per line in markdown and are not in tables.
Read bilingual scanned documents
For teams digitising Canadian or European paperwork they have the right to use. Set ocrLanguage to eng+fra (or eng+spa, eng+deu). Filter on ocr = true to review the pages read by OCR, which cost more and depend on the scan's quality.
Add a site's PDFs to its Markdown corpus
For teams that already crawled a site with Website to Markdown. Take the links ending in .pdf from its links column and paste them into urls here. Both Actors return url, title and markdown, so the rows land in the same index.
Input
| Field | Type | What it does | Default |
|---|---|---|---|
urls (Document URLs) | array | Public links to PDF or DOCX files, e.g. ['https://arxiv.org/pdf/1706.03762']. | ["https://arxiv.org/pdf/1706.03762"] |
maxPagesPerDocument (Max pages per document) | integer | Convert at most this many pages of each document, from the first page, e.g. 50. | 300 |
ocr (OCR scanned pages) | boolean | Read pages that have no text layer (scans, photos) with the open-source Tesseract OCR engine. | true |
ocrLanguage (OCR language) | string | Language of scanned pages: 'eng' (English), 'fra' (French), 'spa' (Spanish), 'deu' (German), or English plus one of them, e.g. 'eng+fra'... | "eng" |
chunkSize (Chunk size (characters)) | integer | Split each page's Markdown into chunks of at most this many characters on paragraph and sentence boundaries, with 200 characters... | 2000 |
All 5 fields, with examples: see the Input tab.
Switching from memo23/pdf-text-extractor
Already running memo23/pdf-text-extractor? Map its input fields to this Actor's like this:
memo23/pdf-text-extractor input | This Actor's input | Notes |
|---|---|---|
urls | urls | Same field. Links without a .pdf ending work, because the file type is read from the content. DOCX links work too. |
pdfFile / base64Pdfs | no equivalent | Only public links are read; uploaded files and base64 are not supported. |
pageRange | maxPagesPerDocument | Ours reads from the first page up to this many pages (1 to 2,000, default 300); a range in the middle is not supported. |
ocrScannedPages | ocr | On by default here. Only pages without a text layer are read by OCR and charged at the OCR price. |
ocrLanguage | ocrLanguage | English, French, Spanish, German, or English plus one of them (eng+fra, eng+spa, eng+deu). |
ocrMaxPagesPerPdf | no equivalent | maxPagesPerDocument caps all pages; a document also stops after 5 blank scanned pages in a row, which are not charged. |
includeMarkdown / includeFullText | not needed | Every row carries the page's markdown; join the rows of one url in page order for the full text. |
includePerPageText | not needed | Output is always one row per page. |
pdfPassword | no equivalent | Password-protected PDFs are skipped and not charged. |
maxPdfSizeMb / proxyConfiguration | no equivalent | The size limit is fixed at 50 MB per file, and no proxy is used. |
- Pricing changes from per PDF to per page: $0.30 per 1,000 pages plus $0.001 per run, so short PDFs cost less and long PDFs can cost more (see the FAQ on per-page pricing).
- Output changes from one row per PDF to one row per page, with
pageandpages_total, plustablesas JSON rows andchunksfor embeddings. - Failed links (HTTP errors, robots.txt, not a PDF or DOCX) produce no row and no charge; up to 3 of them are named in the run's status message, and all of them in the log.
- The same URL given twice is downloaded once.
Use with AI agents (Apify MCP server, Claude, ChatGPT, n8n AI agent)
PDF to Markdown OCR & Table Extraction is a ready-made tool for AI agents. Through the Apify MCP server an agent reads this Actor's input schema, fills in the input from your request, starts the run and reads the pages back. You pay the same per-result price as a run started by hand, from your own Apify account.
Example prompts
- "Convert https://arxiv.org/pdf/1706.03762 to Markdown, one row per page, and give me the chunks with page numbers so I can cite them"
- "Extract every table from https://www.bls.gov/news.release/pdf/empsit.pdf as rows I can paste into a spreadsheet, first 20 pages only"
- "Read these scanned French and English PDFs with OCR and tell me which pages were read by OCR and how many words each has"
Claude (claude.ai and Claude Desktop)
Open Settings > Connectors, choose Add custom connector, paste https://mcp.apify.com/?tools=aurelix/pdf-to-markdown and sign in to Apify when asked. Then ask Claude one of the prompts above.
Claude Code, Cursor, VS Code and other MCP clients
Clients configured with JSON take the same URL:
A client without Apify sign-in sends the header Authorization: Bearer <YOUR_APIFY_TOKEN>; to run the server locally instead, use npx -y @apify/actors-mcp-server --actors aurelix/pdf-to-markdown with APIFY_TOKEN set.
ChatGPT
Where your ChatGPT plan offers custom connectors (developer mode), add https://mcp.apify.com/?tools=aurelix/pdf-to-markdown as a connector, sign in to Apify, and ask for the data in plain words.
n8n AI agent
Give an AI Agent node an MCP Client Tool with the endpoint https://mcp.apify.com/?tools=aurelix/pdf-to-markdown and a Bearer credential holding your Apify token. The agent can then call PDF to Markdown OCR & Table Extraction whenever a workflow step needs pages; for a fixed, non-agent workflow use Apify's n8n node with Run Actor instead.
Use it from AI agents (MCP), the API or no-code
Copy this to your AI assistant
MCP server URL for this Actor: https://mcp.apify.com/?tools=aurelix/pdf-to-markdown (setup for each client in the section above).
API
Start a run and read the dataset with Apify's REST API or the Python and JavaScript clients:
No-code: schedule it in 3 clicks
Send the results to Google Sheets, Zapier, Make, n8n, Slack or any webhook URL.
- Fill in the input, then click Save as a new task.
- In the task, click Schedule and pick daily or weekly (Apify Schedules).
- Open the task's Integrations tab to send every run's results to Slack, Google Sheets, email or any webhook.
Prefer n8n or Make? Ask in the Issues tab and we will share a ready-made workflow for it.
FAQ
Can I convert PDF to Markdown without login?
Yes. It never logs in, so you need no document site account, password or cookies; only a free Apify account to run it.
Is there a PDF to Markdown API?
You can use this Actor as one. Start it with Apify's REST API or the Python and JavaScript clients and read the results as JSON (see the code above), or call it from an AI agent through MCP.
How much does it cost to convert PDF to Markdown?
About $0.30 for 1,000 pages on Apify's free plan and $0.25 on paid plans, start fee included. The free $5 monthly credit covers about 16,000 pages.
Can I export the extracted tables to Excel or Google Sheets?
Yes. Download the results as Excel, CSV, JSON, XML or HTML from the run's Storage tab, or send them to Google Sheets with Apify's Google Sheets integration or the API.
Is it legal to extract text from PDFs on the web?
It reads only public data any logged-out visitor can see: the documents you link (convert only documents you have the right to use). It goes at a polite pace, respects robots.txt, never logs in and never solves CAPTCHAs. It returns each page's text and tables as the document published them; copyright stays with the owner, and any personal data inside a document is your responsibility. To have a record removed, open an issue on this Actor's Issues tab; if a site owner formally asks us to stop, this Actor will stop. You are responsible for using the data lawfully, incl. anti-spam and privacy laws; this is not legal advice.
How does per-page pricing compare with per-PDF pricing?
You pay $0.30 per 1,000 pages ($0.25 on paid plans) plus $0.001 per run, so a 10-page PDF costs $0.003. Against the most-used per-PDF extractors ($3.45 to $5 per 1,000 PDFs, plus a $0.005 start fee) that is cheaper for PDFs up to 11 pages in a batch and up to 24 pages for a single-PDF run; longer PDFs are cheaper with per-PDF pricing. Scanned pages cost $8 per 1,000 OCR pages instead.
Which files are supported?
PDF (any version, text or scanned) and Word DOCX. The type is detected from the file's content, so download links without a .pdf ending work. Legacy .doc, PowerPoint and Excel files are not supported.
How are scanned PDFs handled?
Each page is checked for a text layer. A page with almost no text and an image is rendered at 200 dpi and read by Tesseract OCR in the language you choose. Scans that already carry a hidden OCR text layer (common for library scans) use that layer as is.
How good is table extraction?
Tables drawn with lines are returned as Markdown tables and JSON rows. Tables laid out with spaces only, common in statistical releases, are kept as one row per line in the Markdown but are not split into cells.
What is a page for a DOCX file?
Word files have no fixed pages, so they are split on paragraph boundaries into page-equivalents of about 3,000 characters, each charged as one page.
Does it respect robots.txt?
Yes. Each download, including every redirect hop, is checked against the site's robots.txt; a robots.txt that answers with a server error counts as disallowed.
What am I charged when a link fails?
Nothing for that link. URLs that return an HTTP error, are blocked by robots.txt, are over 50 MB or are not a PDF or DOCX produce no row and no charge. A run where every link fails costs only the $0.001 start fee, and its status message names up to 3 failed URLs with the reason.
Are blank pages charged?
No. A page with no text, even after OCR, is skipped for free and counted as an empty page in the status message. A document stops after 5 blank scanned pages in a row, so a long blank scan does not keep the run busy.
Does it retry a failed download?
No. A link that answers with an error such as HTTP 429 or 500 is reported as failed and not charged; run it again later. A host that does not answer at all is given up on after 5 seconds.
Can I convert only pages 10 to 20?
Not directly. Max pages per document reads from the first page, so set it to 20 and keep the rows where page is 10 or more. You pay for every page returned.
How are the chunks made?
Each page's Markdown is split on paragraph and then sentence boundaries into chunks of at most chunkSize characters (2,000 by default, up to 20,000), with 200 characters of overlap between chunks. Set chunkSize to 0 to get the whole page as one chunk.
In what order are documents processed?
One at a time, in the order of the urls list, and each document from its first page. The same URL listed twice is downloaded once. If the run approaches its timeout, it stops cleanly and keeps the pages already returned.
How do I know which pages were read by OCR?
The ocr field is true on those pages, and the status message gives the count. OCR pages are charged as OCR pages at $8 per 1,000 instead of the text-page price, never both.
Limits (stated honestly)
- Multi-column layouts (papers, forms) are read line by line across the page, so columns can interleave.
- Tables without ruling lines are kept as text rows, not split into cells; merged cells come back as repeated or empty cells.
- OCR quality depends on the scan; handwriting is not supported, and OCR runs at about 3 to 10 seconds a page.
- Images, charts and formulas are not described; only their horizontal text labels come through (rotated or vertical text is skipped).
- Files over 50 MB, password-protected PDFs, legacy .doc and other formats are skipped without charge.
- Documents are read from the first page up to 'Max pages per document' (300 by default).
- A document stops after 5 blank scanned pages in a row (blank pages are never charged), so scans with long blank runs end early.
Works great with
- Before this: Website to Markdown API: the HTML pages of the same site, so pages and PDFs land in one Markdown corpus
Related Aurelix tools
Public Aurelix Actors, grouped by the data they collect. All are pay-per-result and need no login.
AI, content and SEO
- Google Trends by Region: Google Trends interest over time, by region and rising queries for any number of keywords, plus trending searches.
- Google Autocomplete API: Expands seed keywords into hundreds of real Google and YouTube autocomplete phrases, tagged by search intent.
- Website to Markdown API: Crawls a site and returns one row of clean main-content Markdown per page, with title, headings and links.
Jobs and hiring data
- Greenhouse Jobs Scraper: Live jobs from a company's Greenhouse, Lever, Ashby or SmartRecruiters board, with salary and Canadian province tags.
- LinkedIn Jobs Country Filter Scraper: Public LinkedIn job postings by keyword and country: title, company, location, seniority, job type, salary text, description.
- Multi Job Board Scraper: LinkedIn, about 50 company career sites, Remote OK and We Work Remotely jobs in one deduplicated list.
E-commerce and product data
- AliExpress Scraper API: AliExpress search results by keyword: price, discount, rating, units sold, ship-from country and sponsored flag.
- Amazon New Releases & Best Sellers: Amazon Best Sellers and New Releases top 100 on 10 marketplaces: rank, ASIN, price, rating, rank change.
Leads and company data
- Funded Companies Hiring: Companies that just raised money (SEC Form D), with their open roles and business contacts, as a new-only monitor.
- Google Maps Phone Scraper: Local business lists from Google Maps: phones, websites, ratings, hours, coordinates; optional website emails and socials.
- Recently Funded Companies API: US companies that just filed an SEC Form D: amount raised, industry, state, executives, confirmed website.
Ad intelligence
- Competitor Watch: One report per competitor with only what is new: Meta and TikTok ads, page changes, Shopify products and prices, jobs.
- Facebook Ad Library Search & API: Facebook and Instagram business ads from the Meta Ad Library: copy, creatives, landing pages, dates, optional EU reach.
Canada and government data
- Canada Building Permits: Building permits and development applications from 7 Canadian cities: address, type, status, dates, value, contractor company.
Recent changes
- 0.1: Price lowered to $0.30 per 1,000 pages ($0.25 on paid plans) from $2.00; OCR price unchanged.
The full history is on the Changelog tab.
Tested daily
An automated health check runs this Actor every day on a fixed input and checks that at least 2 pages come back with url, page, markdown, source_url, scraped_at filled in; a failed check alerts the maintainer straight away.
Your feedback
Missing a field, found a bug or need another filter? Open an issue on the Issues tab; we aim to answer within a day. If this Actor saved you time, a short review helps other people find it.


