
Facebook Ad Library Scraper (Meta Ads Library)
Pricing
from $0.55 / 1,000 ad results
Facebook Ad Library Scraper (Meta Ads Library)
Scrape the Facebook Ads Library (Meta Ad Library) by keyword, page ID or URL: ad copy, images, videos, CTAs, landing pages, dates, platforms and page info, plus EU reach, targeting and payer data. Every ad in a group, deduplicated. No login, cookies or proxy setup.
Pricing
from $0.55 / 1,000 ad results
Rating
0.0
(0)
Developer
Yevhenii Molodtsov
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
18 hours ago
Last modified
Categories
Share
What does Facebook Ad Library Scraper do?
Facebook Ad Library Scraper collects ads from the public Facebook Ad Library, also called the Meta Ads Library, by keyword, Facebook page ID or pasted Ad Library URL. Every ad comes back as one row with its copy, headline, call to action, landing page, image and video URLs, carousel cards, dates, platforms and advertiser page. Turn on ad details to add EU reach with its age, gender and country breakdown, targeting, and who paid for the ad.
Use cases
- Competitor creative research: pull the active ads the Ad Library shows for a rival brand in your country, with copy, call to action, landing page and media, and keep them as a swipe file.
- Agency client reporting: schedule a weekly run on a client's or competitor's page ID and see which ads started, stopped or changed format.
- Ad-spy and lead-gen tools: run a keyword list such as "shopify" or "dropshipping" through the API every day and get the advertisers and landing pages behind each ad.
- Political ad research: collect issue and election ads for one country and date window, with spend and impression ranges, audiences and payers.
Why this Facebook Ads Library scraper
- No Facebook account. It reads the Ad Library logged out: no login, cookies or tokens. Proxies are built in and included in the price.
- EU reach and payer data at no extra charge. Reach by country, age and gender, targeting, payer and beneficiary cost the same as a plain ad.
- Every ad in a group. Meta collapses near-identical ads into one result ("24 ads use this creative"). This scraper returns each as its own row: 3.5× more ads than one row per group on a broad search like "shopify".
- Deduplicated, stable columns. Each ad appears once per run and is never billed twice. Meta's own field names,
with every detail key on every row (
nullwhen details are off). - Honest run status. A blocked run ends FAILED with a reason code, never as a quiet empty dataset.
What data you get
| Field | Example | Description |
|---|---|---|
ad_archive_id, ad_library_url | 2858097847888338 | The ad's ID and its Ad Library link |
page_id, page_name | Sneakerjagers Deutschland | The advertiser's Facebook page |
is_active | true | Whether the ad is running now |
start_date_formatted, end_date_formatted | 2026-08-29T07:00:00.000Z | Start and end (also start_date, end_date in Unix seconds) |
publisher_platform | ["FACEBOOK", "INSTAGRAM"] | Facebook, Instagram, Messenger, Threads, Audience Network |
snapshot.body.text, snapshot.title | Nike V5 RNR | Ad copy and headline |
snapshot.link_url | https://sneakerjagers.com/d/dRgK4E | Landing page |
snapshot.cta_text, snapshot.cta_type | Shop now, SHOP_NOW | Call-to-action button |
snapshot.display_format | IMAGE | IMAGE, VIDEO, CAROUSEL, DCO, DPA and more |
snapshot.images[], snapshot.videos[] | https://scontent…fbcdn.net/…jpg | Full-size and 600 px images; HD and SD videos with preview image |
snapshot.cards[] | Carousel and catalog cards, each with its own text, link and media | |
snapshot.page_like_count | 112840 | Page likes, plus page categories, profile link and picture |
collation_id, collation_count | 4 | Meta's group of near-identical ads and its size |
categories, spend, impressions_with_index | ">$1M" | POLITICAL marks issue and political ads; only those carry spend and impression ranges |
position, inputUrl | 6, nike | Rank in Meta's results, and the input that found the ad |
With ad details on:
| Field | Example | Description |
|---|---|---|
eu_total_reach | 1700174 | Total EU reach (also in aaa_info) |
transparency_by_location.eu_transparency | DE, 25-34, male: 196543 | Reach by country, age and gender, plus targeted locations, ages and gender |
aaa_info.payer_beneficiary_data | Sneakerjagers B.V. | Who paid for the ad and who benefits |
advertiser.ad_library_page_info | ig_followers: 8662 | Page likes, Instagram account and followers, category, verification |
insights | Political and issue ads: audience by age, gender and region |
Meta publishes reach and targeting only for ads delivered in the EU, so eu_total_reach is null for ads that ran
only elsewhere.
How to scrape Facebook ads from the Ad Library
- Click Try for free and open the Input tab.
- Enter Search terms, Facebook page IDs or Ad Library URLs, pick a country and filters, and set Maximum ads. Switch on Scrape ad details for EU reach, targeting and payer data.
- Click Start, then export the ads from the Output tab as JSON, CSV or Excel.
Tip: search the Ad Library in your browser, then paste the URL from the address bar into Ad Library URLs to reuse its filters.
Via API, run synchronously and get the ads back in one call:
AI agents can call it as a tool through the Apify MCP server as xmolodtsov/facebook-ads-library-scraper (see
Integrations below).
Pricing
Pay per result: you pay only for ads delivered to your dataset. Platform usage and proxies are included, with no separate usage charge.
| Apify plan | Price per 1,000 ads |
|---|---|
| Free | $0.90 |
| Bronze (Starter) | $0.75 |
| Silver (Scale) | $0.65 |
| Gold (Business), Platinum, Diamond | $0.55 |
- No start fee: a run that finds nothing costs nothing.
- Ad details and every ad in a group included at the same per-ad price.
- Duplicates never charged: an ad found under several search terms is billed once.
- Spending cap respected: set a maximum cost per run and the scraper stops when it is reached.
Example: 5,000 ads with details on the Silver plan cost $3.25.
Is it free?
You can try it on the free Apify plan, with limits set by the developer, not by Apify: 10 ads per run and 5 runs per calendar month per account, resetting on the 1st (UTC). A capped run ends SUCCEEDED and its status message shows how many free runs you have used. Once all 5 are used, a run ends SUCCEEDED with no ads and a status message saying why. Any paid Apify plan removes both limits.
Input
Fill in at least one of Search terms, Facebook page IDs or Ad Library URLs.
| Field | Default | What it does |
|---|---|---|
searchTerms | Keywords; each term is its own Ad Library search | |
pageIds | Numeric Facebook page IDs; returns the ads that page runs | |
urls | Search, page or single-ad (?id=) Ad Library URLs. Each keeps its own filters; the fields below don't apply to it | |
country | ALL | ALL or one 2-letter country code (US, GB, DE …) |
adType | all | all, political_and_issue_ads, housing_ads, employment_ads, credit_ads |
activeStatus | active | active, inactive or all |
mediaType | all | all, image, video, meme, image_and_meme, none |
searchType | keyword_unordered | Any of the words, or keyword_exact_phrase (search terms only) |
startDate, endDate | YYYY-MM-DD: ads that had impressions in this window, not only ads that started in it | |
sortBy | impressions_desc | impressions_desc, impressions_asc or most_recent |
maxItems | 100 | Unique ads across the whole run (free plan: capped at 10) |
maxItemsPerQuery | no cap | Optional cap per search term, page ID or URL |
expandAdGroups | true | Every ad in a group as its own row; false = one row per group |
scrapeAdDetails | false | Adds EU reach, targeting, payer and advertiser info; slower, no extra charge |
The form takes one country per run; for several, paste one Ad Library URL per country. Inputs written for other Ad
Library tools carry over: startUrls works as urls, keywords as searchTerms, and count or resultsLimit as
maxItems.
Example: video ads shown in the UK in September, newest first, for the exact phrase "running shoes" and for Nike's page (the filters apply to both), with ad details, plus one single ad by URL:
Output
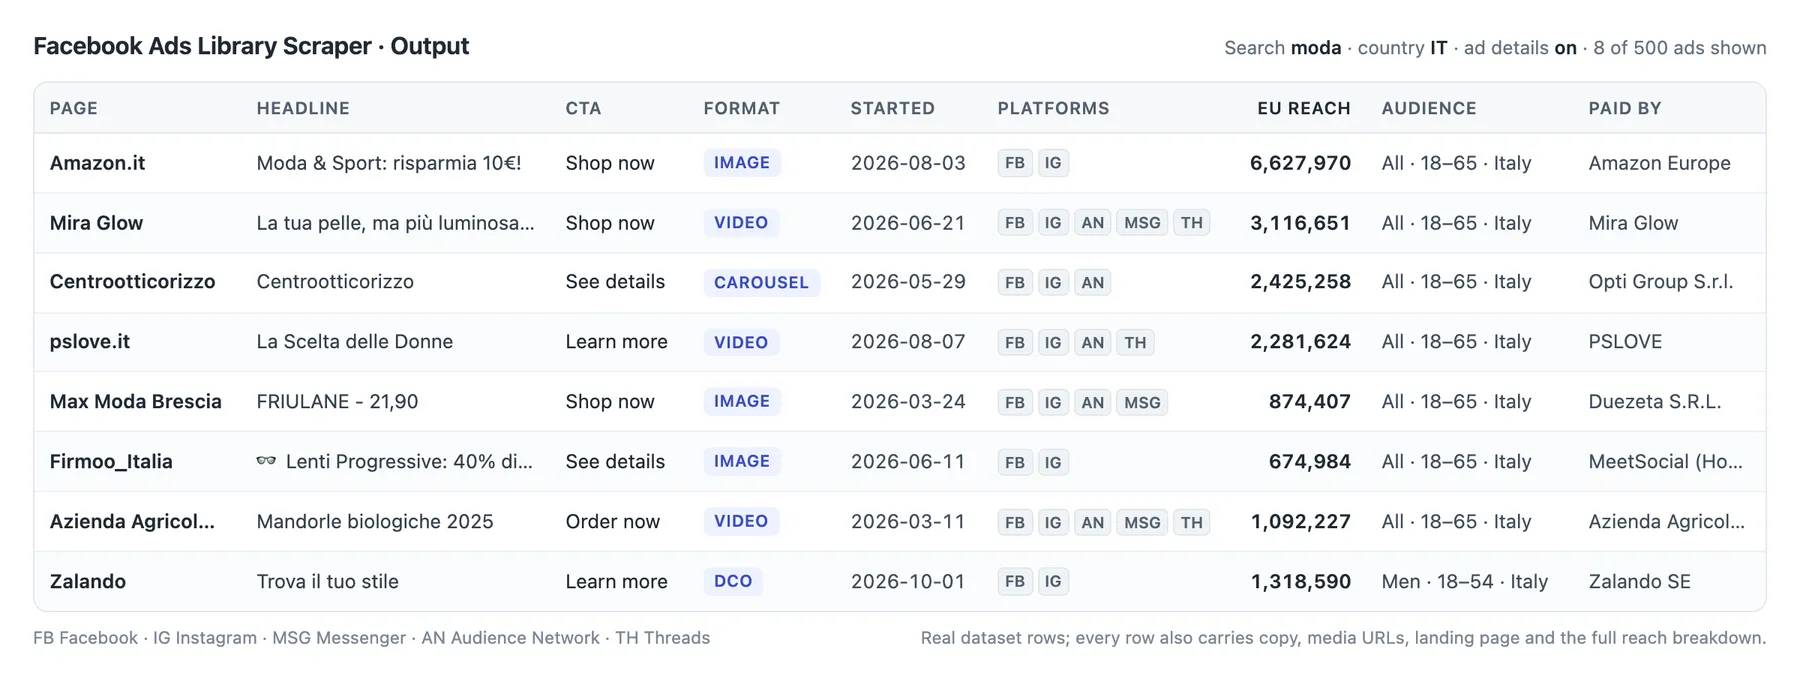
Each ad is one dataset item. The Overview table in the Output tab shows the key fields; exports carry every field. Real rows from a run with search "moda", country Italy and ad details on:
One item, trimmed (long URLs shortened, many keys left out):
Coming from a scraper that outputs camelCase fields?
This scraper keeps Meta's original snake_case names. Map your columns once:
| camelCase field | Field in this scraper |
|---|---|
adArchiveID | ad_archive_id |
pageID | page_id |
pageName | page_name |
startDate | start_date (Unix seconds) or start_date_formatted (ISO 8601) |
endDate | end_date (Unix seconds) or end_date_formatted (ISO 8601) |
publisherPlatform | publisher_platform |
snapshot.body.text | snapshot.body.text (unchanged) |
snapshot.linkUrl | snapshot.link_url |
snapshot.ctaText | snapshot.cta_text |
snapshot.displayFormat | snapshot.display_format |
isActive | is_active |
collationCount | collation_count |
Guarantees and failure semantics
- SUCCEEDED with ads: "N ads scraped." If a query fails partway or another query fails, the run keeps the ads it
got and the status message adds, for example, "1/3 queries stopped early (blocked)". Each query's
failureReasonis inSTATISTICS. - SUCCEEDED with "No results": Meta answered and the search has no matches.
- FAILED, 0 ads: Meta blocked or errored. The status message starts with a machine token, such as
blocked: 0 ads — …, so your integration can retry. - FAILED with
outdated: …: Meta occasionally rotates the private query IDs behind the Ad Library, and the scraper rediscovers them automatically. If that self-heal fails, the run fails, never ending as an empty success, and the scraper needs an update. - Ads pushed before a failure stay in the dataset.
| Token | Meaning | What to do |
|---|---|---|
blocked | Meta refused or rate-limited every retry | Retry later |
network, timeout, server | Connection or server errors on every retry | Retry |
quota, geo | Meta answered HTTP 429 (too many requests) or 451 (unavailable in that region) | Retry later |
invalid | Bad input, such as a non-numeric page ID (the field is named), or Meta rejected the request shape | Fix the input; if the input is fine, report it |
outdated | Meta changed the Ad Library and the automatic fix failed | Report it in the Issues tab |
unknown | Any other error; the log has the details | Retry, then report it with the run ID |
Per-query numbers, including Meta's own total per query (totalCount), are in the run's STATISTICS record.
Integrations
-
API: the Apify API and the JavaScript and Python clients, for example:
import { ApifyClient } from 'apify-client';const client = new ApifyClient({ token: process.env.APIFY_TOKEN });const run = await client.actor('xmolodtsov/facebook-ads-library-scraper').call({ pageIds: ['15087023444'], maxItems: 100 });const { items } = await client.dataset(run.defaultDatasetId).listItems(); -
AI agents (MCP): connect any MCP client to
https://mcp.apify.com?tools=xmolodtsov/facebook-ads-library-scraperand ask "what ads is this brand running in Germany right now?" -
n8n, Make, Zapier: run the scraper with the Apify node or app and pass the ads on.
-
Schedules and webhooks: re-run a search daily and get notified when results are ready.
More scrapers from this developer
TikTok: TikTok Search Scraper: videos and creators for any keyword, pay per result · TikTok Profile Scraper (Pay Per Result): profiles, followers and latest posts by username · TikTok Comments Scraper: comments and full reply threads from any video · TikTok Hashtag Scraper: videos for any hashtag, with views, likes and music · TikTok Sound & Music Scraper: videos that use a sound or song
Social & news: Reddit Search Scraper: posts by keyword, subreddit or author · Google News Scraper: Google News results as clean full-text articles
E-commerce: Prom.ua Product Search Scraper: Prom.ua product search results, no browser needed · Amazon Product Search & Bestsellers Scraper: search results, Best Sellers and product details from Amazon
Maps & leads: Google Maps Scraper: places, leads and emails from Google Maps
Video: YouTube Transcript Scraper: transcripts, subtitles and captions from YouTube videos
FAQ
How many ads can I get per search?
Meta serves 30 results per page, and the scraper keeps paging until Meta runs out or Maximum ads is reached; deep paging was measured at more than 6,000 unique ads for one keyword. For very large pulls, split by country or date window and set Maximum ads per query.
Why did I get fewer ads than Maximum ads?
Meta has fewer results for your filters; duplicates were removed; Meta listed fewer group members than
collation_count says (4 of 180 groups in our tests); Maximum ads per query or your maximum cost per run stopped a query;
or the free plan capped the run at 10 ads.
What do the sort options do?
"Most recent" is Meta's own order, grouped by month, so sort by start_date after export for a strict order.
Impression sorting only reorders political and issue ads, the only ads Meta reports impressions for.
Why are spend and impressions null?
Meta publishes spend, impressions_with_index and reach_estimate only for political and issue ads, as ranges. For
other ads they are null: that is the Ad Library's data, not a scraping gap. For commercial ads shown in the EU, turn on
ad details and use eu_total_reach.
Can I find a page ID from a page name?
Not logged out: Meta resolves advertiser names only for logged-in users. Open the advertiser's ads in the Ad Library and
copy the number after view_all_page_id=, or paste the whole URL into Ad Library URLs. A keyword search for the
brand also shows its page_id.
Do image and video links expire?
Yes. Media URLs are signed Meta CDN links that stop working after a while, so download what you want to keep soon after
the run. ad_library_url stays valid.
Why does a headline show {{product.name}}?
That is a catalog ad (display_format: "DPA"), a template Meta fills in per viewer. The actual products, each with
title, link and image, are in snapshot.cards.
How is this different from the official Meta Ad Library API?
The official API needs a developer app, identity verification and an access token, covers only political and issue ads plus ads delivered in the EU and UK, and returns a snapshot link instead of media files. This scraper reads the public Ad Library website: no app review or access token, commercial ads from any country, and direct image and video URLs.
Is it legal to scrape the Facebook Ads Library?
This scraper collects only what the Ad Library shows to a visitor who is not logged in. It never logs in and uses no cookies or accounts.
- Public by law. Under the EU Digital Services Act (Article 39), very large online platforms must keep a public, searchable repository of the ads they show in the EU. Meta's Ad Library is that repository.
- Court precedent. A 2024 US court ruling (N.D. Cal., January) found that logged-off scraping of public data did not breach Meta's terms. It is a district-court ruling and does not settle every question everywhere.
- Personal data. Payer and beneficiary names can identify a person, such as a sole trader or a politician, which makes them personal data under the GDPR and similar laws such as the CCPA. You need your own lawful basis to process them.
This is general information, not legal advice. If you are unsure whether your use is lawful, consult a lawyer.
Support
Found a bug or need a field? Open an issue in the Issues tab on this page and include the run ID.


