
Instagram Comment Scraper: Export Post & Reel Comments
Pricing
from $1.20 / 1,000 comments
Instagram Comment Scraper: Export Post & Reel Comments
Export public top-level Instagram post and reel comments with text, likes, timestamps and public usernames. Public Instagram data, no login. Replies and reply counts are not included. Export JSON, CSV or Excel.
Pricing
from $1.20 / 1,000 comments
Rating
0.0
(0)
Developer

GoFetch
Maintained by CommunityActor stats
0
Bookmarked
1
Total users
0
Monthly active users
3 days ago
Last modified
Categories
Share
Export public Instagram post and reel comments as structured data: comment text, likes, timestamps, public usernames and source post links. Public Instagram data, no login. This Actor collects top-level comments only; replies and reply counts are not included.
Quick start
- Paste a public post or reel URL into Instagram post or reel URLs.
- Set Comments per post and a run-wide Maximum comments per run.
- Run the Actor, open the Overview dataset view, and export JSON, CSV or Excel.
The prefill collects up to 20 top-level comments from a Kew Gardens post:
For several posts, put each URL in the list. Posts run in input order. Use resultsLimit: 0 to collect all reachable top-level comments, while retaining a suitable maxItems cap.
Input
| Field | Default | Meaning |
|---|---|---|
directUrls | Required; working prefill supplied | 1–100 public Instagram URLs or bare shortcodes |
resultsLimit | 50 | Saved comments per post, 0–50,000; 0 means all reachable |
maxItems | 1000 | Run-wide saved comment cap, 1–100,000; free limits also apply |
Accepted URLs use instagram.com or www.instagram.com, with /p/, /reel/, /reels/ or /tv/. Query parameters are accepted. Inputs are trimmed and duplicates removed by post ID. Invalid entries are skipped with a warning when some entries are valid; entirely invalid input fails with invalid:.
No proxy field or account credentials are needed. Cloud runs always use Apify datacenter proxies. There is no residential or third-party proxy mode. Guest cookies and public page tokens are fetched automatically; the Actor does not use Instagram accounts, logins or session cookies.
Output
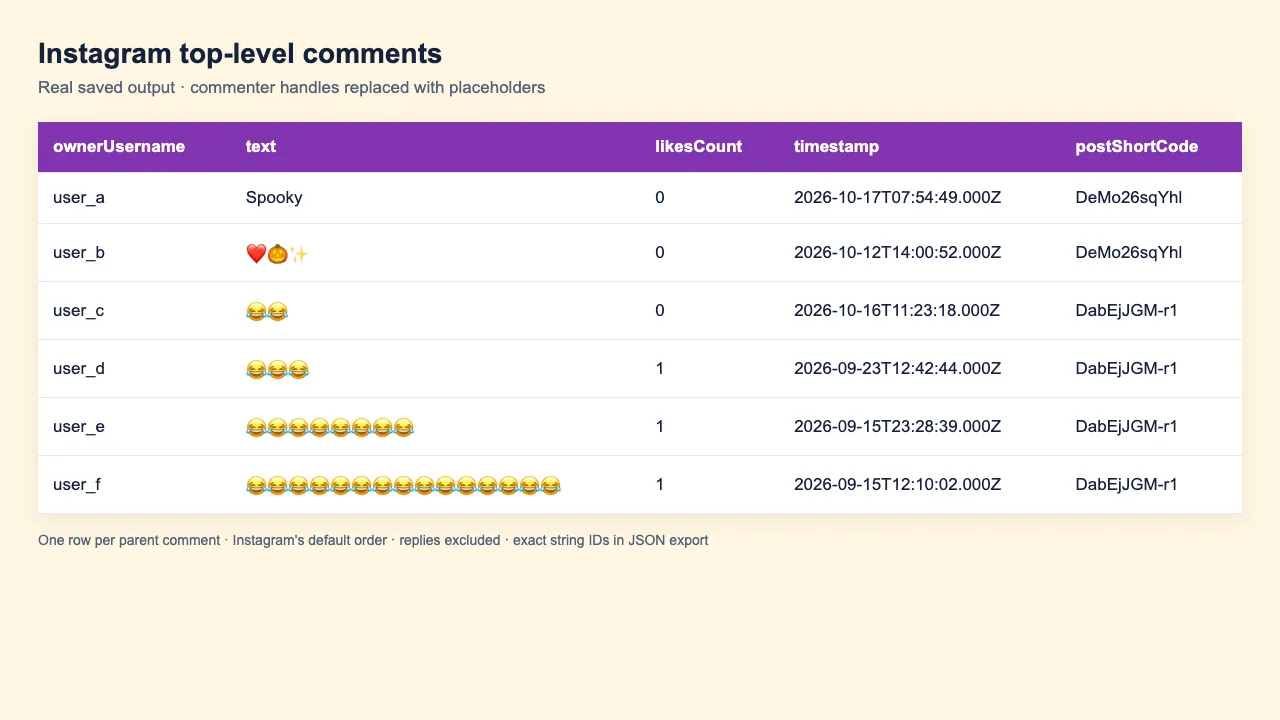
One row is one top-level comment. This example is from a real proof run; commenter identity fields are replaced with placeholders, and the optional profile image is omitted for privacy:
| Fields | Meaning |
|---|---|
id | Exact comment ID as a string |
text | Comment text, or null for a textless GIF/sticker comment |
timestamp | Source creation time in ISO UTC, or null |
ownerUsername, ownerId | Public username and exact string owner ID, when provided |
ownerProfilePicUrl, ownerIsVerified | Public profile image URL and source verification boolean, or null |
likesCount | Source comment likes count, or null |
postUrl, postShortCode, postId | Canonical source URL, shortcode and exact string media ID |
inputUrl | Trimmed input URL or shortcode that identified the post |
scrapedAt | Collection time in ISO UTC |
Missing values are null, never empty strings. A comment without text remains a billable saved row. IDs stay strings so large values are not rounded. The source can return signed image URLs that expire; this Actor exports the URL and does not download images.
The order is Instagram's default order, preserved as returned by the logged-out query. It is not a newest-first or chronological guarantee. Replies are excluded, and there is no repliesCount field: Instagram does not reliably supply it to logged-out visitors. Public usernames and profile fields are returned as displayed, with no contact enrichment.
Pricing
One Comment event (apify-default-dataset-item) is billed per saved dataset row. There is no start fee or add-on event. Duplicate comments within a run are not saved or charged again, including after an Actor reboot.
| Apify pricing tier | Per 1,000 saved comments |
|---|---|
| FREE | $1.56 |
| BRONZE | $1.44 |
| SILVER | $1.32 |
| GOLD | $1.20 |
| PLATINUM / DIAMOND | $1.20 |
Example Actor result charges:
| Saved comments | BRONZE | GOLD |
|---|---|---|
| 100 | $0.144 | $0.12 |
| 1,000 | $1.44 | $1.20 |
| 5,000 | $7.20 | $6.00 |
These are Actor result-event totals; applicable platform charges and account credits follow your Apify plan. Set the run charge budget before starting a large export.
Is it free?
On the Apify free plan, this Actor allows 100 results per run and 20 runs per calendar month (UTC). These are limits set by the developer. Run 21 succeeds gracefully with a quota message before making target requests. The allowance resets on the first of the UTC month. Paid plans use the requested input limits. Apify's credits and billing rules still apply; the FREE pricing tier does not mean unlimited free usage.
Reach and reliability
The Actor collects the top-level comments Instagram shows to logged-out visitors; very large posts may expose fewer than the total count. A private proof collected 1,533 top-level comments from Kew Gardens (1,607 reported total) and 1,395 from LEGO (1,855 reported total), each with a confirmed clean server end and no duplicate IDs. Displayed totals include replies and may include hidden or inaccessible comments. A requested limit is a cap, not a promised result count. Comments can be added, removed or reordered during collection.
- Posts with comments off, private/deleted posts and unknown items are recorded as not available when Instagram confirms this across fresh guest sessions. They do not stop later inputs. A valid empty answer is a possible result.
- The Actor tries two pinned comments query IDs first. Only if both return schema or persisted-query errors does it scan public page JavaScript for a replacement, caching that attempt per run. Blocks and network errors use bounded retries without discovery. A malformed connection or failed query is recorded as an
outdatedper-post outcome. - Apparent server ends are checked on fresh guest sessions. A missing or repeating cursor, or a page that adds nothing while the server still promises more, is recorded as truncation. It is not reported as a clean end.
STATISTICSrecords posts requested/done/not available/failed, per-post counts and end states, requests/pages, rows, refusals by code, query-ID source, truncations, transfer and wall time. Saved rows survive a later per-post error.- A run with saved rows succeeds as partial after a later processing error or deadline. Zero rows succeed as “no results” only after confirmed empty/unavailable answers; otherwise the run fails with a reason token such as
blocked:,network:,timeout:,outdated:,invalid:orquota:. - The Actor stops starting requests before the platform timeout, flushes statistics, and succeeds with saved partial output. An exhausted charge budget stops collection and succeeds with “run budget reached.” Only saved rows count toward result charges.
- Reboots seed exact comment IDs and post counts from the existing dataset. Source pages may be fetched again, but saved comments are not pushed again. Deduplication applies within a run; separate runs are independent.
- Default memory is 256 MB, with a 512 MB maximum; the default timeout is 3,600 seconds. No source availability or exhaustive historical coverage is guaranteed.
API and integrations
Send the same input JSON through Apify's API. Keep your Apify token in an environment variable:
For large jobs, start an asynchronous run and download its dataset after completion. JSON, CSV and Excel exports work with spreadsheets and analytics pipelines. Use Apify integrations with n8n, Make, webhooks or scheduled runs to supply post URLs and consume output. The Actor does not create tasks or schedules automatically.
Support
Open the Actor's Issues tab with your run ID, input and expected output. Do not include account credentials or private data.
More scrapers from this developer
TikTok: TikTok Search Scraper: Videos and creators for any keyword, pay per result · TikTok Profile Scraper (Pay Per Result): Profiles, followers and latest posts by username · TikTok Comments Scraper: Comments and full reply threads from any video · TikTok Hashtag Scraper: Videos for any hashtag, with views, likes and music · TikTok Sound & Music Scraper: Videos that use a sound or song · TikTok Top Ads Scraper: Public Creative Center ad rankings, engagement, media and landing pages
Social & news: Reddit Search Scraper: Posts by keyword, subreddit or author · Google News Scraper: Google News results as clean full-text articles · Threads Replies Scraper: Public post replies, likes, authors and inline nested replies
E-commerce: Prom.ua Product Search Scraper: Prom.ua product search results, no browser needed · Amazon Product Search & Bestsellers Scraper: Search results, Best Sellers and product details from Amazon · AliExpress Search Scraper: AliExpress products by keyword with prices, orders and shipping · AliExpress Product Reviews Scraper: Public product reviews, ratings, buyer photos and follow-up feedback
Maps & leads: Google Maps Scraper: Places, leads and emails from Google Maps
Ads: Facebook Ad Library Scraper (Meta Ads Library): Ads from the Meta Ad Library, with EU reach and payers · Google Ads Transparency Scraper: Google ad creatives by advertiser or domain, with regional details
Video: YouTube Transcript Scraper: Transcripts, subtitles and captions from YouTube videos · YouTube Shorts Scraper: Shorts of any channel with exact views, likes and duration · YouTube Channel Scraper: Every video of a channel, with channel stats · YouTube Search Scraper: Search results and videos for any keyword · YouTube Comments Scraper: Comments, replies and likes from any video · Bilibili Comments Scraper: Public hot comments and reply threads by video or keyword
Jobs: SEEK Job Listings Scraper: Public AU/NZ job listings, salaries and redacted descriptions
Frequently asked questions
Can I collect replies or reply counts? No. This Actor exports top-level comments only. It leaves reply counts out rather than presenting unreliable guest values.
Why is my result count below the post's total? The total can include replies and inaccessible comments. The guest query may expose only a subset. Your input caps, free allowance, charge budget or run deadline can also stop collection. Inspect STATISTICS for the per-post outcome.
Is it legal to scrape Instagram comments? The Actor requests publicly accessible data without login and does not collect contact details. Public usernames, profile images and comment text can still be personal data. Public access alone does not establish permission for every reuse. Check applicable law, including GDPR/CCPA, Instagram terms and your intended purpose before collecting, retaining or republishing results.
Can it access private posts? No. No Instagram account credentials are accepted or used.
Can I request newest first? No. The Actor keeps Instagram's default guest-query order and does not promise chronological results.


