
Threads Replies Scraper: Post Replies, Likes & Authors
Pricing
from $1.10 / 1,000 replies
Threads Replies Scraper: Post Replies, Likes & Authors
Scrape public Threads post replies with text, likes, authors, media and inline nested replies. Choose top or recent order and export one row per reply. No login; public subset only.
Pricing
from $1.10 / 1,000 replies
Rating
0.0
(0)
Developer

GoFetch
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Share
Get replies from public Threads posts as structured rows. Threads Replies Scraper: Post Replies, Likes & Authors collects reply text, public author handles and display names, verification, likes, reply counts, timestamps, media URLs and the nested replies already included in the public response. Supply post URLs; each saved reply becomes one dataset row. No login or account cookies are needed.
Use it to review public conversations, compare reactions across supplied posts, or feed a research workflow. It collects public replies to the supplied posts; it does not search profiles or enrich authors.
Quick start
- Paste one or more public post links in
postUrls. Boththreads.comandthreads.netlinks work. - Choose the per-post limit and reply order. Start with 20 replies on one post.
- Run the actor and open the dataset. Export JSON, CSV, Excel or JSONL, or read it through the Apify API.
Run synchronously through the API using your own token:
For larger jobs, start an asynchronous actor run, wait for it to finish, then read its default dataset. Avoid embedding tokens in shared URLs or exported workflow definitions.
Inputs
| Field | Default | What it controls |
|---|---|---|
postUrls | Required | 1–100 public /@user/post/<code> links. Query strings and trailing slashes are accepted; canonical URLs are deduplicated. Invalid entries are skipped with a warning when some links are valid. No valid links means FAILED invalid:. |
maxRepliesPerPost | 100 | Saved rows per source post, including inline nested replies when enabled. 0 requests all reachable replies, bounded by maxItems, time and budget. |
sort | top | top follows public web ranking; recent starts the recent-replies connection. |
includeNestedReplies | true | Include child replies already inlined by the public response. |
maxItems | 1000 | Run-wide saved-row cap, 1–100000. Free-plan cap: 100 results/run and 20 runs/UTC calendar month. |
proxyConfiguration | Apify datacenter | Residential is optional. Explicit choices do not silently fall back. Free-plan runs use only Apify Proxy; custom/direct settings are ignored. |
Output
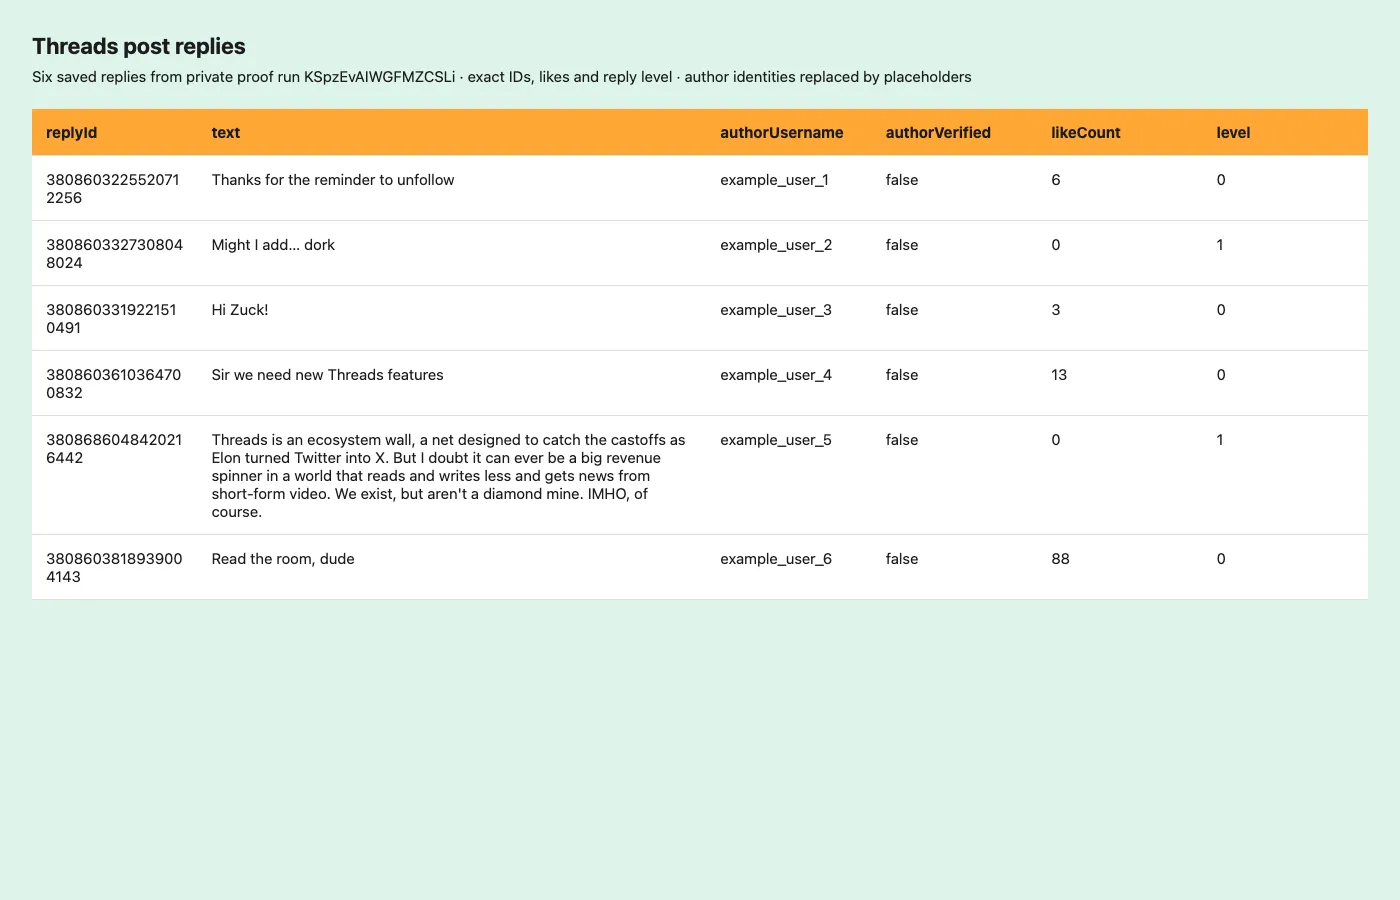
This example uses a row from a private proof run, with the replier’s identity and permalink replaced by placeholders. Dataset IDs are strings so exports and downstream applications can preserve their exact values.
| Fields | Meaning |
|---|---|
postUrl, postId | Canonical input post URL and exact string post ID. |
replyId, replyCode, replyUrl | Exact reply ID, public shortcode and permalink. Deduplication uses the reply ID within each source post. |
text, createdAt | Reply text and ISO publication time. Missing values are null. |
authorUsername, authorName | Public author handle and display name. |
authorVerified, authorProfilePicUrl | Public verification flag and profile picture URL when supplied. |
likeCount, replyCount, repostCount, quoteCount | Public engagement counts, each nullable. A missing count is not replaced with zero. |
media | Array of { "type": "image" or "video", "url": "…" }; empty when no media is returned. |
level, parentReplyId | 0 is a direct reply; larger levels are inline children. Parent ID is set only when resolved in the same public thread segment; otherwise null. |
scrapedAt | ISO collection time. |
Quoted and embedded posts are excluded from reply rows. Media links can expire. No contact fields or profile enrichment are added.
Pricing
Only saved reply rows use the apify-default-dataset-item event, titled Reply. There are no actor-start or add-on events. The run and per-post limits count saved rows across direct and included nested replies.
| Apify plan | Price per 1,000 saved replies |
|---|---|
| FREE | $2.00 |
| BRONZE | $1.80 |
| SILVER | $1.50 |
| GOLD | $1.10 |
| PLATINUM / DIAMOND | $1.10 |
Example result charges, excluding any separate Apify platform or proxy charges:
| Saved rows | BRONZE | GOLD |
|---|---|---|
| 100 | $0.18 | $0.11 |
| 300 | $0.54 | $0.33 |
| 2,000 | $3.60 | $2.20 |
Is it free?
On the Apify free plan, this developer allows 100 results per run × 20 runs per UTC calendar month. These are developer limits, not Apify's general platform limits. Free-plan actor result events are subject to Apify's free-plan billing rules; platform credits and proxy usage still follow your Apify plan. The FREE row is the published event ladder, not a promise of unlimited free platform usage.
The monthly allowance resets on the first day of the month. A run above the allowance exits SUCCEEDED, saves zero rows and makes zero requests to Threads, with an explanatory quota message. Paid Apify plans are not subject to the developer's 100/20 cap. The developer owner and Apify TEST runs are exempt for health checks.
Coverage and failure guarantees
- Public subset per sort. The post's displayed reply total can include replies unavailable to anonymous readers.
topandrecentexpose different sets. In local checks, top reached 939 on a post reporting 6,552 replies. After fixing source field error handling, recent saved 5,509 and exhausted the public connection on the same post, then reporting 6,551 replies (previously it stopped at 3,733). These are observations, not promised counts or coverage percentages.0requests continued pagination, not a guarantee of every reported reply. - Inline nested replies only. Included children carry source-derived level and nullable parent links. Anonymous separate child expansion is unavailable and is never called. Disabling nested replies keeps direct replies only.
- Cursor guards. Pagination stops on exhaustion, an empty cursor, a repeated cursor, a result cap, deadline or run budget. Empty/repeated cursors and deep source errors mark the input truncated and the run partial; exhaustion and result caps remain complete successes.
STATISTICSrecords each input's reported total, saved count, sort, exhaustion and truncation flags. - Operation changes fail loudly. The actor discovers the GraphQL operation from the page, with CDN-bundle fallback. A critical error on a post’s first GraphQL page triggers one shared rediscovery and retry. Persistent first-page failure or missing post state without a positive not-found signal is
outdated:; the run fails only when nothing was saved. Usable reply connections survive source field errors, which are counted inSTATISTICS.sourceFieldErrors. A critical source error at a deep cursor ends coverage for that post, marks ittruncatedwithcoverageStop: "source_error", and continues with later inputs as a partial success. - Unavailable posts are skipped. An HTTP 404 or the source’s explicit not-found page state marks the input
notFound: true, logs a warning with its URL and continues. This counts as a confirmed empty input. Missing post state alone is an error. - Saved rows survive. Later operation, network, block or time errors produce a partial success when rows were saved. Zero rows with errors fail with
blocked:,network:,timeout:,invalid:,quota:oroutdated:. A confirmed valid empty response succeeds as no results. Infrastructure quota errors fail closed; an exhausted monthly allowance is a graceful successful refusal. - Budgets and restarts. Writes are serialized and bounded; a charge limit ends successfully with
run budget reached. Finite run deadlines stop requests early to save data. After reboot or migration, saved dataset IDs seed deduplication and limits so existing replies are not pushed again.
For reproducibility, keep your input, sort, run ID and dataset. Public replies and ranking can change between runs, and a new run can return a different subset.
Integrations
Use Apify datasets, schedules, webhooks and API clients in your own workflows. n8n and Make can start the actor and consume dataset rows. For spreadsheet analysis, export CSV or Excel and preserve postId, replyId and parentReplyId as text. Your workflow can join rows by postUrl or postId and group replies by author handle without fetching additional profile data.
Support
Open the actor's Issues tab with the run ID, a public post URL, reply order and expected behavior. Do not include tokens, private accounts or account cookies.
More scrapers from this developer
TikTok: TikTok Search Scraper: videos and creators for any keyword, pay per result · TikTok Profile Scraper (Pay Per Result): profiles, followers and latest posts by username · TikTok Comments Scraper: comments and full reply threads from any video · TikTok Hashtag Scraper: videos for any hashtag, with views, likes and music · TikTok Sound & Music Scraper: videos that use a sound or song · TikTok Top Ads Scraper: public Creative Center ad rankings, engagement, media and landing pages
Social & news: Reddit Search Scraper: posts by keyword, subreddit or author · Google News Scraper: Google News results as clean full-text articles
Instagram: Instagram Reel Scraper: public profile reels, plays, captions, music and media URLs · Instagram Comment Scraper: public post and reel comments, likes, timestamps and usernames
E-commerce: Prom.ua Product Search Scraper: Prom.ua product search results, no browser needed · Amazon Product Search & Bestsellers Scraper: search results, Best Sellers and product details from Amazon · AliExpress Search Scraper: aliExpress products by keyword with prices, orders and shipping · AliExpress Product Reviews Scraper: public product reviews, ratings, buyer photos and follow-up feedback
Maps & leads: Google Maps Scraper: places, leads and emails from Google Maps
Ads: Facebook Ad Library Scraper (Meta Ads Library): ads from the Meta Ad Library, with EU reach and payers · Google Ads Transparency Scraper: Google ad creatives by advertiser or domain, with regional details
Video: YouTube Transcript Scraper: transcripts, subtitles and captions from YouTube videos · YouTube Shorts Scraper: Shorts of any channel with exact views, likes and duration · YouTube Channel Scraper: every video of a channel, with channel stats · YouTube Search Scraper: search results and videos for any keyword · YouTube Comments Scraper: comments, replies and likes from any video · Bilibili Comments Scraper: public hot comments and reply threads by video or keyword
Jobs: SEEK Job Listings Scraper: public AU/NZ job listings, salaries and redacted descriptions
FAQ
Why are there fewer rows than the post's reply count?
Anonymous public responses expose a subset. Sorting, visibility, removed replies, source errors and the chosen caps affect coverage. Try recent order when you need a deeper public set. Compare saved counts with reported totals in STATISTICS; neither sort promises completeness.
Does it need a Threads account?
No. Only public post pages and their anonymous reply endpoint are requested. Private content and authenticated child expansion are outside its scope.
Is it legal to scrape Threads replies?
This actor accesses public posts and public author handles/display names without login and does not add contact data. Public content can still contain personal data. Assess your purpose, applicable terms, lawful basis, retention and deletion obligations, and GDPR/CCPA requirements where applicable. Minimize what you retain and respect privacy and data-subject requests. This description is not legal advice.


