
Instagram Post Scraper: Posts, Likes & Captions by Profile
Pricing
from $0.60 / 1,000 posts
Instagram Post Scraper: Posts, Likes & Captions by Profile
Export public Instagram data, no login: posts by profile or post URL, likes, comments counts, captions, locations, images, videos and carousel children.
Pricing
from $0.60 / 1,000 posts
Rating
0.0
(0)
Developer

GoFetch
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Share
Export public Instagram posts by profile or post URL, including likes, comment counts, captions, locations and media URLs. Collect public Instagram data, no login, and export one row per post as CSV, Excel or JSON.
Use it to compare public brand content, collect campaign posts or send engagement data to a reporting workflow. Images, videos and carousels share the same row format.
Quick start
- Enter
nasa,@nike, a profile URL, or a post URL such ashttps://www.instagram.com/p/DewuZccPEQA/. - Set Posts per profile and the run-wide Maximum posts per run.
- Keep the default Apify datacenter proxy, run and export the dataset.
The prefill requests 10 NASA posts. A post URL requests one row. No Instagram account or account cookies are needed.
Call the actor from an Apify integration or over HTTP:
For deeper jobs, start an asynchronous run and read its default dataset after completion. You can connect runs to n8n, Make, Zapier, webhooks or Apify schedules. Keep your token in the integration credential store.
Input
| Field | Default | Meaning |
|---|---|---|
username | Required | 1–100 handles, profile URLs or /p/, /reel/, /tv/ post URLs. Trimmed and deduplicated; handle case is normalized and shortcode case is preserved. Invalid entries are skipped with a warning when valid inputs remain; all-invalid input fails invalid:. |
resultsLimit | 30 | Maximum posts saved per profile, 1–10,000. Each post URL contributes at most one row. |
onlyPostsNewerThan | Unset | UTC YYYY-MM-DD or relative N days. Tests each root timestamp and stops after four consecutive older posts. Up to three old pinned posts can appear first. No pinned-skipping guarantee. |
maxItems | 1000 | Run-wide saved-row cap, 1–100,000. Free-plan limits can reduce it. |
proxyConfiguration | Apify DC | Apify RESIDENTIAL is replaced by datacenter. Paid runs may use their own proxy URLs. Free runs use Apify Proxy only. |
Profiles run in input order. Root requests have bounded concurrency within each grid page, and rows are saved as the walk progresses. Results are deduplicated by post ID across inputs and reboots.
Output
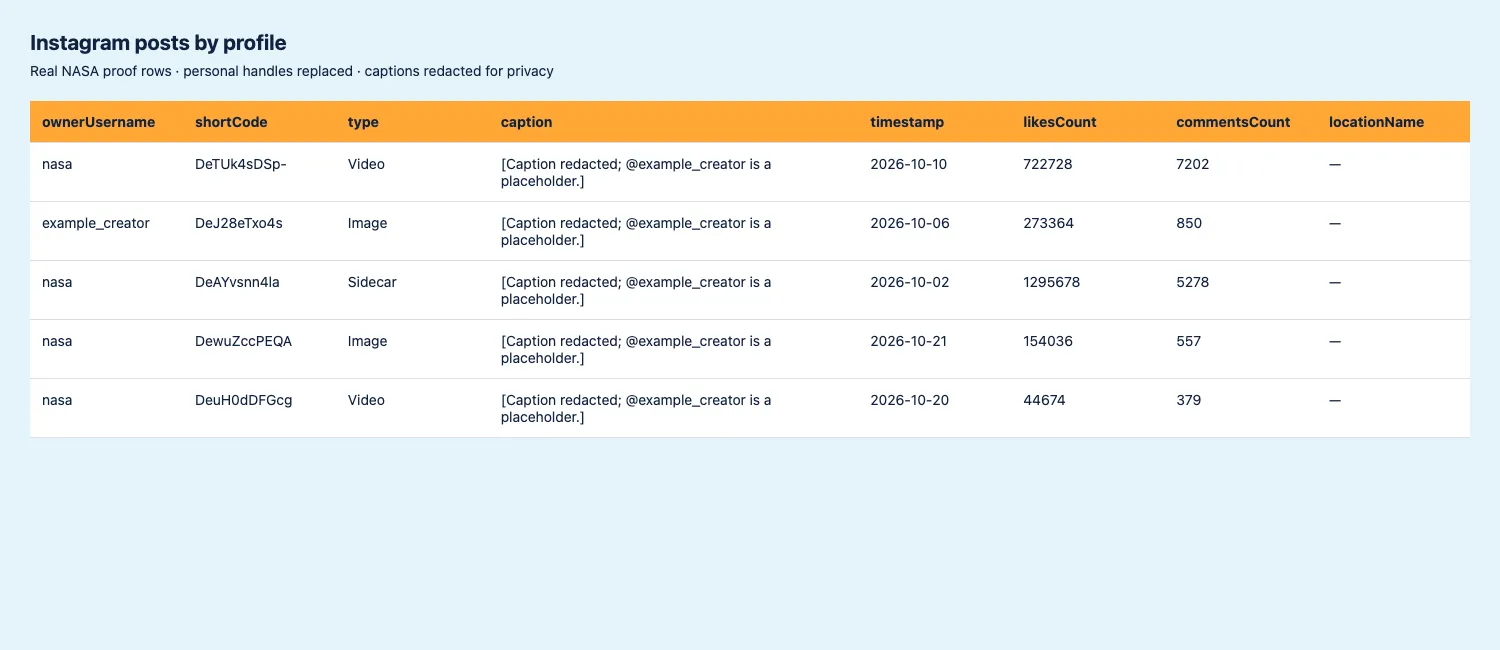
The overview shows URL, owner, type, caption, date, likes, comment count and location. IDs remain strings. Missing scalar values are null; absent collections are empty arrays. Hidden likes remain null.
This example retains identity and counters from a real NASA proof run. Caption text and personal attribution are redacted or replaced with explicit placeholders; signed media URLs are omitted here for readability.
| Fields | Meaning |
|---|---|
id, shortCode, url | Exact media identity and canonical https://www.instagram.com/p/<code>/ URL. |
type, productType | Image, Video or Sidecar, plus the source product type. |
caption, hashtags, mentions, timestamp | Caption text, extracted tags and mentions, and ISO publication time. |
likesCount, commentsCount | Public counters; comment text is separate and excluded. |
displayUrl, videoUrl, videoDuration | Image/video playback URLs and source duration in seconds, when present. URLs expire. |
images, childPosts | Carousel image URLs and children with id, type, displayUrl, videoUrl; empty for other types. |
dimensionsHeight, dimensionsWidth | Source media dimensions. |
locationName, locationId | Tagged location, when supplied; a null location is valid. |
coauthorProducers, taggedUsers | Source-supplied usernames without profile enrichment. |
isCommentsDisabled | Source comments setting when available. |
ownerUsername, ownerId, ownerFullName | Public media owner; collaborative posts may name another owner. |
inputUrl, scrapedAt | Original input and ISO collection time. |
Harmless source errors in location pictures or tagged-user objects do not discard a valid post. A malformed or mismatched post root is reported as an input failure.
Pricing and free-plan limits
Billing uses the saved dataset-item event, titled Post. There are no actor start or add-on fees.
| Apify plan | USD per 1,000 posts |
|---|---|
| Free | $0.78 |
| Bronze | $0.72 |
| Silver | $0.66 |
| Gold | $0.60 |
| Platinum / Diamond | $0.60 |
Examples: 10 posts cost $0.0078 at the Free rate; 100 cost $0.072 on Bronze; 1,000 cost $0.60 on Gold. Fewer saved rows mean fewer result events.
Is it free?
The developer limit on the Apify free plan is 100 results per run and 20 runs per calendar month (UTC). Free-tier result events consume available Apify credits at the rate above; the cap does not waive fees. Monthly reservations are atomic across concurrent runs and reset on the 1st. After the monthly limit, a run succeeds with a quota message before any target requests. Paid plans use the requested caps. Free runs use Apify Proxy only.
Coverage and failure handling
The actor follows the public Posts-tab grid and hydrates each post from its public root. It stops at a clean source end, requested cap, four consecutive older posts, or a bounded failure. It does not download media or accumulate an entire profile in memory.
Unknown/private/unavailable inputs are counted separately when Instagram confirms their status. An individual input failure ends that input and allows later inputs to run. A global grid-query schema change ends the run. Saved rows survive later errors with a successful partial status. Zero rows succeed for confirmed empty outcomes; processing errors fail with blocked:, network:, timeout:, invalid:, quota: or outdated:. Missing/repeated cursors or repeated pages with more available are counted as truncations, never clean ends.
The actor stops starting requests before its platform deadline to flush rows and STATISTICS. A result-event ceiling ends successfully with run budget reached. Dataset rows seed deduplication and caps after a reboot. Check STATISTICS for per-input outcomes, requests, refusal codes, bytes, truncations and elapsed time.
Residential Apify Proxy is not used by this actor: an Apify RESIDENTIAL group is replaced by datacenter, with a warning and STATISTICS.proxyOverride = "RESIDENTIAL->DATACENTER". Datacenter measured 0 refusals in the build proof. Paid runs can use their own proxy URLs for another route. A 300-post build proof measured about $0.028/1,000 posts in datacenter platform usage. This is a measured sample, not a price quote or reliability guarantee. Every retry uses fresh public guest tokens and a fresh proxy session. The guest-visible inventory and ordering can change, and counters or media URLs may differ from the app. Relative dates are evaluated at run start. No promise covers every post ever published.
What's not included
Video views/plays, pinned flags, latest comments, downloads, private profiles, account access or contact enrichment are excluded. For video engagement fields use our Instagram Reel Scraper; for comment text use our Instagram Comment Scraper. These sibling links come from the live developer catalog.
FAQ
Why did I receive fewer posts than requested?
The source may expose fewer posts; duplicates, dates, an unavailable input, the free cap, deadline or run budget can also reduce results. Inspect the input outcomes in STATISTICS for a clean end versus truncation.
Why are locations, duration or likes null?
The source may not supply them. Hidden likes remain null; null does not mean zero. A field-level source error can also remove an optional value while preserving the post.
Is it legal to scrape public Instagram data?
This actor accesses publicly available data without an account. You are responsible for checking your purpose, applicable terms and laws, including GDPR/CCPA obligations where relevant. Public information can still be personal data: minimize collection, respect deletion requests and avoid unwanted contact.
Where can I get help?
Use the Apify Issues tab with the run ID, input shape and affected public profile or post. Never include credentials. Logs and STATISTICS distinguish refusals, transport faults and pagination changes.
More scrapers from this developer
TikTok: TikTok Search Scraper: Videos and creators for any keyword, pay per result · TikTok Profile Scraper (Pay Per Result): Profiles, followers and latest posts by username · TikTok Comments Scraper: Comments and full reply threads from any video · TikTok Hashtag Scraper: Videos for any hashtag, with views, likes and music · TikTok Sound & Music Scraper: Videos that use a sound or song · TikTok Top Ads Scraper: Public Creative Center ad rankings, engagement, media and landing pages
Social & news: Reddit Search Scraper: Posts by keyword, subreddit or author · Google News Scraper: Google News results as clean full-text articles · Threads Replies Scraper: Public post replies, likes, authors and inline nested replies · VK Posts Scraper: Public wall posts, engagement counts, repost context and attachment metadata
Instagram: Instagram Reel Scraper: Public profile reels, plays, captions, music and media URLs · Instagram Comment Scraper: Public post and reel comments, likes, timestamps and usernames
E-commerce: Prom.ua Product Search Scraper: Prom.ua product search results, no browser needed · Amazon Product Search & Bestsellers Scraper: Search results, Best Sellers and product details from Amazon · AliExpress Search Scraper: AliExpress products by keyword with prices, orders and shipping · AliExpress Product Reviews Scraper: Public product reviews, ratings, buyer photos and follow-up feedback
Maps & leads: Google Maps Scraper: Places, leads and emails from Google Maps
Ads: Facebook Ad Library Scraper (Meta Ads Library): Ads from the Meta Ad Library, with EU reach and payers · Google Ads Transparency Scraper: Google ad creatives by advertiser or domain, with regional details
Video: YouTube Transcript Scraper: Transcripts, subtitles and captions from YouTube videos · YouTube Shorts Scraper: Shorts of any channel with exact views, likes and duration · YouTube Channel Scraper: Every video of a channel, with channel stats · YouTube Search Scraper: Search results and videos for any keyword · YouTube Comments Scraper: Comments, replies and likes from any video · Bilibili Comments Scraper: Public hot comments and reply threads by video or keyword
Jobs: SEEK Job Listings Scraper: Public AU/NZ job listings, salaries and redacted descriptions


