
Cutshort Jobs Scraper | Salaries, Skills and Companies
Pricing
from $1.53 / 1,000 jobs
Cutshort Jobs Scraper | Salaries, Skills and Companies
Cutshort scraper for tech jobs in India: get 50 jobs in 3 seconds with 41 fields each, including salary range, experience, skills, remote policy, posting date, recruiter and the hiring company's website, LinkedIn, size and stage. Search by keyword, city, Cutshort URL or job ID. No account needed.
Pricing
from $1.53 / 1,000 jobs
Rating
0.0
(0)
Developer
SilentFlow
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
an hour ago
Last modified
Categories
Share
Cutshort Jobs Scraper | Tech Jobs, Salaries and Hiring Companies in India (2026)
From SilentFlow. Creators of Pinterest Scraper and Leboncoin Scraper, with 420,000+ combined lifetime runs.
Every Cutshort job as one clean row: the role, the salary band in numbers, the experience range, the skills, the workplace, the posting date, the recruiter, and the company behind it with its website, LinkedIn, size, stage and founding year. Type a skill, paste a Cutshort link or give the job codes you already track, and get a table you can filter, chart, load into a CRM or feed to a job board. The default input returned 50 Python jobs in 14 seconds on 11 Oct 2026.
Why choose this actor?
Copying Cutshort jobs into a spreadsheet one card at a time? Getting a salary like "₹8L - ₹24L / yr" as text you still have to split into numbers? Finding a company that is hiring for your stack, then opening three more tabs to get its website, its LinkedIn and its size?
- 38 fields per job, filled from the job list itself. On the default run (keyword
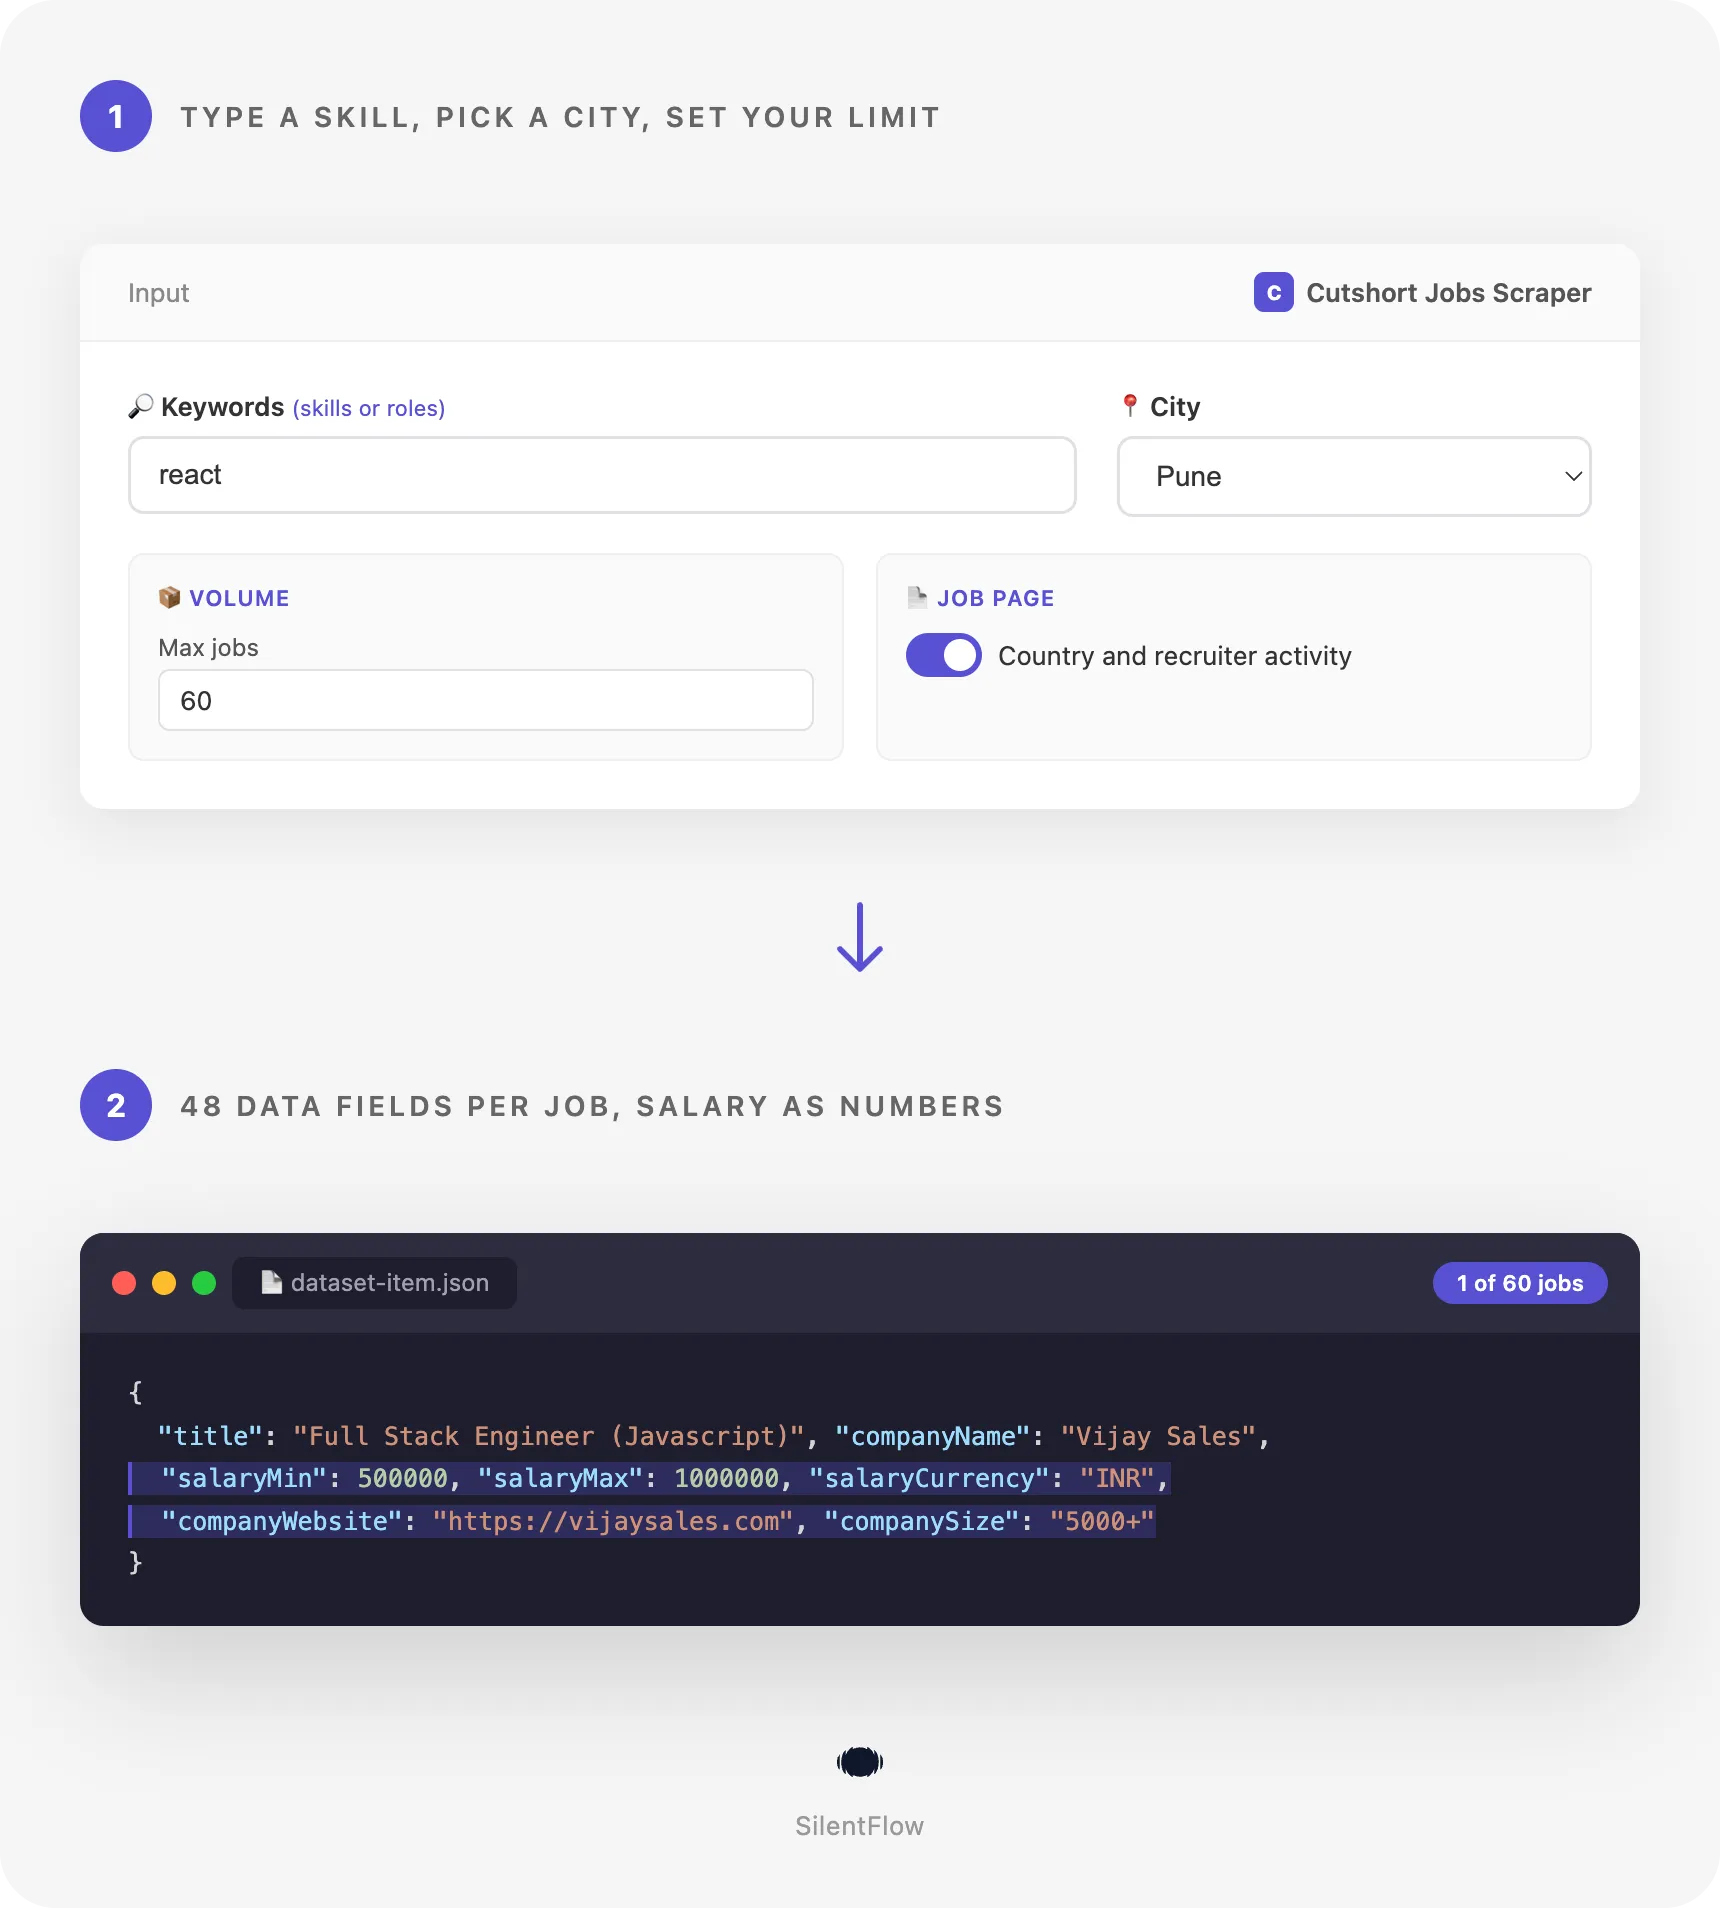
python, 50 jobs, 11 Oct 2026), 38 data fields carried a value on at least half of the rows and 28 on every single row: title, skills, employment type, salary minimum and maximum with currency and period, experience range, location list, workplace type, posting date, recruiter, apply link, and the hiring company's name, logo and Cutshort page. Turn on one option and the job page adds the country, postcode, job category and tags, and the recruiter's last activity: 43 fields on at least half of the rows on a 60-job React run in Pune. - The hiring company on the same row, ready for outreach. 12 of those fields describe the company that posted the job: its name, Cutshort id and page, logo, website, LinkedIn page, team size, funding stage, company type, founding year, follower count and description, with its tech stack when the company lists one. On the default run, 41 of 50 jobs came with the company website and 36 with its LinkedIn page, with no second tool and no extra step. When a recruitment agency posts for an unnamed client, the row says so in
isHiringForClientand names the agency inagencyName. - Three ways in: keywords, Cutshort links and job IDs. Type skills or roles (
react,sales,product manager), paste any Cutshort link (a job list, a city list, a company page, or one job), or list the 8-character codes that end a job link to refresh the jobs you already track. On 11 Oct 2026, one run mixing a company page, the remote Golang list and two job codes returned 80 jobs, the two tracked jobs first.
Try your first Cutshort job search
Paste this input into the Input tab (JSON view) and press Start. It is the default input of the form: the newest Python jobs on Cutshort, up to 50.
The Apify Free plan is enough to run it and to try the actor on your own skills, cities and companies: no credit card, no Cutshort account, no setup. Each job becomes one row of the dataset, which you can export as JSON, CSV or Excel, open in Google Sheets, or read from the Apify API. On 11 Oct 2026 this input returned 50 jobs posted between 5 and 10 October, 19 of them for Bengaluru only, with salaries quoted in INR and skills such as Python, SQL, AWS, React.js, Generative AI, PySpark and PostgreSQL.
Copy to your AI assistant
Paste this block into Claude, ChatGPT or Cursor to give it the full context of this actor:
How to scrape Cutshort jobs
Get the newest React jobs in India
One keyword, no filter. The run reads the React list newest first and stops at 100 jobs.
Pull remote Python jobs posted this week
Remote only, last 7 days. The run uses Cutshort's remote list for the skill when there is one, and stops reading as soon as it reaches older jobs.
Compare data and DevOps salaries in Bengaluru
Two roles, one city, one month, with the job page details. Each row carries the salary band as numbers in salaryMin and salaryMax, next to experienceMinYears, so you can chart pay against seniority in a spreadsheet.
Input parameters
| Parameter | Type | Default | What it does |
|---|---|---|---|
searchQueries | array | none (the form suggests python) | Skills or roles. Each is matched to the closest Cutshort job category: react reads React.js jobs, node.js Node.js jobs, go Golang jobs, data scientist Data Science jobs. |
startUrls | array | none | Cutshort links: job lists, city lists, remote lists, company pages, single jobs. |
jobIds | array | none | Job codes, job ids or job links. Read before anything else. |
location | string | all of India | One of the 14 cities Cutshort keeps lists for, by code or name, or any other place to filter on. |
remoteOnly | boolean | false | Keep only fully remote and remote-friendly jobs. |
postedWithinDays | integer | none | Keep only jobs posted in the last N days. |
maxItems | integer | 100 | Cap on rows across all keywords, links and IDs. No fixed upper limit. |
includeDetails | boolean | false | Add country, postcode, category, tags and last recruiter activity from each job page. |
debugMode | boolean | false | Detailed logs for support. |
Formats accepted. Keywords ignore case and punctuation: React.js, react and REACT are one search, ui/ux and UI UX too, and a trailing "jobs" is dropped. Cities read by code (bangalore-bengaluru), by Cutshort's name (Bengaluru (Bangalore)), or by the name people type (Bangalore, BLR, Gurugram, Noida, New Delhi, Bombay, Cochin, Calcutta), with or without a state after a comma. Job IDs read as the 8-character code (Se3ugX4F), the 24-character id, a job link, or the apply link of a job. Links work with or without https:// and www..
What gets combined. Keywords, links and IDs add up in one run, and a job reached twice is saved once. The city, remote and date filters narrow keywords, job lists and company pages, and they combine: python with remoteOnly and postedWithinDays: 7 returns the remote and remote-friendly Python jobs of the last seven days. Jobs asked by ID are always returned as asked.
What data can you extract from Cutshort?
Each row holds 48 fields in eight groups:
- Identity (4):
idis Cutshort's own id of the job, stable for its whole life;shortIdis the 8-character code that ends the job link;urlis the public job page;titleis the role as posted. - Content (7):
descriptionin plain text, one paragraph or bullet per line, anddescriptionHtmlas Cutshort shows it;skillsas the employer tagged them;employmentTypes(full-time,internship);categories, the Cutshort job families the posting belongs to (Fullstack Developer,Backend Developer); and, from the job page,category(tech) andtags(fullstack,frontend). - Company (15):
companyName,companyId,companyUrl(its Cutshort page),companyLogo,companyWebsite,companyLinkedin,companyDescriptionin plain text,companyType(Product, Services, Products & Services),companyStage(Bootstrapped, Raised funding, Profitable),companySize(0-20to5000+),companyFoundedYear,companyFollowerson Cutshort,companyTechStack, andisHiringForClientwithagencyNamewhen an agency posts for a client. - Recruiter (2):
recruiterName, the person who posted the job, andrecruiterPhotoUrl. - Pay and experience (8):
salaryMinandsalaryMaxas whole numbers,salaryCurrency,salaryPeriod,salaryTextexactly as Cutshort writes it (₹8L - ₹24L / yr),isSalaryHidden,experienceMinYearsandexperienceMaxYears. - Place and time (8):
locationas shown,locationsas a list,workplaceType(onsite,remote,remote-friendly),isRemote, and from the job pagecountryCodeandpostalCode;postedAtandlastActiveAt(the recruiter's last activity on the job), RFC 3339 in UTC. - Links (1):
applyUrl, the Cutshort page where a candidate applies. - Meta (3):
searchQueryandsourceUrl, the keyword and the list or company page that found the job, andscrapedAt.
What stays empty, and why: the company block is empty when an agency hides its client's name (10 of 50 rows on the default run), and Cutshort shows that client under a generic name such as "AI-Powered Technology Company". Smaller companies leave their size, stage or LinkedIn blank on Cutshort, so those fields follow (34 of 50 rows had a size and a stage). locations is empty on fully remote jobs, where location reads "Remote only". The job-page fields are null unless includeDetails is on or the job was read by ID.
Output example
One real row from a React run in Pune on 11 Oct 2026 with includeDetails on. The three long texts are shortened here for reading; the dataset holds them in full.
Advanced usage
Track every open job of a company
Paste a company page to get all its open jobs, page after page. Run it weekly against your competitors or your target accounts and compare the job ids between runs to see what opened and what closed. On 11 Oct 2026 one company page returned its 25 open jobs over three pages.
Refresh the jobs you already track
Keep the shortId of the jobs in your pipeline and read them again by ID: each comes back with its current salary, location and last recruiter activity, plus the job-page fields. A job that was closed or removed is named in the log and never saved as an empty row.
Build a list of companies hiring for your stack
Run several skills at once without a city: each keyword reads its national list, then each city list, and a job found twice is saved once. On 11 Oct 2026 the keyword python alone gave 1,500 distinct jobs in 4 minutes 40 seconds before reaching the cap. Group the dataset by companyId to get one line per company, with its website, LinkedIn, size and stage, and the roles it is hiring for.
Read one Cutshort list exactly as the site shows it
When you already filtered on Cutshort, paste the list link. City lists and remote lists work the same way, and the remote, date and city filters still apply on top if you set them.
Feed a daily job board or Slack channel
Schedule this input every morning in Apify (Schedules tab). With postedWithinDays: 1 each run only saves the jobs posted in the last 24 hours and stops reading as soon as it reaches older ones, so the daily dataset is your new-jobs feed. Connect a webhook, Make, Zapier or Google Sheets integration to push it where your team reads it.
FAQ
What is Cutshort? Cutshort (cutshort.io) is an Indian hiring platform for tech and startup jobs, where companies and recruiters post roles with a salary band, an experience range and skills. Its jobs cluster in India's tech hubs, Bengaluru first, then Mumbai, Delhi NCR, Hyderabad, Pune and Chennai, plus remote roles.
Do I need a Cutshort account? No. The actor reads the job pages anyone can open without logging in. No account, no password, no API key.
How many jobs can one keyword return?
A Cutshort job list holds a few hundred jobs, newest first. Without a city, the actor continues with that skill's city lists and removes repeats, so one keyword can go well past one list: python returned 1,500 distinct jobs on 11 Oct 2026 before reaching the maxItems cap. Set maxItems to what you need.
Which keywords work?
Skills and roles as Cutshort names its categories: languages and tools (python, java, react, node.js, golang, kubernetes, aws, salesforce), roles (product manager, data engineer, devops, android, frontend, backend, full stack) and functions (sales, marketing, hr, business development, customer success). A keyword that matches no Cutshort category is named in the log, and the rest of the run goes on.
How fresh is the data?
Jobs are read when the run starts, at most an hour behind the site. postedAt is the posting date Cutshort shows, and lastActiveAt (with includeDetails) the last time the recruiter acted on the job, which tells an active job from a quiet one.
Why is the company name sometimes generic?
Recruitment agencies post some jobs for clients they do not name. Cutshort then shows a description such as "AI-Powered Technology Company" instead of the client. The row keeps that name in companyName, sets isHiringForClient to true, and names the agency in agencyName, so you can keep or drop those jobs. When the client has no name at all, companyName is the agency, as on Cutshort's own job page.
Why does a job say "Best in industry" but still have a salary range?
Some employers hide the salary on the page. Cutshort still holds the band they entered, and the actor returns it in salaryMin and salaryMax with isSalaryHidden set to true, so you can include or exclude those rows in a salary study.
Does it cover jobs outside India?
Yes when Cutshort lists them: remote roles and jobs abroad, such as postings in the United Arab Emirates, come with their location, and salaries in USD or SGD keep their currency in salaryCurrency. The 14 city lists are Indian cities; type any other place in the city field to keep the jobs whose location names it.
Can I run several keywords, cities or companies in one run? Several keywords, links and job IDs, yes, in one run, with repeats removed. The city field takes one city per run; run the actor once per city, or leave the city empty to cover every city list.
Are the links permanent?
url, companyUrl and applyUrl stay valid while the job and the company page are online on Cutshort. id and shortId never change for a job, so they are the keys to use when you compare runs. Logos and recruiter photos are plain image links.
More SilentFlow scrapers
🛒 E-commerce
 Pinterest - Pinterest Scraper | Pins, Boards and Profiles
 Leboncoin - Leboncoin Scraper | Classified Ads, Prices and Sellers
 Leboncoin - Leboncoin Ad Details Scraper
 Back Market - Back Market Scraper | Refurbished Prices
 ImportYeti - US Customs Records, Suppliers & Trade Data - ImportYeti Scraper - US Customs Records, Suppliers & Trade Data
 TikTok Shop - TikTok Shop Scraper | Products, Sellers and Creator Videos
 1688 Wholesale - 1688 Wholesale Scraper
 Naver - Naver Scraper | Shopping Products, Prices and Reviews
 Udemy Course - Udemy Course Scraper
 JD - JD Products Scraper | Prices, Brands and Barcodes
 Store Leads Ecommerce - Store Leads Ecommerce Scraper
 Amazon Seller - Amazon Seller Scraper | Emails, Phones and Ratings
 Naver - Naver Reviews Scraper | Shopping Product Reviews
 Bring a Trailer - Bring a Trailer Scraper
 Lowes - Lowes Products Scraper | Prices, Stock and Specs
 Store Leads - Store Leads Scraper | Shopify Data
 Avito - Avito Scraper | Listings, Prices and Sellers
 Leboncoin - Leboncoin Scraper
 Mobile.de - Mobile.de Scraper
 Naver - Naver Products Scraper | Shopping Prices, Sellers and Ratings
 Taobao - Taobao Scraper | Products, Prices and Sellers
 Udemy - Udemy Scraper
 Agoda - Agoda Scraper | Hotel Prices and Guest Ratings
 Alibaba - Alibaba Products Scraper | Wholesale Prices and MOQ
 AliExpress - AliExpress Reviews Scraper | Feedback, Ratings and Photos
 AliExpress - AliExpress Scraper | Products, Prices and Sales
 Allegro - Allegro Scraper | Products, Prices and Sellers
 Avito - Avito Profiles Scraper | Sellers, Ratings and Reviews
 Back Market - Back Market Scraper | Refurbished Electronics Prices
 BAUHAUS - BAUHAUS Scraper | Product Prices, EAN and Specs
 CARFAX - CARFAX Scraper | Used Cars, Prices and History
 Coupang - Coupang Detail Scraper | Product Prices and Options
 Ctrip - Ctrip Scraper | Attractions, Tickets and Reviews
 eBay Marketplace - eBay Marketplace Scraper
 Europages - Europages Scraper | Suppliers and B2B Companies
 Eventim - Eventim Scraper | Events, Ticket Prices and Venues
 GasBuddy - GasBuddy Scraper | Gas Prices by Station
 Google Hotels - Google Hotels Scraper | Prices, Offers and Ratings
 Homedepot - Homedepot Reviews Scraper | Customer Reviews and Ratings
 Leboncoin - Leboncoin Details Scraper | Full Ad Data and Sellers
 Mercari - Mercari Scraper | Listings, Sold Prices and Sellers
 Vinted Marketplace - Vinted Marketplace Scraper
 Walmart - Walmart Product Scraper
 Alibaba - Alibaba Scraper | Products, Prices and Suppliers
 Amazon - Amazon Product Scraper
 Amazon Marketplace - Amazon Marketplace Scraper
 AutoScout24 - AutoScout24 Scraper
 eBay Listings - eBay Listings Scraper
 Europages Deep Dive Extractor - Europages Deep Dive Extractor | VAT, Decision Makers, ISO Certs
 Pinterest - Pinterest Scraper
 Trip - Trip Scraper | Hotels, Prices and Reviews
 Vinted - Vinted Scraper
 Walmart - Walmart Scraper | Prices, Reviews, Sellers, Availability
💼 Jobs
 ZipRecruiter - ZipRecruiter Jobs Scraper | Salary, Company & Location Filters
 Indeed - Indeed Company Reviews Scraper
 Multi Board - Multi Board Job Scraper
 Glassdoor Job Listings - Glassdoor Job Listings Scraper
 🔥 Glassdoor - 🔥 Glassdoor Scraper
 LinkedIn Job Search - LinkedIn Job Search Scraper | Salaries & Seniority
 ATS - ATS Jobs Scraper | Greenhouse, Lever and Ashby
 Dice Tech - Dice Tech Jobs Scraper
 iimjobs - iimjobs Scraper | Jobs, Companies and Recruiters
 Jora - Jora Jobs Scraper
 Malt Freelancer - Malt Freelancer Scraper
 Malt - Malt Scraper | Freelance Profiles
 Welcome to the Jungle - Welcome to the Jungle Job Scraper
 All - All Jobs Scraper
 Arbeitsagentur - Arbeitsagentur Jobs Scraper
 Dice - Dice Jobs Scraper | US Tech Jobs, Salaries, Skills
 Glassdoor - Glassdoor Jobs Scraper
 Indeed - Indeed Jobs Scraper | Job Listings in 73 Countries
 Jora - Jora Scraper | Jobs in Australia, New Zealand, Singapore
 StepStone - StepStone Scraper
 YCombinator - YCombinator Jobs Scraper | Startup Jobs, Salaries and Founders
 Arbeitsagentur - Arbeitsagentur Scraper | German and Austrian Job Board
 Indeed - Indeed Companies Scraper | Reviews, Salaries, Interviews
 Indeed - Indeed Jobs Scraper | NLP Skills
 LinkedIn - LinkedIn Jobs Scraper
 Naukri & NaukriGulf - Naukri & NaukriGulf Jobs Scraper
 Seek - Seek Job Scraper
 Welcome to the Jungle - Welcome to the Jungle Scraper | Jobs and Company Data
 Ziprecruiter - Ziprecruiter Scraper
🏠 Real estate
 SeLoger - SeLoger Scraper | Real Estate Listings
 Anjuke - Anjuke Scraper | Rental Listings, Prices and Agents
 Realtor Rental Listings - Realtor Rental Listings Scraper
 Airbnb Pro Host Contact & - Airbnb Pro Host Contact & Email Scraper
 Bien'ici - Bien'ici Scraper | Property Listings
 Rightmove - Rightmove Scraper
 Trulia Rental Listings - Trulia Rental Listings Scraper
 Airbnb Professional Host - Airbnb Professional Host Scraper | Emails, Phones, SIRET
 Airbnb Search - Airbnb Search Scraper
 Bienici - Bienici Scraper
 Idealista - Idealista Scraper
 Realestate.com.au - Realestate.com.au Scraper
 SeLoger - SeLoger Scraper | French Property Listings and Agencies
 Zillow - Zillow Scraper
 Airbnb Search - Airbnb Search Scraper | Prices, Fees, Amenities, Hosts
 Idealista - Idealista Scraper
 Realtor Rental - Realtor Rental Scraper
 Trulia Rental - Trulia Rental Scraper | US Rentals, Prices, Pet Policy
📣 Social media
 LinkedIn Post Search - LinkedIn Post Search Scraper | Keywords, Hashtags & Profiles
 Facebook Search - Facebook Search Scraper
 Instagram - Instagram Story Scraper | Stories & Highlights
 LinkedIn Leads - LinkedIn Leads Scraper | Sales Navigator Export
 TikTok - TikTok Scraper
 YouTube - YouTube Channel Scraper | Videos, Shorts and Views
 Instagram Engagement - Instagram Engagement Scraper
 Facebook Search - Facebook Search Profiles Scraper | People by Name or Keyword
 Meta Ad Library - Meta Ad Library Scraper
 OnlyFans - OnlyFans Profile Scraper
 TikTok Trend - TikTok Trend Scraper | Trending Hashtags and Videos
 OnlyFans - OnlyFans Creator Scraper
 Skool Community - Skool Community Scraper
 Bilibili - Bilibili Scraper
 Facebook Thread - Facebook Thread Profiles Scraper | Followers, Bios & Engagement
 Kuaishou - Kuaishou Scraper | Videos, Comments and Creator Stats
 LinkedIn Event - LinkedIn Event Scraper
 Reddit - Reddit Scraper | Posts, Comments and Subreddits
 Reddit - Reddit Scraper | Comments, Posts and Users
 Snapchat - Snapchat Contacts Scraper | Phones, Emails and Websites
 Weibo - Weibo Scraper | Posts, Profiles and Engagement
 Xigua - Xigua Scraper | Videos, Creators and Downloads
 Discord - Discord Scraper | Servers, Member Counts and Invites
 Facebook - Facebook Company Scraper | Emails, Phones, Ratings
 Facebook Business Page - Facebook Business Page Scraper
 Kwai - Kwai Scraper | Videos, Creators and Hashtags
 LinkedIn Ads Library - No Cookies - LinkedIn Ads Library Scraper - No Cookies
 LinkedIn Hashtag & - LinkedIn Hashtag & Post Scraper | No Cookies
 Skool Group - Skool Group Scraper
 Snapchat - Snapchat Ads Scraper | Ad Library, Impressions & Targeting
 YouTube - YouTube Transcript Scraper
🏢 Business data
 Tencent - Tencent Scraper | Maps Places, Phones and Ratings
 LinkedIn People Search - LinkedIn People Search Scraper | Profiles & Companies
 LinkedIn Company Search - LinkedIn Company Search Scraper | Profiles & Firmographics
 Company Data - Company Data Scraper | Emails, Phones and Tech Stack
 FanDuel - FanDuel Scraper | Odds, Spreads and Player Props
 ForexFactory - ForexFactory Scraper | Economic Calendar and Forecasts
 Justdial - Justdial Companies Scraper | Business Leads, Phones and Emails
 Kakao - Kakao Scraper | Map Places, Reviews and Phones
 OpenTable - OpenTable Reviews Scraper | Restaurant Reviews and Ratings
 SoftwareAdvice - SoftwareAdvice Scraper | Reviews, Ratings and Pros & Cons
 Teachable Course - Teachable Course Scraper
 Zomato - Zomato Reviews Scraper | Restaurant Ratings and Replies
 2GIS - 2GIS Reviews Scraper | Ratings, Photos and Owner Replies
 LinkedIn Sales Navigator - LinkedIn Sales Navigator Scraper
 Teachable - Courses, Prices & Instructors - Teachable Scraper - Courses, Prices & Instructors
 Trustpilot - Trustpilot Scraper | Reviews, Ratings and Company Contacts
 Website Tech Stack - Website Tech Stack Scraper
✈️ Travel
 Google Maps - Google Maps Scraper
 Booking.com Hotel - Booking.com Hotel Scraper
 Flight Price - Flight Price Scraper
 Trip - Trip Reviews Scraper | Hotel Reviews and Ratings
 Booking - Booking Scraper | Hotel Prices, Photos, Availability
🎯 Lead generation
 Northdata - Northdata Company Scraper
 ZocDoc - ZocDoc Scraper | Doctors, Reviews and Availability
 UK Companies House - UK Companies House Enricher
 Dealroom - Dealroom Scraper | Companies and Investors
 CNPJ Brazilian - CNPJ Brazilian Company Enricher
 Google Ads Transparency - Google Ads Transparency Scraper
 SIRET - SIRET Company Enricher
 BuiltWith - BuiltWith Scraper | Tech Stacks and Top Sites
 Domain - Domain Enricher
 French Company Prospector - French Company Prospector
 SEC - SEC Scraper | EDGAR Filings and Company Data
 USPTO - USPTO Scraper | Trademark Search and Status
 ZocDoc - ZocDoc Scraper
 Clutch - Clutch Scraper | Agencies, Reviews, Ratings, Services
 Clutch Agency - Clutch Agency Scraper
 Dealroom Startup Data - Dealroom Startup Data Scraper
 G2 - G2 Reviews Scraper
 PagesJaunes - PagesJaunes Scraper | French Business Emails and SIRET
 PagesJaunes - PagesJaunes Business Scraper
 SIRET French - SIRET French Company Enricher
 ThomasNet Suppliers - ThomasNet Suppliers Scraper
🔎 SEO
 Similarweb - Similarweb Scraper | Website Traffic, Rankings and Competitors
 Google News - Google News Scraper
 Apple - Apple Scraper | App Store Apps, Ratings and Charts
📈 Marketing
 Pexels -
🧰 More tools
 PrizePicks - PrizePicks Scraper | Player Props, Lines and Projections
 Apple - Apple Reviews Scraper | App Store Reviews and Ratings
Support
Need something this scraper does not do yet? We ship features fast.
- Feature requests go straight to our backlog
- Enterprise needs? We do custom integrations and high-volume plans
- Pricing questions? Check the Monetization tab on the actor page
Response time: usually under 24 hours.
Legal compliance
This Actor extracts publicly available data from Cutshort: job postings and company profiles that anyone can open without an account. It does not bypass any login, paywall, or CAPTCHA, and it reads no candidate profile or application. Users are responsible for complying with Cutshort's terms of service and applicable data protection laws (GDPR, CCPA, PIPL, and India's DPDP Act where relevant). Rows include the names and photos of the recruiters who posted the jobs, which are personal data: handle them accordingly and only for a lawful purpose. The data returned is informational; verify it before any regulated use.
Built by SilentFlow for recruiters, sales teams, salary analysts and job boards who want Cutshort's jobs as data, not browser tabs.


