
YCombinator Jobs Scraper | Startup Jobs, Salaries and Founders
Pricing
from $0.04 / 1,000 jobs
YCombinator Jobs Scraper | Startup Jobs, Salaries and Founders
YCombinator jobs scraper: export open jobs at Y Combinator startups by keyword, YC URL or company. 100 jobs in 13 seconds, 53 fields each: title, full description, salary and equity as numbers, posting date, apply link, hiring manager, plus company batch, team size and founders. No account.
Pricing
from $0.04 / 1,000 jobs
Rating
0.0
(0)
Developer
SilentFlow
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
a day ago
Last modified
Categories
Share
YCombinator Jobs Scraper | Startup Jobs, Salaries and Founders (2026)
From SilentFlow. Creators of Pinterest Scraper (#1 for “pinterest pins scraper” in Apify Store search) and Leboncoin Scraper Ppe, with 260,000+ combined lifetime runs.
Turn the Y Combinator job board into a table you can sort: every open job at YC startups, with the salary and equity as numbers, the full job description, the exact posting date, the hiring manager, and the company's batch, industry, team size, links and founders on the same row. The prefilled search returned 100 software engineering jobs from 64 YC companies in 13 seconds, no account needed.
Why choose this actor?
Opening YC company pages one by one to find who is hiring, for what, and for how much? Copying salaries written as text into a spreadsheet, then hunting for the founders on another page? Using a YC jobs scraper that only takes a keyword, when what you have is a list of companies or a link to a YC search?
- The job, its pay and its company on one row, without extra options. Each row carries 55 fields, and 51 of them were filled on at least half of the rows of the prefilled run (100 jobs, measured on 7 Oct 2026). The full description, the exact posting date and the founders come by default: 100 of 100 rows had the description and the date, 99 had at least one founder with a LinkedIn link, 95 named the hiring manager.
- Salaries you can sort and filter. The salary text YC shows is kept, and also split into
salaryMin,salaryMax,salaryCurrencyandsalaryPeriod(year, month or hour). On the prefilled run, 96 of 100 jobs came with numeric salary bounds and 50 with numeric equity bounds, ready for a pivot table or a salary benchmark. - Start from what you already have. Type keywords (
software engineer,react,fintech), paste YC links (a company, a single job, a directory search with its batch and industry filters, a jobs page by role or city), or list companies by name (Stripe,noloco). All three can run together, and every filter (location, role, job type, remote, batch) applies to all of them.
Try your first YC jobs export
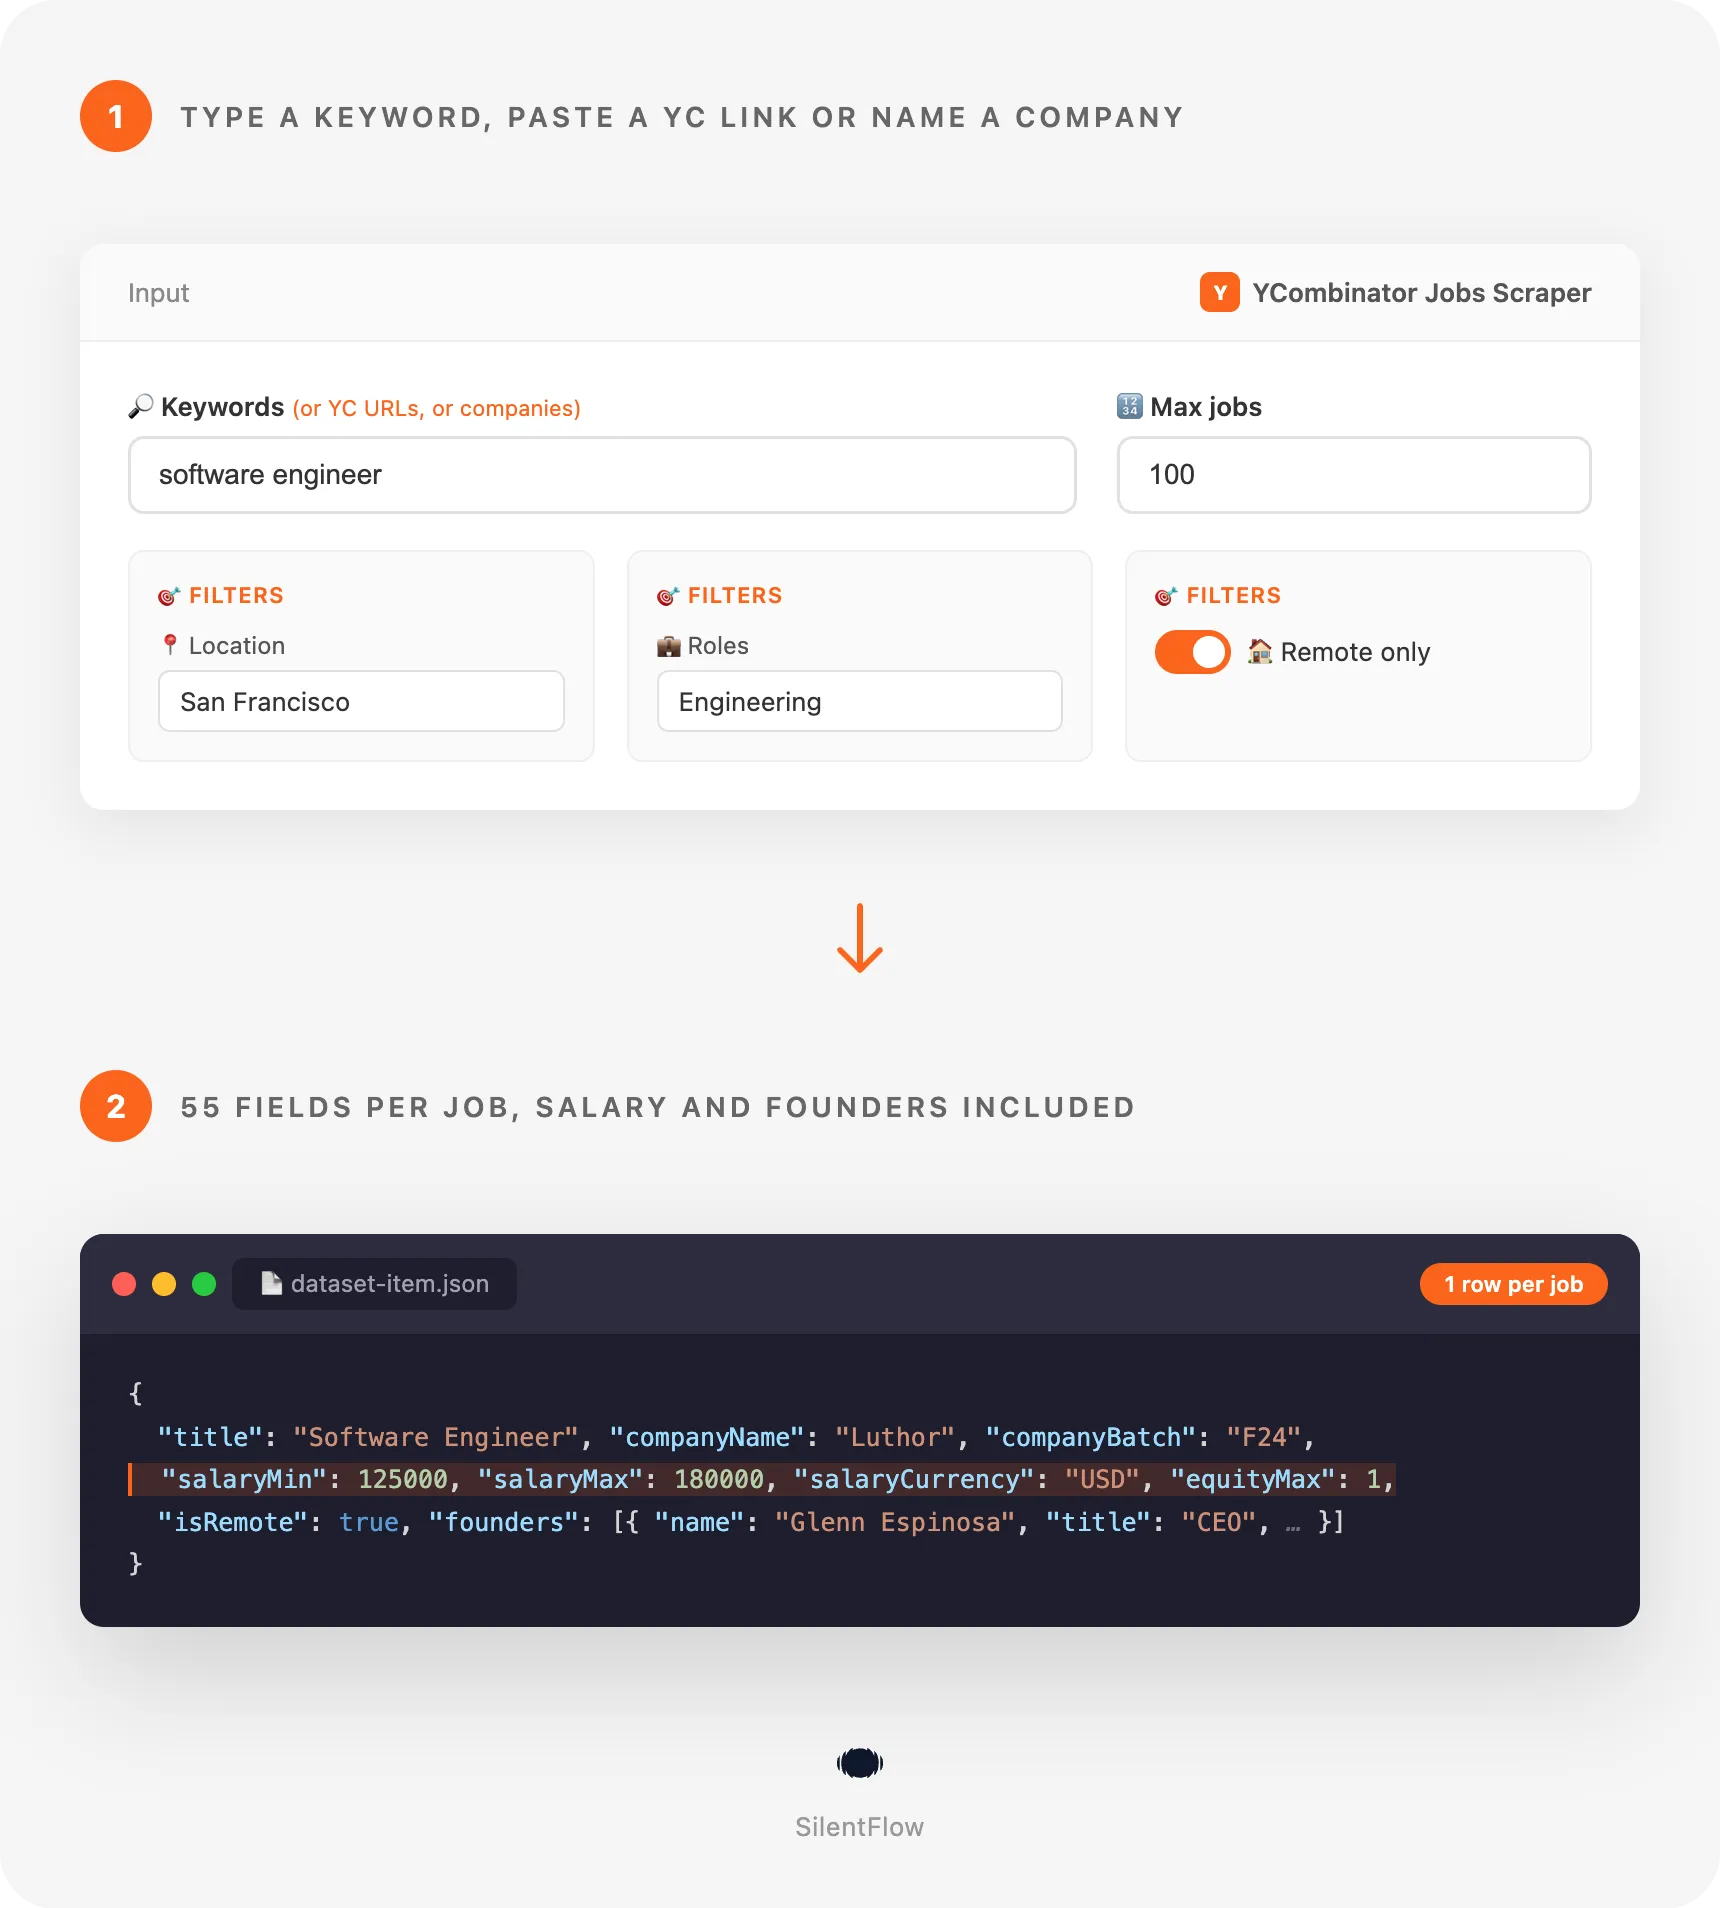
Paste this input into the Input tab (JSON view) and press Start. It is the prefilled input of the form: the first 100 open jobs at YC startups that match software engineer.
Runs of this size fit easily in the Apify Free plan, so you can try the actor on your own searches before scheduling anything. Each job is one row of the dataset; export it as JSON, CSV, Excel or HTML from the Storage tab, or read it from the API. The Jobs view shows the title, company, batch, location, salary, posting date and link at a glance; the Companies view shows the company, batch, industry, team size, headquarters, website, LinkedIn and YC profile.
Copy to your AI assistant
Paste this block into Claude, ChatGPT or Cursor to give it full context about this actor:
How to scrape Y Combinator jobs
Three ways to start, from the simplest to the most targeted. Each block runs as is.
Get the latest software engineering jobs at YC startups
The run reads the YC companies that rank for the keyword first, then every other hiring company, and keeps the jobs whose title, role, specialty or skills match. On the prefilled run, 99 of the 100 titles contained "engineer", "developer" or "technical staff".
Pull every opening of the startups on your watchlist
Names and slugs both work: the actor finds the company on YC when the name is not its exact slug. A company with no opening today is reported in the log and returns no row.
Export remote engineering jobs that list React
This one read 500 YC companies to collect 25 remote engineering jobs that mention React, from 23 different companies, in 31 seconds.
Input parameters
| Field | Type | Default | What it does |
|---|---|---|---|
searchQueries | array of strings | prefilled software engineer | Keywords. Every word must appear in the job (title, role, specialty, skills) or in its company's name, tags or industries. |
startUrls | array of URLs | none | YC company, company jobs page, single job, directory search, or jobs page by role or city. |
companySlugs | array of strings | none | YC companies by name or slug. Every open job of each company. |
location | text or pick | any | City, US state code, Remote, or a country by code, ISO-3 code or English name. |
roles | list | all | Engineering, Design, Product, Science, Sales, Marketing, Support, Operations, Recruiting and HR, Finance, Legal. |
jobTypes | list | all | Full-time, Part-time, Contract, Internship, Cofounder. |
remoteOnly | boolean | false | Only jobs that can be done remotely, including Remote (US) style postings. |
batches | array of strings | all | YC batches: W24, S21, F24 (Fall), X25 (Spring) or Winter 2024. |
maxItems | integer | 100 | Total jobs saved across all inputs. No fixed limit: the run stops as soon as it is reached. |
debugMode | boolean | false | Detailed progress in the log. |
Accepted formats
- Company links:
https://www.ycombinator.com/companies/airbnb, the same with/jobs, orhttps://www.workatastartup.com/companies/airbnb. - Job links:
https://www.ycombinator.com/companies/noloco/jobs/M2m3UVI-senior-software-engineer. - Directory searches: any
https://www.ycombinator.com/companies?...link. Its keyword,batch,industryandregionsare kept, and only companies that are hiring are read. - Jobs pages:
https://www.ycombinator.com/jobs,/jobs/role/software-engineer,/jobs/location/san-francisco,/jobs/role/product-manager/new-york. The role and city of the link become filters. - Companies: a name (
Scale AI) or the slug at the end of the YC profile link (scale-ai). - Batches:
W24,S21,F24,X25,Winter 2024,summer 2013. - Locations:
San Francisco,New York,Berlin,CA,Remote,gb,gbr,United Kingdom. A job listed in several places matches on any of them.
What data can you extract from Y Combinator?
Each row is one open job, flat, with 55 fields grouped the way you read a job post:
- The job (12 fields):
id,url,title, the fulldescriptionin Markdown and as HTML,role,specialization(for example Full stack, Backend, Machine learning),jobType,experienceandminExperienceYears,visa, andskills. - Pay (8 fields):
salaryRangeas YC shows it,salaryMin,salaryMax,salaryCurrency,salaryPeriod, andequityRangewithequityMinandequityMaxin percent. - Place and date (6 fields):
locationas listed,isRemote,city,region,countryCode, andpostedAt, the exact date the job was published, in RFC 3339. - Applying (3 fields):
applyUrl, the YC application link,hiringManagerNameandhiringManagerImageUrl. - The company (25 fields): YC id, name, slug, YC profile, website, logo, batch, one-liner, long description, why-join-us text, industry and sub-industry, tags, stage, status, YC top company badge, founding year, team size, headquarters and its country code, LinkedIn, X, Facebook and Crunchbase links, and
founders, a list where each founder has a name, title, bio, LinkedIn, X and photo (6 fields each). - Meta:
scrapedAt.
id is YC's own job number and url is the permanent job page, so they make good keys for deduplicating across runs. Dates are RFC 3339 in UTC. Logo and photo links are permanent image files. Fields a company did not fill are null, never an empty string.
Output example
The long texts are cut here for reading; the dataset holds them in full.
Advanced usage
Export every open job at YC startups
With no keyword, link or company, the run walks through every company the YC directory marks as hiring. A full pass over the 1,496 hiring companies took 1 minute 42 seconds to read; jobs then come back as fast as their pages load. Use it for a complete weekly snapshot of YC hiring.
Follow a single batch from Demo Day onwards
Keeps only companies from the Spring 2025 and Fall 2025 batches. Schedule it every week to see when a young batch starts hiring and for which roles, with team size and stage on each row.
Turn a YC directory search into a jobs table
Set your filters on the YC company directory in your browser, copy the link, and paste it here: the hiring companies of that search come back as one row per open job. This exact link returned 16 jobs from 7 fintech companies of the Winter 2024 batch.
Find startups that sponsor visas in London or Berlin
Run it once with gb and once with Berlin, then filter the visa column on Will sponsor. On the prefilled run, 17 of 100 jobs said the company sponsors visas and 13 did not require US work authorization.
Build a founder outreach list of companies hiring for sales
Each row brings the company's website, LinkedIn and team size with the founders' names, titles and LinkedIn links: a list of startups that are investing in growth right now, with the people to talk to. Use the Companies view or deduplicate on companyId for one line per company.
FAQ
What does this scraper extract? Every open job published by Y Combinator startups on ycombinator.com, one row per job: the posting with its full description, the salary and equity both as text and as numbers, location, remote flag, experience, visa policy, skills, exact posting date, the hiring manager, and the company's YC profile with its founders.
What is Y Combinator, and what is Work at a Startup? Y Combinator (YC) is the startup accelerator behind Airbnb, Stripe, DoorDash and thousands of other companies. Work at a Startup is YC's job platform: YC companies post their openings there, and the same jobs appear on each company's page on ycombinator.com, which is what this actor reads.
Do I need a YC or Work at a Startup account? No. The actor reads public pages only. You do not log in and you do not share any password or session.
How fresh is the data?
Every run reads the pages live, at run time; nothing is cached. postedAt is the date the job was first published, and a job disappears from the results as soon as the company closes it.
How do the keyword and the filters combine?
Every filter applies to every input, and they add up. searchQueries: ["react"] with location: "Remote" and roles: ["eng"] returns engineering jobs that can be done remotely and mention React. Inside a keyword, every word must match: fintech engineer finds engineering jobs at fintech companies.
Why do some rows have no salary or no equity?
Those fields come from what the company published. When a company did not give a salary range, salaryRange, salaryMin and salaryMax are null. The text stays as YC shows it, and the numbers are read from it as written: a range shown as 75 to 95 EUR stays 75 and 95, it is not rescaled, and its salaryPeriod stays null because such a range could be thousands a year or an hourly rate. Ranges written with K or M, with thousands separators, or with "/ hourly" and "/ monthly" are converted for you.
How many jobs can I get?
There is no fixed limit: set maxItems to what you need. The run stops as soon as that number is reached. Without any keyword, link or company, it can read every hiring YC company.
Can I search several keywords, companies and links in one run?
Yes. Add as many lines as you want in each field. maxItems is shared by the whole run, and a job found twice (for example by a keyword and by its company) is saved once.
What happens if a company does not exist or is not hiring? The log says so and the run continues with the rest of the input. A run that finds nothing ends with a message saying why: no matching job, no open job at these companies, or a company that YC does not list.
Are the links permanent?
url is the permanent job page and companyUrl the permanent YC profile. Logo and photo links point to permanent image files. applyUrl is YC's application link, which asks the candidate to sign in to Work at a Startup before applying.
Which batches can I filter on?
All of them: write W24 for Winter 2024, S21 for Summer 2021, F24 for Fall 2024 and X25 for Spring 2025, or write the full name. Unknown batch names are refused with a message rather than silently ignored.
More SilentFlow scrapers
🛒 E-commerce
 Pinterest - Pinterest Scraper | Pins, Boards and Profiles
 Leboncoin Ppe - Leboncoin Scraper Ppe
 Back Market - Back Market Scraper | Refurbished Prices
 Leboncoin - Leboncoin Ad Details Scraper
 1688 Wholesale - 1688 Wholesale Scraper
 TikTok Shop - TikTok Shop Scraper
 ImportYeti - US Customs Records, Suppliers & Trade Data - ImportYeti Scraper - US Customs Records, Suppliers & Trade Data
 Udemy Course - Udemy Course Scraper
 Bring a Trailer - Bring a Trailer Scraper
 Store Leads - Store Leads Scraper | Shopify Data
 Avito - Avito Scraper | Listings, Prices and Sellers
 Naver - Naver Products Scraper | Shopping Prices, Sellers and Ratings
 Naver - Naver Scraper | Shopping Products, Prices and Reviews
 Taobao - Taobao Scraper | Products, Prices and Sellers
 Vinted Marketplace - Vinted Marketplace Scraper
 Walmart - Walmart Product Scraper
 Agoda - Agoda Scraper | Hotel Prices and Guest Ratings
 Alibaba - Alibaba Products Scraper | Wholesale Prices and MOQ
 AliExpress - AliExpress Reviews Scraper | Feedback, Ratings and Photos
 AliExpress - AliExpress Scraper | Products, Prices and Sales
 Allegro - Allegro Scraper | Products, Prices and Sellers
 Amazon Seller - Amazon Seller Scraper | Emails, Phones and Ratings
 CARFAX - CARFAX Scraper | Used Cars, Prices and History
 Coupang - Coupang Detail Scraper | Product Prices and Options
 Ctrip - Ctrip Scraper | Attractions, Tickets and Reviews
 Europages - Europages Scraper | Suppliers and B2B Companies
 Google Hotels - Google Hotels Scraper | Prices, Offers and Ratings
 Homedepot - Homedepot Reviews Scraper | Customer Reviews and Ratings
 JD - JD Products Scraper | Prices, Brands and Barcodes
 Lowes - Lowes Products Scraper | Prices, Stock and Specs
 Mobile.de - Mobile.de Scraper
 Naver - Naver Reviews Scraper | Shopping Product Reviews
 Alibaba - Alibaba Scraper | Products, Prices and Suppliers
 Amazon Marketplace - Amazon Marketplace Scraper
 AutoScout24 - AutoScout24 Scraper
 eBay Listings - eBay Listings Scraper
 Mercari - Mercari Scraper | Listings, Sold Prices and Sellers
 Trip - Trip Scraper | Hotels, Prices and Reviews
💼 Jobs
 ZipRecruiter - ZipRecruiter Jobs Scraper | Salary, Company & Location Filters
 Indeed - Indeed Company Reviews Scraper
 Multi Board - Multi Board Job Scraper
 Glassdoor Job Listings - Glassdoor Job Listings Scraper
 LinkedIn Job Search - LinkedIn Job Search Scraper | Salaries & Seniority
 ATS - ATS Jobs Scraper | Greenhouse, Lever and Ashby
 🔥 Glassdoor - 🔥 Glassdoor Scraper
 Indeed Jobs Ppr - Indeed Jobs Scraper Ppr
 Jora - Jora Jobs Scraper
 Malt - Malt Scraper | Freelance Profiles
 Welcome to the Jungle - Welcome to the Jungle Job Scraper
 Arbeitsagentur - Arbeitsagentur Jobs Scraper
 Dice Tech - Dice Tech Jobs Scraper
 Naukri & NaukriGulf - Naukri & NaukriGulf Jobs Scraper
 Seek - Seek Job Scraper
 StepStone - StepStone Scraper
🏠 Real estate
 SeLoger - SeLoger Scraper | Real Estate Listings
 Realtor Rental Listings - Realtor Rental Listings Scraper
 Airbnb Pro Host Contact & - Airbnb Pro Host Contact & Email Scraper
 Bien'ici - Bien'ici Scraper | Property Listings
 Zillow - Zillow Scraper
 Trulia Rental Listings - Trulia Rental Listings Scraper
 Airbnb Search - Airbnb Search Scraper
 Anjuke - Anjuke Scraper | Rental Listings, Prices and Agents
 Idealista - Idealista Scraper
 Realestate.com.au - Realestate.com.au Scraper
 Rightmove - Rightmove Scraper
📣 Social media
 LinkedIn Post Search - LinkedIn Post Search Scraper | Keywords, Hashtags & Profiles
 Facebook Search - Facebook Search Scraper
 LinkedIn Leads - LinkedIn Leads Scraper | Sales Navigator Export
 Instagram - Instagram Story Scraper | Stories & Highlights
 OnlyFans - OnlyFans Profile Scraper
 TikTok - TikTok Scraper
 Instagram Engagement - Instagram Engagement Scraper
 YouTube - YouTube Channel Scraper | Videos, Shorts and Views
 Meta Ad Library - Meta Ad Library Scraper
 Skool Community - Skool Community Scraper
 Facebook Search - Facebook Search Profiles Scraper | People by Name or Keyword
 Kuaishou - Kuaishou Scraper | Videos, Comments and Creator Stats
 Reddit - Posts, Comments, Communities & - Reddit Scraper - Posts, Comments, Communities & Users
 Snapchat - Snapchat Ads Scraper | Ad Library, Impressions & Targeting
 TikTok Trend - TikTok Trend Scraper | Trending Hashtags and Videos
 Weibo - Weibo Scraper | Posts, Profiles and Engagement
 Bilibili - Bilibili Scraper
 Discord - Discord Scraper | Servers, Member Counts and Invites
 Facebook Business Page - Facebook Business Page Scraper
 Kwai - Kwai Scraper | Videos, Creators and Hashtags
 YouTube - YouTube Transcript Scraper
🏢 Business data
 LinkedIn People Search - LinkedIn People Search Scraper | Profiles & Companies
 Company Data - Company Data Scraper | Emails, Phones and Tech Stack
 ForexFactory - ForexFactory Scraper | Economic Calendar and Forecasts
 Justdial - Justdial Companies Scraper | Business Leads, Phones and Emails
 Kakao - Kakao Scraper | Map Places, Reviews and Phones
 OpenTable - OpenTable Reviews Scraper | Restaurant Reviews and Ratings
 Tencent - Tencent Scraper | Maps Places, Phones and Ratings
 Teachable - Courses, Prices & Instructors - Teachable Scraper - Courses, Prices & Instructors
 Trustpilot - Trustpilot Enricher
 Website Tech Stack - Website Tech Stack Scraper
✈️ Travel
 Google Maps - Google Maps Scraper
 Booking.com Hotel - Booking.com Hotel Scraper
 Flight Price - Flight Price Scraper
 Trip - Trip Reviews Scraper | Hotel Reviews and Ratings
🎯 Lead generation
 Northdata - Northdata Company Scraper
 UK Companies House - UK Companies House Enricher
 ZocDoc - Pay Per Result - ZocDoc Scraper - Pay Per Result
 SIRET - SIRET Company Enricher
 Dealroom - Dealroom Scraper | Companies and Investors
 Google Ads Transparency - Google Ads Transparency Scraper
 BuiltWith - BuiltWith Scraper | Tech Stacks and Top Sites
 CNPJ Brazilian - CNPJ Brazilian Company Enricher
 Domain - Domain Enricher
 French Company Prospector - French Company Prospector
 SEC - SEC Scraper | EDGAR Filings and Company Data
 ThomasNet Suppliers - ThomasNet Suppliers Scraper
 USPTO - USPTO Scraper | Trademark Search and Status
 Clutch Agency - Clutch Agency Scraper
 G2 - G2 Reviews Scraper
 PagesJaunes - PagesJaunes Business Scraper
🔎 SEO
 Similarweb - Similarweb Scraper | Website Traffic, Rankings and Competitors
 Google News - Google News Scraper
 Apple - Apple Scraper | App Store Apps, Ratings and Charts
📈 Marketing
 Pexels -
🧰 More tools
 Apple -
Support
Need something this scraper doesn't do yet? We ship features fast.
- Feature requests go straight to our backlog
- Enterprise needs? We do custom integrations and high-volume plans
- Pricing questions? Check the Monetization tab on the actor page
Response time: usually under 24 hours.
Legal compliance
This actor extracts publicly available data from ycombinator.com. It does not bypass any login, paywall or CAPTCHA. Users are responsible for complying with Y Combinator's terms of service and applicable data protection laws (GDPR, CCPA, and PIPL where relevant). Rows contain personal data about founders and hiring managers (names, titles, bios, profile links and photos): handle it accordingly, and use it for legitimate purposes such as recruiting and business outreach that respects opt-outs. The data returned is informational: confirm salary and visa details with the company before relying on them.
Built by SilentFlow for recruiters, job boards and analysts who would rather read the YC job market than copy it.


