
RedNote Videos Scraper | Downloader, Transcripts and Stats
Pricing
from $3.78 / 1,000 videos
RedNote Videos Scraper | Downloader, Transcripts and Stats
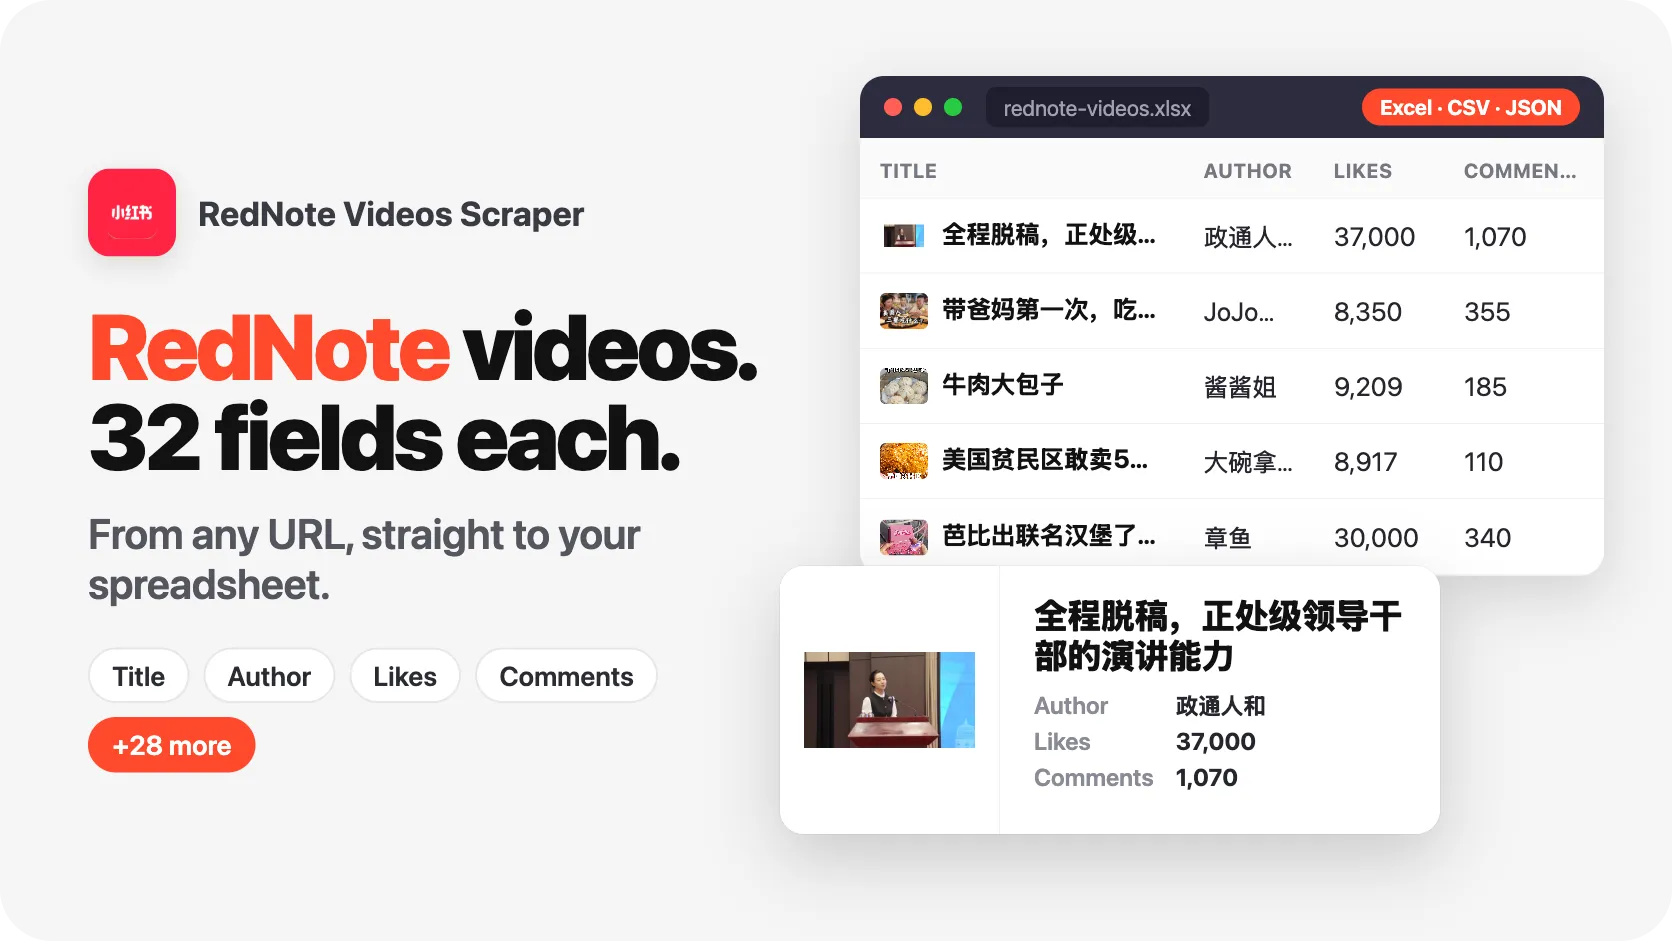
RedNote Videos Scraper for Xiaohongshu (小红书): turn video links, share links or the trending Explore feed into rows with the watermark-free video file, the transcript with its English translation, likes, saves, comments, shares, author and hashtags. 12 videos in 2 seconds, 32 fields each, no account.
Pricing
from $3.78 / 1,000 videos
Rating
0.0
(0)
Developer
SilentFlow
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Share
RedNote Videos Scraper (小红书) | Video Downloader, Transcripts and Stats (2026)
From SilentFlow. Creators of Pinterest Scraper and Leboncoin Scraper, with 420,000+ combined lifetime runs.
Every Xiaohongshu video you paste, or every video trending in its Explore feed, as one row: the original file without watermark, what is said in it in Chinese and in English, and how many people liked, saved, commented on and shared it. Paste video links or share links from the app, or leave the list empty and pick a feed. On a local run, 12 videos from 12 links came back in 2 seconds, with no Xiaohongshu account.
Why choose this actor?
Got a list of RedNote links from a creator or a client, and no clean way to save the videos without the watermark? Watching Chinese videos you cannot follow to write a campaign report? Copying likes and saves from the app one post at a time?
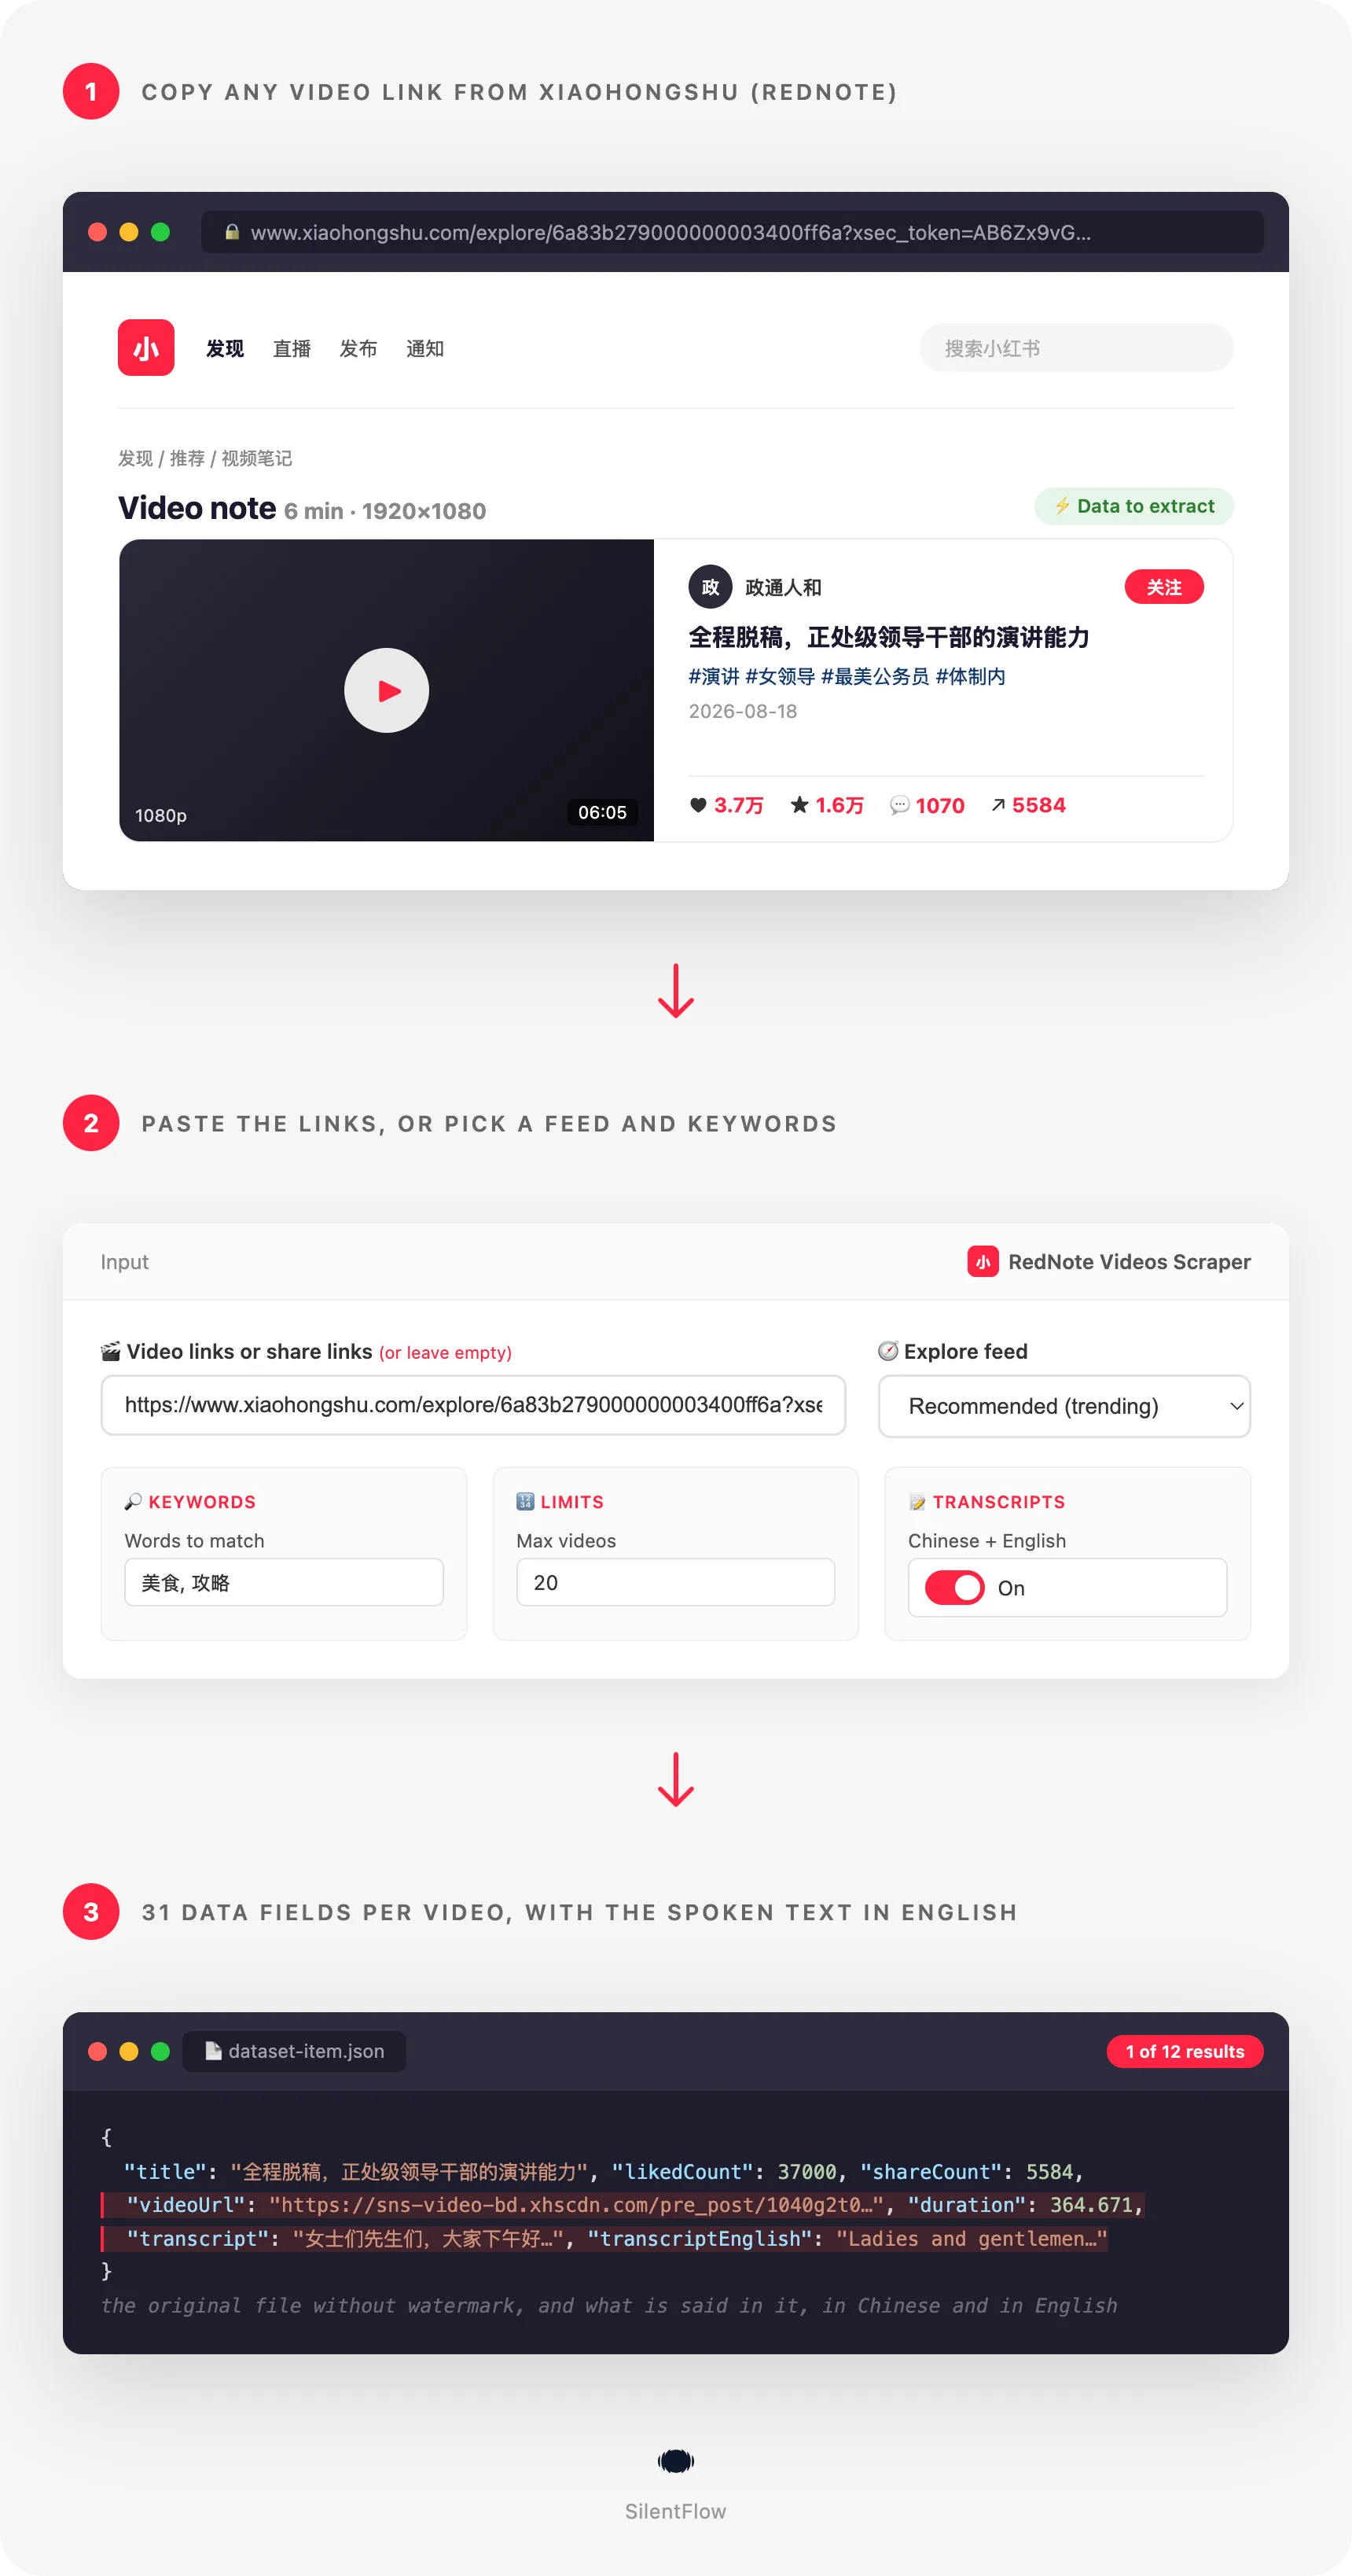
- 31 data fields per video, not 22. The most used RedNote video downloader on the Store returns 22 fields per video in its output example. On the prefilled run (12 videos, 16 Oct 2026), all 31 data fields carried a value: the original MP4 without watermark and a second stream link, length, width, height, frame rate, bitrate and file size, the cover, title, description and hashtags, the creator with profile link and verified flag, likes, saves, comments, shares, publish and update dates, the spoken language, and the transcript with its English translation. 12 of the 12 videos came with a transcript, 11 with an English one, and 25 fields were filled on every row of all three test runs.
- Two ways in: video links, or keywords over the live Explore feed. The most used RedNote video downloader reads video links and nothing else. Here you paste links, app share links or whole share messages, and you can also type keywords: the actor reads the Explore feed you pick and keeps the videos whose title, description or hashtags mention them. On a local run, 10 videos mentioning 美食 came out of 21 checked in the Food feed, in 14 seconds.
- Nothing to fill in before you press Start. The most used RedNote video downloader makes its list of links mandatory. Here no field is required: the form comes prefilled with 12 real videos, and a run with an empty form returns the trending videos of an Explore feed. On a local run, the Food feed gave 15 videos in 9 seconds with no link at all.
Try your first RedNote videos
Paste this input into the Input tab (JSON view) and press Start. It is the prefilled input of the form: 12 public Xiaohongshu videos (food, travel, a public speech), read with their transcripts.
The Apify Free plan is enough to run it and to test the actor on your own links: no credit card, no Xiaohongshu account, nothing to install. Each video becomes one row of the dataset, which you can export as JSON, CSV or Excel, or read from the API. The table opens on a view with the cover, title, creator, likes, comments, length, publish date and the video file; a second view lists the transcripts side by side with their English translation.
To try the feed instead, clear the list of links and press Start: you get 20 videos trending in the Recommended feed at that moment. Pick Food, Travel, Beauty or another feed in the Discovery section to stay on one topic.
| SilentFlow · RedNote suite | |
 RedNote Detail Scraper Notes, Images and Videos |  RedNote Videos Scraper You are here |
Copy to your AI assistant
Paste this block into Claude, ChatGPT or Cursor to give it full context about this actor:
How to scrape Xiaohongshu videos
Three inputs, from the simplest to the most targeted. Each one runs as is.
Save a few videos with their numbers and transcripts
Paste the links you have, from the browser or from the app's share button. Each link becomes one row.
Get what is trending in one category today
Leave the links empty and pick a feed. The feed changes every few seconds, so each run brings different videos.
Find videos about a topic in a feed
Keywords keep only the videos whose title, description or hashtags mention one of the words. Broad words in Chinese, in the feed that matches the topic, find the most videos.
Input parameters
| Field | Type | Default | What it does |
|---|---|---|---|
videoUrls | list of text | 12 sample videos in the form | The videos to read, one per line: video links, app share links, or whole share messages copied from the app. |
keywords | list of text | empty | Keep only the Explore feed videos whose title, description or hashtags contain one of these words. |
category | choice | recommend | The Explore feed read when no link is given, or when keywords are set: Recommended, Fashion, Food, Beauty, Movies and TV, Career, Relationships, Home, Gaming, Travel, Fitness. |
maxItems | number | 20 | The most videos saved in the run, across the links and the feed. |
includeTranscript | yes / no | yes | Adds the spoken text of each video and its English translation when the site has subtitles for it. |
No field is required. With links, the actor reads those videos. With keywords, it reads the chosen feed and keeps the videos that mention them. With neither, it returns the trending videos of the chosen feed. Links and keywords can be used in the same run, and maxItems caps the total.
Accepted formats
- Video link from the browser:
https://www.xiaohongshu.com/explore/64b75f2a000000002b038d50?xsec_token=... - Video link from a mobile page:
https://www.xiaohongshu.com/discovery/item/64b75f2a000000002b038d50?xsec_token=... - Share link from the app:
https://xhslink.com/a/...orhttps://xhslink.com/o/... - Whole share message: the text the app copies when you tap Share, for example
看看这个视频 https://xhslink.com/a/... 复制本条信息,打开【小红书】App查看精彩内容!. The link inside is found for you.
A note id alone (64b75f2a000000002b038d50) is not enough: Xiaohongshu only opens a note for a link that carries its access code (xsec_token). Copy the full link from the browser address bar, or use the app's share button. Picture posts (notes with photos and no video) are skipped and counted in the log.
What data can you extract from Xiaohongshu?
Each video is one flat row of 31 data fields plus scrapedAt, grouped the same way on every row:
- Identity (3):
id,url(the video page, with its access code),title. - Content (2):
description(hashtag markup removed),hashtags(the topics the creator tagged). - Creator (5):
authorId,authorName,authorAvatar,authorUrl,authorVerified. - Engagement (4):
likedCount,collectedCount(saves),commentCount,shareCount. - Time (2):
publishedAt,updatedAt, in RFC 3339 UTC. - Video (14):
durationin seconds,widthandheightof the original upload,fps,bitrate,fileSize,videoUrl(the original file without watermark),streamUrl(the H.264 stream),coverUrl,videoLanguage,hasHumanVoice,subtitleLanguages,transcript,transcriptEnglish. - Access (1):
xsecToken, the note's access code, to open the note again later. - Meta:
scrapedAt, andkeywordon rows found by a keyword.
Which fields are always there: on all three test runs (pasted links, a trending feed, keywords), the same 25 data fields were filled on every row. description and hashtags stay empty when the creator wrote none; the language and the two transcripts stay empty on videos without speech or subtitles (music clips, silent cooking videos). Absent values are null, never an empty text.
Output example
One complete row from the prefilled run, a 41-second food video from Yangzhou:
Advanced usage
Track the trending Beauty videos every morning
Schedule this input daily in the Schedules tab: each run adds the videos trending in the Beauty feed at that moment, with their engagement and transcripts, so you can see which products and formats keep coming back.
Refresh the numbers of a campaign's videos every week
Keep the links of your campaign posts in one saved input and run it every week, without transcripts for speed. Each run gives the current likes, saves, comments and shares of every post; compare runs by id to chart their growth.
Collect travel guides from the Travel feed
Travel videos on Xiaohongshu are tagged with 攻略 (guide) and 旅行 (travel). Put both words in the Travel feed: a video that mentions either is kept, and keyword tells you which word matched.
Build a bilingual speech dataset
Read the Recommended feed with transcripts on, then open the Transcripts view of the dataset: one row per video with the spoken language, the original text and the English translation, ready to export as CSV for translation memories, subtitle research or language models.
Download the original files to a folder
Run the actor from Python and save each videoUrl, the original upload without watermark, as an MP4 named after the video's id. The same loop works with streamUrl when you prefer the H.264 stream.
FAQ
What is Xiaohongshu (RedNote)? Xiaohongshu (小红书, "Little Red Book"), called RedNote in English, is China's lifestyle platform: a mix of Instagram and Pinterest where people post short videos and photo notes about food, travel, beauty, fashion and products. It is the place brands watch to understand Chinese consumers.
Do I need a Xiaohongshu account or the app? No. The actor reads what the site shows any visitor. There is nothing to log into, nothing to install, and no account of yours is used.
Can I search Xiaohongshu by keyword?
Not with the app's search box: Xiaohongshu shows search results only to logged-in users. The keywords field works on the live Explore feed instead: the actor reads the feed you pick and keeps the videos whose title, description or hashtags contain your words. Broad Chinese words in the matching feed work best (美食 in Food, 攻略 in Travel). A run checks about 400 videos at most before it stops, and the log says how many it checked.
Why does a note id alone not work?
Xiaohongshu opens a note only for a link that carries its access code (xsec_token), which the site adds to every link it shows and shares. Copy the full link from the browser, or tap Share in the app and paste the link or the whole message. Each row keeps the code in xsecToken and in url, so you can open the note again later.
Are the videos really without watermark?
videoUrl points to the file the creator uploaded, in its original resolution (1080 by 1440 on the example above), not the copy the site plays with its overlay. streamUrl is the H.264 stream the site plays. Both are plain links that open in a browser or a download tool.
How long do the links work?
videoUrl, streamUrl and coverUrl carry no expiry time in them: they work as long as the video is online. url opens the video page with its access code. If the creator deletes the video or makes it private, the files go away with it, so download what you need to keep.
Where do the transcripts come from, and in which languages?
From the subtitles Xiaohongshu creates for videos with speech: transcript is the spoken text in its own language (mostly Chinese), transcriptEnglish the site's English translation, one subtitle line per line. On the prefilled run 12 of 12 videos had a transcript; on a Food trending run, 8 of 15 did, because many cooking clips have music and no speech. Videos without subtitles keep both fields null.
Why do some counts look rounded?
Xiaohongshu shows large counts rounded, such as 3.7万 for 37,000. The actor turns them into plain numbers, so a video the site shows at 3.7万 likes reads 37000. Counts under 10,000 are exact.
What happens with photo posts? They are skipped: this actor returns videos only, and the log tells you how many posts had pictures and no video. For photo notes, use our RedNote Note Scraper.
Can I mix links and keywords in one run?
Yes. The links are read first, then the feed is read and filtered by your keywords, and maxItems caps the total. Duplicates are removed by id, so a video found twice is saved once.
How fresh is the data? Every run reads the live site: counts, transcripts and the feed are as they are at the time of the run. Nothing comes from a cache.
More SilentFlow scrapers
🛒 E-commerce
 Pinterest - Pinterest Scraper | Pins, Boards and Profiles
 Leboncoin - Leboncoin Scraper | Classified Ads, Prices and Sellers
 Leboncoin - Leboncoin Ad Details Scraper
 ImportYeti - US Customs Records, Suppliers & Trade Data - ImportYeti Scraper - US Customs Records, Suppliers & Trade Data
 Back Market - Back Market Scraper | Refurbished Prices
 TikTok Shop - TikTok Shop Scraper | Products, Sellers and Creator Videos
 Naver - Naver Scraper | Shopping Products, Prices and Reviews
 1688 - 1688 Scraper | Products, Details, Wholesale Prices, Suppliers
 Udemy Course - Udemy Course Scraper
 JD - JD Products Scraper | JD.com Prices, Brands and Barcodes
 Amazon Seller - Amazon Seller Scraper | Emails, Phones and Ratings
 Store Leads Ecommerce - Store Leads Ecommerce Scraper
 Naver - Naver Reviews Scraper | Shopping Product Reviews
 Naver - Naver Products Scraper | Shopping Prices, Sellers and Ratings
 Bring a Trailer - Bring a Trailer Scraper
 CARFAX - CARFAX Scraper | Used Cars, Prices and History
 Leboncoin - Leboncoin Scraper
 Lowes - Lowes Products Scraper | Prices, Stock and Specs
 Store Leads - Store Leads Scraper | Shopify Data
 Avito - Avito Scraper | Listings, Prices and Sellers
 GasBuddy - GasBuddy Scraper | Gas Prices by Station
 Mobile.de - Mobile.de Scraper
 Taobao - Taobao Scraper | Products, Details, Prices and Sellers
 Udemy - Udemy Scraper
 Agoda - Agoda Scraper | Hotel Prices and Guest Ratings
 Alibaba - Alibaba Products Scraper | Wholesale Prices and MOQ
 AliExpress - AliExpress Reviews Scraper | Feedback, Ratings and Photos
 AliExpress - AliExpress Scraper | Products, Prices and Sales
 Allegro - Allegro Scraper | Products, Prices and Sellers
 Avito - Avito Profiles Scraper | Sellers, Ratings and Reviews
 Back Market - Back Market Scraper | Refurbished Electronics Prices
 BAUHAUS - BAUHAUS Scraper | Product Prices, EAN and Specs
 Coupang - Coupang Detail Scraper | Product Prices and Options
 Ctrip - Ctrip Scraper | Attractions, Tickets and Reviews
 eBay Marketplace - eBay Marketplace Scraper
 Europages - Europages Scraper | Suppliers and B2B Companies
 Eventim - Eventim Scraper | Events, Ticket Prices and Venues
 Google Hotels - Google Hotels Scraper | Prices, Offers and Ratings
 Homedepot - Homedepot Reviews Scraper | Customer Reviews and Ratings
 Leboncoin - Leboncoin Details Scraper | Full Ad Data and Sellers
 Mafengwo - Mafengwo Scraper | Attractions, Ratings and Tickets
 Mercari - Mercari Scraper | Listings, Sold Prices and Sellers
 Pinterest - Pinterest Scraper
 Vinted Marketplace - Vinted Marketplace Scraper
 Walmart - Walmart Product Scraper
 Alibaba - Alibaba Scraper | Products, Supplier Companies and Prices
 Amazon - Amazon Product Scraper
 Amazon Marketplace - Amazon Marketplace Scraper
 AutoScout24 - AutoScout24 Scraper
 eBay Listings - eBay Listings Scraper
 Europages Deep Dive Extractor - Europages Deep Dive Extractor | VAT, Decision Makers, ISO Certs
 Trip - Trip Scraper | Hotels, Prices and Reviews
 Vinted - Vinted Scraper
 Walmart - Walmart Scraper | Prices, Reviews, Sellers, Availability
💼 Jobs
 ZipRecruiter - ZipRecruiter Jobs Scraper | Salary, Company & Location Filters
 Indeed - Indeed Company Reviews Scraper
 Multi Board - Multi Board Job Scraper
 Glassdoor Job Listings - Glassdoor Job Listings Scraper
 ATS - ATS Jobs Scraper | Greenhouse, Lever and Ashby
 🔥 Glassdoor - 🔥 Glassdoor Scraper
 Jora - Jora Jobs Scraper
 Glassdoor - Glassdoor Jobs Scraper
 LinkedIn Job Search - LinkedIn Job Search Scraper | Salaries & Seniority
 Malt Freelancer - Malt Freelancer Scraper
 Malt - Malt Scraper | Freelance Profiles
 Welcome to the Jungle - Welcome to the Jungle Job Scraper
 All - All Jobs Scraper
 Arbeitsagentur - Arbeitsagentur Jobs Scraper
 Cutshort - Cutshort Jobs Scraper | Salaries, Skills and Companies
 Dice - Dice Jobs Scraper | US Tech Jobs, Salaries, Skills
 Dice Tech - Dice Tech Jobs Scraper
 Indeed - Indeed Jobs Scraper | Job Listings in 73 Countries
 Jora - Jora Scraper | Jobs in Australia, New Zealand, Singapore
 StepStone - StepStone Scraper
 YCombinator - YCombinator Jobs Scraper | Startup Jobs, Salaries and Founders
 Arbeitsagentur - Arbeitsagentur Scraper | German and Austrian Job Board
 iimjobs - iimjobs Scraper | Jobs, Companies and Recruiters
 Indeed - Indeed Companies Scraper | Reviews, Salaries, Interviews
 Indeed - Indeed Jobs Scraper | NLP Skills
 LinkedIn - LinkedIn Jobs Scraper
 Naukri & NaukriGulf - Naukri & NaukriGulf Jobs Scraper
 Seek - Seek Job Scraper
 Welcome to the Jungle - Welcome to the Jungle Scraper | Jobs and Company Data
 Ziprecruiter - Ziprecruiter Scraper
🏠 Real estate
 SeLoger - SeLoger Scraper | Real Estate Listings
 Realtor Rental Listings - Realtor Rental Listings Scraper
 Airbnb Pro Host Contact & - Airbnb Pro Host Contact & Email Scraper
 Bien'ici - Bien'ici Scraper | Property Listings
 Rightmove - Rightmove Scraper
 Trulia Rental Listings - Trulia Rental Listings Scraper
 Airbnb Professional Host - Airbnb Professional Host Scraper | Emails, Phones, SIRET
 Airbnb Search - Airbnb Search Scraper
 Bienici - Bienici Scraper
 Idealista - Idealista Scraper
 Realestate.com.au - Realestate.com.au Scraper
 SeLoger - SeLoger Scraper | French Property Listings and Agencies
 Airbnb Search - Airbnb Search Scraper | Prices, Fees, Amenities, Hosts
 Anjuke - Anjuke Scraper | Rental Listings, Prices and Agents
 Idealista - Idealista Scraper
 Realtor Rental - Realtor Rental Scraper
 Trulia Rental - Trulia Rental Scraper | US Rentals, Prices, Pet Policy
 Zillow - Zillow Scraper
📣 Social media
 LinkedIn Post Search - LinkedIn Post Search Scraper | Keywords, Hashtags & Profiles
 Facebook Search - Facebook Search Scraper
 Instagram - Instagram Story Scraper | Stories & Highlights
 LinkedIn Leads - LinkedIn Leads Scraper | Sales Navigator Export
 TikTok - TikTok Scraper
 YouTube - YouTube Channel Scraper | Videos, Shorts and Views
 Facebook Search - Facebook Search Profiles Scraper | People by Name or Keyword
 Instagram Engagement - Instagram Engagement Scraper
 Meta Ad Library - Meta Ad Library Scraper
 OnlyFans - OnlyFans Profile Scraper
 TikTok Trend - TikTok Trend Scraper | Trending Hashtags and Videos
 OnlyFans - OnlyFans Creator Scraper
 Pinterest - Pinterest Ads Scraper | Ad Library, Reach & Targeting
 Pinterest - Pinterest Profiles Scraper | Followers, Emails and Bios
 Skool Community - Skool Community Scraper
 Douyin - Douyin Comments Scraper | Comments, Likes and IP Regions
 Facebook Thread - Facebook Thread Profiles Scraper | Followers, Bios & Engagement
 Kuaishou - Kuaishou Scraper | Videos, Comments and Creator Stats
 LinkedIn Ads Library - No Cookies - LinkedIn Ads Library Scraper - No Cookies
 LinkedIn Event - LinkedIn Event Scraper
 LinkedIn Hashtag & - LinkedIn Hashtag & Post Scraper | No Cookies
 Pinterest - Pinterest Videos Scraper | Video Downloader, MP4 Links, Stats
 Reddit - Reddit Comments Scraper | Search, Threads and Replies
 Reddit - Reddit Profiles Scraper | User Karma, Activity and Communities
 Reddit - Reddit Scraper | Posts, Comments and Subreddits
 Reddit - Reddit Scraper | Comments, Posts and Users
 Snapchat - Snapchat Contacts Scraper | Phones, Emails and Websites
 TwitchTracker - TwitchTracker Scraper | Twitch Streamer Stats and Rankings
 Weibo - Weibo Scraper | Posts, Profiles and Engagement
 Xigua - Xigua Scraper | Videos, Creators and Downloads
 Discord - Discord Scraper | Servers, Member Counts and Invites
 Facebook - Facebook Company Scraper | Emails, Phones, Ratings
 Facebook Business Page - Facebook Business Page Scraper
 Kwai - Kwai Scraper | Videos, Creators and Hashtags
 Skool Group - Skool Group Scraper
 Snapchat - Snapchat Ads Scraper | Ad Library, Impressions & Targeting
 YouTube - YouTube Transcript Scraper
🏢 Business data
 Tencent - Tencent Scraper | Maps Places, Phones and Ratings
 LinkedIn Company Search - LinkedIn Company Search Scraper | Profiles & Firmographics
 LinkedIn People Search - LinkedIn People Search Scraper | Profiles & Companies
 Justdial - Justdial Companies Scraper | Business Leads, Phones and Emails
 Bilibili - Bilibili Scraper | Videos, Profiles, Comments, Danmaku
 Company Data - Company Data Scraper | Emails, Phones and Tech Stack
 FanDuel - FanDuel Scraper | Odds, Spreads and Player Props
 ForexFactory - ForexFactory Scraper | Economic Calendar and Forecasts
 Kakao - Kakao Scraper | Map Places, Reviews and Phones
 OpenTable - OpenTable Reviews Scraper | Restaurant Reviews and Ratings
 SoftwareAdvice - SoftwareAdvice Scraper | Reviews, Ratings and Pros & Cons
 Teachable Course - Teachable Course Scraper
 Zomato - Zomato Reviews Scraper | Restaurant Ratings and Replies
 2GIS - 2GIS Reviews Scraper | Ratings, Photos and Owner Replies
 LinkedIn Sales Navigator - LinkedIn Sales Navigator Scraper
 Teachable - Courses, Prices & Instructors - Teachable Scraper - Courses, Prices & Instructors
 Trustpilot - Trustpilot Scraper | Reviews, Ratings and Company Contacts
 Website Tech Stack - Website Tech Stack Scraper
✈️ Travel
 Google Maps - Google Maps Scraper
 Flight Price - Flight Price Scraper
 Booking.com Hotel - Booking.com Hotel Scraper
 Trip - Trip Reviews Scraper | Hotel Reviews and Ratings
 Booking - Booking Scraper | Hotel Prices, Photos, Availability
🎯 Lead generation
 Northdata - Northdata Company Scraper
 ZocDoc - ZocDoc Scraper | Doctors, Reviews and Availability
 Dealroom - Dealroom Scraper | Companies and Investors
 UK Companies House - UK Companies House Enricher
 CNPJ Brazilian - CNPJ Brazilian Company Enricher
 Google Ads Transparency - Google Ads Transparency Scraper
 SIRET - SIRET Company Enricher
 BuiltWith - BuiltWith Scraper | Tech Stacks and Top Sites
 Domain - Domain Enricher
 French Company Prospector - French Company Prospector
 PagesJaunes - PagesJaunes Scraper | French Business Emails and SIRET
 SEC - SEC Scraper | EDGAR Filings and Company Data
 USPTO - USPTO Scraper | Trademark Search and Status
 ZocDoc - ZocDoc Scraper
 Clutch - Clutch Scraper | Agencies, Reviews, Ratings, Services
 Clutch Agency - Clutch Agency Scraper
 Dealroom Startup Data - Dealroom Startup Data Scraper
 G2 - G2 Reviews Scraper
 PagesJaunes - PagesJaunes Business Scraper
 SIRET French - SIRET French Company Enricher
 ThomasNet Suppliers - ThomasNet Suppliers Scraper
🔎 SEO
 Similarweb - Similarweb Scraper | Website Traffic, Rankings and Competitors
 Apple - Apple Scraper | App Store Apps, Ratings and Charts
 Google News - Google News Scraper
📈 Marketing
 Pexels -
🧰 More tools
 Apple - Apple Reviews Scraper | App Store Reviews and Ratings
 PrizePicks - PrizePicks Scraper | Player Props, Lines and Projections
Support
Need something this scraper doesn't do yet? We ship features fast.
- Feature requests go straight to our backlog
- Enterprise needs? We do custom integrations and high-volume plans
- Pricing questions? Check the Monetization tab on the actor page
Response time: usually under 24 hours.
Legal compliance
This Actor extracts publicly available data from Xiaohongshu (xiaohongshu.com). It does not bypass any login, paywall or CAPTCHA, and it reads only videos that the site shows to any visitor. Users are responsible for complying with Xiaohongshu's terms of service and with applicable data protection laws (GDPR, CCPA, and China's PIPL). The output contains creator names, profile links and avatars, which are personal data: handle them accordingly, and respect the creators' rights before reusing their videos. The data returned is informational; verify accuracy for regulated use cases.
RedNote Videos Scraper by SilentFlow: Xiaohongshu videos, numbers and transcripts, one row per video.


